引言与 AI 系统概述
Chapter 1. Introduction and AI System Overview
本章目录
In late 2024, a small startup in China called DeepSeek.AI stunned the AI community by training a frontier large language model (LLM) without access to the latest, stateof-the-art NVIDIA GPUs at the time. Due to export restrictions, DeepSeek’s engineers could not obtain top-tier NVIDIA Blackwell (B200, B300, etc.) or Hopper (H100, H200, etc.) GPUs, so they resorted to locally available, export-compliant alternatives at the time, including the NVIDIA H800 GPU. They used custom kernels and advanced optimization techniques such as model distillation to squeeze out maximum performance from these less capable GPUs.2024 年底,中国一家名为 DeepSeek.AI 的初创公司震惊了 AI 界:它在当时无法获得最新、最先进的 NVIDIA GPU 的情况下,训练出了一个*前沿*大语言模型(LLM)。由于出口限制,DeepSeek 的工程师无法获得顶级的 NVIDIA Blackwell(B200、B300 等)或 Hopper(H100、H200 等)GPU,因此他们转而使用当时本地可获得、符合出口管制的替代产品,包括 NVIDIA H800 GPU。他们使用自定义内核和模型蒸馏等先进优化技术,从这些性能较弱的 GPU 上榨取出最大性能。
Despite these limitations, DeepSeek.AI trained their DeepSeek-R1 model and achieved reasoning capabilities near the performance of leading frontier models that were trained on the most capable NVIDIA chips at the time. This case underscores that practitioners and researchers skilled in AI systems performance engineering can get the most out of their available hardware—no matter the constraints.尽管存在这些限制,DeepSeek.AI 仍训练出了其 DeepSeek-R1 模型,并达到了接近当时用最强 NVIDIA 芯片训练出的领先前沿模型的推理能力。这一案例表明,精通 AI 系统性能工程的从业者和研究人员无论面对何种约束,都能充分发挥现有硬件的潜力。
For example, DeepSeek’s engineers treated communication bandwidth as a scarce resource, optimizing every byte over the wire to achieve what many thought impossible on that infrastructure. They scaled out to thousands of these constrained GPUs— connected with limited-bandwidth interconnects—using novel software and algorithmic optimizations to overcome these limitations.例如,DeepSeek 的工程师将通信带宽视为一种*稀缺资源*,对链路上的每一个字节都进行优化,从而在该基础设施上实现了许多人认为不可能的事情。他们扩展到数千块这类受限 GPU——通过有限带宽的互连相连——并利用新颖的软件与算法优化来克服这些限制。
Contrast DeepSeek’s approach with the “brute force” path taken by the largest AI frontier labs in the United States and Europe. These labs continue to pursue larger compute clusters and larger models. Model sizes have exploded from millions to billions and now to trillions of parameters. And while each 10× increase in scale has unlocked qualitatively new capabilities, they require tremendous cost and resources.将 DeepSeek 的做法与美国和欧洲最大的 AI 前沿实验室所走的“蛮力”路线相对比。这些实验室持续追求更大的计算集群和更大的模型。模型规模已从数百万参数爆炸式增长到数十亿,如今又增长到数万亿参数。虽然规模每提升 10 倍都会解锁质变性的新能力,但也需要巨大的成本和资源。
For instance, training OpenAI’s GPT-4 (2023) reportedly cost an estimated ~$100 million, while training Google’s Gemini Ultra (late 2023) is estimated at a staggering ~$191 million. This demonstrates the need for resource efficiency going forward as these models scale up in size and cost.例如,据报道,训练 OpenAI 的 GPT-4(2023 年)估计耗资约 1 亿美元,而训练 Google 的 Gemini Ultra(2023 年底)的估计成本则高达约 1.91 亿美元。这表明,随着这些模型在规模和成本上不断攀升,未来必须重视资源效率。
DeepSeek claims that their DeepSeek-R1 model was trained for less than $6 million in compute—an order of magnitude lower than models like GPT-4 and Gemini Ultra. At the same time, DeepSeek-R1 matches the performance of rival models that cost orders of magnitude more money.DeepSeek 声称,其 DeepSeek-R1 模型的训练计算成本不到 600 万美元——比 GPT-4 和 Gemini Ultra 等模型低一个数量级。与此同时,DeepSeek-R1 的性能却与成本高出数个数量级的竞品模型相当。
And while there is some doubt as to the validity of the $6 million claim—and what exactly it includes (e.g., just a single training run) or excludes (e.g., experimentation and the model-development pipeline)—the announcement briefly shocked the US financial markets, including NVIDIA’s stock, which dropped ~17% in a single day based on this news. This was caused by concerns that DeepSeek’s efficiency innovations would somehow require less NVIDIA hardware in the future. While this market reaction was a bit overblown—and NVIDIA stock recovered in subsequent trading sessions—it demonstrates the significant financial impact that breakthroughs in AI efficiency can have on global financial markets.尽管有人对 600 万美元这一说法的有效性存疑——也不清楚它究竟包含什么(例如,仅一次训练运行)或不包含什么(例如,实验和模型开发流水线)——但这一公告一度震动了美国金融市场,包括 NVIDIA 的股价,后者因这一消息在单日内下跌约 17%。其原因是市场担心 DeepSeek 的效率创新会在未来以某种方式减少对 NVIDIA 硬件的需求。虽然这一市场反应有些过度——NVIDIA 股价在随后的交易时段中有所回升——但它表明,AI 效率方面的突破可以对全球金融市场产生重大的财务影响。
Beyond model training, DeepSeek boasts significant inference efficiency gains through novel hardware-aware algorithmic improvements to the transformer architecture that powers most modern, frontier LLMs. DeepSeek has clearly demonstrated that clever AI systems performance engineering optimizations can upend the eco-nomics of ultrascale AI model training and inference. These optimizations are covered throughout the rest of the book.除模型训练之外,DeepSeek 还通过对驱动大多数现代前沿 LLM 的 Transformer 架构进行新颖的硬件感知算法改进,宣称在推理效率上取得了显著提升。DeepSeek 已清楚地证明,巧妙的 AI 系统性能工程优化可以颠覆超大规模 AI 模型训练与推理的经济性。这些优化将在本书其余部分中介绍。
The takeaway is a profound realization that, at these scales, every bit of performance squeezed out of our systems could translate to millions, or even billions, of dollars saved. Every bottleneck eliminated can have an outsized impact on training throughput and inference latency. This, in turn, reduces cost and increases overall end-user happiness. In short, AI systems performance engineering isn’t just about speed—it’s about making the previously impossible both possible and affordable.由此得出的结论发人深省:在这种规模下,从系统中榨取的每一分性能都可能转化为数百万乃至数十亿美元的节省。消除的每一个瓶颈都会对训练吞吐量和推理时延产生超乎寻常的影响,进而降低成本并提升终端用户的整体满意度。简而言之,AI 系统性能工程不仅仅关乎速度——它更在于让曾经不可能之事变得既可行又可负担。
In Chapter 1, we embark on an in-depth exploration of the AI systems performance engineer—a role that has become pivotal in the era of large-scale artificial intelligence. This chapter serves as a comprehensive guide to understanding the multiface-ted responsibilities and the critical impact of this profession on modern AI systems.在第 1 章中,我们将深入探索 AI 系统性能工程师这一角色——在大规模人工智能时代,这一角色已变得举足轻重。本章旨在全面介绍这一职业的多方面职责及其对现代 AI 系统的关键影响。
We begin by tracing the evolution of AI workloads, highlighting the transition from traditional computing paradigms to the demands of contemporary AI applications. This context sets the stage for appreciating the necessity of specialized performance engineering in AI.我们首先追溯 AI 工作负载的演进历程,重点阐述从传统计算范式向当代 AI 应用需求的转变。这一背景为理解 AI 领域专门化性能工程的必要性做好了铺垫。
The chapter then dives into the core competencies required for an AI systems performance engineer. We examine the technical proficiencies essential for the role, including a deep understanding of hardware architectures, software optimization techniques, and system-level integration. Additionally, we discuss the importance of soft skills such as problem solving, communication, and collaboration, which are vital for navigating the interdisciplinary nature of AI projects.随后,本章深入探讨 AI 系统性能工程师所需的核心能力。我们考察该角色必备的技术素养,包括对硬件架构、软件优化技术和系统级集成的深刻理解。此外,我们还讨论解决问题、沟通与协作等软技能的重要性,这些技能对于应对 AI 项目的跨学科特性至关重要。
A significant portion of the chapter is dedicated to the practical aspects of the role. We explore how performance engineers analyze system bottlenecks, implement optimization strategies, and ensure the scalability and reliability of AI systems. Real-world scenarios and case studies are presented to illustrate these concepts, providing tangible examples of challenges and solutions encountered in the field.本章相当大的篇幅专门讨论该角色的实践层面。我们探讨性能工程师如何分析系统瓶颈、实施优化策略,并确保 AI 系统的可扩展性与可靠性。书中呈现了真实场景和案例研究来阐释这些概念,提供了该领域所遇挑战与解决方案的具体实例。
Furthermore, we discuss the tools and methodologies commonly employed by performance engineers, offering insights into performance testing, monitoring, and benchmarking practices. This includes an overview of industry-standard tools and how they are applied to assess and enhance system performance.此外,我们还讨论性能工程师常用的工具与方法,深入介绍性能测试、监控和基准测试实践,包括对业界标准工具的概述及其在评估和提升系统性能方面的应用方式。
By the end of Chapter 1, readers will have a thorough understanding of the AI systems performance engineer’s role, the skills required to excel in this position, and the critical importance of performance engineering in the successful deployment and operation of AI systems. This foundational knowledge sets the stage for the subsequent chapters, where we dive deeper into specific techniques, technologies, and best practices that define excellence in AI performance engineering.到第 1 章结束时,读者将对 AI 系统性能工程师的角色、胜任该职位所需的技能,以及性能工程在 AI 系统成功部署与运行中的关键重要性形成透彻的理解。这些基础知识为后续章节奠定了基础,我们将在其中深入探讨那些定义 AI 性能工程卓越水准的具体方法、技术与最佳实践。
AI 系统性能工程师
The AI Systems Performance Engineer
The AI systems performance engineer is a specialized role focused on optimizing the performance of AI models and the underlying systems they run on. These engineers ensure that AI training and inference pipelines are fast, cost-efficient, and performant—as well as reliable and highly available. As the scale increases, the AI systems performance engineer becomes even more critical.AI 系统性能工程师是一个专门化的角色,专注于优化 AI 模型*以及*其运行所依赖的底层系统的性能。这些工程师确保 AI 训练与推理流水线快速、经济高效且性能出色——同时兼具可靠性与高可用性。随着规模不断扩大,AI 系统性能工程师的重要性愈发凸显。
An AI systems performance engineer commands top salaries—and for very good reasons. Our work has a clear impact on the bottom line. We blend expertise across hardware, software, and algorithms. We must understand low-level OS considerations, memory hierarchies, networking fundamentals, and multiple languages like Python and C++, as well as different AI frameworks and libraries such as PyTorch, OpenAI’s Triton, and NVIDIA’s Compute Unified Device Architecture (CUDA).AI 系统性能工程师享有顶级薪酬——而且理由十分充分。我们的工作对利润底线有着显著影响。我们融合了硬件、软件与算法方面的专业能力。我们必须理解底层操作系统层面的考量、显存层次结构、网络基础知识以及 Python 和 C++ 等多种编程语言,还要熟悉 PyTorch、OpenAI 的 Triton 以及 NVIDIA 的统一计算设备架构(CUDA)等不同的 AI 框架和库。
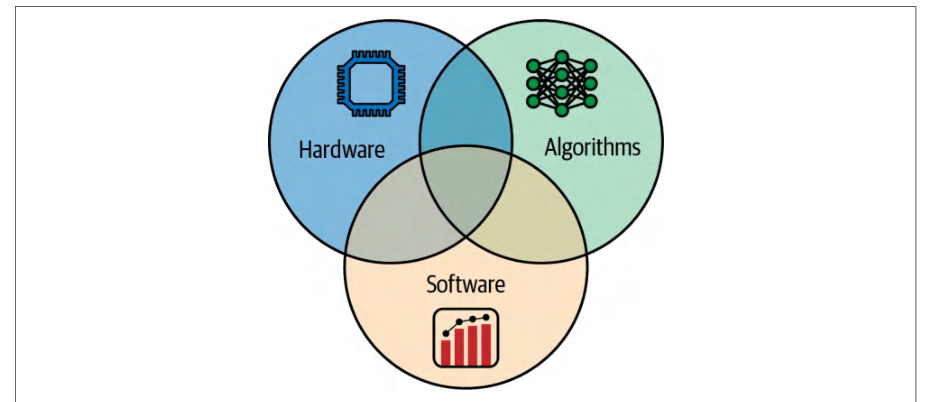
On any given day, an AI systems performance engineer might be examining low-level GPU kernel efficiency, optimizing OS thread scheduling, analyzing memory access patterns, increasing network throughput efficiency, or debugging distributed training algorithms. Key responsibilities of an AI systems performance engineer include benchmarking, profiling, debugging, optimizing, scaling, and managing resources efficiently. And while performance engineers may specialize in a combination of hardware, software, and algorithms, the point is that these specializations need to be codesigned together (see Figure 1-1). As such, it’s good to understand their trade-offs and how they affect one another.在任何一天,AI 系统性能工程师可能都在检查底层 GPU 内核效率、优化操作系统线程调度、分析显存访问模式、提升网络吞吐效率,或调试分布式训练算法。AI 系统性能工程师的主要职责包括基准测试、性能剖析、调试、优化、扩展以及高效管理资源。尽管性能工程师可能专精于硬件、软件和算法的某种组合,但关键在于这些专精领域需要协同设计(见图 1-1)。因此,理解它们之间的权衡以及彼此如何影响是很有益的。
基准测试与性能剖析
Benchmarking and Profiling
Benchmarking and profiling involve measuring latency, throughput, memory usage, and other performance metrics for AI models under various workloads, including training and inference. To identify bottlenecks, we must iteratively use NVIDIA Nsight Systems and NVIDIA Nsight Compute together with the PyTorch profiler. Combined, these tools help pinpoint bottlenecks and track performance over time at different levels of the stack as we continue to improve overall performance of our AI system.基准测试与性能剖析涉及在各种工作负载(包括训练和推理)下测量 AI 模型的时延、吞吐量、显存占用以及其他性能指标。为了识别瓶颈,我们必须迭代地将 NVIDIA Nsight Systems 和 NVIDIA Nsight Compute 与 PyTorch 性能剖析器结合使用。在我们持续提升 AI 系统整体性能的过程中,这些工具结合起来有助于在技术栈的不同层级上定位瓶颈并跟踪性能随时间的变化。
Debugging and optimizing performance issues requires that we trace performance issues to their root cause, whether it’s a suboptimal CUDA kernel, an unnecessary communication overhead, or an imbalance in our training or inference workload.调试和优化性能问题要求我们将性能问题追溯到根本原因,无论原因是次优的 CUDA 内核、不必要的通信开销,还是训练或推理工作负载中的不均衡。
In one case, we may want to use more efficient matrix operations that take advantage of the latest NVIDIA Transformer Engine (TE) hardware optimized for modern LLMs that use the transformer architecture. In another case, we can improve the software framework by configuring a higher degree of parallelism for our在一种情况下,我们可能希望使用更高效的矩阵运算,以利用最新的 NVIDIA Transformer Engine(TE)硬件——它针对使用 Transformer 架构的现代 LLM 进行了优化。在另一种情况下,我们可以通过为我们的
“embarrassingly parallel” inference workload. In yet another case, we may try to improve the transformer’s attention algorithm by implementing better memory management and reducing the amount of memory moved in and out of GPU RAM relative to the number of GPU computations required.“高度并行”的推理工作负载配置更高程度的并行性来改进软件框架。在又一种情况下,我们可能尝试通过实现更好的内存管理,并相对于所需的 GPU 计算量减少进出 GPU 显存的数据移动量,来改进 Transformer 的注意力算法。
Even minor code tweaks can produce major wins. For example, maybe a data preprocessing step written in Python is holding up an entire training pipeline. You can remove that bottleneck by reimplementing the code in C++ or use NVIDIA cuPyNumeric, a drop in NumPy replacement, that can distribute array-operation workloads across both CPUs and GPUs.即使是微小的代码调整也能带来巨大的收益。例如,某个用 Python 编写的数据预处理步骤可能拖慢了整个训练流水线。你可以通过用 C++ 重新实现该代码来消除这个瓶颈,或者使用 NVIDIA cuPyNumeric——一个可直接替换 NumPy 的库,它能够将数组运算工作负载分布到 CPU 和 GPU 上。
扩展分布式训练与推理
Scaling Distributed Training and Inference
Scaling small research workloads to larger production workloads on ultrascale clusters will ensure that as we move from 8 GPUs to 80,000 GPUs, the system will scale with minimal overhead and loss of efficiency. This requires optimizing communication using NVIDIA Collective Communications Library (NCCL, pronounced “nickel”) for distributed collectives like all-reduce commonly seen in training runs. In addition, the NVIDIA Inference Xfer Library (NIXL) provides high throughput, low latency, and point-to-point data movement across GPU memory and storage tiers for distributed inference. This communication can be between GPUs either on a single node or across thousands of nodes. They also optimize communication and collective aggregation operations like all-reduce, all-to-all, and all-gather, which are used extensively during model training and inference.将小型研究工作负载扩展到超大规模集群上的大型生产工作负载,可确保当我们从 8 个 GPU 扩展到 80,000 个 GPU 时,系统能以最小的开销和效率损失实现扩展。这需要使用 NVIDIA 集合通信库(NCCL,读作“nickel”)来优化通信,以支持训练运行中常见的全归约等分布式集合操作。此外,NVIDIA Inference Xfer Library(NIXL)为分布式推理提供跨 GPU 显存和存储层级的高吞吐、低时延点对点数据移动。这种通信可以发生在单个节点上的 GPU 之间,也可以跨越数千个节点。它们还优化了全归约、全对全和全收集等通信与集合聚合操作,这些操作在模型训练和推理期间被广泛使用。
You may want to place data cleverly across nodes using data, tensor, and pipeline parallelism. Or you may need to redesign the workload to use tensor parallelism or pipeline parallelism because the model is so large that it doesn’t fit onto a single GPU. Perhaps you are using a mixture of experts (MoE) model and can take advantage of expert parallelism.你可能希望利用数据并行、张量并行和流水线并行,巧妙地将数据分布到各个节点上。或者,由于模型规模过大、无法放入单个 GPU,你需要重新设计工作负载以采用张量并行或流水线并行。也许你使用的是*混合专家*(mixture of experts,MoE)模型,因而可以利用专家并行。
高效管理资源
Managing Resources Efficiently
It’s important to optimize how models utilize resources like CPU cores, GPU memory, interconnect bandwidth, and storage I/O. This can involve many efforts such as ensuring GPUs are fed with data at full throttle, pinning threads on specific CPU cores, reducing context-switch overhead, orchestrating memory usage, and avoiding out-of-memory (OOM) errors on GPUs when training and inferencing with large models. Techniques like GPU virtualization (e.g., NVIDIA’s Multi-Instance GPU [MIG]) can partition GPU resources for better overall utilization when full GPU power isn’t needed for a job.优化模型对 CPU 核心、GPU 显存、互连带宽和存储 I/O 等资源的使用方式非常重要。这涉及许多工作,例如确保以全速为 GPU 供给数据、将线程绑定到特定 CPU 核心、降低上下文切换开销、编排显存使用,以及在使用大模型进行训练和推理时避免 GPU 出现显存不足(out-of-memory,OOM)错误。GPU 虚拟化(例如 NVIDIA 的多实例 GPU(MIG))等技术可以划分 GPU 资源,从而在作业不需要完整 GPU 算力时获得更好的整体利用率。
跨团队协作
Cross-Team Collaboration
Cross-team collaboration is absolutely critical for AI systems performance engineers. It’s important to work hand in hand with researchers, data scientists, and application developers—as well as infrastructure teams, including networking and storage.跨团队协作对 AI 系统性能工程师而言绝对至关重要。重要的是与研究人员、数据科学家和应用开发者,以及包括网络和存储在内的基础设施团队携手合作。
Improving performance might require modifying model code, which involves coordination with researchers. Or you may want to deploy a new GPU driver to improve efficiency, which requires the infrastructure team.提升性能可能需要修改模型代码,这需要与研究人员的协调。或者你可能希望部署新的 GPU 驱动以提升效率,这需要基础设施团队的支持。
Often, performance improvements span multiple teams. For instance, updating the CUDA driver or CUDA version for bug fixes and efficiency will involve careful coordination with DevOps, infrastructure, and support teams. And improving model code for performance involves close work with researchers. The performance engineer sits at the intersection of these multidisciplinary domains and speaks the language of AI, computer science, and systems engineering.性能改进往往跨越多个团队。例如,为修复缺陷和提升效率而更新 CUDA 驱动或 CUDA 版本,需要与 DevOps、基础设施和支持团队仔细协调。而为提升性能改进模型代码,则需要与研究人员的紧密合作。性能工程师正处于这些多学科领域的交汇点,能够使用 AI、计算机科学和系统工程的语言进行沟通。
透明度与可复现性
Transparency and Reproducibility
In performance engineering, it’s vital to measure everything and trust data, not assumptions. By publishing your work, others can learn, reproduce, and build upon your findings.在性能工程中,度量一切并相信数据而非假设至关重要。通过公开你的工作,其他人可以学习、复现并基于你的发现继续推进。
One notable aspect of DeepSeek’s story is how openly they shared their infrastructure optimizations. During DeepSeek’s Open-Source Week in February 2025, they released a suite of open source GitHub repositories, including FlashMLA, DeepGEMM, DeepEP, expert parallelism load balancer (EPLB), DualPipe, and Fire-Flyer File System (3FS). Each project was production-tested and aimed at squeezing the most performance from their hardware. These projects are described in the DeepSeek-V3 Technical Report.DeepSeek 故事中一个值得注意的方面,是他们如此公开地分享了其基础设施优化成果。在 2025 年 2 月的 DeepSeek 开源周期间,他们发布了一系列开源 GitHub 仓库,包括 FlashMLA、DeepGEMM、DeepEP、专家并行负载均衡器(expert parallelism load balancer,EPLB)、DualPipe 和 Fire-Flyer 文件系统(3FS)。每个项目都经过生产环境测试,旨在从其硬件中榨取最大性能。这些项目在 DeepSeek-V3 技术报告中有所描述。
FlashMLA is their optimized attention kernel written in CUDA C++. DeepGEMM provides an FP8-optimized matrix multiplication library that reportedly outperforms many vendor kernels on both dense and sparse operations. Deep Experts Parallelism (DeepEP) is their highly tuned communication library for mixture-of-experts (MoE) models. EPLB implements a redundant expert strategy that duplicates heavily loaded experts to handle the additional load. DualPipe is a bidirectional pipeline parallelism algorithm that overlaps the forward/backward computation and communication phases to reduce pipeline bubbles. And 3FS is their high-performance distributed filesystem, reminding us that every layer needs to be optimized—including the filesystem—to get the most performance out of our AI system.FlashMLA 是他们用 CUDA C++ 编写的优化注意力内核。DeepGEMM 提供了一个针对 FP8 优化的矩阵乘法库,据报道其在稠密和稀疏运算上均优于许多厂商内核。Deep Experts Parallelism(DeepEP)是他们为混合专家(MoE)模型高度调优的通信库。EPLB 实现了一种冗余专家策略,通过复制负载较重的专家来处理额外负载。DualPipe 是一种双向流水线并行算法,它将前向/反向计算与通信阶段重叠,以减少流水线气泡。而 3FS 是他们高性能的分布式文件系统,提醒我们为了让 AI 系统发挥最大性能,每一层都需要优化——包括文件系统。
By open sourcing these projects on GitHub during their February 2025 “Open-Source Week,” DeepSeek not only demonstrated the credibility of their claims by allowing others to reproduce their results but also contributed back to the community. This transparency allows other developers to benchmark, reproduce, and learn from their methods, including overlapping communication with DeepEP/DualPipe pipeline parallelism and saturating NVMe SSD/RDMA bandwidth with 3FS.DeepSeek 在 2025 年 2 月的“开源周”(Open-Source Week)期间将这些项目在 GitHub 上开源,不仅通过允许他人复现其结果证明了自身主张的可信度,也回馈了社区。这种透明度使其他开发者能够对其方法进行基准测试、复现并从中学习,包括利用 DeepEP/DualPipe 流水线并行实现通信重叠,以及借助 3FS 使 NVMe SSD/RDMA 带宽达到饱和。
Open efforts like DeepSeek’s Open Infra Index provide valuable baselines and tools. They provide real-world performance measurements on various AI hardware setups and encourage apples-to-apples comparisons and reproducibility. Similarly, the MLPerf open benchmark suite provides a standard for reproducibly comparing training and inference performance across hardware and software setups.DeepSeek 的 Open Infra Index 等开放性工作提供了宝贵的基线和工具。它们在各种 AI 硬件配置上提供真实场景的性能测量数据,并鼓励同口径比较与可复现性。类似地,MLPerf 开放基准测试套件为在不同硬件与软件配置之间可复现地比较训练与推理性能提供了标准。
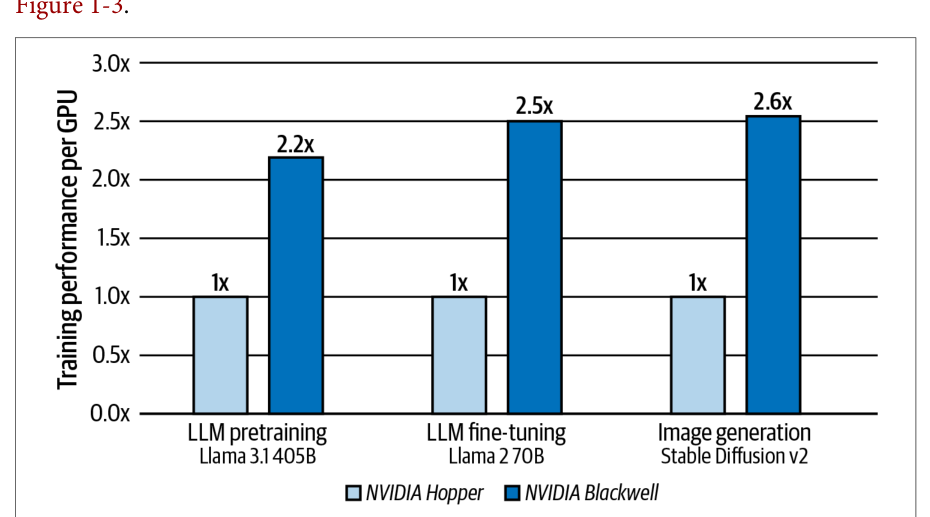
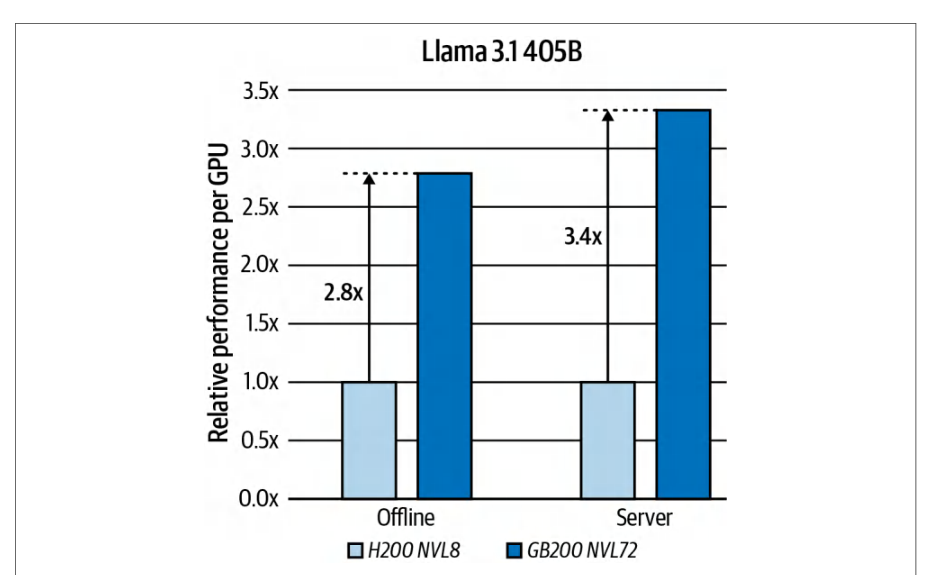
Industry benchmarks such as MLPerf have quantified these kinds of codesigned optimizations across hardware generations. In MLPerf Training v5.0 (2025), a Blackwell-based NVIDIA GB200 NVL72 system produced up to 2.6× higher training throughput per GPU over an equivalent Hopper system, as shown in Figure 1-2. In MLPerf Inference v5.0 (2025), the Blackwell NVL72 achieved about 3.4× higher inference throughput per GPU over an equivalent Hopper cluster due to higher per-GPU performance and the much larger NVLink domain. These results are shown in诸如 MLPerf 的行业基准测试已量化了跨硬件代际的这类协同设计优化。在 MLPerf Training v5.0(2025)中,基于 Blackwell 的 NVIDIA GB200 NVL72 系统相比同等 Hopper 系统实现了最高 2.6× 的每 GPU 训练吞吐量提升,如图 1-2 所示。在 MLPerf Inference v5.0(2025)中,Blackwell NVL72 由于更高的每 GPU 性能和更大的 NVLink 域,相比同等 Hopper 集群实现了约 3.4× 的每 GPU 推理吞吐量提升。这些结果显示在
In later chapters, we’ll reference some of these open benchmarks to support various performance tuning concepts. For instance, when discussing GPU kernel optimizations, we will reference DeepSeek’s published profiles showing how their custom kernels achieved near-peak memory bandwidth utilization on NVIDIA GPUs.在后续章节中,我们将引用其中一些开放基准来支撑各种性能调优概念。例如,在讨论 GPU 内核优化时,我们将引用 DeepSeek 公布的性能剖析结果,其中展示了其自定义内核如何在 NVIDIA GPU 上实现接近峰值的显存带宽利用率。
Experimental transparency and reproducibility are critical in moving the field of AI performance engineering forward. It’s easy to fall into the trap of anecdotal “vibe” optimizations (“We did X and things felt faster”). Instead, I’m advocating for a rigorous, scientific approach that develops hypotheses, measures the results with reproducible benchmarks, adjusts to improve the results, reruns the benchmarks, and shares all of the results at every step.实验的透明性与可复现性对于推动 AI 性能工程领域的发展至关重要。人们很容易陷入轶事式“凭感觉”优化的陷阱(“我们做了 X,感觉变快了”)。相反,我倡导一种严谨、科学的方法:提出假设、用可复现的基准测量结果、进行调整以改进结果、重新运行基准,并在每一步分享全部结果。
DeepSeek 在美国对华出口硬件限制下仍将模型扩展至约 6800 亿参数
DeepSeek Scales to ~680-Billion Parameter Models Despite US Export Hardware Restrictions in China
Sometimes systems-performance innovations are born from necessity. As mentioned, DeepSeek found itself constrained to using only NVIDIA’s H800 GPUs due to US export restrictions. The H800 is an export-compliant variant of the Hopper GPU. Compared to the H100, it reduces NVLink interconnect bandwidth and FP64 performance while keeping HBM capacity and bandwidth largely similar.有时,系统性能方面的创新源于必要性。如前所述,由于美国的出口限制,DeepSeek 只能使用 NVIDIA 的 H800 GPU。H800 是符合出口合规要求的 Hopper GPU 变体。与 H100 相比,它降低了 NVLink 互连带宽和 FP64 性能,而 HBM 容量与带宽则大体保持相近。
For context, an NVIDIA H100 provides about 900 GB/s NVLink interconnect bandwidth per GPU, while H800 provides about 400 GB/s bandwidth per GPU. This makes inter-GPU data transfers slower and ultimately limits multi-GPU scalability. Additionally, while the H100 offers 3.35 TB/s of memory bandwidth, the H800’s limited throughput means that data transfers are much slower. This threatens to bottleneck distributed training jobs and limit scalability efficiency.作为背景,NVIDIA H100 每块 GPU 提供约 900 GB/s 的 NVLink 互连带宽,而 H800 每块 GPU 仅提供约 400 GB/s 的带宽。这使得 GPU 间的数据传输变慢,并最终限制了多 GPU 的可扩展性。此外,尽管 H100 提供 3.35 TB/s 的显存带宽,但 H800 受限的吞吐量意味着数据传输要慢得多。这有可能成为分布式训练作业的瓶颈,并限制可扩展性效率。
DeepSeek set out to train a massive ~680-billion-parameter MoE language model, called DeepSeek-V3, in this heavily constrained environment. This MoE model uses only about 37 billion active parameters per input token—rather than all ~680 billion at once.在这种高度受限的环境下,DeepSeek 着手训练一个名为 DeepSeek-V3 的约 6800 亿参数的大规模混合专家(MoE)语言模型。该 MoE 模型对每个输入词元(token)仅使用约 370 亿个激活参数,而非一次性动用全部约 6800 亿参数。
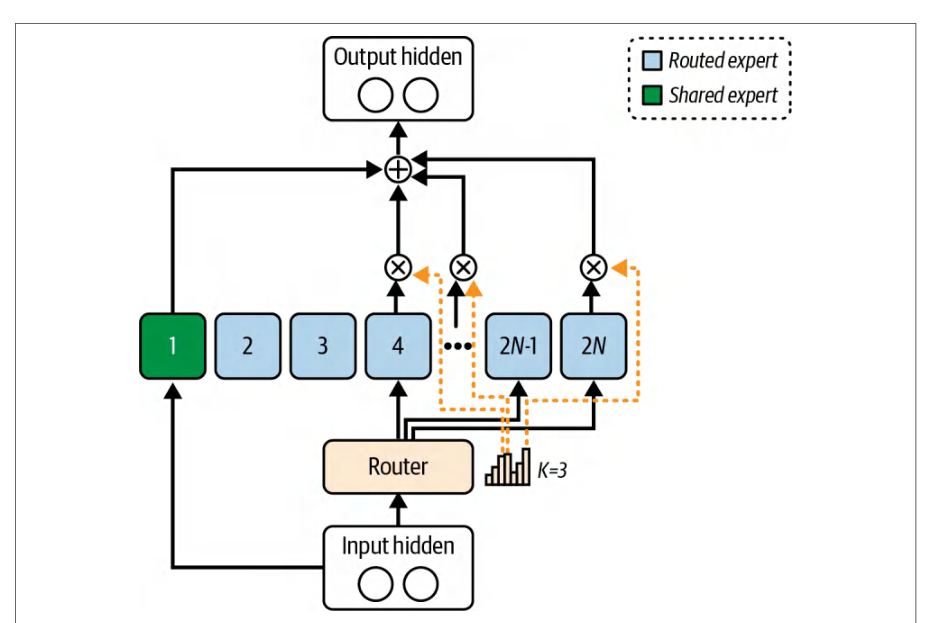
With this architecture, only a fraction of the model is activated at any given time. This helps manage computational load—even with the compact H800 setup. Specifically, for each token, DeepSeek-V3 uses 1 shared expert plus 8 router-selected experts (out of 256 experts) for a total of 9 active experts per token, as shown in Figure 1-4.在这种架构下,任意时刻只有模型的一部分被激活。这有助于管理计算负载——即便在紧凑的 H800 配置下也是如此。具体而言,对于每个词元,DeepSeek-V3 使用 1 个共享专家加上 8 个由路由器选出的专家(从 256 个专家中选出),即每个词元共有 9 个激活专家,如图 1-4 所示。
We’ll cover MoEs in more detail in the upcoming chapters. But just know that, to work around the environment limitations, DeepSeek implemented a novel DualPipe parallelism algorithm that carefully overlaps computation and communication to mask the H800’s inherent weaknesses.我们将在后续章节中更详细地讨论 MoE。但只需知道,为绕开环境限制,DeepSeek 实现了一种新颖的 DualPipe 并行算法,通过精心重叠计算与通信来掩盖 H800 的固有弱点。
By designing custom CUDA kernels to bypass some of the default NCCL communication collectives, DeepSeek was able to coordinate data transfers in tandem with ongoing computations. This keeps the GPUs efficiently utilized despite their reduced interconnect bandwidth. This kind of communication/computation overlap is a theme we will revisit throughout the rest of the book.通过设计自定义 CUDA 内核以绕过部分默认的 NCCL 集合通信,DeepSeek 得以让数据传输与正在进行的计算协同进行。尽管互连带宽有所降低,这仍使 GPU 保持高效利用。这种通信/计算重叠是贯穿本书余下部分的一个主题。
This innovative engineering paid off, as DeepSeek-V3 was trained to completion at a fraction of the GPU time (and cost) of similarly sized frontier models from OpenAI, Meta, DeepMind, and others. This is a fraction of the resources that many assumed were necessary to train a model of this scale using a more capable cluster.这项创新工程取得了回报:DeepSeek-V3 完成训练所耗费的 GPU 时间(及成本)仅为 OpenAI、Meta、DeepMind 等公司同等规模前沿模型的一小部分。而这只是许多人认为使用能力更强的集群训练如此规模模型所必需资源的一小部分。
DeepSeek reports that V3’s performance approaches GPT-4’s on several standardized benchmarks, including language understanding, reading comprehension, and reasoning. It even matches or slightly exceeds GPT-4 on some tests. These comparisons were based on standardized tests used across the industry. This implies that an open MoE model can rival the best closed models—despite using less capable hardware.DeepSeek 报告称,V3 在语言理解、阅读理解与推理等多项标准化基准上的表现已接近 GPT-4。在某些测试中,它甚至与 GPT-4 持平或略有超越。这些比较基于业界通用的标准化测试。这意味着,一个开放的 MoE 模型即便使用能力较弱的硬件,也能与最好的闭源模型相抗衡。
Building on the DeepSeek-V3 model, the team then created DeepSeek-R1, which is its specialized reasoning model built similarly to OpenAI’s o1 and o3 series of reasoning models. Instead of relying heavily on costly human feedback loops for fine-tuning, DeepSeek pioneered a “cold start” strategy that used minimal supervised data, instead emphasizing reinforcement learning techniques to embed chain-of-thought reasoning directly into R1. This approach reduced training cost and time and under-scored that smart software and algorithm design can overcome hardware bottlenecks.在 DeepSeek-V3 模型的基础上,团队随后创建了 DeepSeek-R1,这是其专用推理模型,构建方式与 OpenAI 的 o1 和 o3 系列推理模型类似。DeepSeek 没有严重依赖昂贵的人工反馈回路进行微调,而是开创了一种“冷启动”策略,仅使用极少量监督数据,转而强调强化学习技术,将思维链推理直接嵌入 R1。这种方法降低了训练成本与时间,并凸显了聪明的软件与算法设计能够克服硬件瓶颈。
The lessons learned are that large, sparsely activated MoE models can be effectively scaled even on limited memory and compute budgets. Novel training schedules and low-level communication/computation overlap optimizations can overcome hardware limitations, as demonstrated by the enormous return on investment (ROI) of DeepSeek’s efforts.由此得到的经验是:大型稀疏激活的 MoE 模型即使在有限的内存与算力预算下也能有效扩展。新颖的训练调度与底层通信/计算重叠优化能够克服硬件限制,DeepSeek 工作所带来的巨大投资回报率(ROI)便证明了这一点。
The ROI is clear, as DeepSeek’s unconventional approach brought about huge efficiencies and created a series of powerful models at much lower training cost and time. By extracting every ounce of performance from NVIDIA’s H800 GPU—even under the constraints of reduced communication bandwidth—the team delivered GPT-4-level model performance for millions of dollars less. Additionally, DeepSeek saved even more money by not requiring as much human-labeled data during R1’s fine-tuning stage for reasoning.ROI 显而易见:DeepSeek 的非传统方法带来了巨大效率提升,以低得多的训练成本和时间打造出一系列强大模型。通过从 NVIDIA H800 GPU 中榨取每一分性能——即便在通信带宽受限的约束下——团队以低数百万美元的成本交付了 GPT-4 级别的模型性能。此外,由于 R1 推理微调阶段所需的人工标注数据更少,DeepSeek 还节省了更多费用。
In short, smart software and algorithm design overcame brute-force hardware limitations. This enabled DeepSeek to develop large-scale AI models on a tight cost and hardware budget.简而言之,聪明的软件与算法设计克服了蛮力硬件的限制。这使 DeepSeek 能够在紧张的成本与硬件预算下开发大规模 AI 模型。
迈向 100 万亿参数模型
Toward 100-Trillion-Parameter Models
100-trillion-parameter models are an aspirational milestone for AI and are often compared against the estimated 100 trillion synaptic connections in the human neo-cortex. Each synaptic connection is equivalent to a model parameter. Achieving a model of this size is theoretically possible, but it demands an extraordinary amount of resources—and money. Scaling to 100-trillion-parameter models by brute force would be impractical for all but the absolute wealthiest organizations.100 万亿参数模型是 AI 的一个理想化里程碑,常被拿来与人类新皮层中估计约 100 万亿个突触连接相比较。每个突触连接相当于一个模型参数。实现如此规模的模型在理论上是可能的,但它需要极其庞大的资源——以及资金。以蛮力方式扩展到 100 万亿参数模型,除最富有的组织外,对任何机构都不切实际。
As a rough order of magnitude, a dense 100-trillion-parameter model trained on about 29 trillion tokens would require on the order of 1.2 × 1029 floating point operations (FLOPS). Larger token counts scale this linearly, while using sparse (MoE) models can reduce the effective compute. However, even with sparsity, this demonstrates that mere brute force is not enough to satisfy the compute needs of ultrascale models. New approaches are needed to make 100-trillion-parameter training feasible in a reasonable amount of time. Achieving this kind of scale requires breakthrough efficiencies in hardware, software, and algorithms codesign—rather than just continuing to scale out current methods.粗略按数量级估算,一个在约 29 万亿个词元(token)上训练的稠密(dense)100 万亿参数模型,将需要约 1.2 × 1029 次浮点运算(FLOPS)。词元数量更大时,这一需求会线性增长;而使用稀疏的混合专家(MoE)模型则可以降低有效计算量。然而,即便有稀疏性,这也表明仅靠蛮力并不足以满足超大规模模型的计算需求。要让 100 万亿参数模型的训练在合理的时间内变得可行,需要新的方法。要达到这种规模,需要在硬件、软件和算法的协同设计上取得突破性的效率提升,而不是仅仅继续横向扩展现有方法。
Such explosive growth in training cost is driving a search for new AI systems and software engineering techniques to increase performance, reduce cost, and make extreme-scale AI feasible with limited compute resources, power constraints, and money. Researchers are always exploring novel techniques to reduce the effective compute requirements.训练成本的爆炸式增长正在推动人们寻找新的 AI 系统和软件工程技术,以提高性能、降低成本,并在计算资源有限、功耗受限且资金有限的情况下使极端规模的 AI 变得可行。研究人员一直在探索新颖的技术来降低有效计算需求。
One prominent idea is to use sparsity and, specifically, MoE models. Sparse models like MoEs are in contrast to traditional dense models like the common GPT-series large language models (LLMs) made popular by OpenAI. In fact, there is public speculation that some frontier models like OpenAI’s proprietary GPT-series and o-series reasoning models are based on the MoE architecture.一个突出的思路是利用稀疏性,具体来说就是 MoE 模型。MoE 这类稀疏模型与传统的稠密模型形成对照,后者的典型代表是由 OpenAI 发扬光大的常见 GPT 系列大语言模型(LLM)。事实上,外界公开猜测,OpenAI 专有的 GPT 系列和 o 系列推理模型等一些前沿模型正是基于 MoE 架构。
Sparse models like MoEs activate only parts of the model for each input token. By routing each input token through only a subset of its many internal “experts,” the FLOPS per token stays roughly constant even as total parameters grow. Such sparse models prove that scaling to multi-trillion-parameter models is done without an equivalent explosion in computation cost. Additionally, since these models use fewer active parameters during inference, request-response latencies are typically much lower for MoE models compared to their dense equivalents. These are crucial insights toward training and serving 100-trillion-parameter-scale models.像 MoE 这样的稀疏模型对每个输入词元只激活模型的一部分。通过将每个输入词元仅路由到模型众多内部“专家”中的一个子集,即使总参数量不断增长,每个词元的 FLOPS 也基本保持恒定。这类稀疏模型证明,扩展到数万亿参数规模的模型并不会带来计算成本的同等爆炸式增长。此外,由于这些模型在推理时使用的激活参数更少,MoE 模型的请求-响应时延通常远低于对应的稠密模型。这些是迈向 100 万亿参数规模模型的训练与服务的关键洞见。
DeepSeek-V3 (base model) and -R1 (reinforcement-learning-based reasoning variant) are great examples of MoE efficiency. They contain ~680 billion total parameters with about 37 billion active per input token. DeepSeek’s technical report and public write-ups describe an MoE with 1 shared expert and 8 selected experts out of 256 per token, which yields about 9 active experts and roughly 37 billion active parameters per token. This makes DeepSeek-V3 and -R1 much more resource-efficient than similarly sized dense large language models. Another example is Google’s Switch Transformer MoE from 2021. This 1.6-trillion-parameter MoE model achieved the same accuracy as a dense model with only a fraction of the computation. It was trained 7× faster than a comparable dense approach.DeepSeek-V3(基座模型)和 -R1(基于强化学习的推理变体)是 MoE 高效性的绝佳范例。它们包含约 6800 亿个总参数,每个输入词元激活约 370 亿个参数。DeepSeek 的技术报告和公开文章描述了一种 MoE:每个词元有 1 个共享专家,并从 256 个专家中选出 8 个专家,从而产生约 9 个激活专家和每个词元约 370 亿个激活参数。这使得 DeepSeek-V3 和 -R1 比规模相近的稠密大语言模型具有高得多的资源效率。另一个例子是 Google 于 2021 年推出的 Switch Transformer MoE。这个 1.6 万亿参数的 MoE 模型仅用一小部分计算量就达到了与稠密模型相同的准确率,其训练速度比可比的稠密方法快 7 倍。
In addition to massive compute requirements, memory is also a major bottleneck. For example, a 100-trillion-parameter model would require approximately 182 TB of GPU memory (182 TB = 100 trillion parameters × 16 bits per weight × 8 bits per byte) to load the model if each parameter is stored in 16-bit (2-byte) precision. This is 3 orders of magnitude (1,000×) compared to the 192 (180 usable) GB of GPU RAM on a single NVIDIA Blackwell B200 GPU.除了巨大的计算需求之外,显存也是一个主要瓶颈。例如,如果每个参数以 16 位(2 字节)精度存储,加载一个 100 万亿参数的模型将需要约 182 TB 的 GPU 显存(182 TB = 100 万亿参数 × 每个权重 16 位 × 每字节 8 位)。相比之下,单块 NVIDIA Blackwell B200 GPU 的 GPU 显存为 192 GB(可用 180 GB),这一需求高出 3 个数量级(1000 倍)。
To simply load the 100-trillion model weights would require close to 1,000 Blackwell B200 GPUs (192 [180 usable] GB each)—or 700 Blackwell Ultra B300 GPUs (~288 GB each). And this estimate is just to load the model and does not include activation memory, optimizer states, and inference input. These would further increase the total memory required.仅仅是加载这个 100 万亿参数模型的权重,就需要接近 1,000 块 Blackwell B200 GPU(每块 192 [可用 180] GB)——或 700 块 Blackwell Ultra B300 GPU(每块约 288 GB)。而且这一估算仅针对加载模型本身,尚未包含激活内存、优化器状态和推理输入,这些还会进一步增加所需的总内存量。
For context, a typical B200 GPU compute node contains just 8 B200 GPUs. To use these, you would require ~125 GPU nodes just to load the model with a B200, and ~86 GPU nodes to load the model with a cluster of Ultra B300 GPU compute nodes (8 B300 GPUs per node).作为参照,一个典型的 B200 GPU 计算节点仅包含 8 块 B200 GPU。若使用 B200,仅加载模型就需要约 125 个 GPU 节点;若使用 Ultra B300 GPU 计算节点集群(每节点 8 块 B300 GPU)来加载模型,则需要约 86 个 GPU 节点。
Additionally, loading training data also becomes extremely difficult since feeding such a model with data fast enough to keep all of those GPUs busy is nontrivial. In particular, communication overhead between the GPUs grows significantly as the 100-trillion-parameter model is partitioned across 1,000 B200 GPUs or 700 B300 GPUs. Training a single model could consume millions of GPU-hours and megawatthours of energy. This is an enormous amount of cost—and energy consumption—to scale out large enough to train and serve a 100-trillion-parameter model.此外,加载训练数据也变得极其困难,因为要以足够快的速度为这样一个模型喂数据、让所有这些 GPU 保持满负荷运转,绝非易事。尤其是当 100 万亿参数模型被划分到 1,000 块 B200 GPU 或 700 块 B300 GPU 上时,GPU 之间的通信开销会显著增长。训练单个模型可能消耗数百万 GPU 小时以及数百万兆瓦时的能量。要将规模横向扩展到足以训练和服务一个 100 万亿参数模型,其成本——以及能耗——都极为可观。
The era of 100-trillion-parameter AI will force us to completely rethink system design to make training and deployment practical at this scale. Hardware, algorithms, and software all need to coevolve to meet this new frontier.100 万亿参数 AI 的时代将迫使我们彻底重新思考系统设计,才能让训练和部署在这一规模下切实可行。硬件、算法和软件都需要协同演进,以迎接这一全新前沿。
NVIDIA 的“单机架 AI 超级计算机”
NVIDIA’s “AI Supercomputer in a Rack”
To meet the challenges of ultrascale computing, NVIDIA has built a new class of AI supercomputers specifically aimed at trillion-parameter-scale workloads. Some examples include the NVIDIA Grace Blackwell GB200 NVL72 in 2024 and the GB300 NVL72 Ultra, which uses Blackwell Ultra GPUs with 288 GB HBM3e per GPU and maintains a 72-GPU NVLink domain with about 130 terabytes per second aggregate bandwidth.为应对超大规模计算的挑战,NVIDIA 构建了一类专门面向万亿参数级工作负载的新型 AI 超级计算机。典型例子包括 2024 年的 NVIDIA Grace Blackwell GB200 NVL72,以及 GB300 NVL72 Ultra——后者采用每块配备 288 GB HBM3e 的 Blackwell Ultra GPU,并维持一个 72 GPU 的 NVLink 域,聚合带宽约 130 TB/s。
Vera Rubin VR200 (2026) and Feynman (2028) systems continue this trend of exascale supercomputers condensed into a single data center rack. In fact, NVIDIA refers to these rack systems like NVL72 as “AI supercomputers in a rack”—and for good reason.Vera Rubin VR200(2026 年)和 Feynman(2028 年)系统延续了这一趋势:把百亿亿次(exascale)超级计算机浓缩进单个数据中心机架。事实上,NVIDIA 将 NVL72 这类机架系统称为“单机架 AI 超级计算机”——而且理由充分。
Each GB200/GB300 NVL72 rack integrates 36 Grace Blackwells connected through NVLink with NVSwitch, providing the rack scale switching fabric. Each Grace Blackwell Superchip is a combination of one NVIDIA Grace CPU (with 72 CPU cores) and two NVIDIA Blackwell GPUs for a total of 36 Grace CPUs and 72 Blackwell GPUs— hence, the “72” in the name “NVL72.”每个 GB200/GB300 NVL72 机架集成 36 个 Grace Blackwell,通过 NVLink 和 NVSwitch 相互连接,提供机架级交换结构。每个 Grace Blackwell 超级芯片由一颗 NVIDIA Grace CPU(含 72 个 CPU 核心)和两块 NVIDIA Blackwell GPU 组成,合计 36 颗 Grace CPU 和 72 块 Blackwell GPU——这正是名称“NVL72”中“72”的由来。
Each Grace Blackwell board connects to other boards using NVSwitch, the on-rack NVLink switch network. This way, all 72 GPUs can communicate with one another at full NVLink 5 bandwidth of 1.8 TB/s bidirectional per GPU (18 × 100 GB/s links). Across the rack, the NVLink Switch System provides about 130 TB/s aggregate GPU to GPU bandwidth within one NVL72 domain.每块 Grace Blackwell 板卡通过 NVSwitch(机架内 NVLink 交换网络)与其他板卡相连。这样,全部 72 块 GPU 都能以 NVLink 5 的满带宽相互通信,即每块 GPU 1.8 TB/s 的双向带宽(18 × 100 GB/s 链路)。在整个机架范围内,NVLink Switch System 在单个 NVL72 域内提供约 130 TB/s 的 GPU 到 GPU 聚合带宽。
Effectively, the NVL72’s internal fabric unifies all 72 Grace Blackwell GPUs into one high-speed cluster. As such, frameworks like PyTorch for training and vLLM for inference can use the single NVLink domain for efficient data tensor pipeline and expert parallelism. CUDA Unified Memory can migrate or remotely access pages across NVLink when needed. However, remote memory has distinct latency and bandwidth that should be treated as nonuniform. When relying on managed allocations across Grace and Blackwell, prefer explicit prefetch using cudaMemPrefetch Async and cudaMemAdvise to reduce page-fault stalls.实际上,NVL72 的内部互连网络将全部 72 块 Grace Blackwell GPU 统一为一个高速集群。因此,用于训练的 PyTorch 和用于推理的 vLLM 等框架可以利用这一单一 NVLink 域,实现高效的数据、张量、流水线和专家并行。CUDA 统一内存可以在需要时跨 NVLink 迁移或远程访问页面。然而,远程内存具有独特的时延和带宽,应当作非均匀内存来对待。当依赖跨 Grace 与 Blackwell 的托管显存分配时,应优先使用 cudaMemPrefetch Async 和 cudaMemAdvise 进行显式预取,以减少缺页停顿。
More details are provided on the compute, memory, and interconnect hardware details of this supercomputer in upcoming chapters. For now, let’s analyze the overall performance specifications of this AI supercomputer as a whole in the context of modern generative AI models.关于这台超级计算机在计算、内存和互连硬件方面的更多细节,将在后续章节中给出。现在,让我们结合现代生成式 AI 模型的背景,从整体上分析这台 AI 超级计算机的性能规格。
A full GB200 NVL72 rack can theoretically reach about 1.44 exaFLOPS for FP4 with 2 to 1 structured sparsity and about 720 petaFLOPS for FP8 with 2 to 1 structured sparsity. It provides roughly 13.5 TB (13,824 GB = 192 GB per GPU × 72 GPUs) of HBM3e across the 72 GPUs and around 30 TB total when counting Grace CPU memory in the same NVLink domain.一个完整的 GB200 NVL72 机架在 2:1 结构化稀疏性下,FP4 理论上可达约 1.44 exaFLOPS,FP8 理论上可达约 720 petaFLOPS。它在 72 个 GPU 上共提供约 13.5 TB(13,824 GB = 192 GB/GPU × 72 GPU)的 HBM3e;若将同一 NVLink 域内的 Grace CPU 内存计入,总容量约为 30 TB。
NVLink provides pooled access across the 72 GPUs, and CUDA Unified Memory can migrate or remotely access pages over NVLink, but remote access has different performance, and the rack does not behave as a single uniform memory device.NVLink 提供跨 72 个 GPU 的池化访问,CUDA 统一内存可以通过 NVLink 迁移或远程访问页面,但远程访问的性能有所不同,整个机架并不会表现为单一的均匀内存设备。
In short, the GB200 NVL72 is a self-contained 72 GPU 1.44 exaFLOPS 30 TB memory system with about 120 to 132 kW rack power, depending on vendor configuration and cooling. It’s truly an AI supercomputer that can train and serve multi-trillion-parameter models in a single rack.简而言之,GB200 NVL72 是一个自成一体的 72 GPU、1.44 exaFLOPS、30 TB 内存系统,机架功耗约为 120 至 132 kW,具体取决于厂商配置和散热方案。它是一台名副其实的 AI 超级计算机,能够在单个机架内训练和服务数万亿参数的模型。
By combining these racks to form ultrascale clusters, you can support massive multi-trillion-parameter models. Even better, you can provision these racks and rack clusters with a few clicks (and quite a few dollars!) using your favorite cloud provider, including Amazon Web Services (AWS), Google Cloud Platform (GCP), Microsoft Azure, CoreWeave, Lambda Labs, and many others.通过将这些机架组合成超大规模集群,你可以支持庞大的数万亿参数模型。更棒的是,只需点击几下(外加相当可观的美元开销!),你就可以通过自己喜爱的云服务提供商开通这些机架和机架集群,包括 Amazon Web Services(AWS)、Google Cloud Platform(GCP)、Microsoft Azure、CoreWeave、Lambda Labs 等众多厂商。
Throughout the book, you will learn how each generation’s innovation in compute, memory, networking, and storage will contribute to more AI scaling in the form of ultrascale clusters, multi-trillion-parameter models, high-throughput training jobs, and extreme-low-latency model inference servers. These innovations are fueled by hardware-aware algorithms that enforce the principles of mechanical sympathy and hardware-software codesign discussed in the next section.在本书中,你将了解每一代在计算、内存、网络和存储方面的创新如何以超大规模集群、数万亿参数模型、高吞吐量训练作业和极低时延模型推理服务器的形式,推动 AI 实现更大规模的扩展。这些创新由硬件感知算法提供动力,此类算法贯彻了下一节将讨论的机械同理心(mechanical sympathy)与软硬件协同设计(hardware-software codesign)原则。
机械同理心:软硬件协同设计
Mechanical Sympathy: Hardware-Software Codesign
*Mechanical sympathy *is a term originally coined by software engineer Martin Thompson, who was drawing an analogy to the British Formula One champion Jackie Stewart, who intimately understood his cars’ mechanical details. In computing, it refers to writing software that is deeply aware of the hardware it runs on. In the AI context, it means codesigning algorithms hand in hand with hardware capabilities to maximize performance.*机械同理心*一词最初由软件工程师 Martin Thompson 提出,他借此类比英国一级方程式冠军 Jackie Stewart——后者对赛车的机械细节了如指掌。在计算领域,它指编写能够深刻感知其所运行硬件的软件。在 AI 领域,它意味着让算法与硬件能力携手协同设计,以最大化性能。
Real-world experience has shown that even minor tweaks in GPU kernels or memory access patterns can produce outsized gains. A classic example is FlashAttention, a novel algorithm that reimplements the transformer attention mechanism in a hardware-aware way.实践经验表明,即便对 GPU 内核或显存访问模式做微小的调整,也可能带来超乎寻常的收益。一个经典例子是 FlashAttention,这是一种以硬件感知的方式重新实现 Transformer 注意力机制的新型算法。
FlashAttention “tiles” GPU computations, which minimizes the number of reads and writes issued to the GPU’s memory. FlashAttention significantly reduces memory movement and speeds up attention computation. Replacing the default transformer attention mechanism/algorithm with FlashAttention produces a 2×–4× speedup in training and inference for long sequences while also reducing the overall memory footprint.FlashAttention 对 GPU 计算进行“分块”(tile),从而将向 GPU 显存发出的读写次数降至最低。FlashAttention 显著减少了内存数据搬运,并加快了注意力计算。用 FlashAttention 替换默认的 Transformer 注意力机制/算法,可在长序列的训练和推理中带来 2×–4× 的加速,同时降低整体显存占用。
This kind of change reduces what used to be a major bottleneck (attention) down to a fraction of overall runtime. FlashAttention became the default in many libraries almost overnight because it let models handle longer sequences faster and more efficiently. Since FlashAttention, many new attention algorithms have emerged, including DeepSeek’s Multi-Head Latent Attention (MLA).这类改动把过去的主要瓶颈(注意力)压缩到整体运行时长的很小一部分。FlashAttention 几乎在一夜之间成为许多库中的默认实现,因为它让模型能够更快、更高效地处理更长的序列。自 FlashAttention 之后,涌现出许多新的注意力算法,包括 DeepSeek 的多头潜在注意力(Multi-Head Latent Attention,MLA)。
DeepSeek’s MLA algorithm—implemented as an NVIDIA GPU kernel and open sourced in 2025—is another example of hardware-software codesign, or mechanical sympathy. Similar to FlashAttention, MLA restructures the attention computations to better utilize NVIDIA’s memory hierarchy and dedicated GPU “Tensor Cores.” These optimizations allowed MLA to exploit the constrained H800 GPUs’ architecture, achieving higher throughput at a fraction of the cost—surpassing even FlashAttention’s performance on those same H800 systems.DeepSeek 的 MLA 算法——以 NVIDIA GPU 内核实现并于 2025 年开源——是硬件-软件协同设计(或称机械同理心)的又一个例子。与 FlashAttention 类似,MLA 重构了注意力计算,以更好地利用 NVIDIA 的内存层级和专用的 GPU“张量核心”。这些优化使 MLA 能够充分利用受限的 H800 GPU 架构,以极小的成本实现更高的吞吐量——在同样的 H800 系统上甚至超越了 FlashAttention 的性能。
This entire book is effectively a study in mechanical sympathy. We will see countless cases where new hardware features—or hardware constraints, as in the case of DeepSeek—inspire novel new software and algorithmic techniques. Conversely, we’ll see where new software algorithms encourage new hardware innovations.整本书实际上就是一项关于机械同理心的研究。我们将看到无数案例:新的硬件特性——或者如 DeepSeek 案例中的硬件约束——催生出新颖的软件与算法技术。反过来,我们也会看到新的软件算法如何推动新的硬件创新。
For instance, the rise of transformer models and reduced-precision quantization (e.g., FP8/FP4) led NVIDIA to add specialized hardware like the Transformer Engine and dedicated reduced-precision Tensor Cores for faster matrix-math computation units. These hardware innovations, in turn, enable researchers to explore novel numeric optimizers and neural-network architectures. This, then, pushes hardware designers even further, which then unlocks even newer algorithms, etc. It’s a virtuous cycle!例如,Transformer 模型的兴起与低精度量化(如 FP8/FP4)促使 NVIDIA 增加了 Transformer Engine 和专用低精度张量核心等专用硬件,以实现更快的矩阵数学计算单元。这些硬件创新反过来又使研究人员能够探索新颖的数值优化器和神经网络架构。这又进一步推动硬件设计者前进,从而解锁更新的算法,如此循环。这是一个良性循环!
Modern GPUs use the latest Transformer Engine with FP4 support and microscaling. Combined with the latest generation NVLink, these features increase attention throughput primarily through faster Tensor Core math, higher memory bandwidth, and improved Special Function Units (SFUs.) For instance, the exponential computation unit is specifically designed to accelerate the softmax operation used heavily by the transformer’s attention algorithm—a key part of today’s LLM models. With the popularity of transformers, softmax latency had become a bottleneck on previous GPUs, given that it’s critical to the transformer attention mechanism.现代 GPU 采用支持 FP4 和微缩放(microscaling)的最新一代 Transformer Engine。结合最新一代 NVLink,这些特性主要通过更快的张量核心数学运算、更高的显存带宽以及改进的专用函数单元(Special Function Unit,SFU)来提升注意力吞吐量。例如,指数计算单元专门用于加速 Transformer 注意力算法大量使用的 softmax 运算——这是当今 LLM 模型的关键部分。随着 Transformer 的流行,softmax 时延在之前的 GPU 上已成为瓶颈,因为它对 Transformer 注意力机制至关重要。
This tight interplay—GPUs and AI algorithms coevolving—is the heart of mechanical sympathy in AI. These codesign innovations can happen only with close collaboration between the hardware companies (e.g., NVIDIA and Advanced RISC Machine [ARM]), AI research labs (e.g., OpenAI and Anthropic), and AI systems performance engineers (e.g., us!).这种紧密的相互作用——GPU 与 AI 算法共同演进——正是 AI 中机械同理心的核心。这类协同设计创新只有在硬件公司(如 NVIDIA 和 Advanced RISC Machine [ARM])、AI 研究实验室(如 OpenAI 和 Anthropic)以及 AI 系统性能工程师(比如我们!)之间紧密协作下才能发生。
衡量“有效吞吐”:有用的吞吐量
Measuring “Goodput” Useful Throughput
When operating clusters of hundreds, thousands, or millions of GPUs, it’s important to understand how much of the theoretical hardware capability is actually performing useful work. Traditional throughput metrics like FLOPS and device utilization are misleadingly high, as much of the time is likely spent on stalled communication, idling computation, or failed job restarts. This is where the concept of “goodput” comes in—as described by Meta as “effective training-time ratio” in a 2025 paper.在运营数百、数千乃至数百万块 GPU 的集群时,理解理论硬件能力中有多少真正在做有用的工作非常重要。FLOPS 和设备利用率等传统吞吐量指标会高得具有误导性,因为大量时间很可能花在停滞的通信、空转的计算或失败作业的重启上。这正是“有效吞吐”(goodput)概念的用武之地——Meta 在 2025 年的一篇论文中将其描述为“有效训练时间比”。
In simple terms, goodput measures the throughput of useful work completed (number of tokens processed or inference requests completed) per unit time—discounting everything that doesn’t directly contribute to model training or inference. It’s effectively the end-to-end efficiency of the system from the perspective of productive model training or inference. Goodput can then be normalized by the cluster’s maximum possible throughput to produce a percent efficiency value.简而言之,有效吞吐衡量的是单位时间内完成的有用工作量(处理的 token 数量或完成的推理请求数)的吞吐量——扣除一切不直接贡献于模型训练或推理的部分。它实际上是从有效模型训练或推理的角度看系统的端到端效率。随后可以将有效吞吐按集群的最大可能吞吐量归一化,得到一个百分比效率值。
For example, suppose a node with 8 GPUs can process 100,000 tokens in 10 seconds. In this case, its goodput is 10,000 tokens per second. If each GPU in the node can achieve a peak theoretical throughput of 1,500 tokens per second, or 12,000 tokens per second across all 8 GPUs, the node’s efficiency is 83.3% (0.833 = 10,000 achieved throughput/12,000 peak throughput).例如,假设一个拥有 8 块 GPU 的节点能在 10 秒内处理 100,000 个 token。此时其有效吞吐为每秒 10,000 个 token。如果该节点中每块 GPU 的峰值理论吞吐为每秒 1,500 个 token,即 8 块 GPU 合计每秒 12,000 个 token,则该节点的效率为 83.3%(0.833 = 10,000 实际吞吐/12,000 峰值吞吐)。
Meta’s AI infrastructure team highlighted the importance of goodput in the “Revisiting Reliability” paper. The paper introduces the effective training time ratio metric and shows how preemptions resource fragmentation and failures reduce realized training time even when headline utilization is high. In this paper, Meta’s team analyzes how preemptions, hardware faults, and network congestion reduce realized throughput.Meta 的 AI 基础设施团队在《Revisiting Reliability》论文中强调了有效吞吐的重要性。该论文引入了*有效训练时间比指标*,并展示了即使表面利用率很高,抢占、资源碎片化和故障也会如何减少实际训练时间。在这篇论文中,Meta 团队分析了抢占、硬件故障和网络拥塞如何降低实际吞吐。
In other words, while the cluster appeared to be 100% utilized, 70%–75% of the compute was lost due to overheads like communication delays, suboptimal parallelization, data delays, or failure recovery. Additionally, Meta’s analysis showed that, at scale, issues like job preemptions, network hotspots, and unrecoverable faults were major contributors to lost goodput.换句话说,虽然集群看起来利用率达到 100%,但由于通信延迟、并行化不理想、数据延迟或故障恢复等开销,70%–75% 的算力被损失掉了。此外,Meta 的分析表明,在大规模场景下,作业抢占、网络热点和不可恢复故障是有效吞吐损失的主要来源。
For example, imagine a training job that could theoretically process 1,000 samples/ second on ideal hardware, but due to a poor input pipeline and excessive synchronization, it achieves only 300 samples/second of actual training throughput. We’d say that the job is running at 30% goodput. The remaining 70% capacity is essentially wasted.例如,设想一个训练作业在理想硬件上理论上每秒可处理 1,000 个样本,但由于输入流水线不佳和过度同步,实际训练吞吐仅达到每秒 300 个样本。我们会说该作业以 30% 的有效吞吐运行。剩余 70% 的容量实际上被浪费了。
Identifying these gaps and closing them is a core part of our work. For instance, if GPUs are waiting on data loading from storage, we might introduce caching or async prefetch. If they’re idling during the gradient synchronization step of our model training process, we likely want to overlap the GPU computation (e.g., calculating the gradients) with the communication between GPUs (e.g., synchronizing the gradients). Our goal is to turn wasted, inefficient cycles into useful work.识别这些差距并弥合它们是我们工作的核心部分。例如,如果 GPU 在等待从存储加载数据,我们可能会引入缓存或异步预取。如果它们在模型训练过程的梯度同步步骤中空闲,我们通常希望将 GPU 计算(例如计算梯度)与 GPU 之间的通信(例如同步梯度)重叠起来。我们的目标是把被浪费的低效周期转化为有用工作。
This gap between theoretical and realized performance is the value proposition of the AI systems performance engineer role. Our mission is to drive that goodput number as high as possible—ideally increasing it closer to 100%—by attacking inefficiencies and reducing cost at every level of the stack, including hardware, software, and algorithms.理论性能与实际性能之间的这一差距,正是 AI 系统性能工程师这一角色的价值所在。我们的使命是尽可能提高有效吞吐这一数字——理想情况下使其接近 100%——方法是在技术栈的每一层(包括硬件、软件和算法)消除低效并降低成本。
By focusing on goodput, we are optimizing what truly matters—the amount of useful training done per dollar of cost and per joule of power. Goodput is the ultimate metric of success—more so than raw FLOPS or device utilization—because it encapsulates how well hardware, software, and algorithms are harmonized toward the end goal of training AI models faster and cheaper.通过关注有效吞吐,我们优化的是真正重要的东西——每美元成本和每焦耳电力所完成的有用训练量。有效吞吐是衡量成功的终极指标——比原始 FLOPS 或设备利用率更重要——因为它体现了硬件、软件和算法在更快、更便宜地训练 AI 模型这一最终目标上的协同程度。
Improving goodput requires a deep understanding of the interactions between the hardware (e.g., CPUs, GPUs, network topologies, memory hierarchies, storage layouts), software (e.g., operating system configurations, paged memory, I/O utilization), and algorithms (e.g., transformer architecture variants, attention mechanism alternatives, and different caching and batching strategies).提升有效吞吐需要深入理解硬件(例如 CPU、GPU、网络拓扑、显存层次结构、存储布局)、软件(例如操作系统配置、分页内存、I/O 利用率)与算法(例如 Transformer 架构变体、注意力机制替代方案,以及不同的缓存与批处理策略)之间的相互作用。
This broad and deep understanding of multiple disciplines—including hardware, software, and algorithms—is why AI systems performance engineers are so scarce today. This is also why I’m writing this book! Next is the roadmap and methodology that maps out the rest of this book.正是这种横跨硬件、软件与算法等多个学科的广博而深入的理解,使得 AI 系统性能工程师在今天如此稀缺。这也是我撰写本书的原因!接下来是本书其余部分的路线图与方法论。
本书路线图与方法论
Book Roadmap and Methodology
How will we approach the optimization of 100-trillion-parameter AI systems? This book is organized to take you from the hardware fundamentals up through the software stack and algorithmic techniques—with an emphasis on hands-on analysis at each level. Here is a breakdown of the rest of the book.我们将如何着手优化百万亿参数级别的 AI 系统?本书的组织方式将带你从硬件基础出发,逐层深入到软件栈与算法技术,并强调在每一层进行动手分析。以下是本书其余部分的分解说明。
Chapter 2 provides an in-depth look at NVIDIA AI system hardware, including the GB200/GB300 NVL72 “AI supercomputer in a rack,” which combines Grace Blackwell Superchip design with the NVLink network to create performance/power characteristics of an AI supercomputer.第 2 章深入介绍 NVIDIA AI 系统硬件,包括 GB200/GB300 NVL72“机架级 AI 超级计算机”,它将 Grace Blackwell 超级芯片设计与 NVLink 网络相结合,从而具备 AI 超级计算机的性能与功耗特性。
Chapters 3–5 will then cover OS-level, networking, and storage optimizations for GPU-based AI systems. These optimizations include CPU and memory pinning, as well as Docker container and Kubernetes orchestration considerations, including network I/O and storage configurations for GPU environments.第 3 至第 5 章将涵盖面向基于 GPU 的 AI 系统的操作系统级、网络与存储优化。这些优化包括 CPU 与内存绑核,以及 Docker 容器与 Kubernetes 编排方面的考量,包括 GPU 环境下的网络 I/O 与存储配置。
Chapters 6–12 discuss NVIDIA CUDA programming fundamentals and CUDA-kernel optimizations that are essential for developing novel hardware-aware algorithms. Such popular algorithms include FlashAttention and DeepSeek’s MLA. These algorithms target the resource-intensive attention mechanism of the transformer architecture, which dominates today’s generative AI workloads.第 6 至第 12 章讨论 NVIDIA CUDA 编程基础与 CUDA 内核优化,这些内容对于开发新颖的硬件感知算法至关重要。此类流行算法包括 FlashAttention 和 DeepSeek 的 MLA。这些算法针对的是 Transformer 架构中资源密集的注意力机制,而该机制主导着当今的生成式 AI 工作负载。
With NVIDIA hardware and CUDA software context in hand, we’ll dive into distributed communication optimizations, including training and serving ultralarge models efficiently. We’ll examine strategies to minimize communication, such as overlapping computation with communication—a pattern that applies to many layers of the AI system stack.在掌握了 NVIDIA 硬件与 CUDA 软件背景之后,我们将深入探讨分布式通信优化,包括高效地训练与服务超大规模模型。我们将考察最小化通信的策略,例如将计算与通信重叠——这一模式适用于 AI 系统栈的许多层次。
Chapters 13 and 14 discuss PyTorch-specific optimizations, including the PyTorch compiler stack and OpenAI’s Python-based Triton language and compiler for custom GPU kernels. These compilers lower the barrier for developing novel CUDA kernels, as they don’t require a deep understanding of C++ typically required to develop CUDA kernels. These chapters also discuss distributed parallelization techniques for model training, including data parallelism (DP), fully sharded data parallelism (FSDP), tensor parallelism (TP), pipeline parallelism (PP), context parallelism (CP), and mixture-of-experts (MoE). We will show how multi-trillion-parameter models are split and trained across many GPUs efficiently. And we will discuss techniques for memory optimization during ultrascale model training, including activation checkpointing, sharding optimizer states, and offloading to larger CPU memory. These techniques are vital when model sizes exceed the physical GPU hardware limits.第 13 章和第 14 章讨论 PyTorch 特有的优化,包括 PyTorch 编译器栈,以及 OpenAI 基于 Python 的 Triton 语言与编译器(用于自定义 GPU 内核)。这些编译器降低了开发新颖 CUDA 内核的门槛,因为它们不要求开发者具备开发 CUDA 内核通常所需的深厚 C++ 功底。这两章还讨论用于模型训练的分布式并行化技术,包括数据并行(DP)、完全分片数据并行(FSDP)、张量并行(TP)、流水线并行(PP)、上下文并行(CP)以及混合专家(MoE)。我们将展示万亿参数级模型如何被切分并高效地跨众多 GPU 训练。此外,我们还将讨论超大规模模型训练期间的内存优化技术,包括激活检查点、优化器状态分片,以及卸载到更大的 CPU 内存。当模型规模超出 GPU 硬件的物理限制时,这些技术至关重要。
Chapters 15–19 focus on software and algorithmic innovations for high-throughput, low-latency model inference and agentic AI systems. This includes disaggregated prefill and decode, which is now supported in NVIDIA Dynamo and community stacks with key-value (KV) cache movement over UCX with GPUDirect RDMA, NCCL point-to-point, or framework-provided transports. We also discuss the widely used model serving engines, including vLLM, SGLang, and NVIDIA TensorRT LLM. We then cover the NVIDIA Dynamo distributed inference framework, which integrates with these engines and includes NIXL for low-latency KV cache transfer in disaggregated prefill decode setups.第 15–19 章聚焦于面向高吞吐、低时延模型推理与智能体 AI 系统的软件与算法创新。其中包括解耦的预填充与解码,NVIDIA Dynamo 与社区技术栈现已支持该方式,可通过基于 GPUDirect RDMA 的 UCX、NCCL 点对点或框架自带的传输方式移动键值(KV)缓存。我们还将讨论广泛使用的模型服务引擎,包括 vLLM、SGLang 和 NVIDIA TensorRT LLM。随后介绍 NVIDIA Dynamo 分布式推理框架,它与这些引擎集成,并包含 NIXL,用于在解耦预填充-解码配置中实现低时延 KV 缓存传输。
We’ll also look at leveraging the Grace CPU in the NVL72 for preprocessing, corunning smaller “draft” models for high-performance inference algorithms such as speculative decoding, and efficient request routing and batching to maximize overall throughput of the inference system. We will also explore model compression and acceleration techniques such as 4-bit quantization, knowledge distillation to teach smaller “student” models from wiser “teacher” models, sparsity and pruning, and the use of specialized TensorRT kernels. There is a heavy focus on disaggregated prefill-decode and adaptive techniques to dynamically tune a system at runtime.我们还将探讨如何利用 NVL72 中的 Grace CPU 进行预处理、协同运行较小的“草稿”模型以支持投机解码等高性能推理算法,以及通过高效的请求路由与批处理来最大化推理系统的整体吞吐量。我们还将探索模型压缩与加速技术,例如 4 位量化、用更聪明的“教师”模型教导较小“学生”模型的知识蒸馏、稀疏性与剪枝,以及专用 TensorRT 内核的使用。本章重点聚焦解耦的预填充-解码,以及在运行时动态调优系统的自适应技术。
Chapter 20 describes modern efforts to use AI-assisted tools to optimize kernel and AI system performance. The chapter also includes case studies on training and serving multi-billion- and multi-trillion-parameter models efficiently. It also covers emerging trends for self-improving AI system optimizations and agents. This helps to paint a picture of where 100-trillion-parameter-scale AI systems are headed—and how to position ourselves for the future of AI systems performance engineering.第 20 章介绍利用 AI 辅助工具优化内核与 AI 系统性能的最新实践。本章还包含高效训练与服务数十亿乃至数万亿参数模型的案例研究,并涵盖自我改进的 AI 系统优化与智能体的新兴趋势。这有助于勾勒出 100 万亿参数规模 AI 系统的发展方向——以及我们该如何为 AI 系统性能工程的未来做好准备。
The Appendix provides a checklist of common performance-optimization and cost-saving tips and tricks to apply to your own AI system. This is a summary of actionable optimizations and efficiency gains discussed throughout this book.附录提供了常见性能优化与节省成本技巧的清单,可应用于你自己的 AI 系统。这是对全书讨论的可操作优化与效率提升的总结。
In short, this book implements a hands-on and empirical methodology to apply performance optimizations. We will frequently analyze actual runs, case studies, benchmark results, and profiling data to understand bottlenecks and verify improvements. By the end of the book, you should grasp the principles of optimizing ultralarge AI systems—as well as gain some practical experience with tools to apply those optimizations on ultrascale, multi-GPU, multinode, and multirack AI systems like the NVIDIA GB200/GB300 NVL72 AI supercomputer in a rack—or similar AI systems now and in the future.简而言之,本书采用动手实践与实证的方法来实施性能优化。我们将频繁分析实际运行、案例研究、基准测试结果与性能剖析数据,以理解瓶颈并验证改进。读完本书后,你应当掌握优化超大型 AI 系统的原理,并在使用相关工具方面获得实践经验,从而将这些优化应用于超大规模、多 GPU、多节点、多机架的 AI 系统——例如单机架的 NVIDIA GB200/GB300 NVL72 AI 超级计算机——以及现在与未来的类似 AI 系统。
关键要点
Key Takeaways
The following qualities collectively define the role of the AI systems performance engineer, whose expertise in merging deep technical knowledge with strategic, profile-driven optimizations transforms raw hardware into cost-effective, high-performance AI solutions:以下特质共同定义了 AI 系统性能工程师这一角色:他们善于将深厚的技术知识与战略性、基于性能剖析的优化相结合,把原始硬件转化为高性价比、高性能的 AI 解决方案:
- Measure goodput测量有效吞吐
- Look beyond raw FLOPS or utilization. Instead, measure the ratio of time the GPU spends performing useful work (e.g., forward/backprop computations) versus waiting on data or other overhead. Use NVIDIA Nsight Systems/Compute or PyTorch profiler to measure this ratio. Strive to improve this ratio, as goodput focuses on effective, useful GPU utilization.不要只看原始 FLOPS 或利用率。相反,应测量 GPU 用于执行有用工作(例如前向/反向传播计算)的时间与等待数据或其他开销的时间之比。使用 NVIDIA Nsight Systems/Compute 或 PyTorch profiler 测量这一比例。努力提升这一比例,因为有效吞吐关注的是有效、有用的 GPU 利用率。
- Prefer skillful engineering optimizations instead of brute-force spending优先采用精巧的工程优化,而非蛮力式投入。
- More hardware isn’t a silver bullet. Clever software and system optimizations can bridge the gap when hardware is limited, enabling results that would otherwise require far more expensive infrastructure. We saw this with DeepSeek’s achieve-ment. By optimizing communication and hardware usage, their engineers trained a frontier model on restricted H800 GPUs (with limited interconnect bandwidth) at a fraction of the cost. The DeepSeek model matched the performance of frontier更多硬件不是银弹。巧妙的软件和系统优化可以在硬件受限时弥合差距,实现原本需要昂贵得多的基础设施才能取得的结果。我们在 DeepSeek 的成就中看到了这一点。通过优化通信和硬件使用,其工程师在受限的 H800 GPU(互连带宽有限)上以一小部分成本训练了一个前沿模型。DeepSeek 模型的性能与在远更强大硬件上训练的前沿
models trained on far more powerful hardware. In other words, skillful engineering outperformed brute-force spending.模型相匹配。换言之,精湛的工程能力胜过了蛮力式支出。
- Look for order-of-magnitude impact with incremental optimizations关注增量优化带来的数量级影响
- At scale, even a small-percentage efficiency gain can save millions of dollars. Said differently, small inefficiencies such as redundant computations and slow data pipelines can silently increase costs as the system scales.在规模化场景下,即使百分比很小的效率提升也能节省数百万美元。换句话说,冗余计算和慢速数据管道等微小低效会在系统扩展时悄然增加成本。
- Approach performance tuning with a profile-driven mindset以剖析驱动的思维方式开展性能调优
- Use data and profiling tools to guide optimizations. Use profilers to identify the true bottlenecks—whether it’s compute utilization, memory bandwidth, memory latency, cache misses, or communication/network delays. Then apply targeted optimizations for that bottleneck.使用数据和性能剖析工具指导优化。使用性能剖析器识别真正的瓶颈——无论是计算利用率、显存带宽、内存时延、缓存未命中,还是通信/网络延迟。然后针对该瓶颈应用定向优化。
- Maintain a holistic view保持全局视角
- Improving AI systems performance spans hardware, including the GPU, CPU, memory, and network—as well as software such as algorithms and libraries. A weakness in any layer can bottleneck the whole. The best performance engineers consider hardware-software codesign: sometimes algorithm changes can alleviate hardware limits, and sometimes new hardware features enable new algorithms.提升 AI 系统性能涵盖硬件(包括 GPU、CPU、内存和网络)以及算法和库等软件。任何一层的弱点都可能成为整体瓶颈。最优秀的性能工程师会考虑硬件-软件协同设计:有时算法变更可以缓解硬件限制,有时新硬件特性可以催生新算法。
- Stay informed on the latest hardware, software, and algorithms持续关注最新的硬件、软件和算法
- Modern AI hardware and software are evolving rapidly. New capabilities such as unified CPU-GPU memory, faster interconnects, and novel numerical-precision formats can change the optimal strategies. A good performance engineer keeps an eye on these and updates their mental models accordingly to eliminate bottlenecks quickly. Additionally, the MLPerf benchmark suites are a great resource to understand AI hardware performance for various models.现代 AI 硬件和软件正在快速演进。CPU-GPU 统一内存、更快的互连以及新的数值精度格式等新能力可以改变最优策略。优秀的性能工程师会关注这些变化,并相应更新心智模型,以快速消除瓶颈。此外,MLPerf 基准测试套件是了解各种模型的 AI 硬件性能的重要资源。
结语
Conclusion
This introductory analysis underscores that optimizations are not optional at large scale—they are absolutely necessary. It is the difference between a system that works and one that is utterly impractical. Traditional approaches, whether in hardware or algorithms, break down at this scale. To push forward, we need both advanced hardware and smart software techniques.这一入门分析强调,在大规模场景下优化并非可选项——而是绝对必要的。它决定了系统是可用,还是完全不可行。传统方法,无论是硬件还是算法层面,在这种规模下都会失效。要向前推进,我们既需要先进硬件,也需要巧妙的软件技术。
It’s clear that AI models are pushing physical resource limits. Hardware is racing to keep up with new model architectures and algorithms. And performance engineers are the ones in the driver’s seat to ensure that all this expensive machinery is actually delivering results.显然,AI 模型正在逼近物理资源的极限。硬件正在竞相追赶新的模型架构与算法。而性能工程师正是掌舵者,确保所有这些昂贵的机器真正产出结果。
We have demonstrated that the role of the AI systems performance engineer is gaining more and more importance. Simply throwing money and hardware at the problem is not enough. We need to co-optimize everything—model architectures, algorithms, hardware, and system design—to push toward the next leaps in AI capability.我们已经说明,AI 系统性能工程师的角色正变得越来越重要。仅仅向问题投入资金和硬件是不够的。我们需要协同优化一切——模型架构、算法、硬件与系统设计——以推动 AI 能力实现下一次跃升。
As an AI systems performance engineer, your job is multidisciplinary, complex, and dynamic. You will dive into GPU profiling one day, network topology the next day, and perhaps algorithmic complexity the following day. This is a role for a “full-stack” performance geek who loves to squeeze out every drop of available performance from both hardware and software.作为 AI 系统性能工程师,你的工作是跨学科的、复杂的且动态变化的。你可能今天深入 GPU 性能剖析,明天研究网络拓扑,后天又要分析算法复杂度。这个角色适合热爱从硬件和软件中榨取每一滴可用性能的“全栈”性能极客。
In essence, an AI systems performance engineer’s mantra is “mechanical sympathy.” We deeply understand the machinery—both hardware and software—so that we can tailor efficient solutions that exploit the entire stack’s performance capabilities to the fullest.本质上,AI 系统性能工程师的信条是「机械同理心(mechanical sympathy)」。我们深入理解机器——包括硬件与软件——从而能够量身定制高效的解决方案,最大限度地发挥整个技术栈的性能潜力。
As we saw earlier, a 100-trillion-parameter model is well beyond the reach of today’s hardware—even an exascale system would require several millennia of GPU time for one training run. This is clearly impractical, underscoring why we need both advanced hardware and clever software optimizations to ever reach this scale.正如我们此前所见,一个 100 万亿参数的模型远远超出了当今硬件的能力范围——即便是一台百亿亿次(exascale)级系统,完成一次训练也需要数千年的 GPU 时间。这显然不切实际,也凸显出为何我们必须同时依靠先进硬件与巧妙的软件优化,才有可能达到这一规模。
In the coming chapters, we will demonstrate how to break down the components of an AI system from processors to memory to interconnects to software frameworks— and learn how to optimize each component in a principled way. We’ll study concrete case studies where making small changes brings about huge performance and cost improvements. Doing so, we will help create a mental model for reasoning about performance optimization along multiple dimensions.在接下来的章节中,我们将演示如何把 AI 系统的各个组成部分——从处理器到内存、从互连到软件框架——逐一拆解,并学习如何以有原则的方式优化每一个组件。我们将研究具体的案例,其中微小的改动带来了性能与成本上的巨大改善。在此过程中,我们将帮助读者建立一个心智模型,用于从多个维度推理性能优化问题。
By the end of this journey, you as a reader and practitioner will be equipped with knowledge of today’s best practices as well as an engineering mindset to tackle tomorrow’s challenges. You will have an arsenal of techniques to push AI systems to their limits—now and in the future. For AI systems performance engineers, the mandate is clear. We must learn from these innovations and be ready to apply aggressive optimizations at every level of the stack.走完这段旅程后,作为读者与实践者的你将掌握当今最佳实践的知识,并具备应对未来挑战的工程思维。你将拥有一套技术武器库,能够在当下与未来把 AI 系统推向极限。对 AI 系统性能工程师而言,使命十分明确:我们必须从这些创新中学习,并随时准备在技术栈的每一层实施激进的优化。
Now, with the context established, let’s dive into the hardware components of modern AI systems, including the CPUs, GPUs, memory technologies, network fabrics, and storage mechanisms. By studying the components that underpin contemporary AI supercomputers, you will learn the fundamentals that provide the foundation of subsequent deep dives into optimization techniques in later chapters.现在,背景已经建立,让我们深入现代 AI 系统的硬件组件,包括 CPU、GPU、内存技术、网络结构(network fabric)与存储机制。通过研究支撑当代 AI 超级计算机的这些组件,你将掌握基础知识,为后续章节深入探讨优化技术奠定根基。