高级预填充-解码与 KV 缓存调优
Chapter 18. Advanced Prefill-Decode and KV Cache Tuning
本章目录
This chapter builds upon Chapter 17 and dives deeper into advanced optimizations for the inference prefill and decode phases. We’ll build upon the high-level scaling strategies and cover low-level techniques, including single decode “mega kernels,” intelligent KV cache tuning and sharing across GPUs, fast GPU-to-GPU transfer of the prompt state, adaptive resource scheduling, and dynamic routing between prefill and decode workers.本章以第 17 章为基础,深入探讨推理预填充与解码阶段的高级优化。我们将在高层扩展策略的基础上继续展开,并涵盖底层技术,包括单次解码的“巨型内核(mega kernel)”、智能的 KV 缓存调优与跨 GPU 共享、提示状态的 GPU 间快速传输、自适应资源调度,以及预填充与解码工作节点之间的动态路由。
We will also highlight hardware and software innovations, which provide new levels of performance and efficiency. By applying these techniques, you can significantly reduce decode latency, improve throughput per GPU, and meet strict latency SLOs at scale.我们还将重点介绍硬件与软件创新,它们带来了全新水平的性能与效率。通过应用这些技术,你可以显著降低解码时延、提升每 GPU 吞吐量,并在大规模下满足严格的时延 SLO。
优化的解码内核
Optimized Decode Kernels
Until now, we have been focused on high-level system and cluster optimization strategies. Another set of techniques to consider when increasing ultrascale inference is low-level kernel and memory management tuning—especially for the decode phase.到目前为止,我们一直聚焦于高层系统与集群优化策略。在提升超大规模推理时,另一类值得考虑的技术是底层内核与内存管理调优——尤其是针对解码阶段。
The decode phase is distributed and often memory bound. This has motivated researchers and practitioners to make the decode phase as fast as possible—and tuned for specific hardware. Two notable innovations in this space are FlashMLA (Deep-Seek), ThunderMLA (Stanford), and FlexDecoding (PyTorch). These specifically target the transformer’s multihead attention efficiency during decode in variable-sequence scenarios common in LLM workloads. Let’s cover each of these next.解码阶段是分布式的,且通常是显存受限的。这促使研究者和工程实践者尽可能让解码阶段变快——并针对特定硬件进行调优。该领域两项值得关注的创新是 FlashMLA(DeepSeek)、ThunderMLA(Stanford)和 FlexDecoding(PyTorch)。它们专门针对 LLM 工作负载中常见的变长序列场景下 Transformer 多头注意力在解码时的效率。下面我们逐一介绍。
FlashMLA(DeepSeek)
FlashMLA (DeepSeek)
Flash Multi-Latent Attention, or FlashMLA, is an optimized decoding kernel introduced by DeepSeek. It specifically focuses on the single-token decode step, which is essentially the forward pass of a transformer layer used to generate the next token. FlashMLA makes decode faster by fusing operations and better using the GPU memory hierarchy.Flash 多潜在注意力(Flash Multi-Latent Attention,FlashMLA)是 DeepSeek 提出的优化解码内核。它专门聚焦于单 token 解码步骤,这本质上就是用于生成下一个 token 的 Transformer 层前向传播。FlashMLA 通过融合算子并更好地利用 GPU 显存层次结构来加速解码。
FlashMLA (decode) is to inference what FlashAttention (prefill) is to training. It reduces memory access overhead and latency. With FlashMLA, you can achieve large latency reductions for the decode phase compared to standard kernels.FlashMLA(解码)之于推理,正如 FlashAttention(预填充)之于训练。它降低了显存访问开销与时延。借助 FlashMLA,相比标准内核,你可以在解码阶段实现大幅的时延降低。
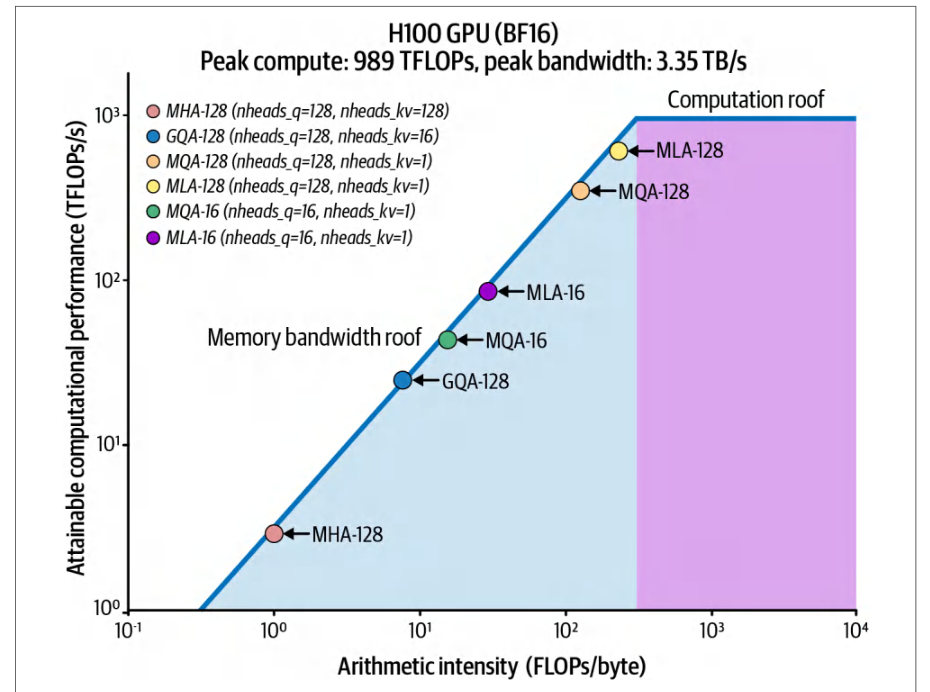
FlashMLA increases arithmetic intensity by fusing multiple attention operations into one. This way, it can process multiple heads and multiple time steps in one fused kernel launch. This increases GPU utilization during the decode by keeping the math units busy despite small batch sizes. Figure 18-1 shows the improvement in arithmetic intensity for MLA compared to other attention implementations like grouped-query attention (GQA) and multiquery attention (MQA) on a Hopper H100 GPU. (Note: Blackwell shifts both rooflines upward with higher TFLOPs and HBM bandwidth.)FlashMLA 通过将多个注意力算子融合为一个来提升算术强度。这样,它就能在一次融合内核启动中处理多个头和多个时间步。尽管批大小很小,它仍能让数学运算单元保持忙碌,从而提升解码期间的 GPU 利用率。图 18-1 展示了在 Hopper H100 GPU 上,MLA 相比分组查询注意力(GQA)和多查询注意力(MQA)等其他注意力实现在算术强度上的提升。(注:Blackwell 凭借更高的 TFLOPs 和 HBM 带宽将两条屋顶线整体上移。)
The introduction of FlashMLA was significant because it showed that the decode phase’s bottlenecks, memory bandwidth, and kernel-launch overhead can be reduced—even on suboptimal GPU hardware. It reduced the number of separate GPU kernel launches and optimized memory access patterns—squeezing as much performance out of constrained hardware as possible for decoding tasks.FlashMLA 的推出意义重大,因为它表明解码阶段的瓶颈——显存带宽和内核启动开销——是可以被降低的,即便在非最优的 GPU 硬件上也是如此。它减少了独立的 GPU 内核启动次数,并优化了显存访问模式——在受限硬件上为解码任务尽可能榨取性能。
DeepSeek’s open sourced FlashMLA implementation is available and seeing adoption. SGLang and vLLM both provide first-class support for DeepSeek models. As such, you should evaluate FlashMLA to increase per-token decode throughput without changing higher-level architecture.DeepSeek 开源的 FlashMLA 实现已可用,并正在被采用。SGLang 和 vLLM 都为 DeepSeek 模型提供了一流的支持。因此,你应当评估 FlashMLA,以在不改变高层架构的前提下提升每 token 的解码吞吐量。
Since DeepSeek’s open sourced FlashMLA is integrated into modern inference serving systems, you should explore it as a way to increase the throughput of each decode worker—or reduce latency per token—without any higher-level architectural change.由于 DeepSeek 开源的 FlashMLA 已集成到现代推理服务系统中,你应当探索它,作为在无需任何高层架构改动的情况下提升每个解码工作节点吞吐量——或降低每 token 时延——的一种途径。
ThunderMLA(Stanford)
ThunderMLA (Stanford)
Building on FlashMLA, researchers at Stanford introduced ThunderMLA, a completely fused attention decode “megakernel” that focuses on decoding and scheduling (rather than fusing the full feed-forward block.) This “megakernel” reduces launch overhead and tail effects by combining multiple kernel launches into one—as well as consolidating intermediate memory writes. ThunderMLA reports 20–35% faster decode throughput compared to FlashMLA across different workloads在 FlashMLA 的基础上,斯坦福的研究人员提出了 ThunderMLA,这是一个完全融合的注意力解码“巨型内核(megakernel)”,聚焦于解码与调度(而非融合整个前馈块)。这个“巨型内核”通过将多次内核启动合并为一次来降低启动开销与尾部效应,同时也整合了中间内存写入。ThunderMLA 报告称,在不同工作负载下,其解码吞吐量相比 FlashMLA 快 20–35%
The key idea of ThunderMLA is that when decoding sequences of different lengths, using fine-grained scheduling and fused operations can avoid the tail effect in which some sequences finish earlier while others leave the GPU partially idle. ThunderMLA keeps the GPU busy even if some decode streams complete earlier. It does this by dynamically packing and processing the remaining streams using its fused approach.ThunderMLA 的核心思想是:在解码不同长度的序列时,采用细粒度调度与融合操作可以避免尾部效应——即某些序列提前完成,而另一些序列使 GPU 部分空闲。即使某些解码流提前完成,ThunderMLA 也能让 GPU 保持忙碌。它通过其融合方法动态打包并处理剩余的流来实现这一点。
These benefits are amplified on modern GPUs with larger L2 caches and faster attention primitives. Notably, modern NVIDIA GPUs also provide Transformer Engine support for FP8 and FP4 (and FP6, although we focus mostly on FP8/FP4 formats in this text since FP6 is not widely used in existing AI frameworks and tools). Combined with higher memory bandwidth, the Tensor Cores let kernels like ThunderMLA operate much closer to hardware limits. On modern GPUs, ThunderMLA achieves even lower latency per token due to these architectural advances.这些优势在具有更大 L2 缓存和更快注意力原语的现代 GPU 上会被进一步放大。值得注意的是,现代 NVIDIA GPU 还通过 Transformer Engine 提供对 FP8 和 FP4 的支持(以及 FP6,不过本文主要关注 FP8/FP4 格式,因为 FP6 在现有 AI 框架与工具中尚未广泛使用)。结合更高的显存带宽,张量核心让 ThunderMLA 这类内核能够运行得更接近硬件极限。在现代 GPU 上,得益于这些架构进步,ThunderMLA 实现了更低的每 token 时延。
FlexDecoding(PyTorch)
FlexDecoding (PyTorch)
In Chapter 14, we discussed PyTorch’s FlexAttention, which lets you JIT-compile fused kernels for arbitrary sparsity patterns in attention, including local windows, block-sparse patterns, etc.—all without writing custom CUDA. Under the hood, TorchInductor + OpenAI’s Triton generate a fused kernel that computes only the allowed query-key pairs for that pattern. Triton automatically applies performance optimization techniques like warp specialization and asynchronous copies when beneficial on the given hardware. However, you can also tune triton.Config to further customize by configuring num_consumer_groups for example.在第 14 章中,我们讨论了 PyTorch 的 FlexAttention,它让你能够针对注意力中的任意稀疏模式(包括局部窗口、块稀疏模式等)JIT 编译融合内核——全程无需编写自定义 CUDA。在底层,TorchInductor + OpenAI 的 Triton 会生成一个融合内核,只计算该模式所允许的 query-key 对。当在给定硬件上有利时,Triton 会自动应用线程束专用化和异步拷贝等性能优化技术。不过,你也可以通过调整 triton.Config 来进一步定制,例如配置 num_consumer_groups。
FlexDecoding is the decoding backend of torch.nn.attention.flex_attention. FlexDecoding also lets you manage KV in place and supports masks and biases just like FlexAttention. Specifically, FlexDecoding compiles a specialized kernel for the decode phase (Q_len=1) attending over a growing KV cache.FlexDecoding 是 torch.nn.attention.flex_attention 的解码后端。FlexDecoding 还允许你原地管理 KV,并且像 FlexAttention 一样支持掩码与偏置。具体而言,FlexDecoding 会为解码阶段(Q_len=1)编译一个专用内核,在不断增长的 KV 缓存上进行注意力计算。
At runtime, the FlexDecoding implementation picks the specialized decode kernel and reuses it across multiple decode steps. This helps to minimize overhead when shapes and dtypes remain compatible—greatly speeding up long-sequence LLM inference.在运行时,FlexDecoding 实现会选择该专用解码内核,并在多个解码步骤中复用它。当形状与 dtype 保持兼容时,这有助于将开销降至最低——从而大幅加速长序列 LLM 推理。
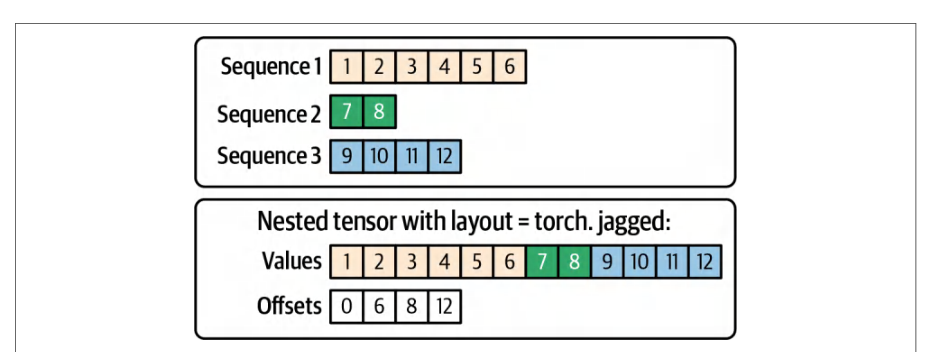
A key feature of FlexAttention and FlexDecoding includes support for nested jagged-layout tensors (NJT). These allow ragged batching of variable-length sequences (common in LLM workloads) during decoding. A jagged tensor representation of various sequences is shown in Figure 18-2.FlexAttention 与 FlexDecoding 的一个关键特性是支持嵌套不规则布局张量(nested jagged-layout tensor,NJT)。这些张量允许在解码期间对变长序列进行不规则批处理(这在 LLM 工作负载中很常见)。图 18-2 展示了各种序列的不规则张量表示。
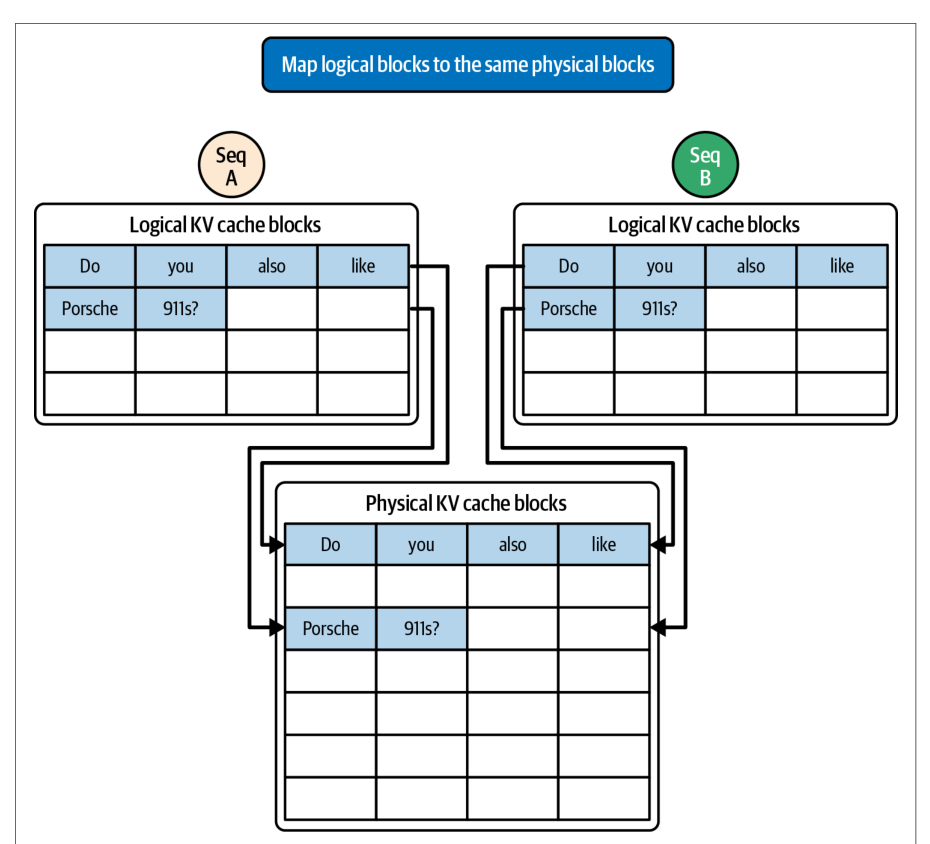
Additionally, FlexDecoding supports bias terms and integrates with PagedAttention by using a block mask conversion interface that maps logical blocks to the physical cache layout. This scatters logical KV blocks into the physical cache layout—without creating extra copies, as shown in Figure 18-3.此外,FlexDecoding 支持偏置项,并通过块掩码转换接口与 PagedAttention 集成,该接口将逻辑块映射到物理缓存布局。如图 18-3 所示,这一过程将逻辑 KV 块分散到物理缓存布局中,且不会产生额外副本。
FlexDecoding leverages captured tensors to vary certain mask or bias values during each iteration—without requiring a recompile. And it integrates with PagedAttention. To use a global KV cache such as vLLM LMCache, map the cache’s page table to Flex-Attention’s BlockMask. This will translate logical KV pages into physical memory addresses on the fly.FlexDecoding 利用捕获的张量在每次迭代中改变某些掩码或偏置值,而无需重新编译。并且它与 PagedAttention 集成。要使用诸如 vLLM LMCache 之类的全局 KV 缓存,需将缓存的页表映射到 Flex-Attention 的 BlockMask。这样就能即时将逻辑 KV 页转换为物理内存地址。
With FlexDecoding, developers have full Python-level flexibility for custom attention sparsity patterns. This is particularly useful for MoE model inference. FlexDecoding allows you to achieve near-optimal performance without requiring you to write any custom CUDA kernels. Essentially, it allows arbitrary attention patterns to be optimized similarly to dense attention patterns. This becomes even more valuable as new inference techniques emerge.借助 FlexDecoding,开发者可以在 Python 层面完全灵活地定制注意力稀疏模式。这对 MoE 模型推理尤为有用。FlexDecoding 让你无需编写任何自定义 CUDA 内核,即可获得接近最优的性能。本质上,它使任意注意力模式都能像稠密注意力模式一样得到优化。随着新的推理技术不断涌现,这一点的价值将愈发凸显。
Many of these capabilities, such as fused attention for decoding and support for PyTorch’s nested jagged tensors (NJT) batching, are available in the core PyTorch library. This makes custom fusion less necessary for typical patterns.其中许多能力,例如用于解码的融合注意力以及对 PyTorch 嵌套锯齿张量(NJT)批处理的支持,都已内置于 PyTorch 核心库中。这使得针对典型模式的自定义融合变得不那么必要。
These kernel-level advancements are highly technical and leverage the full power of the GPU, network, and memory. These software optimizations can significantly improve decode performance—even on the same hardware. When designing an ultrascale system, you should incorporate these optimized kernels, if possible. Be sure to verify overlap and kernel efficiency using Nsight Systems with hardware-based CUDA traces. Additionally, use Nsight Compute for specific memory and link metrics.这些内核层面的进步技术性很强,充分利用了 GPU、网络和内存的全部能力。这些软件优化可以显著提升解码性能——即便是在相同的硬件上。在设计超大规模系统时,应尽可能采用这些优化过的内核。务必使用 Nsight Systems 结合基于硬件的 CUDA 跟踪来验证重叠与内核效率。此外,使用 Nsight Compute 查看具体的内存与链路指标。
调优 KV 缓存利用率与管理
Tuning KV Cache Utilization and Management
Disaggregation requires that you treat the KV cache as a first-class shared resource across the cluster. Since KV caches can now live longer and move between nodes, high-performance inference systems have improved how the KV cache is stored and shared.解耦要求将 KV 缓存视为整个集群中一等公民的共享资源。由于 KV 缓存现在可以存活更久并在节点之间迁移,高性能推理系统已经改进了 KV 缓存的存储与共享方式。
In particular, distributed KV cache pools and prefix reuse across requests become powerful techniques. Additionally, it’s important to keep an eye on the memory bandwidth improvements with newer GPU and HBM generations. Let’s discuss each of these in the context of improving KV cache performance.特别是,分布式 KV 缓存池和跨请求的前缀复用成为强有力的技术。此外,密切关注新一代 GPU 与 HBM 带来的显存带宽提升也很重要。下面我们在提升 KV 缓存性能的背景下逐一讨论这些内容。
解耦 KV 缓存池
Disaggregated KV Cache Pool
Instead of each GPU storing KV only for the requests it’s currently serving, a disaggregated KV cache pool decouples KV storage from individual GPUs. Instead, it spreads the data out across the entire cluster’s GPU memory.解耦 KV 缓存池不再让每块 GPU 只为自己当前正在服务的请求存储 KV,而是将 KV 存储与单块 GPU 解耦。取而代之的是,它将数据分散到整个集群的 GPU 显存中。
The pool can also offload to CPU memory, including the unified CPU and GPU memory of the Grace Blackwell and Vera Rubin platforms. It can also offload to persistent storage like NVMe SSDs.该池还可以卸载到 CPU 内存,包括 Grace Blackwell 和 Vera Rubin 平台的统一 CPU 与 GPU 显存。它还可以卸载到 NVMe SSD 等持久化存储。
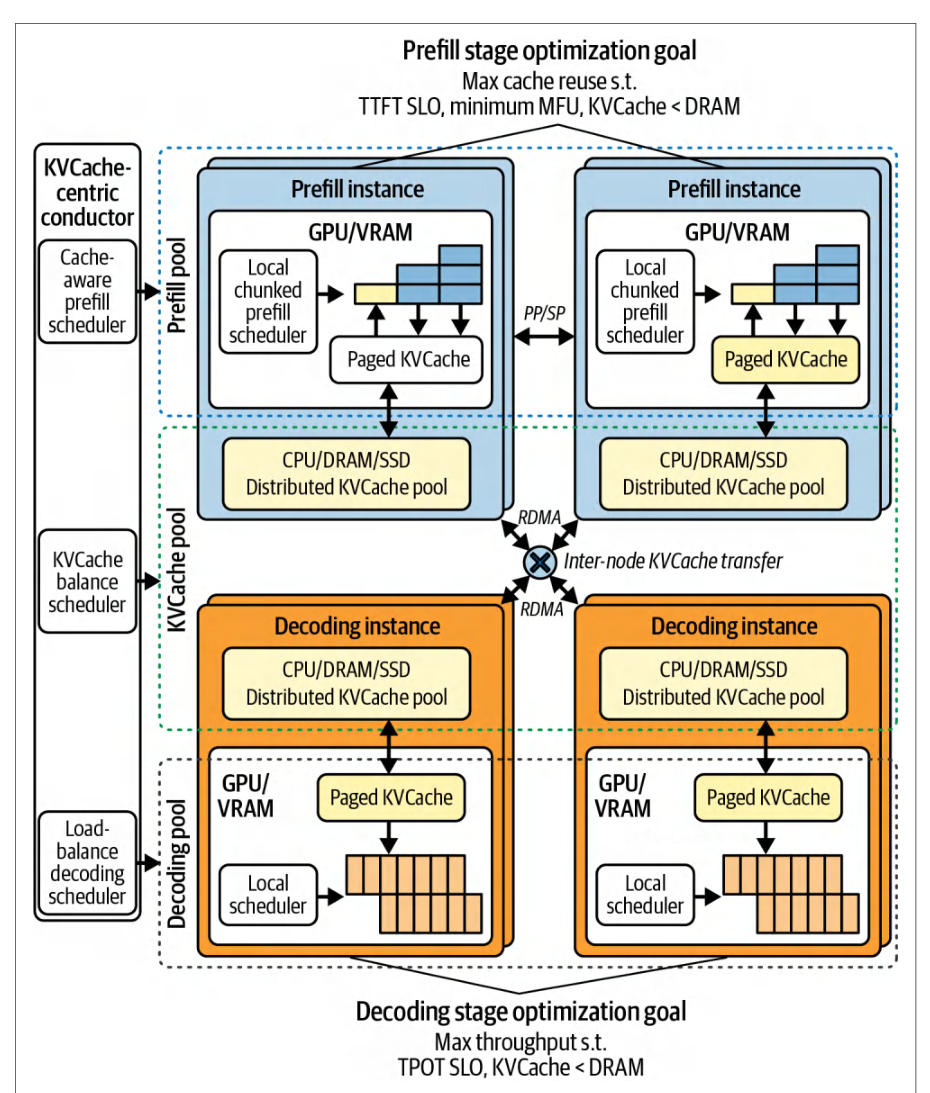
Using a disaggregated KV cache pool, when a prefill computes the KV tensors for a prompt—or when a decode extends the KV tensors—the KV blocks are stored in a distributed manner across many compute nodes. This is shown in Figure 18-4, adap-ted from work on disaggregated KV pools.使用解耦 KV 缓存池时,当预填充为某个提示计算 KV 张量——或当解码扩展 KV 张量时——KV 块会以分布式方式存储在许多计算节点上。如图 18-4 所示,该图改编自解耦 KV 池相关的工作。
Consider a very long 250,000-token context (e.g., a chat session with many turns) using a 70 billion-parameter transformer model with 80 layers and 32 heads in which each head is dimension 128. This generates a huge KV cache footprint per token.考虑一个非常长的 250,000 token 上下文(例如包含多轮对话的聊天会话),使用 700 亿参数的 Transformer 模型,该模型有 80 层、32 个头,每个头的维度为 128。这会为每个 token 产生巨大的 KV 缓存占用。
Each token generates a key and value vector of length equal to the model’s hidden dimension (num_heads × head_dim). Let’s assume this is 4,096 for our model. This results in 8,192 floats per layer. Summing across 80 layers, this creates 655,360 floats of KV data per token. Let’s assume 16-bit precision, or 2 bytes per float. This is roughly 1.31 MB needed per token. Scaling this to 250,000 tokens produces about 328 GB—just for the KV data!每个 token 都会生成一个键向量和一个值向量,其长度等于模型的隐藏维度(num_heads × head_dim)。假设我们的模型该值为 4,096。这样每层会产生 8,192 个浮点数。对 80 层求和,每个 token 就产生 655,360 个浮点数的 KV 数据。假设使用 16 位精度,即每个浮点数 2 字节。那么每个 token 大约需要 1.31 MB。扩展到 250,000 个 token,就产生约 328 GB——仅仅是 KV 数据!
Assuming we quantize the KV cache down to FP8 and use techniques like selective-layer caching, we can reduce this footprint down to maybe the 100–150 GB range for this 250,000-token prompt. A single GPU will likely not have capacity for all of the tokens’ KV along with everything else it needs to hold, such as model weights, etc.— especially as the multiturn conversation continues. As such, the system would need to truncate context—or cause expensive KV recomputation on earlier tokens.假设我们将 KV 缓存量化到 FP8,并使用选择性层缓存等技术,对于这个 250,000 token 的提示,可以将占用降低到大约 100–150 GB 的范围。单块 GPU 很可能无法容纳所有 token 的 KV 以及它需要保存的其他所有内容,例如模型权重等——尤其是随着多轮对话的持续进行。因此,系统将不得不截断上下文——或者对较早的 token 进行代价高昂的 KV 重计算。
With a disaggregated KV pool, however, older parts of the context’s KV can be evicted from the GPU and pushed out to the KV cache pool spread across the cluster—and in CPU DRAM or NVMe storage. The data is then fetched back into GPU memory when it’s needed.然而,借助解耦 KV 池,上下文较旧部分的 KV 可以从 GPU 中逐出,推送到分布在整个集群上的 KV 缓存池——以及 CPU DRAM 或 NVMe 存储中。当需要时,数据再被取回 GPU 显存。
A disaggregated KV cache pool implements a multitier memory hierarchy in which GPU device memory holds the active KV cache while the CPU host RAM (or NVMe storage) serves as the overflow backing store. Modern inference engines can choose to offload KV cache to CPU memory or NVMe. This effectively virtualizes GPU memory much like an OS’s virtual memory subsystem.解耦 KV 缓存池实现了一种多层显存层次结构,其中 GPU 设备显存保存活跃的 KV 缓存,而 CPU 主机 RAM(或 NVMe 存储)充当溢出后备存储。现代推理引擎可以选择将 KV 缓存卸载到 CPU 内存或 NVMe。这实际上虚拟化了 GPU 显存,很像操作系统的虚拟显存子系统。
This design allows for ultralong contexts by asynchronously paging KV blocks between GPU memory and the KV cache pool without stalling the compute pipelines—assuming good communication-computation overlap, as discussed throughout this book.这种设计通过在 GPU 显存与 KV 缓存池之间异步分页 KV 块而不阻塞计算流水线,从而支持超长上下文——前提是具备良好的通信-计算重叠,正如本书通篇所讨论的。
Additionally, by decoupling request state from individual GPUs, the system can use the global KV cache pool to dynamically shard KV data across multiple nodes in the cluster to adaptively balance the load. This simplifies scaling and improves fault isolation in large inference clusters.此外,通过将请求状态与单块 GPU 解耦,系统可以利用全局 KV 缓存池将 KV 数据动态分片到集群中的多个节点上,以自适应地平衡负载。这简化了扩展,并改善了大型推理集群中的故障隔离。
And since any decode node can access the global KV pool, then any decode node can participate in decoding any request, if needed due to failover or load balancing. This adds flexibility for the scheduler since it can choose a decode node closest to where the relevant KV cache blocks are located.并且,由于任何解码节点都可以访问全局 KV 池,因此在因故障转移或负载均衡而需要时,任何解码节点都可以参与解码任何请求。这为调度器增加了灵活性,因为它可以选择距离相关 KV 缓存块所在位置最近的解码节点。
If some KV blocks of a prefix are cached in DRAM on server A, it might be faster to schedule the decode on server A since it can quickly pull them into its GPU. This is in contrast to server B, which would have to fetch the KV blocks over the network.如果某个前缀的部分 KV 块缓存在服务器 A 的 DRAM 中,那么将解码调度到服务器 A 可能更快,因为它可以快速将这些块拉入其 GPU。相比之下,服务器 B 则必须通过网络获取这些 KV 块。
An efficient KV cache scheduler can look at the distribution of KV blocks in the pool—in addition to the network topology—and assign prefill and decode tasks accordingly. As such, a prefill node can place KV data into a pool implemented as a distributed memory space accessible across the cluster.高效的 KV 缓存调度器除了查看网络拓扑之外,还可以查看池中 KV 块的分布,并据此分配预填充与解码任务。因此,预填充节点可以将 KV 数据放入一个以分布式内存空间实现、可跨集群访问的池中。
With the KV cache in a cluster-side shared-memory space, any decode node can retrieve the data. This avoids having to schedule for direct prefill-to-decode transfers every time.当 KV 缓存位于集群侧的共享内存空间时,任何解码节点都能取回这些数据。这样就避免了每次都要调度从预填充到解码的直接传输。
This adds a bit of extra overhead due to an extra hop to retrieve KV data from the pool, but it allows more flexibility because all decode nodes have access to all KV-cached data. It also means that a decode node that didn’t directly receive data from a particular prefill can still access the KV data from the pool, if needed.由于从池中取回 KV 数据需要多一跳,这会带来少量额外开销,但它带来了更大的灵活性,因为所有解码节点都能访问全部已缓存的 KV 数据。这也意味着,没有直接从某个预填充节点接收数据的解码节点,在需要时仍可从池中访问该 KV 数据。
If a decode node crashes—or a request needs to move mid-generation for whatever reason—the KV data isn’t lost. The data lives in the pool, and another node can pick it up and continue where it left off using the saved KV. This improves fault tolerance.如果某个解码节点崩溃——或者请求因某种原因需要在生成过程中迁移——KV 数据也不会丢失。数据存放在池中,另一个节点可以接手,并利用已保存的 KV 从断点继续生成。这提升了容错能力。
A global KV cache pool also provides cache persistence across requests. This way, if two requests share some prefix, the KV for that prefix can be computed once and reused across the cluster—even if the requests end up on different decode servers.全局 KV 缓存池还提供了跨请求的缓存持久性。这样一来,如果两个请求共享某段前缀,该前缀的 KV 只需计算一次,即可在整个集群中复用——即使这两个请求最终落在不同的解码服务器上。
In short, a disaggregated KV cache pool trades memory (or colder storage) for compute. By storing a larger KV cache, the system can avoid recomputing KV data in many scenarios. This approach leverages the fact that reusing data—even from DRAM or SSD—is often cheaper than repeatedly recomputing large attention matrix multiplications with quadratic time complexity, O(N2).简而言之,解耦的 KV 缓存池是用内存(或更冷的存储层)换取算力。通过存储更大的 KV 缓存,系统可以在许多场景下避免重新计算 KV 数据。这种方法利用了这样一个事实:复用数据——即使来自 DRAM 或 SSD——通常也比反复重算具有二次时间复杂度 O(N2) 的大型注意力矩阵乘法更便宜。
KV 缓存复用与前缀共享
KV Cache Reuse and Prefix Sharing
As mentioned, it’s beneficial to reuse cached KV data across requests for prompts that share a common prefix. This scenario arises fairly often in the form of multiturn conversations, shared system prompts, and attached documents.如前所述,对于共享相同前缀的提示词,跨请求复用已缓存的 KV 数据是有益的。这种场景相当常见,表现为多轮对话、共享的系统提示词以及附加文档。
Instead of recomputing the transformer attention outputs for that prefix for every request, the system can store the KV outputs for the prefix and reuse them directly.系统无需为每个请求重新计算该前缀的 Transformer 注意力输出,而是可以存储该前缀的 KV 输出并直接复用。
Essentially, this skips the prefill computation for that portion of the input, which saves a lot of time and GPU cycles.本质上,这跳过了输入中该部分的预填充计算,从而节省大量时间和 GPU 周期。
A proper KV-cache-centric scheduler takes into account prefix cache hits by looking at the “prefix cache hit length,” or how many tokens of this prompt are already present in the cache pool, when assigning work. In practice, if a new request comes and its first N tokens match some cached prefix in the KV pool, the system can decide to reuse that KV data.一个真正以 KV 缓存为中心的调度器在分配工作时会考虑前缀缓存命中情况,即查看“前缀缓存命中长度”,也就是该提示词已有多少 token 存在于缓存池中。在实践中,如果新请求到来,且其前 N 个 token 与 KV 池中某个已缓存前缀匹配,系统就可以决定复用该 KV 数据。
vLLM implements automatic prefix caching using a global hash table of KV “pages” using its PagedAttention mechanism. Here, each unique 16-token block of context has a hash. If a new request needs a prefix that matches a stored block (by hash), it can directly copy those KV tensors instead of recomputing.vLLM 借助其 PagedAttention 机制,使用 KV“页”的全局哈希表实现自动前缀缓存。在这里,上下文中每个唯一的 16 token 块都有一个哈希值。如果新请求所需的前缀与某个已存储块匹配(按哈希),它就可以直接复制这些 KV 张量,而无需重新计算。
If the same context appears again, the system serves it from memory. In essence, it treats the KV of a context as reusable data that can be looked up by content using hashing. Implementations typically maintain a global “prompt tree” to manage these cached contexts and evict them when necessary. This optimizes for the most frequently reused prefixes.如果相同的上下文再次出现,系统直接从内存中提供它。本质上,它把某个上下文的 KV 视为可复用数据,可以通过哈希按内容查找。各类实现通常会维护一棵全局“提示词树”来管理这些已缓存的上下文,并在必要时将其逐出。这样可针对最频繁复用的前缀进行优化。
A key to effective KV reuse is identifying identical or overlapping prefixes. Usually, systems focus on exact matches for simplicity such that if the first N tokens match exactly, they reuse that chunk. Combining partial-prefix overlaps is more complex since you need to somehow merge caches, which isn’t always straightforward. So typical caching uses exact prefix caching.实现高效 KV 复用的关键在于识别相同或重叠的前缀。通常,为了简单起见,系统会聚焦于精确匹配:只要前 N 个 token 完全一致,就复用该块。合并部分前缀重叠更为复杂,因为需要以某种方式合并缓存,而这并不总是直截了当的。因此典型的缓存采用精确前缀缓存。
There is a trade-off, however. Storing many users’ KV caches indefinitely can consume a lot of memory. A system must implement eviction policies like LRU for KV blocks to drop caches that are unlikely to be reused. This frees space for new ones. The scheduler might also decide which caches to keep based on likelihood of reuse. The idea is to maximize cache hits within memory constraints.然而这里存在权衡。无限期地保存众多用户的 KV 缓存会消耗大量内存。系统必须为 KV 块实现 LRU 之类的淘汰策略,丢弃不太可能被复用的缓存,从而为新缓存腾出空间。调度器也可能根据复用可能性决定保留哪些缓存。其思路是在内存约束下最大化缓存命中。
If a certain prefill node already holds a portion of the KV needed in its local GPU memory or local DRAM cache, it might be beneficial to route the request to that node to minimize data transfer. This is an example of data-aware scheduling in which it sends the compute to where the data is, rather than always pulling data to wherever compute is available.如果某个预填充节点在其本地 GPU 显存或本地 DRAM 缓存中已经持有部分所需的 KV,那么把请求路由到该节点可能更有利,可最大限度减少数据传输。这是数据感知调度的一个例子:把计算送到数据所在之处,而不是总把数据拉到有可用计算的地方。
This is analogous to locality-aware scheduling in distributed systems. In our earlier routing discussion, we touched on this. If possible, you should route a request to the server that generated its prefix. This maximizes the likelihood of a cache hit.这类似于分布式系统中的局部性感知调度。在前面的路由讨论中我们已有所涉及。如果可能,应当把请求路由到生成其前缀的那台服务器,从而最大化缓存命中的可能性。
In the broader context of disaggregation, prefix caching is supported by having a unified view of KV across many requests and possibly storing it in a shareable place like the global pool. This is in contrast to a siloed per-request or per-node approach.在更广泛的解耦语境下,前缀缓存的支持方式是对众多请求的 KV 建立统一视图,并可能将其存放在全局池这类可共享的位置。这与按请求或按节点各自为政的做法形成对比。
This also helps reduce the overhead of recomputation that disaggregation might otherwise incur if the same prompt goes to different nodes at different times. With a global KV store or coordinated caching, even if a user’s requests hit different decode servers, they can benefit from each other’s cached work.这也有助于降低解耦原本可能带来的重计算开销——当同一提示在不同时间被发往不同节点时就会出现这种开销。借助全局 KV 存储或协同缓存,即使用户的请求落到不同的解码服务器,它们也能受益于彼此已缓存的工作。
优化的 KV 缓存内存布局
Optimized KV Cache Memory Layout
Another area of low-level innovation is optimizing the KV cache memory layouts. The KV cache, which stores keys and values for all past tokens in each sequence, can become huge for many concurrent decode streams since each stream uses memory roughly proportional to num_layers × 2 × sequence_length × d_head.另一个底层创新领域是优化 KV 缓存的内存布局。KV 缓存保存每条序列中所有历史 token 的键和值,对于大量并发解码流而言可能变得非常庞大,因为每条流占用的内存大致正比于 num_layers × 2 × sequence_length × d_head。
Techniques like tiered caching are useful since not all KV pairs need to be kept in GPU memory at all times. Older parts of the KV cache can be swapped to CPU—or even compressed.分层缓存之类的技术很有用,因为并非所有 KV 对都需要始终留在 GPU 显存中。KV 缓存中较旧的部分可以换出到 CPU,甚至可以被压缩。
Since we emphasize keeping decode latency low, most designs keep the active KV cache in GPU memory for quick access. In this case, you can tune how the memory is laid out and accessed.由于我们强调保持解码时延低,大多数设计会把活跃的 KV 缓存留在 GPU 显存中以实现快速访问。在这种情况下,可以调优显存的布局方式与访问方式。
DeepSeek’s FlashMLA pages KV cache and allocates the cache in fixed-size blocks (pages) so that contiguous memory accesses can happen for active sequences. This reduces cache misses and DRAM traffic.DeepSeek 的 FlashMLA 对 KV 缓存进行分页,以固定大小的块(页)分配缓存,从而使活跃序列能够进行连续显存访问。这减少了缓存未命中和 DRAM 流量。
Additionally, some systems implement prefix compression if a prompt’s prefix will no longer be attended to because the context window has moved, for instance. In this case, the KV cache manager might drop or compress these KV entries. This is more relevant in long conversations because the context window slides. But it can save memory and bandwidth for extremely long sequences.此外,某些系统会实现前缀压缩,例如当提示的前缀因上下文窗口已经前移而不再被关注时。在这种情况下,KV 缓存管理器可能丢弃或压缩这些 KV 条目。这在长对话中更为相关,因为上下文窗口会滑动。但对于极长的序列,它可以节省内存和带宽。
Another technique called POD-Attention similarly reorganizes attention computation to reduce HBM traffic. Specifically, it uses SM-aware thread-block (or cooperative thread array [CTA]) scheduling. This implements runtime operation binding to dynamically assign each CTA running on an SM to either perform a prefill or decode task. This is shown in Figure 18-5.另一种称为 POD-Attention 的技术同样重新组织了注意力计算,以减少 HBM 流量。具体而言,它采用 SM 感知的线程块(或协作线程数组,CTA)调度。该技术实现了*运行时操作绑定*,动态地将运行在某个 SM 上的每个 CTA 分配为执行预填充或解码任务。如图 18-5 所示。
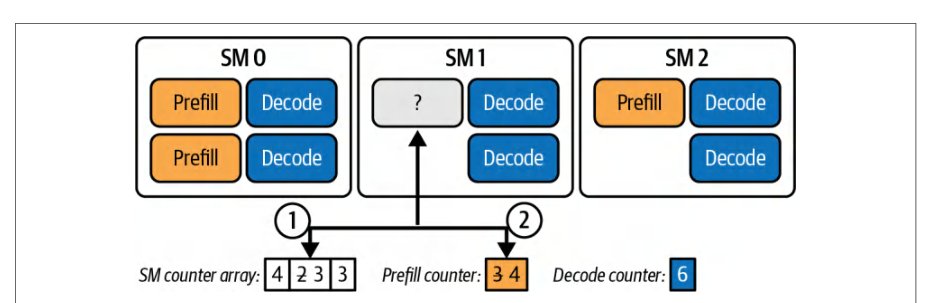
So rather than statically launching separate kernels for each phase, a single kernel launches enough CTAs to cover both workloads. At runtime, each CTA inspects which SM it’s on and uses per-SM counters to decide which operation (prefill or decode) should be run based on what else is running on that SM.因此,不再是针对每个阶段静态启动独立的内核,而是由单个内核启动足够多的 CTA 以覆盖两种工作负载。在运行时,每个 CTA 检查自己位于哪个 SM 上,并依据每 SM 计数器,根据该 SM 上正在运行的其他内容来决定应执行哪种操作(预填充或解码)。
The SM-aware scheduling logic tries to match prefill with decode operations at runtime. This avoids isolated bursts of memory traffic and smooths out resource demands.SM 感知的调度逻辑会在运行时尝试将预填充与解码操作配对。这避免了内存流量的孤立突发,并平滑了资源需求。
Specifically, POD-Attention colocates prefill and decode work on the same SM so the fused kernel can improve locality and reduce redundant HBM transactions. This minimizes memory movement, maximizes bandwidth utilization, and balances compute-bound and memory-bound workloads on each SM. POD-Attention can improve attention performance by up to about 29% by colocating prefill and decode work on the same SMs with proper SM-aware CTA scheduling to unlock full overlap.具体而言,POD-Attention 将预填充与解码工作共置于同一 SM 上,使融合内核能够改善局部性并减少冗余的 HBM 事务。这最小化了显存搬运、最大化了带宽利用率,并在每个 SM 上平衡了计算密集型与显存密集型工作负载。通过恰当的 SM 感知 CTA 调度将预填充与解码工作共置于同一 SM 上以释放完全重叠,POD-Attention 可将注意力性能提升最多约 29%。
POD-Attention’s dynamic binding decouples the hardware’s CTA-SM assignment from the software’s CTA-role assignment—either prefill or decode. This type of innovation shows a growing focus on hardware and software codesign to minimize memory movement and get the most out of your system’s performance.POD-Attention 的动态绑定将硬件的 CTA-SM 分配与软件的 CTA 角色分配(预填充或解码)解耦。这类创新表明,业界日益重视软硬件协同设计,以最小化内存搬运并充分发挥系统性能。
GPU 与 CPU-GPU 超级芯片的改进
GPU and CPU-GPU Superchip Improvements
You should also consider memory bandwidth improvements in new hardware. Higher memory bandwidth and larger L2 caches directly benefit the performance of the memory-bound decode phase.你还应考虑新硬件在显存带宽方面的改进。更高的显存带宽和更大的 L2 缓存直接有利于显存密集型的解码阶段的性能。
NVIDIA’s Grace Blackwell GB200 NVL72 system, a rack-scale platform with 36 Grace CPUs and 72 Blackwell GPUs, allows a single logical decode unit with tens of terabytes of memory for KV cache. This hardware, with its ~30 TB of unified memory, is ideal to keep very large contexts in memory. These contexts can be on the order of millions of tokens.NVIDIA 的 Grace Blackwell GB200 NVL72 系统是一个机架级平台,包含 36 个 Grace CPU 和 72 个 Blackwell GPU,可作为单一逻辑解码单元,提供数十 TB 的内存用于 KV 缓存。该硬件拥有约 30 TB 的统一内存,非常适合将超长上下文保留在内存中。这些上下文可达数百万 token 的量级。
With such a platform, the unified memory footprint is large. However, for latency-critical decode, you still want the active keys and values to live in GPU HBM. As such, you should use Grace CPU memory (LPDDR5X, not HBM) as a lower-tier cache or for very old tokens. Prefill and key-value offloading remain important when contexts exceed available HBM—even on a system like the NVL72.在这样的平台上,统一内存的占用空间很大。然而,对于时延关键的解码而言,你仍希望活跃的键和值驻留在 GPU HBM 中。因此,应将 Grace CPU 内存(LPDDR5X,而非 HBM)用作较低层级的缓存,或用于存放非常旧的 token。当上下文超出可用 HBM 时——即便在 NVL72 这样的系统上——预填充与键值卸载依然重要。
In short, disaggregation at a macro level should be paired with microlevel optimizations to fully achieve maximum inference performance. Advanced decode kernels like FlashMLA/ThunderMLA, efficient memory layouts (paged caches, etc.), and the latest GPU architectures will produce efficient and scalable decode.简而言之,宏观层面的解耦应与微观层面的优化相配合,才能完全实现最大推理性能。FlashMLA/ThunderMLA 等先进解码内核、高效的内存布局(分页缓存等)以及最新的 GPU 架构,将共同带来高效且可扩展的解码。
预填充与解码之间的快速 KV 缓存传输
Fast KV Cache Transfer Between Prefill and Decode
A key requirement of disaggregated inference is quickly and efficiently transferring the KV cache from the prefill worker to a decode worker. If this transfer isn’t fast, any time saved by parallelizing prefill and decode could be lost waiting on data movement.解耦推理的一项关键要求是快速、高效地将 KV 缓存从预填充工作节点传输到解码工作节点。如果该传输不够快,那么通过并行化预填充与解码所节省的时间可能会因等待数据搬运而全部损失。
In this section, we discuss the techniques used to minimize transfer overhead. We then describe how systems implement the handoff, using high-speed interconnects and avoiding extra KV copies.本节讨论用于最小化传输开销的技术。随后介绍系统如何利用高速互连并避免额外的 KV 拷贝来实现这一交接。
KV 缓存大小
KV Cache Size
Prefill output consists primarily of the KV cache for all prompt tokens. This can be a lot of data. Consider a model with L layers, each with h attention heads of dimension d, and a prompt of N tokens. The KV cache size is roughly 2 × L × N × (h × d), where the factor, 2, is for both keys and values.预填充的输出主要由所有提示词 token 的 KV 缓存构成。这可能是一份相当大的数据。考虑一个具有 L 层、每层有 h 个维度为 d 的注意力头的模型,以及一个包含 N 个 token 的提示词。KV 缓存大小大致为 2 × L × N × (h × d),其中因子 2 对应键和值两部分。
The actual size depends on precision (FP16 versus INT8, etc.) and model specifics, but it’s large. For instance, a 40-layer model with 16 heads of size 64 and a 1,000-token prompt produces on the order of 40,000 KV vectors. This could be hundreds of MB of data. If the number of tokens is 5,000, it’s 5× larger.实际大小取决于精度(FP16 与 INT8 等)以及模型的具体情况,但它是很大的。例如,一个 40 层、16 个大小为 64 的头、提示词为 1,000 个 token 的模型,会产生约 40,000 个 KV 向量。这可能是数百 MB 的数据。如果 token 数为 5,000,则大 5 倍。
Transferring this amount of data over a network can introduce significant latency if done naively. For instance, a naive approach might be to copy the KV to CPU memory on the prefill worker, then send it over TCP—or even write it to disk for the decode process to load. This could be extremely slow, on the order of hundreds of milliseconds for large prompts. The goal is to reduce the transfer time down to only a few milliseconds. This allows prefill and decode to truly overlap in parallel.如果采用朴素的方式,通过网络传输如此数量的数据会引入显著的时延。例如,一种朴素的做法可能是先把 KV 复制到预填充工作节点的 CPU 内存,再通过 TCP 发送——甚至写入磁盘供解码进程加载。对于大型提示词,这可能极其缓慢,达到数百毫秒量级。目标是把传输时间降低到仅几毫秒。这样才能让预填充与解码真正并行重叠。
零拷贝 GPU 到 GPU 传输
Zero-Copy GPU-to-GPU Transfer
Modern disaggregated systems use zero-copy GPU-to-GPU transfer techniques. In practice, this involves using remote direct memory access (RDMA) over high-speed fabrics. For example, you can use InfiniBand for transfer between racks/nodes—or use NVLink/NVSwitch for direct GPU memory writes within a single node (multi-GPU) platform. These methods send data directly between GPUs without copying through CPU memory.现代解耦系统采用零拷贝的 GPU 到 GPU 传输技术。在实践中,这涉及在高速网络上使用远程直接显存访问(RDMA)。例如,可以使用 InfiniBand 在机架/节点之间传输——或在单节点(多 GPU)平台内使用 NVLink/NVSwitch 直接写入 GPU 显存。这些方法直接在 GPU 之间发送数据,无需经由 CPU 内存拷贝。
NVIDIA’s high-performance GPU-to-GPU transfer library for inference is called NVIDIA Inference Xfer Library (NIXL). NIXL provides a plugin architecture (e.g., NVLink, UCX fabrics, GPUDirect Storage) for zero-copy GPU↔GPU and GPU↔storage data movement.NVIDIA 面向推理的高性能 GPU 到 GPU 传输库名为 NVIDIA Inference Xfer Library(NIXL)。NIXL 提供插件式架构(例如 NVLink、UCX 网络、GPUDirect Storage),用于零拷贝的 GPU↔GPU 与 GPU↔存储数据搬运。
NIXL streamlines RDMA-style transfers, allowing one GPU to write directly into another GPU’s memory over the available high-speed fabric—for example, Infini-Band or NVLink-based connections. In other words, the prefill GPU can directly inject the KV tensors into the decode worker GPU’s memory.NIXL 简化了 RDMA 风格的传输,允许一块 GPU 通过可用的高速网络直接写入另一块 GPU 的内存——例如 InfiniBand 或基于 NVLink 的连接。换言之,预填充 GPU 可以把 KV 张量直接注入解码工作节点 GPU 的内存。
RDMA-based protocols bypass the CPU and make full use of the GPU interconnect bandwidth. Systems like NVIDIA Dynamo and the open source vLLM plus LMCache integration rely on NIXL. Specifically, they use NIXL to write KV tensors directly into remote GPU memory over NVLink or RDMA. Modern GPU interconnects provide very high bandwidth, and a 1 GB transfer can complete in a few to tens of milliseconds depending on link type and contention.基于 RDMA 的协议绕过 CPU,充分利用 GPU 互连带宽。NVIDIA Dynamo 以及开源 vLLM 加 LMCache 集成等系统都依赖 NIXL。具体而言,它们使用 NIXL 通过 NVLink 或 RDMA 把 KV 张量直接写入远端 GPU 显存。现代 GPU 互连提供极高的带宽,1 GB 的传输可在几毫秒到几十毫秒内完成,具体取决于链路类型和竞争情况。
In practice, implementations achieve low transfer times by overlapping data transfer with computation. For instance, with RDMA, a decode GPU can continue generating tokens for other sequences while a prefill worker is writing KV data into its memory buffer asynchronously. The prefill can push the data (RDMA write push model), or the decode can pull it (RDMA read), depending on design. Either way, no CPU involvement is needed in the data path.在实践中,实现方案通过让数据传输与计算重叠来获得较低的传输时间。例如,使用 RDMA 时,解码 GPU 可以在预填充工作节点异步向其内存缓冲区写入 KV 数据的同时,继续为其他序列生成 token。预填充端可以推送数据(RDMA 写推送模型),解码端也可以拉取数据(RDMA 读),取决于设计。无论哪种方式,数据路径都不需要 CPU 参与。
Common strategies for fast KV transfer include prefill-side push, decode-side pull, shared-memory (CUDA IPC) buffer, connector/queue abstraction, and nonblocking overlap. Let’s discuss each of these:快速 KV 传输的常见策略包括预填充侧推送、解码侧拉取、共享内存(CUDA IPC)缓冲区、连接器/队列抽象,以及非阻塞重叠。下面逐一讨论:
- Prefill-side push预填充侧推送
- The prefill worker, upon finishing the prompt, initiates an RDMA write of the KV data directly into a reserved buffer on the decode worker’s GPU. This can be done nonblockingly; the prefill can start the transfer and then move on to other work while the DMA occurs in the background.预填充工作节点在完成提示词处理后,发起一次 RDMA 写,把 KV 数据直接写入解码工作节点 GPU 上预留的缓冲区。这可以非阻塞地完成;预填充端可以启动传输后继续做其他工作,而 DMA 在后台进行。
- Decode-side pull解码侧拉取
- Alternatively, the decode worker can RDMA-read directly from the prefill GPU’s memory when it’s ready to begin decoding. Either push or pull achieves the same end result (no CPU copies). Some implementations might prefer push to offload coordination to the sender; others prefer pull for the receiver to control timing.另一种方式是,解码工作进程可以在准备开始解码时,直接从预填充 GPU 的内存进行 RDMA 读取。推或拉都能达到相同的最终结果(无 CPU 拷贝)。某些实现可能倾向于推,把协调工作交给发送方;另一些则倾向于拉,让接收方控制时机。
- Shared-memory (IPC) buffer共享内存(IPC)缓冲区
- If prefill and decode happen to be on the same machine (different GPUs in one server), they might use CUDA interprocess communication to share a memory handle or even a PCIe bar, effectively copying using NVLink or NVSwitch on the same host. This is a local variant of zero-copy transfer without going over the network.如果预填充与解码恰好在同一台机器上(同一台服务器中的不同 GPU),它们可能使用 CUDA 进程间通信来共享内存句柄,甚至共享 PCIe BAR,实际上就是在同一主机上通过 NVLink 或 NVSwitch 进行拷贝。这是零拷贝传输的本地变体,无需经过网络。
- Connector/queue abstraction连接器/队列抽象
- vLLM’s implementation abstracts the transfer mechanism behind a logical interface (a Pipe or LookupBuffer). The prefill process places the KV into this buffer or signals its availability, and the decode side retrieves it. Under the hood, this can use RDMA or even a high-performance pub-sub message (NATS in Dynamo’s case for control signals). The key is to decouple the logical handoff from the transport so different transports (RDMA, shared memory, etc.) can be plugged in.vLLM 的实现把传输机制抽象在一个逻辑接口(Pipe 或 LookupBuffer)之后。预填充进程将 KV 放入该缓冲区或发出其可用信号,解码侧再取回。在底层,这可以使用 RDMA,甚至高性能的发布-订阅消息(在 Dynamo 中控制信号使用 NATS)。关键在于将逻辑交接与传输解耦,从而可以插入不同的传输方式(RDMA、共享内存等)。
- Nonblocking overlap非阻塞重叠
- As mentioned, optimized systems overlap KV transfer with ongoing decode computations. For example, Dynamo’s decode worker continues generating tokens on other requests while a prefill worker is writing KV data into its GPU memory for a new request. This hides much of the transfer latency. As such, you can overlap a ~5 ms KV transfer with decode computation and add virtually zero net latency to the request’s first generated token.如前所述,经过优化的系统会将 KV 传输与正在进行的解码计算重叠。例如,Dynamo 的解码工作进程在为某个新请求把 KV 数据写入其 GPU 显存的同时,继续为其他请求生成 token。这隐藏了大部分传输时延。因此,你可以将约 5 ms 的 KV 传输与解码计算重叠,从而为该请求的首个生成 token 增加几乎为零的净时延。
With these methods, KV transfers can take on the order of a few milliseconds. This is much less than the hundreds of milliseconds required to actually compute that KV on the prefill worker. As such, the pipeline of prefill → transfer → decode achieves good parallelism since the decode can start almost immediately after prefill completes— without a long stall.借助这些方法,KV 传输只需几毫秒量级。这远小于在预填充工作进程上实际计算该 KV 所需的数百毫秒。因此,预填充 → 传输 → 解码这条流水线能实现良好的并行度,因为解码几乎可以在预填充完成后立即开始——而不会出现长时间停顿。
Be careful to avoid fragmentation and overhead when sending KV cache data. For instance, vLLM’s PagedAttention stores the KV cache in fixed-size token blocks, commonly 16 tokens per block. The KV blocks are relatively small (although the bytes per block scale with the number of heads, head dimension, number of layers, and dtype.) Naively sending thousands of small KV pages over RDMA would incur excessive overhead since each transfer has fixed latency and protocol overhead. This would lead to poor bandwidth utilization.发送 KV 缓存数据时,要注意避免碎片和开销。例如,vLLM 的 PagedAttention 将 KV 缓存存储在固定大小的 token 块中,通常每块 16 个 token。KV 块相对较小(尽管每块的字节数会随头数、头维度、层数和 dtype 缩放)。天真地通过 RDMA 发送数千个小的 KV 页会带来过多开销,因为每次传输都有固定的时延和协议开销。这会导致带宽利用率低下。
The LMCache extension addresses this inefficiency by collating KV pages into large contiguous buffers before transfer. Essentially, it gathers the small chunks into one big chunk in GPU memory, then sends that large buffer in one transfer.LMCache 扩展通过在传输前将 KV 页合并到大的连续缓冲区来解决这一低效问题。本质上,它把小块聚集到 GPU 显存中的一个大块中,然后一次传输发送这个大缓冲区。
For instance, if sending a 7,500-token KV cache as 470 small transfers takes 20 ms, collating them into larger blocks (e.g., 128-token pages) reduces transfer time down to 8 ms. This simple batching optimization keeps the network pipe full and reduces per-packet overhead.例如,如果以 470 次小传输发送 7,500 token 的 KV 缓存需要 20 ms,那么将它们合并成更大的块(例如 128 token 的页)可将传输时间降至 8 ms。这个简单的批处理优化能让网络管道保持满载,并减少每包开销。
Let’s show how a system is configured for fast GPU-to-GPU KV transfer. Here is an example config for LMCache’s prefill-decode mode using a NIXL transfer channel:下面展示如何配置系统以实现快速的 GPU 到 GPU KV 传输。以下是使用 NIXL 传输通道的 LMCache 预填充-解码模式的示例配置:
# 预填充服务器配置(lmcache-prefiller-config.yaml)
enable_pd: true
transfer_channel: "nixl"
pd_role: "sender"              # 本实例发送 KV 数据
pd_proxy_host: "decode-host"   # PD 代理 / 解码协调器
pd_proxy_port: 7500            # 代理/解码器上的控制平面端口
# 按计划传输的 KV 大小设置缓冲区
# FP8/FP4 KV 应能显著缩小其体积
pd_buffer_size: 1073741824     # 1 GiB 传输缓冲区大小
pd_buffer_device: "cuda"       # 缓冲区驻留在 GPU 显存中
# Prefill server config (lmcache-prefiller-config.yaml)
enable_pd: true
transfer_channel: "nixl"
pd_role: "sender"              # this instance sends KV data
pd_proxy_host: "decode-host"   # PD proxy / decode coordinator
pd_proxy_port: 7500            # control-plane port on the proxy/decoder
# size the buffer to the KV you plan to transfer
# FP8/FP4 KV should shrink it significantly
pd_buffer_size: 1073741824     # 1 GiB transfer buffer size
pd_buffer_device: "cuda"       # buffer stays in GPU memory
Here, the prefill server is configured as the RDMA sender. It targets the decode host’s port 7500 with a 1 GB GPU buffer allocated for KV transfers. The decode server is configured as the receiver on that port with a matching 1 GB GPU buffer, as shown here:这里,预填充服务器被配置为 RDMA 发送端。它以解码主机的 7500 端口为目标,并分配了 1 GB 的 GPU 缓冲区用于 KV 传输。解码服务器则被配置为该端口上的接收端,并配有大小匹配的 1 GB GPU 缓冲区,如下所示:
# 解码服务器配置(lmcache-decoder-config.yaml)
enable_pd: true
transfer_channel: "nixl"
pd_role: "receiver"            # 本实例接收 KV
pd_peer_host: "0.0.0.0"        # NIXL 对端的绑定地址
pd_peer_init_port: 7300        # NIXL 握手/控制端口
pd_peer_alloc_port: 7400       # NIXL 分配/数据端口
pd_buffer_size: 1073741824     # 1 GiB(与发送端一致,除非计划分片)
pd_buffer_device: "cuda"       # 将缓冲区保留在 GPU 显存中
nixl_backends: [UCX]           # UCX 后端足以应对解耦场景
# Decode server config (lmcache-decoder-config.yaml)
enable_pd: true
transfer_channel: "nixl"
pd_role: "receiver"            # this instance receives KV
pd_peer_host: "0.0.0.0"        # bind address for NIXL peer
pd_peer_init_port: 7300        # NIXL handshake/control port
pd_peer_alloc_port: 7400       # NIXL allocation/data port
pd_buffer_size: 1073741824     # 1 GiB (match sender unless you plan to shard)
pd_buffer_device: "cuda"       # keep buffer in GPU memory
nixl_backends: [UCX]           # UCX backend is sufficient for disagg
This configuration allows the prefill to write the KV cache directly into the decode GPU’s memory—up to 1 GB per transfer—with no CPU intervention. Both sides keep the transfer buffer in GPU memory for zero-copy operation.该配置允许预填充将 KV 缓存直接写入解码 GPU 的显存——每次传输最多 1 GB——无需 CPU 介入。双方都将传输缓冲区保留在 GPU 显存中,以实现零拷贝操作。
When sizing the transfer buffer, start at pd_buffer_size = 1 GB. This is roughly a FP16 KV cache estimated at ~4–8k tokens for a model with 70-billion parameters, 80 layers, 32 heads, and 128-dimension heads. Use 2 GB if prompts exceed ~7.5k tokens. You can scale with the dtype and head count: bytes ≈ 2 × L × N × (H × Dh) × bytes_per_val. Make sure to collate pages before transferring. This will avoid small-IO inefficiency.在确定传输缓冲区大小时,从 pd_buffer_size = 1 GB 起步。对于具有 700 亿参数、80 层、32 个注意力头、每头 128 维的模型,这大致相当于约 4–8k token 的 FP16 KV 缓存。如果提示超过约 7.5k token,则使用 2 GB。你可以根据 dtype 和头数进行缩放:bytes ≈ 2 × L × N × (H × Dh) × bytes_per_val。务必在传输前合并页(collate pages),以避免小 I/O 带来的低效。
In practice, one might launch the decode server with the CLI using the following shell script. This will reduce eager fragmentation and encourage rendezvous on larger buffers:在实践中,可以用下面的 shell 脚本通过 CLI 启动解码服务器。这样可以减少 eager 模式的碎片化,并促使在更大的缓冲区上使用 rendezvous 模式:
# 示例解码工作进程
# (按索引或 UUID 选择设备)
UCX_RNDV_THRESH=16384
UCX_MAX_EAGER_RAILS=1
UCX_TLS=cuda_ipc,rc,rdmacm,cuda_copy,cuda_ipc,tcp \
CUDA_VISIBLE_DEVICES=1 \
LMCACHE_CONFIG_FILE=lmcache-decoder-config.yaml \
python run_vllm_decoder.py --port 8200
# Example decode worker
# (select device by index or UUID)
UCX_RNDV_THRESH=16384
UCX_MAX_EAGER_RAILS=1
UCX_TLS=cuda_ipc,rc,rdmacm,cuda_copy,cuda_ipc,tcp \
CUDA_VISIBLE_DEVICES=1 \
LMCACHE_CONFIG_FILE=lmcache-decoder-config.yaml \
python run_vllm_decoder.py --port 8200
You would similarly start the prefill server on another GPU with its config file. These settings ensure the system uses InfiniBand RDMA across nodes or NVLink peer-topeer within a node rather than standard TCP sockets for KV transfer.同样地,你会在另一块 GPU 上用其配置文件启动预填充服务器。这些设置确保系统在跨节点时使用 InfiniBand RDMA,在节点内使用 NVLink 点对点通信,而不是用标准 TCP socket 进行 KV 传输。
With RDMA and proper buffering in place, the handoff latency can be in the single-digit to tens of milliseconds depending on the interconnect and page size. For example, with a 7,500-token context, LMCache measured about 20 milliseconds with many small transfers and about 8 milliseconds after collating into larger blocks. Specifically, it’s recommended to collate 16-token pages into ≥ 128-token slabs before RDMA. This will help reduce per-packet overhead.在具备 RDMA 和恰当缓冲的情况下,交接时延可以低至个位数到数十毫秒,具体取决于互连和页大小。例如,在 7,500 token 的上下文下,LMCache 测得大量小传输时约为 20 毫秒,而合并成更大的块后约为 8 毫秒。具体而言,建议在 RDMA 之前将 16 token 的页合并为 ≥ 128 token 的 slab。这有助于降低每包开销。
In short, disaggregated systems should use fast interconnects and smart data collation to make the prefill → decode transition seamless and fast. Minimizing handoff time is critical because if the handoff is slow, it negates the benefit of parallelizing the phases in the first place.简而言之,解耦系统应使用高速互连和智能数据合并,使预填充 → 解码的过渡无缝且快速。最小化交接时间至关重要,因为如果交接缓慢,就会抵消一开始将各阶段并行化所带来的收益。
连接器与数据路径设计
Connector and Data Path Design
Building on the zero-copy optimization, let’s see how the prefill and decode nodes coordinate the transfer end to end—beyond just moving the bits. The prefill and decode workers often communicate using a scheduler or router. In practice, this scheduler is often implemented as a centralized component, as used in NVIDIA Dynamo, or a decentralized coordination approach, as used by SGLang.在零拷贝优化的基础上,我们来看看预填充节点和解码节点如何端到端地协调传输——而不仅仅是搬运比特。预填充和解码 worker 通常通过调度器或路由器通信。在实践中,该调度器常常实现为集中式组件(如 NVIDIA Dynamo 所采用),或采用去中心化的协调方式(如 SGLang 所采用)。
For instance, NVIDIA Dynamo implements a global scheduling queue in which the decode workers push new prompt tasks into a queue that prefill workers consume. In this design, a decode node enqueues a request for prompt processing, as shown in the “Put RemovePrefillRequest” (step 6) in Figure 18-6.例如,NVIDIA Dynamo 实现了一个全局调度队列,解码 worker 将新的提示任务推入队列,由预填充 worker 消费。在该设计中,解码节点将提示处理请求入队,如图 18-6 中的“Put RemovePrefillRequest”(步骤 6)所示。
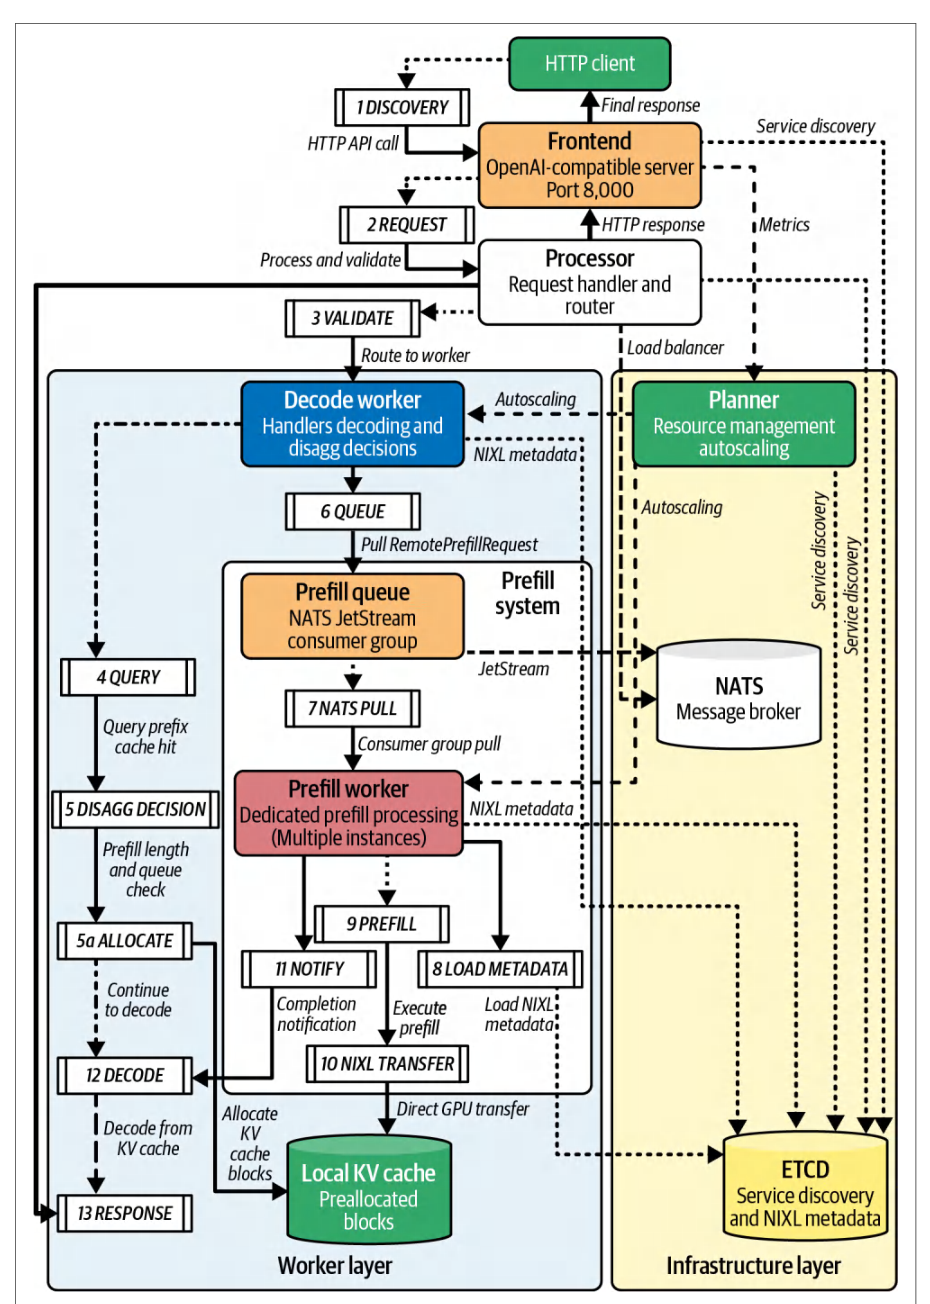
A prefill node picks up this request and, when done, knows exactly which decode node to send the results to since the request carries an origin or reply-to ID for the decode node. The KV is then transferred directly to that decode worker’s GPU using NIXL RDMA.预填充节点取出该请求,完成后能确切知道将结果发送到哪个解码节点,因为请求中携带了解码节点的来源 ID 或回复 ID(reply-to ID)。随后,KV 通过 NIXL RDMA 直接传输到该解码 worker 的 GPU。
In the vLLM + LMCache implementation, a more decentralized approach is used. The decode and prefill processes establish a direct channel using a pipe or buffer for each request’s KV. Under the hood, this might use a one-to-one TCP or RDMA connection negotiated at request start. Rather than a global queue, each request sets up its own transfer channel. Both approaches have pros and cons. The global queue is simpler for load balancing and failure handling. Direct channels can minimize queuing.在 vLLM + LMCache 的实现中,采用了更为去中心化的方式。解码与预填充进程为每个请求的 KV 建立一条直接通道,使用管道或缓冲区。底层可能使用在请求开始时协商建立的一对一 TCP 或 RDMA 连接。与全局队列不同,每个请求都建立自己的传输通道。两种方式各有优劣。全局队列在负载均衡和故障处理上更简单;直接通道则能将排队降到最低。
When deciding which pattern to use, consider your workload and infrastructure constraints. If you need robust multitenant load balancing and easy failover, and you’re comfortable with a small queuing delay, the global-queue model is usually the better fit. Conversely, if you have stringent tail-latency requirements, a relatively stable set of decode-prefill pairs, and high-speed interconnects, the per-request direct-channel approach can minimize hop count and jitter.在决定采用哪种模式时,请考虑你的工作负载与基础设施约束。如果你需要健壮的多租户负载均衡和便捷的故障转移,并且能接受少量排队时延,全局队列模型通常更合适。反之,如果你有严格的尾时延要求、解码-预填充配对相对稳定,且具备高速互连,那么按请求建立直接通道的方式可以最小化跳数与抖动。
The key design goal is to make the pipeline nonblocking and high-throughput such that while one request is being decoded, another prompt can start prefilling—meanwhile, another’s KV can be in transit. As such, no stage sits idle if there is work to do in another stage. This is the exact reason that disaggregation improves overall throughput at scale—all stages are kept busy in parallel.关键的设计目标是让流水线非阻塞且高吞吐,使得当一个请求正在解码时,另一个提示可以开始预填充——与此同时,还有另一个请求的 KV 正在传输中。这样,只要其他阶段有工作可做,就没有阶段会空闲。这正是解耦在大规模下提升整体吞吐量的原因——所有阶段都在并行地保持忙碌。
It’s important to make sure that this pipeline is robust to failures. If a decode node fails mid-generation, a global KV cache pool, discussed earlier, can allow another node to pick up where it left off using the saved KV. Similarly, if a prefill node fails mid-prompt, that prompt can be retried elsewhere. The connector design should handle these failures gracefully so that one node’s failure doesn’t error out the whole request.确保该流水线对故障具有鲁棒性很重要。如果解码节点在生成中途失败,前面讨论的全局 KV 缓存池可以让另一个节点利用已保存的 KV 从断点继续。同样,如果预填充节点在提示处理中途失败,该提示可以在别处重试。连接器设计应优雅地处理这些故障,使单个节点的故障不会导致整个请求出错。
预填充与解码的异构硬件与并行策略
Heterogeneous Hardware and Parallelism Strategies for Prefill and Decode
One powerful advantage of disaggregation is the freedom to choose different hardware—and even a different model-parallel configuration—that best suits the needs of the prefill and decode clusters separately. In a unified, monolithic deployment, you typically have only one hardware type and configuration for both phases. With disaggregation, you can mix and match hardware and strategies per phase, as described next.解耦的一大优势是能够自由选择不同的硬件——甚至不同的模型并行配置——分别最贴合预填充集群与解码集群的需求。在统一的一体化部署中,两个阶段通常只有一种硬件类型和配置。而采用解耦后,你可以按阶段混搭硬件与策略,如下所述。
计算优化型与内存优化型硬件
Compute-Optimized Versus Memory-Optimized Hardware
The prefill phase benefits from GPUs with high compute throughput, lots of TFLOPS, specialized Tensor Cores, and high clock rates. It also benefits from substantial memory bandwidth, but it doesn’t necessarily require massive HBM capacity beyond what the prompt’s KV cache requires.预填充阶段受益于具备高计算吞吐量、大量 TFLOPS、专用张量核心以及高时钟频率的 GPU。它同样受益于可观的显存带宽,但除了提示词所需的 KV 缓存之外,并不一定需要海量的 HBM 容量。
The decode phase, on the other hand, benefits from both large memory capacity and memory bandwidth since it handles many tokens’ worth of KV. It doesn’t need extreme compute power, but the more the better.另一方面,解码阶段同时受益于大容量显存和显存带宽,因为它要处理大量 token 对应的 KV。它不需要极致的算力,但算力越多越好。
This opens up the possibility of using different generations of GPUs for each phase. For example, one design can use the latest high-compute GPUs for the prefill cluster but stick with older-generation or cost-efficient GPUs with sufficient memory bandwidth for the decode cluster.这为每个阶段使用不同代际的 GPU 创造了可能。例如,一种设计可以在预填充集群中使用最新的高算力 GPU,而在解码集群中沿用具备足够显存带宽的旧代际或高性价比 GPU。
This way, we avoid wasting the newest GPUs (e.g., the latest Tensor Cores) on a task like decode that doesn’t use their full potential. The prefill tasks tend to draw more power by maxing out the GPU math units, whereas the decode tasks use far less power on the same GPU.这样一来,我们就避免了把最新的 GPU(例如最新的张量核心)浪费在解码这类无法充分发挥其潜力的任务上。预填充任务往往因让 GPU 数学单元满载而消耗更多功耗,而解码任务在同一块 GPU 上的功耗则低得多。
吞吐量与成本收益
Throughput and cost benefits
Splitting the phases among heterogeneous hardware can improve throughput per cost and throughput per watt. In the Splitwise study, using phase-specific hardware led to one configuration achieving 1.4× higher throughput at 20% lower cost over a homogeneous baseline.将各阶段拆分到异构硬件上,可以提升单位成本的吞吐量和单位功耗的吞吐量。在 Splitwise 研究中,使用针对阶段特化的硬件使某一配置相比同构基线实现了 1.4× 的吞吐量提升,同时成本降低 20%。
In another configuration aimed at max performance under a fixed cost/power budget, they achieved 2.35× more throughput for the same cost and power. Specifically, this study used 4× H100 (high-compute) for prefill and 4× A100 (high-memory) for decode. This mixed configuration achieved ~2.35× the RPS of an 8-GPU homogeneous system (either all H100s or all A100s) at the same cost/power.在另一项以固定成本/功耗预算下最大化性能为目标的配置中,他们在相同成本和功耗下获得了 2.35× 的吞吐量。具体而言,该研究使用 4× H100(高算力)做预填充、4× A100(大显存)做解码。这一混合配置在相同成本/功耗下达到了 8 GPU 同构系统(全 H100 或全 A100)约 2.35× 的 RPS。
Alternatively, they found that, to match the baseline throughput, the heterogeneous system could actually use fewer GPUs overall (e.g., five or six instead of eight) by offloading decode to cheaper GPUs. This highlights the cost-savings opportunity and shows the value of using each type of GPU where it’s most effective. Specifically, you can perform compute-bound work on the highest-compute-per-dollar GPUs (e.g., Blackwell or Rubin generation) and assign memory-bound work to more cost-efficient older-generation GPUs with suitable memory bandwidth (e.g., Hopper or Ampere).另外,他们发现,若要达到基线吞吐量,异构系统实际上可以使用更少的 GPU(例如用五到六块而非八块),只需把解码卸载到更便宜的 GPU 上。这凸显了节省成本的机会,也说明了把每类 GPU 用在最能发挥其效力之处所具有的价值。具体来说,你可以把计算受限的工作放在每美元算力最高的 GPU(例如 Blackwell 或 Rubin 代际)上,而把显存受限的工作分配给具备合适显存带宽、性价比更高的旧代际 GPU(例如 Hopper 或 Ampere)。
The Splitwise evaluation accounted for the overhead of state transfer between heterogeneous GPUs. This test transferred KV data over an NVSwitch fabric and incurred minimal overhead—even between different generations of GPUs. This indicates that high-bandwidth interconnects like NVSwitch and NVLink can enable prefill/decode disaggregation with negligible impact on performance—even in mixed-GPU setups.Splitwise 的评估计入了异构 GPU 之间状态传输的开销。该测试通过 NVSwitch 互联结构传输 KV 数据,开销极小——即使是在不同代际的 GPU 之间也是如此。这表明,像 NVSwitch 和 NVLink 这样的高带宽互连能够支撑预填充/解码解耦,对性能的影响可以忽略不计——即便在混合 GPU 的部署中也是如此。
Another system is HexGen-2, which is a distributed inference framework that treats the allocation of disaggregated inference on heterogeneous GPUs as an optimization problem. Its scheduler optimizes resource allocation, per-phase parallelism strategy, and communication efficiency together.另一个系统是 HexGen-2,它是一个分布式推理框架,把异构 GPU 上解耦推理的资源分配视为一个优化问题。其调度器将资源分配、各阶段的并行策略以及通信效率放在一起联合优化。
In experiments on models like Llama 2 70B, HexGen-2 shows up to a 2× improvement in serving throughput (~1.3× on average) as compared to state-of-the-art systems at the same price point. Additionally, it achieves similar throughput to a high-end baseline while using approximately 30% less cost. These improvements came from mixing GPU types and optimizing the work split. This is basically an automated way to do what Splitwise did conceptually.在 Llama 2 70B 等模型上的实验中,HexGen-2 在相同价格点上相比最先进的系统,服务吞吐量最高提升 2×(平均约 1.3×)。此外,它在使用约少 30% 成本的情况下,达到了与高端基线相近的吞吐量。这些改进来自混合 GPU 类型并优化工作划分。这基本上是以自动化的方式实现 Splitwise 在概念上所做的事情。
These results confirm that disaggregation is not just about speed. It’s also about efficiency and doing more with less. When deploying inference in a cloud environment, this can lead to significant cost savings on the order of millions of dollars in GPU time for a large inference service supporting millions or billions of end users.这些结果证实,解耦不仅仅关乎速度,也关乎效率和以更少资源做更多事。在云环境中部署推理时,对于一个支撑数百万乃至数十亿终端用户的大型推理服务,这可能带来数百万美元量级的 GPU 时间成本节省。
For instance, you can fulfill the same traffic with 6 GPUs (prefill + decode mix) instead of 8 top-tier GPUs; you can save roughly 25% on hardware costs for that service. As such, disaggregation lets you serve more users on the same hardware. This is critical since GPU supply is often limited—especially for the latest GPUs.例如,你可以用 6 块 GPU(预填充 + 解码混合)而不是 8 块顶级 GPU 来承载相同的流量;该服务的硬件成本可节省约 25%。因此,解耦让你能在相同的硬件上服务更多用户。这一点至关重要,因为 GPU 供应往往有限——尤其是最新的 GPU。
Energy efficiency is also important given power constraints in certain parts of the world, including the United States. Splitwise demonstrated better power efficiency by running decode tasks on lower-power GPUs—at a slight decrease in speed.考虑到包括美国在内的世界某些地区存在供电限制,能效同样重要。Splitwise 通过将解码任务运行在功耗更低的 GPU 上,展示了更好的能效——代价是速度略有下降。
By assigning prefill and decode tasks onto different hardware types, you can choose where and how to run each phase to increase performance and reduce cost. Disaggregation allows this flexibility since phases are independent.通过将预填充与解码任务分配到不同的硬件类型上,你可以选择每个阶段的运行位置与运行方式,从而提升性能并降低成本。由于各阶段相互独立,解耦提供了这种灵活性。
In short, the evaluations from Splitwise, HexGen-2, and related heterogeneous deployment studies show that disaggregation can be leveraged for cost optimization in addition to pure speed. By matching hardware to workload, you can significantly reduce the cost per query and, at the same time, increase performance within a fixed budget.简而言之,来自 Splitwise、HexGen-2 以及相关异构部署研究的评估表明,解耦除了带来纯粹的速度提升,还可用于成本优化。通过让硬件与工作负载相匹配,你可以显著降低每次查询的成本,同时在固定预算内提升性能。
For large-scale services, this is critical to keep them economically viable. The trade-offs include a bit more system complexity because you have to manage multiple GPU types. And you will be limited in cluster-configuration flexibility and dynamic reallocation of GPUs across prefill and decode tasks since the GPUs are not matched in capabilities. But, in many cases, using different hardware for each phase may be worth the efficiency gains.对于大规模服务而言,这对维持其经济可行性至关重要。代价包括系统复杂度略有增加,因为你必须管理多种 GPU 类型。此外,由于各 GPU 的能力并不匹配,集群配置的灵活性以及在预填充与解码任务之间动态重新分配 GPU 的能力都会受到限制。但在许多情况下,为每个阶段使用不同硬件所带来的效率收益或许是值得的。
阶段专属的模型并行
Phase-specific model parallelism
Another form of heterogeneity and per-phase specialization is choosing different model parallelism (e.g., tensor parallel, pipeline parallel, etc.) across GPUs for each phase. This is relevant for very large models sharded across GPUs due to memory constraints.异构性与按阶段专用化的另一种形式,是为每个阶段选择不同的模型并行方式(例如张量并行、流水线并行等)来跨 GPU 运行。对于因内存限制而分片到多块 GPU 上的超大模型,这一点尤为重要。
In a traditional setup, you might run the model with a fixed parallelism strategy and split the model across multiple GPUs using tensor parallelism or pipeline parallelism for both the prefill and decode phases. But the optimal parallelism strategy for prefill may not be the same for decode.在传统部署中,你可能会以固定的并行策略运行模型,并在预填充与解码两个阶段都使用张量并行或流水线并行将模型切分到多块 GPU 上。但预填充的最优并行策略未必与解码相同。
For instance, the prefill phase is a big forward pass through N prompt tokens, and it benefits from a high degree of parallelization. You can use tensor parallelism (TP) across many GPUs to perform the computations faster and reduce TTFT.例如,预填充阶段是对 N 个提示词 token 的一次大规模前向传播,它能从高度并行化中获益。你可以跨多块 GPU 使用张量并行(TP)来更快地完成计算并降低 TTFT。
The overhead of synchronizing the GPUs is amortized over the large number of tokens that can be processed at once. This reduces the wall-clock time of this stage, which is critical for TTFT.GPU 之间同步的开销被一次性可处理的大量 token 所摊薄。这缩短了该阶段的挂钟时间,而这对 TTFT 至关重要。
You might even use pipeline parallelism (PP) to further speed up prefill and increase throughput. This would split the model layers across GPUs and stream the prompt through multiple pipeline stages.你甚至可以使用流水线并行(PP)来进一步加速预填充并提升吞吐量。这会按层将模型切分到多块 GPU 上,并让提示词流经多个流水线阶段。
The decode phase, on the other hand, is sequential and latency-sensitive per step. Using too many GPUs for one decode can actually hurt time-per-output-token (TPOT) latency, also called inter-token latency (ITL). This is because each token step would require additional multi-GPU communication overhead. As such, the potential for speedup is limited since there’s only one token’s worth of compute to split at a time (or a few tokens, if using speculative decoding).另一方面,解码阶段是串行的,且对每一步的时延都很敏感。为单次解码使用过多 GPU 实际上会恶化每输出 token 时间(TPOT)时延,也称为*token 间时延*(ITL)。这是因为每个 token 步骤都会带来额外的多 GPU 通信开销。因此,加速潜力有限,因为一次只有相当于一个 token 的计算量可供切分(若使用投机解码,则为几个 token)。
Disaggregation makes it possible to mix these approaches and use TP for one phase and PP for another—or use different degrees of each technique. For instance, you can run prefill with TP=8 to span 8 GPUs and minimize prompt latency. You can then run decode with TP=1, or a single GPU, to maximize per-token throughput and minimize step latency. In this way, each phase’s throughput and latency can be tuned separately, as shown in Figure 18-7.解耦使得混合这些方法成为可能:一个阶段使用 TP,另一个阶段使用 PP——或者对每种技术使用不同的并行度。例如,你可以用 TP=8 运行预填充以跨越 8 块 GPU,从而最小化提示词时延。随后你可以用 TP=1(即单块 GPU)运行解码,以最大化每 token 吞吐量并最小化单步时延。这样,每个阶段的吞吐量与时延都可以单独调优,如图 18-7 所示。
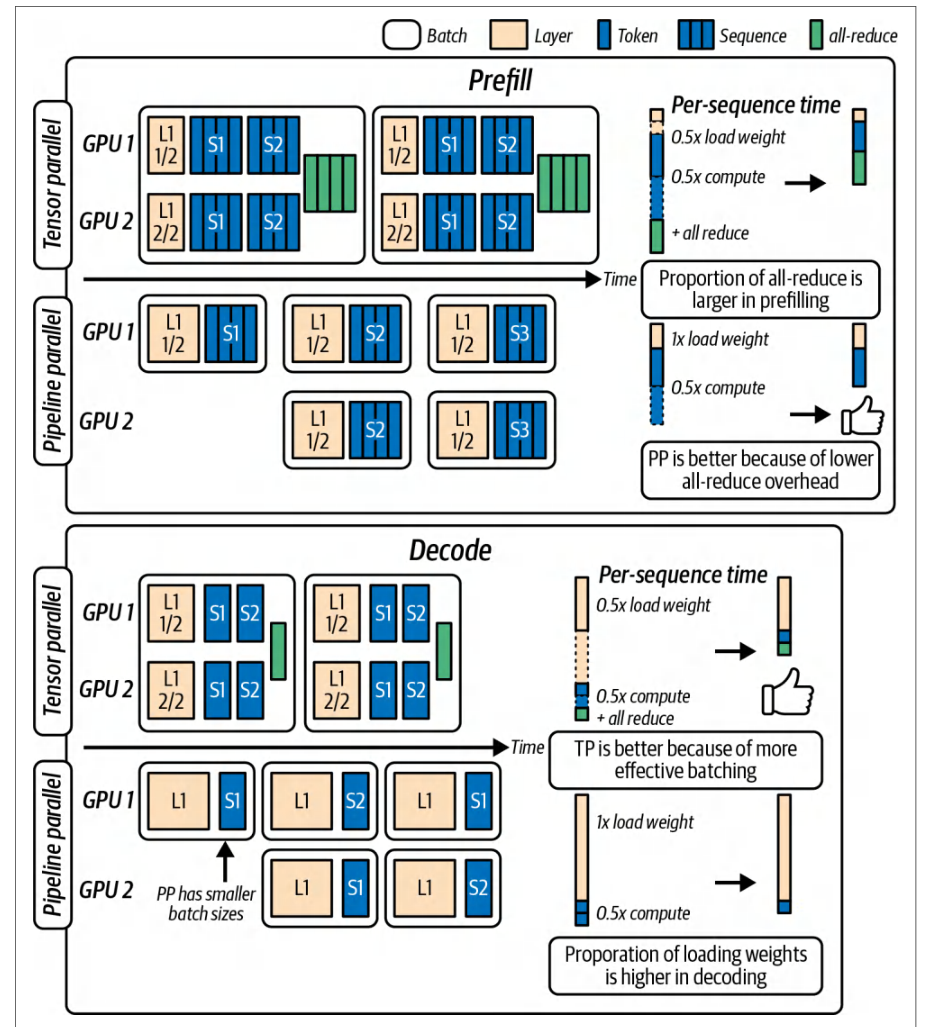
Here, tensor parallelism’s additional all-reduce communication overhead is more prominent during the prefill stage since a large number of tokens are being processed in parallel. As such, we choose pipeline parallelism because it’s more efficient for our prefill workload.在这里,张量并行带来的额外全归约通信开销在预填充阶段更为突出,因为此时有大量 token 正在被并行处理。因此,我们选择流水线并行,因为它对预填充工作负载更高效。
For the decode phase, however, pipeline parallelism can lead to more, albeit smaller, forward passes as the tokens are passed between GPUs. This requires a lot of data movement in and out of the GPUs for just a single token generation. As such, we choose tensor parallelism because it’s better suited for our decoding workload.然而对于解码阶段,流水线并行会导致更多(尽管更小)的前向传播,因为 token 需要在 GPU 之间传递。仅为生成单个 token,就需要大量数据进出 GPU。因此,我们选择张量并行,因为它更适合我们的解码工作负载。
This introduces a complication, however. Since our model’s parallelization scheme differs between the prefill and decode, the format of the KV cache must differ as well. For instance, if the prefill phase uses TP = 1 (since it’s using PP) with four GPUs, each of the four GPUs has a full-size KV tensor.然而这会带来一个复杂问题。由于我们的模型在预填充与解码之间的并行化方案不同,KV 缓存的格式也必须不同。例如,如果预填充阶段使用 TP = 1(因为它使用 PP)并占用四块 GPU,那么这四块 GPU 各自持有一份完整大小的 KV 张量。
And let’s say the decode phase uses TP = 4. In this case, each GPU expects only 1/4 of the KV tensors since the data should be split up along the model’s hidden size. To handle this, systems like NVIDIA Dynamo can perform KV transposes, or conversions, during the transfer. Essentially, it converts and rearranges the KV cache from [TP_p parts] into the format needed by [TP_d parts], where TP_p is prefill’s parallel degree and TP_d is decode’s parallel degree.再假设解码阶段使用 TP = 4。在这种情况下,每块 GPU 只期望得到 1/4 的 KV 张量,因为数据应沿模型的隐藏维度切分。为处理这一点,NVIDIA Dynamo 等系统可以在传输过程中执行 KV 转置(或称转换)。本质上,它把 KV 缓存从 [TP_p parts] 转换并重排为 [TP_d parts] 所需的格式,其中 TP_p 是预填充的并行度,TP_d 是解码的并行度。
Dynamo includes a high-performance kernel to do this transpose on the fly after reading from NIXL—and before writing into the decode worker’s memory. This way, the receiving decode gets the KV cache data in the layout that it expects.Dynamo 包含一个高性能内核,在从 NIXL 读取之后、写入解码 worker 的内存之前,即时完成这一转置。这样,接收端的解码就能以它期望的布局获得 KV 缓存数据。
The overhead of this transpose can be small compared to the network transfer, however—especially given NVLink throughput, which can handle these data reor-ganizations quickly. In this case, it’s easily justified by the compute savings of using different parallelism strategies optimized for each phase.不过,与网络传输相比,这一转置的开销可能很小——尤其考虑到 NVLink 的吞吐量,它可以快速处理这些数据重排。在这种情况下,使用针对各阶段优化的不同并行策略所带来的计算节省,足以证明这一开销是合理的。
Let’s explore an example of phase-specific parallelism. Consider a large model where we can apply various parallelism schemes: tensor (TP), pipeline (PP), data (DP), sequence (SP, splitting sequences across GPUs), etc. We might choose separate parallelism configurations. Table 18-1 shows an example parallelism configuration for the prefill phase.让我们探讨一个阶段专用并行的示例。考虑一个大型模型,我们可以应用多种并行方案:张量并行(TP)、流水线并行(PP)、数据并行(DP)、序列并行(SP,将序列拆分到多块 GPU)等。我们可能选择各自独立的并行配置。表 18-1 展示了预填充阶段的一个并行配置示例。
| Parallelism strategy并行策略 | Symbol符号 | Value值 | Description描述 |
|---|---|---|---|
| Tensor parallelism张量并行 | TP_pTP_p | 22 | Split the model’s weight tensors across 2 GPUs to halve prefill latency with manageable communication overhead.将模型的权重张量拆分到 2 个 GPU 上,以在通信开销可控的情况下将预填充时延减半。 |
| Pipeline流水线 | PP_pPP_p | 22 | Divide the model layers into two pipeline stages, streaming microbatches through将模型层划分为两个流水线阶段,使微批数据流经 |
| parallelism并行 | each stage for deep models.每个阶段,适用于深层模型。 | ||
| Sequence序列 | SP_pSP_p | 11 | Do not split the input sequence across GPUs (no sequence sharding) unless不要将输入序列拆分到多个 GPU 上(不做序列分片),除非 |
| parallelism并行 | processing extremely large contexts.处理极长上下文。 | ||
| Context parallelism上下文并行 | CPCP | 11 | Keep the entire context on a single GPU (no context-level partitioning) when it fits in memory after optimizations.当优化后整个上下文能够放入内存时,将其完整保留在单个 GPU 上(不做上下文级切分)。 |
| Data parallelism数据并行 | DP_pDP_p | 1 (or 2)1(或 2) | Use one model replica per GPU (or two for doubled throughput on batched prompts by weight replication).每个 GPU 使用一个模型副本(或使用两个副本,通过权重复制使批量提示词的吞吐量翻倍)。 |
| Parallelism strategy并行策略 | Symbol符号 | Value值 | Description描述 |
|---|---|---|---|
| Tensor张量 | TP_dTP_d | 1 (default)1(默认) | Default to TP_d = 1 for simplicity and minimal sync overhead.为简化实现并将同步开销降至最低,默认取 TP_d = 1。 |
| parallelism并行 | ... N (number of GPUs)… N(GPU 数量) | TP_d = N number of GPUs can improve efficiency for tiny GEMMs on small batches or when a single GPU can’t hold the model.TP_d = N 块 GPU 可提升小批量下微小 GEMM 的效率,或在单块 GPU 无法容纳模型时提升效率。 | |
| Pipeline流水线 | PP_dPP_d | 11 | Pipeline parallelism adds bubbles for single-token decoding, so PP_d = 1流水线并行在单 token 解码时会引入气泡,因此 PP_d = 1 |
| parallelism并行 | avoids idle stages.可避免流水级空闲。 | ||
| Sequence序列 | SP_dSP_d | 11 | Splitting the output sequence across GPUs is uncommon.将输出序列拆分到多块 GPU 上并不常见。 |
| parallelism并行 | SP_d = 1 keeps each decode stream local unless handling extremely long outputs.除非需要处理极长的输出,否则 SP_d = 1 可使每条解码流保持在本地。 | ||
| Data parallelism数据并行 | DP_dDP_d | 11 | One model replica per GPU per decode stream. Use separate replicas to handle parallel requests rather than replicating for a single stream.每个解码流在每个 GPU 上放置一个模型副本。使用独立副本处理并行请求,而不是为单个流做复制。 |
These numbers minimize inter-GPU overhead while still using multiple GPUs to speed up big prompts. Next, let’s look at an example parallelism strategy for decode, as shown in Table 18-2.这些数值在仍然使用多个 GPU 加速大提示词的同时,将 GPU 间开销降到最低。接下来,我们看一个用于解码的并行策略示例,如表 18-2 所示。
Ideally, each decode stream runs on a single GPU and avoids cross-GPU overhead. This is possible only if the model fits into GPU memory. In this case, TP_d = 1, which means it’s not using any tensor parallelism during decode. If the model can’t fit into memory, you can increase the degree of tensor parallelism (e.g., TP_d = N, where N is the number of GPUs).理想情况下,每个解码流都在单个 GPU 上运行,避免跨 GPU 开销。只有当模型能放入 GPU 显存时才可能做到这一点。此时 TP_d = 1,意味着解码期间不使用任何张量并行。如果模型无法放入显存,可以提高张量并行度(例如 TP_d = N,其中 N 是 GPU 数量)。
Increasing tensor parallelism is also useful if the system is issuing tiny GEMMs to process small batches. This is because distributing small matrix multiplications across devices can hide communication latency behind computation and potentially produce higher overall throughput.如果系统正在发出微小的 GEMM 来处理小批量,提高张量并行也很有用。这是因为将小矩阵乘法分布到多个设备上,可以把通信时延隐藏在计算之后,并有可能带来更高的整体吞吐量。
These are illustrative values, but the main point is that disaggregation allows you to configure resources separately on the prompt side to reach a TTFT target. At the same time, you can independently adjust resources on the decode side to hit throughput and latency targets for streaming tokens back to the end user.这些只是示例性数值,但要点在于:解耦让你可以在提示词侧单独配置资源以达到 TTFT 目标,同时可以在解码侧独立调整资源,以满足将 token 流式返回给最终用户时的吞吐量和时延目标。
This way, the two parallelism strategies do not interfere with each other. In a unified system, if you tried to do this, you’d have to pick one compromise strategy that works suboptimally for both phases.这样一来,两种并行策略互不干扰。在统一系统中,如果尝试这样做,就必须选择一种折中策略,而该策略对两个阶段的运行效果都不理想。
预填充与解码使用不同精度
Different precision for prefill and decode
Some inference engines let you use different precision between prefill and decode. For example, you could perform prefill in a lower precision, such as FP8, INT8, or FP4, to speed it up. At the same time, you could decode in a higher precision if needed for better generation accuracy.一些推理引擎允许在预填充和解码之间使用不同的精度。例如,可以用较低的精度(如 FP8、INT8 或 FP4)执行预填充以加速。同时,如果需要更好的生成准确度,可以用更高的精度进行解码。
Generally, you have both run in the same precision so that the KV cache computed in the prefill phase is usable in the decode phase. However, you can apply a conversion similar to the parallelism conversion described in the previous section. You would choose to quantize the KV and compress from FP16 to INT8/FP8/FP4 before sending. You would then convert it back on the receiving end, if needed.通常,两者以相同精度运行,以便预填充阶段计算出的 KV 缓存可以在解码阶段使用。不过,你可以应用类似上一节所述并行转换的精度转换。你可以选择在发送前对 KV 进行量化,从 FP16 压缩到 INT8/FP8/FP4,然后在接收端按需转换回来。
For instance, you can choose to send the lower precision over the network to speed up the transfer. Or you could choose to perform the conversion on the sender or receiver based on available FLOPS, etc.例如,你可以选择在网络上发送较低精度以加快传输;也可以根据可用的 FLOPS 等条件,选择在发送端或接收端执行转换。
These are advanced ideas. But they highlight that nearly every aspect—hardware type, number of GPUs, and precision—can be independently tuned for each phase in a disaggregated setup.这些是进阶思路。但它们凸显了一点:在解耦架构中,几乎每个方面——硬件类型、GPU 数量和精度——都可以针对每个阶段独立调优。
GPU-CPU 协作的混合预填充
Hybrid Prefill with GPU-CPU Collaboration
So far, we have assumed that both the prefill and decode phases run on GPUs—and possibly different types of GPUs. However, at extreme scales—or with extremely large models and prompts—it’s worth evaluating if CPUs can offload pressure from GPUs.到目前为止,我们一直假设预填充和解码两个阶段都运行在 GPU 上——而且可能是不同类型的 GPU。然而,在极端规模下——或者面对极大规模的模型和提示词时——值得评估 CPU 能否分担 GPU 的压力。
Modern CPUs are far slower than GPUs for neural network computations, but they come with other advantages like ample RAM, no contention for GPU memory bandwidth, and flexibility to handle tasks that GPUs might not handle as well, like extremely long sequences and nontransformer operations like tokenization, padding, etc.在神经网络计算方面,现代 CPU 远慢于 GPU,但它们具备其他优势,例如充裕的 RAM、不与 GPU 争抢显存带宽,以及能够灵活处理 GPU 可能不太擅长的任务,比如超长序列,以及分词、填充等非 Transformer 运算。
With a hybrid prefill strategy, part of the prefill computation is done on CPUs. One scenario is CPU offloading for superlong prompts. Consider a prompt with tens of thousands of tokens from a large document attachment. Even a powerful GPU might struggle to process such a large prompt due to memory constraints.采用混合预填充策略时,一部分预填充计算由 CPU 完成。一种场景是针对超长提示词的 CPU 卸载。设想一个来自大型文档附件的、包含数万个 token 的提示词。受显存限制,即便是强大的 GPU 也可能难以处理如此庞大的提示词。
In the case of extremely long prompts, the system could choose to perform the initial layers of the model on a CPU worker with lots of RAM to hold the long sequence. It would then stream intermediate results to a GPU later—or even perform the entire prefill on the CPU if latency isn’t an issue. The decode GPU would then receive the huge KV cache from the CPU worker.对于极长的提示词,系统可以选择在拥有大量 RAM、足以容纳长序列的 CPU 工作节点上执行模型的初始层。随后再把中间结果流式传输到 GPU——如果时延不是问题,甚至可以在 CPU 上完成整个预填充。解码 GPU 随后会从该 CPU 工作节点接收庞大的 KV 缓存。
A practical use of CPU offloading is processing background or low-priority prefill tasks. For instance, an LLM service might allow very large prompt submissions for offline processing of noninteractive requests. These could be assigned to CPU-only workers that eventually feed into a decode GPU for fast token generation. The latency would be high since CPUs are slower, but since it’s an offline job, this might be acceptable. And this configuration frees up GPU resources for more interactive workloads.CPU 卸载的一个实际用途是处理后台或低优先级的预填充任务。例如,某个 LLM 服务可能允许提交超大的提示词,以便对非交互式请求进行离线处理。这些请求可以分配给纯 CPU 工作节点,最终再送入解码 GPU 以快速生成 token。由于 CPU 较慢,时延会很高,但既然是离线任务,这或许可以接受。而且这种配置还能释放 GPU 资源,用于更多交互式工作负载。
Hybrid prefill is more common on CPU-GPU superchips like Grace Blackwell, in which the chip-to-chip interconnect is super fast. And it leverages the fact that CPU memory is massive compared to GPU memory.在 Grace Blackwell 这类 CPU-GPU 超级芯片上,混合预填充更为常见,因为其芯片间互连速度极快。它还利用了 CPU 内存相比 GPU 显存容量巨大这一事实。
Imagine storing a gigantic KV cache in CPU memory with fast access from the GPU. A hybrid prefill would use the CPU’s memory to buffer or preprocess input tokens while the GPU focuses on the heavy transformer layers.设想把庞大的 KV 缓存存放在 CPU 内存中,同时 GPU 能快速访问。混合预填充会利用 CPU 的内存来缓冲或预处理输入 token,而 GPU 则专注于繁重的 Transformer 层。
A Grace Blackwell Superchip could handle a massive context by letting the CPU manage memory and initial layers and the GPU handle dense attention on chunks of the sequence. The Grace CPU could also be used to spill KV cache data that doesn’t fit in HBM into CPU DDR memory. This effectively extends the context length that the GPU can support.Grace Blackwell 超级芯片可以让 CPU 管理内存和初始层、让 GPU 对序列分块执行密集注意力,从而处理超大的上下文。Grace CPU 还可以用来把无法放入 HBM 的 KV 缓存数据溢出到 CPU 的 DDR 内存中。这实际上扩展了 GPU 所能支持的上下文长度。
You can slice the transformer across devices by running the first N layers on the GPU in which the bulk of the tokens are handled and the sequence is essentially compressed. You would then offload the next M layers to the CPU, which has lots of memory, before finally bringing the remaining layers back onto the GPU to generate the final outputs.你可以把 Transformer 切分到不同设备上:在 GPU 上运行前 N 层,此时大部分 token 已被处理、序列实质上已被压缩。然后把接下来的 M 层卸载到拥有大量内存的 CPU,最后再把剩余的层放回 GPU 以生成最终输出。
This layer-partitioning technique adds significant data movement and orchestration complexity—and should be justified only in rare cases, such as ultralong contexts or severe GPU memory limits. Regardless, it shows how you can push hardware boundaries in extreme inference scenarios.这种层划分技术会带来大量数据移动和编排复杂度——只有在极少数情况下才值得采用,例如超长上下文或 GPU 显存严重受限。无论如何,它展示了在极端推理场景下如何突破硬件边界。
In our disaggregated architecture, involving CPUs would mean introducing a third kind of worker: the CPU prefill worker. The scheduling logic could then choose among three options: GPU prefill worker, CPU prefill worker, or local decode GPU prefill. The decision would depend on factors like prompt length or priority.在我们的解耦架构中,引入 CPU 意味着增加第三类工作节点:CPU 预填充工作节点。调度逻辑随后可以在三种选项中选择:GPU 预填充工作节点、CPU 预填充工作节点,或本地解码 GPU 预填充。决策取决于提示词长度或优先级等因素。
For instance, the policy might be: if prompt_length > 5,000, route to a CPU prefill worker, knowing it will be slow but at least it won’t tie up GPUs and can use large memory. The decode stage would then wait longer for KV. Or possibly, in an extreme case, the decode could also be done on the CPU if truly offline.例如,策略可能是:如果 prompt_length > 5,000,就路由到 CPU 预填充工作节点,明知它会很慢,但至少不会占用 GPU,而且可以使用大容量内存。随后解码阶段等待 KV 的时间会更长。或者在极端情况下,如果确实是离线场景,解码也可以在 CPU 上完成。
Generally, CPU offload would increase TTFT, so it’s not used for normal latency-sensitive requests. It’s more of an extensibility and safety-net feature. If utilized, the system should monitor how often this path is taken, as frequent CPU offloads might indicate the need for more GPU capacity or model optimization instead.一般来说,CPU 卸载会增加 TTFT,因此不会用于常规的时延敏感请求。它更像是一种可扩展性与安全兜底特性。如果启用,系统应监控该路径被采用的频率,因为频繁的 CPU 卸载可能表明需要更多 GPU 容量,或者需要做模型优化。
CPU offload also allows the system to handle edge cases like super long inputs or bursts when GPUs are all busy. It does this by falling back to the slower CPU rather than failing entirely. However, remember that it’s best to fail fast if the processing is too slow and exceeds SLO requirements.CPU 卸载还使系统能够处理超长输入,或 GPU 全部繁忙时的突发流量等边缘情况。其做法是回退到较慢的 CPU,而不是彻底失败。不过请记住,如果处理过慢并超出 SLO 要求,最好快速失败。
From a cost perspective, using CPUs for some work can be more economical since CPU cores are cheaper than GPU hours. Some cloud providers might run a mix of GPU and CPU instances for LLM serving. The CPUs perform input preprocessing— or even small model inferences—before engaging the GPUs.从成本角度看,用 CPU 承担部分工作可能更经济,因为 CPU 核时比 GPU 机时更便宜。一些云服务商可能会为 LLM 服务混合运行 GPU 和 CPU 实例。CPU 在动用 GPU 之前完成输入预处理——甚至小模型推理。
In short, while core disaggregation logic focuses on distributing work across GPUs, a robust ultrascale inference system can leverage CPUs in creative ways for certain parts of the workload. As hardware evolves and moves toward tightly coupled CPU-GPU superchip designs like Grace Blackwell, the line between using a GPU and CPU will blur.简而言之,虽然核心的解耦逻辑侧重于在 GPU 之间分配工作,但一个健壮的超大规模推理系统可以创造性地利用 CPU 承担工作负载的某些部分。随着硬件演进并走向 Grace Blackwell 这类紧耦合的 CPU-GPU 超级芯片设计,使用 GPU 与 CPU 之间的界线将变得模糊。
Efficient scheduling should consider all available compute resources. The guiding principle remains the same, however. Use GPUs for what they do best, including massive parallel compute on moderate sequence lengths. And use CPUs when GPUs might be inefficient, such as for extremely long sequences, memory-heavy tasks, or low-priority tasks.高效的调度应考虑所有可用的计算资源。不过,指导原则依然不变:把 GPU 用在它最擅长的地方,包括在中等序列长度上进行大规模并行计算;而当 GPU 可能效率不高时——例如极长序列、显存密集型任务或低优先级任务——则使用 CPU。
SLO 感知的请求管理与容错
SLO-Aware Request Management and Fault Tolerance
To hit SLO targets at ultrascale, it’s not enough to scale and schedule efficiently. Sometimes you need to also reject or defer work that would violate SLOs under the current load. We touched on this with Mooncake’s early rejection.要在超大规模下达成 SLO 目标,仅靠高效扩展与调度是不够的。有时还需要拒绝或推迟那些在当前负载下会违反 SLO 的工作。我们在 Mooncake 的提前拒绝中已有所涉及。
提前拒绝(准入控制)
Early Rejection (Admission Control)
Early rejection, or admission control, was introduced in Chapter 17. In short, it means that if the system predicts that it cannot serve a request within the latency target, it will fail fast by returning an error or responding with “please try later.” This prediction can be based on current queue lengths, recent throughput, or even a lightweight ML model that forecasts response time.提前拒绝,即准入控制,已在第 17 章介绍。简而言之,如果系统预测无法在时延目标内服务某个请求,就会快速失败,返回错误或响应“请稍后重试”。这种预测可以基于当前队列长度、近期吞吐量,甚至基于一个预测响应时间的轻量级机器学习模型。
Early rejection is in contrast to queuing the request and then missing its SLO dead-line. This preserves goodput by making sure requests served by the inference system will meet their guarantees.提前拒绝与“先将请求排队、随后又错过其 SLO 截止时间”形成对照。它通过确保推理系统所服务的请求能够满足其保证,来维持有效吞吐。
In Mooncake, the early rejection strategy evaluates incoming requests against the estimated load on both the prefill and decode clusters. For instance, consider a decode cluster that is currently handling a large number of long sequences.在 Mooncake 中,提前拒绝策略会依据预填充集群和解码集群的预估负载来评估传入请求。例如,设想一个当前正在处理大量长序列的解码集群。
When a new request arrives, and based on its expected output length, the system determines if decode utilization would surpass a safe threshold. Here, the system will immediately reject or defer that request and free up resources on the GPU node, as shown in Figure 18-8.当新请求到达时,系统根据其预期输出长度判断解码利用率是否会超过安全阈值。此时,系统会立即拒绝或推迟该请求,并释放 GPU 节点上的资源,如图 18-8 所示。
By doing so, you prevent a situation where the request sits in the queue and then takes so long that it surpasses its latency SLO and slows down all other requests by consuming scarce compute or memory bandwidth resources. This reinforces the fact that it’s better to return a quick “too busy” response than to silently accept and then fail the latency guarantee.这样做可以避免出现请求滞留在队列中、等待过久以致超出其时延 SLO,并通过占用稀缺的计算或显存带宽资源拖慢所有其他请求的情况。这也进一步印证:与其静默接受、随后又无法兑现时延保证,不如快速返回一个“太忙”的响应。
This is analogous to how web servers shed load under extreme overload to keep serving the remaining requests with acceptable latency—the dreaded HTTP 503 error. This is better than timing out all requests.这类似于 Web 服务器在极端过载时卸载负载,以便以可接受的时延继续服务其余请求——即令人头疼的 HTTP 503 错误。这比让所有请求都超时更好。
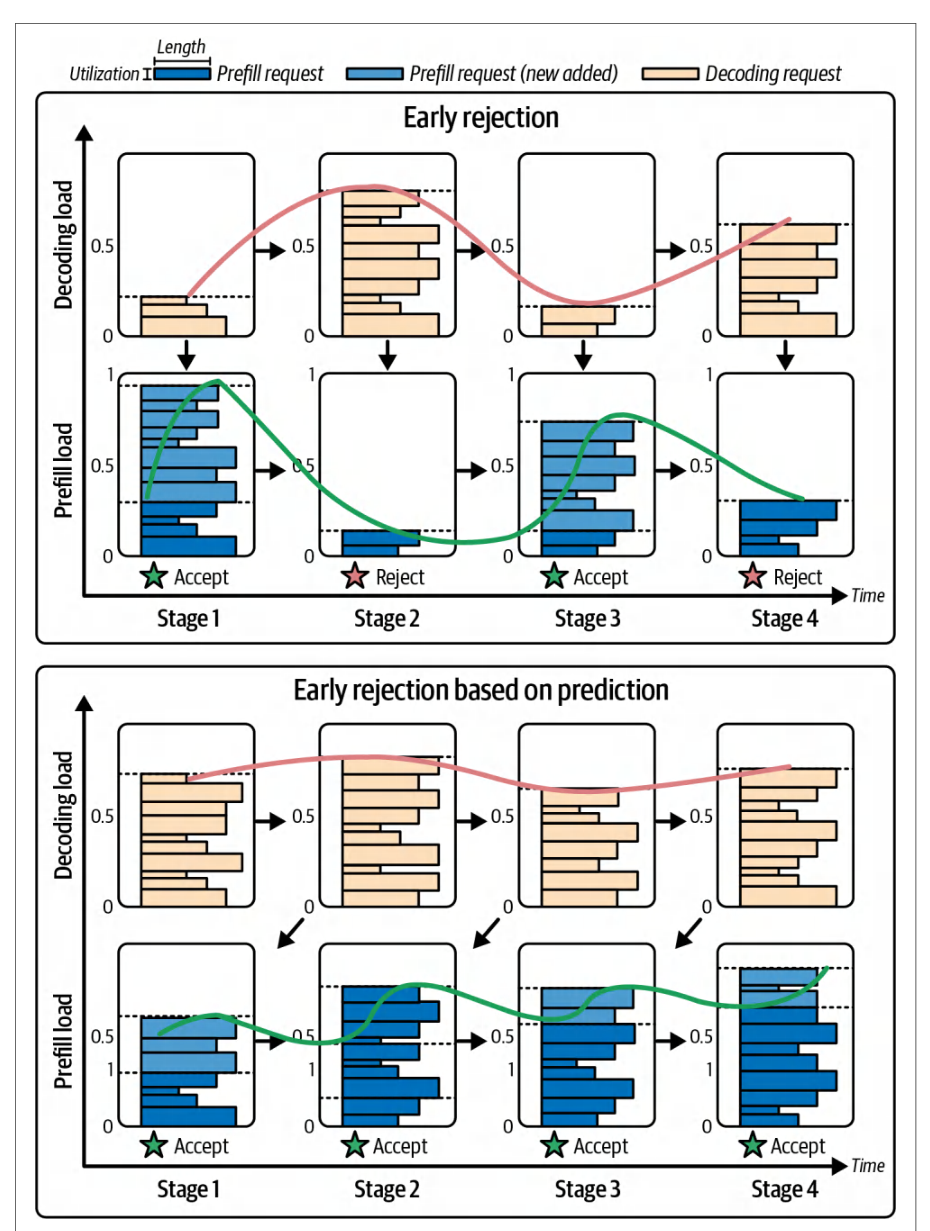
In LLM serving, because request sizes and durations vary widely, having a clear admission control step helps maintain performance for accepted requests. A well-behaved admission control keeps the system in a regime where it can meet both TTFT and TPOT targets for the load that it has accepted.在 LLM 服务中,由于请求大小和持续时间差异很大,设置一个明确的准入控制步骤有助于为已接受的请求维持性能。行为良好的准入控制会让系统保持在一个能够为已接受的负载同时满足 TTFT 和 TPOT 目标的状态。
It effectively sets a limit on concurrent work. If doing more would break the SLO, it won’t attempt it. This must be combined with scaling policies. For instance, you can scale up rather than reject. However, since scale-up is typically not instantaneous—or you’re at max capacity—rejection is the safest and most performant option in the long run.它实际上为并发工作设定了上限。如果做更多会破坏 SLO,它就不会尝试。这必须与扩缩容策略结合使用。例如,你可以选择扩容而不是拒绝。然而,由于扩容通常不是瞬时的——或者你已经处于最大容量——从长远来看,拒绝是最安全且性能最好的选择。
服务质量
Quality of Service
Another aspect of SLO-aware management is quality of service (QoS) differentiation. Some requests might include priority levels. For instance, paying customers have higher priority than free-tier customers. Or interactive queries have higher priority than offline batch requests.SLO 感知管理的另一个方面是服务质量(QoS)区分。某些请求可能带有优先级。例如,付费客户的优先级高于免费层客户。或者交互式查询的优先级高于离线批处理请求。
A scheduler might prioritize certain requests to always meet SLO—even if others have to wait or be dropped. Disaggregation can aid this by dedicating some portion of prefill and decode workers to high-priority tasks. For instance, you can choose to reserve 10% of cluster capacity exclusively for premium-tier requests and 30% for standard tier.调度器可能优先处理某些请求以始终满足 SLO——即使其他请求必须等待或被丢弃。解耦可以通过将一部分预填充和解码工作进程专门分配给高优先级任务来帮助实现这一点。例如,你可以选择将 10% 的集群容量专门保留给高级层请求,30% 保留给标准层。
This tiered approach will guarantee headroom for the paying tiers (premium and standard). It makes sure these requests aren’t delayed by lower-priority (free-tier) requests. Here is an example QoS configuration for NVIDIA Dynamo that demonstrates this type of tiered scheduling:这种分层方法将为付费层(高级层和标准层)保证余量。它确保这些请求不会被低优先级(免费层)请求延迟。下面是一个 NVIDIA Dynamo 的 QoS 配置示例,展示了这种分层调度:
# configs/qos.yaml
scheduler:
  # 定义 QoS 类别及其预留容量
  qos_classes:
    - name: premium
      reserved_fraction: 0.10   # 预留 10% 的预填充/解码工作进程
      priority: 100
    - name: standard
      reserved_fraction: 0.30   # 为标准层级预留 30%
      priority: 50
    - name: free
      reserved_fraction: 0.60   # 共享剩余容量(免费层级)
      priority: 10
# 按标签将传入请求映射到 QoS 类别
request_router:
  routes:
    - match:
        header: "x-customer-tier: premium"
# configs/qos.yaml
scheduler:
  # Define QoS classes and their reserved capacity
  qos_classes:
    - name: premium
      reserved_fraction: 0.10   # reserve 10% of prefill/decode workers
      priority: 100
    - name: standard
      reserved_fraction: 0.30   # reserve 30% for standard tier
      priority: 50
    - name: free
      reserved_fraction: 0.60   # share remaining capacity (free tier)
      priority: 10
# Map incoming requests to QoS classes by label
request_router:
  routes:
    - match:
        header: "x-customer-tier: premium"
      qos: premium
    - match:
        header: "x-customer-tier: standard"
      qos: standard
    - match:
        header: "x-customer-tier: free"
      qos: free
    - match:
        # 默认回退
      qos: free
      qos: premium
    - match:
        header: "x-customer-tier: standard"
      qos: standard
    - match:
        header: "x-customer-tier: free"
      qos: free
    - match:
        # default fallback
      qos: free
This tiered approach allows higher-priority requests to be admitted and served with low latency using reserved capacity. Lower-priority requests will be queued—or potentially rejected—if the system is busy processing higher-priority requests.这种分层方法允许高优先级请求使用预留容量被准入并以低时延得到服务。如果系统正忙于处理高优先级请求,低优先级请求将被排队——或者可能被拒绝。
Latency monitoring and feedback loops are useful for this type of system to continuously monitor TTFT and TPOT p99 and p99.9. If the system sees these metrics approaching SLO limits, it can trigger actions such as scaling or rejecting new load, degrading the requests by limiting the maximum output length, or temporarily reducing the load.时延监控和反馈回路对此类系统很有用,可以持续监控 TTFT 和 TPOT 的 p99 与 p99.9。如果系统发现这些指标接近 SLO 限值,就可以触发相应动作,例如扩缩容或拒绝新负载、通过限制最大输出长度来降级请求,或临时降低负载。
In a disaggregated system, you can observe the prefill queue and decode the queue separately. This helps pinpoint which side is the bottleneck. With this information, the system can adjust accordingly by stopping to accept new prompts if prefill is backed up or limiting long-output reasoning requests if decode is saturated.在解耦系统中,你可以分别观察预填充队列和解码队列。这有助于精确定位哪一侧是瓶颈。有了这些信息,系统就可以相应地调整:如果预填充积压,就停止接受新的提示;如果解码饱和,就限制长输出推理请求。
容错
Fault Tolerance
Fault tolerance is another aspect of running a robust inference system. In a disaggregated system, if a decode node fails mid-generation, the KV cache pooling we discussed earlier can enable recovery on another node since the KV was saved in the pool. This way, another decode worker can pick up generating the remaining tokens—perhaps with a slight delay.容错是运行健壮推理系统的另一个方面。在解耦系统中,如果某个解码节点在生成过程中途失败,我们前面讨论的 KV 缓存池化可以让另一个节点实现恢复,因为 KV 已保存在池中。这样,另一个解码工作进程就可以接着生成剩余的 token——也许会有轻微的延迟。
If the KV was not saved, the system will have to recalculate the prefill on another node and then continue with the decode. This is why systems like vLLM periodically checkpoint or copy the KV cache to the pool—even if disaggregation isn’t strictly needed. This is done to protect against failures.如果 KV 未被保存,系统就必须在另一个节点上重新计算预填充,然后继续解码。这正是 vLLM 等系统会定期对 KV 缓存做检查点或将其复制到缓存池的原因——即使并不严格需要解耦。这样做是为了防范故障。
In addition to framework-level KV snapshots, a Linux process hosting a GPU worker can be suspended and snapshotted with cuda-checkpoint plus Checkpoint/Restore in Userspace (CRIU) as discussed in Chapter 5. This way, the checkpoint can be restored onto another node of the same GPU chip type to minimize work lost on preemption or failure.除了框架级的 KV 快照之外,承载 GPU 工作进程的 Linux 进程还可以借助 cuda-checkpoint 与用户空间检查点/恢复(Checkpoint/Restore in Userspace,CRIU)进行挂起和快照,如第 5 章所述。这样一来,检查点就可以恢复到相同 GPU 芯片类型的另一个节点上,从而最大限度地减少因抢占或故障而损失的工作。
Checkpointing can hurt latency, but at least the request can complete. Prefill node failure is less impactful after it finishes computing and sending the KV data to either a decode worker or the KV cache pool since the KV data is off the failed node. But if the prefill worker fails during a prompt, the prompt task needs to be retried on another prefill node. The architecture should handle these types of failures gracefully so that one node’s failure doesn’t drop the entire request or cause large cascaded delays.检查点操作可能损害时延,但至少请求能够完成。预填充节点在完成计算并将 KV 数据发送给解码工作进程或 KV 缓存池之后发生故障,影响较小,因为此时 KV 数据已不在故障节点上。但如果预填充工作进程在处理某个提示词的过程中失败,该提示词任务就需要在另一个预填充节点上重试。架构应当优雅地处理这类故障,使单个节点的故障不会导致整个请求被丢弃,也不会引发大规模的级联延迟。
In short, SLO-aware request management makes sure that even under extreme conditions, the system maintains performance guarantees for the load that it chooses to serve. It does this by intelligently deciding which requests to serve, which to shed, and which to delay. Early rejection is a concrete example that uses load prediction at admission time to prevent overload and maintain high throughput within the SLO constraints.简而言之,SLO 感知的请求管理确保即使在极端条件下,系统也能对其选择服务的负载维持性能保证。它通过智能地决定服务哪些请求、丢弃哪些请求、延迟哪些请求来实现这一点。提前拒绝就是一个具体例子,它在准入时利用负载预测来防止过载,并在 SLO 约束内保持高吞吐量。
SLO-aware request management and fault tolerance—combined with all the other strategies we’ve discussed so far (e.g., scaling, scheduling, and caching)—help maintain strict SLO goals in production.SLO 感知的请求管理与容错——结合我们目前讨论过的所有其他策略(例如扩缩容、调度和缓存)——有助于在生产环境中维持严格的 SLO 目标。
Disaggregation makes this possible because it provides clear control points. You can observe prefill and decode metrics separately and apply admission controls specifically where they’re needed. For instance, stop taking new prompts if the prefill cluster is backed up, or stop allowing long outputs if the decode cluster is at capacity.解耦之所以能让这一切成为可能,是因为它提供了清晰的控制点。你可以分别观测预填充和解码的指标,并在确实需要的地方施加准入控制。例如,如果预填充集群积压,就停止接收新的提示词;如果解码集群已达容量上限,就停止允许长输出。
The result is a more predictable, stable, and adaptable inference service in which performance doesn’t degrade sharply when load exceeds capacity. Instead, it gracefully rejects excess load and rapidly rebalances to handle the changing conditions.其结果是得到一个更可预测、更稳定、适应性更强的推理服务:当负载超出容量时,性能不会急剧下降,而是优雅地拒绝超额负载,并快速重新平衡以应对不断变化的条件。
动态调度与负载均衡
Dynamic Scheduling and Load Balancing
Upfront, you can determine how many resources to dedicate to prefill versus decode. But then you want to dynamically adjust those resource splits as the workload changes.一开始,你可以确定将多少资源分配给预填充、多少分配给解码。但随后你会希望随着工作负载的变化动态调整这些资源划分。
With a purely static configuration, if the workload mix changes and you require a more prompt-heavy or generation-heavy split, the fixed ratio will become suboptimal. The optimal balance of prefill and decode capacity will shift over time. At one moment, many new requests arrive, and you want a heavy prefill split. Later on, you may have many long, ongoing reasoning generations, and you want a heavy decode split.在纯静态配置下,如果工作负载构成发生变化,而你需要更偏重提示词或更偏重生长的划分,固定比例就会变得次优。预填充与解码容量的最优平衡会随时间推移而变化。某一时刻大量新请求到达,你希望采用偏重预填充的划分;之后你可能有许多长时间持续进行的推理生成,此时你希望采用偏重解码的划分。
Adaptive scheduling and load-balancing mechanisms aim to continuously tune the system so that neither phase becomes a bottleneck. This keeps goodput high under changing conditions.自适应调度与负载均衡机制旨在持续调整系统,使任何一个阶段都不会成为瓶颈。这能在不断变化的条件下保持较高的有效吞吐。
Modern inference engines like vLLM, SGLang, and NVIDIA Dynamo incorporate load monitoring and dynamic worker assignment into their platforms. In addition, many cloud inference platforms have custom autoscalers and routers that use similar principles.vLLM、SGLang 和 NVIDIA Dynamo 等现代推理引擎已将负载监控和动态工作进程分配集成到其平台中。此外,许多云推理平台都配有采用类似原理的自定义自动扩缩器和路由器。
自适应资源调度与热点预防
Adaptive Resource Scheduling and Hotspot Prevention
One issue with disaggregated setups is load imbalance between the prefill and decode clusters. If the ratio of prefill to decode workers is misconfigured for the current load mix, one side might saturate while the other side remains underutilized.解耦部署的一个问题是预填充集群与解码集群之间的负载不均衡。如果预填充与解码工作者的比例相对于当前负载组合配置不当,一侧可能饱和,而另一侧仍处于利用不足状态。
For instance, if there are not enough decode workers relative to prefill, then decode tasks will queue up. This increases TPOT even though prompts are being processed quickly. Conversely, if decode is overprovisioned but prefill is underprovisioned, new requests may wait to start. This leads to high TTFT while many decode GPUs sit idle.例如,如果相对于预填充而言解码工作者数量不足,解码任务就会排队。即使提示词被快速处理,这也会抬高 TPOT。反之,如果解码过度配置而预填充配置不足,新请求可能要等待开始。这会导致 TTFT 偏高,而许多解码 GPU 却处于空闲状态。
The ideal scenario is when both sides are working near capacity but are not overwhelmed. This way the system keeps both prefill and decode busy but neither has a growing queue.理想情况是两侧都在接近满负荷的状态下工作,但都未被压垮。这样系统能让预填充和解码都保持忙碌,而任何一侧的队列都不会持续增长。
Static prefill-decode worker allocations are not sufficient in real-world conditions because workloads can vary greatly throughout the day. The mix of input lengths and output lengths can vary significantly from hour to hour in a long-running, large-scale inference system.静态的预填充-解码工作者分配在真实环境中并不够用,因为负载在一天之内可能变化很大。在长时间运行的大规模推理系统中,输入长度与输出长度的组合可能逐小时显著变化。
For instance, one hour might have a lot of long questions that produce short answers (e.g., summarization). These require more prefill resources and fewer decode resources. The next hour, you might get short questions that produce long answers (e.g., reasoning, web search). These require less prefill but much more decode.例如,某个小时可能有大量长问题产生短答案(如摘要)。这类负载需要更多预填充资源和更少解码资源。下一个小时,可能出现短问题产生长答案(如推理、网页搜索)。这类负载需要更少预填充但多得多的解码。
In other words, a static prefill-to-decode ratio that worked for one scenario may not be optimal for another. Thus, the optimal X_p versus Y_d configuration is workload-dependent and will shift over time.换言之,适用于某种场景的静态预填充与解码比例,对另一种场景可能并非最优。因此,最优的 X_p 与 Y_d 配置取决于负载,并会随时间变化。
To address this, advanced inference systems can use adaptive scheduling algorithms that can redistribute load or even repurpose instances on the fly. Let’s discuss a few of these approaches next.为解决这一问题,先进的推理系统可以使用自适应调度算法,动态地重新分配负载,甚至重新调配实例用途。接下来我们讨论其中几种方法。
TetriInfer 的两级调度器
TetriInfer’s two-level scheduler
The research prototype scheduler TetriInfer operates at two granularities. First, at the individual request level, it assigns incoming requests to specific prefill and decode instances based on current load. This is the normal routing that we expect. Second, it monitors resource utilization cluster-wide and predicts where bottlenecks might form. This proactively shifts work to prevent hotspots.研究原型调度器 TetriInfer 在两个粒度上运作。首先,在单个请求层面,它根据当前负载将到来的请求分配到特定的预填充实例和解码实例。这是我们预期的常规路由。其次,它在集群范围内监控资源利用率,并预测瓶颈可能形成的位置。这种主动迁移工作负载以预防热点。
For instance, the scheduler might see that one decode node is getting a bunch of very long sequences queued up. Before it becomes a problem, the scheduler routes some of those sequences to a different decode node that’s more available—even if it wouldn’t normally route to this decode node. This way, the load is balanced out. Figure 18-9 shows a comparison between existing systems and the TetriInfer work in terms of execution timeline and architecture.例如,调度器可能发现某个解码节点上排起了大量超长序列。在它成为问题之前,调度器会把其中一些序列路由到另一个更空闲的解码节点——即使按常规它不会路由到这个解码节点。这样负载就被均衡了。图 18-9 展示了现有系统与 TetriInfer 工作在执行时间线和架构上的对比。
Here, you see that by predicting resource usage through queue lengths, GPU utilization trends, etc., TetriInfer’s two-level scheduler smooths out the load across the cluster and prevents any single node from being overloaded.在这里可以看到,通过依据队列长度、GPU 利用率趋势等预测资源使用情况,TetriInfer 的两级调度器平滑了整个集群的负载,防止任何单个节点过载。
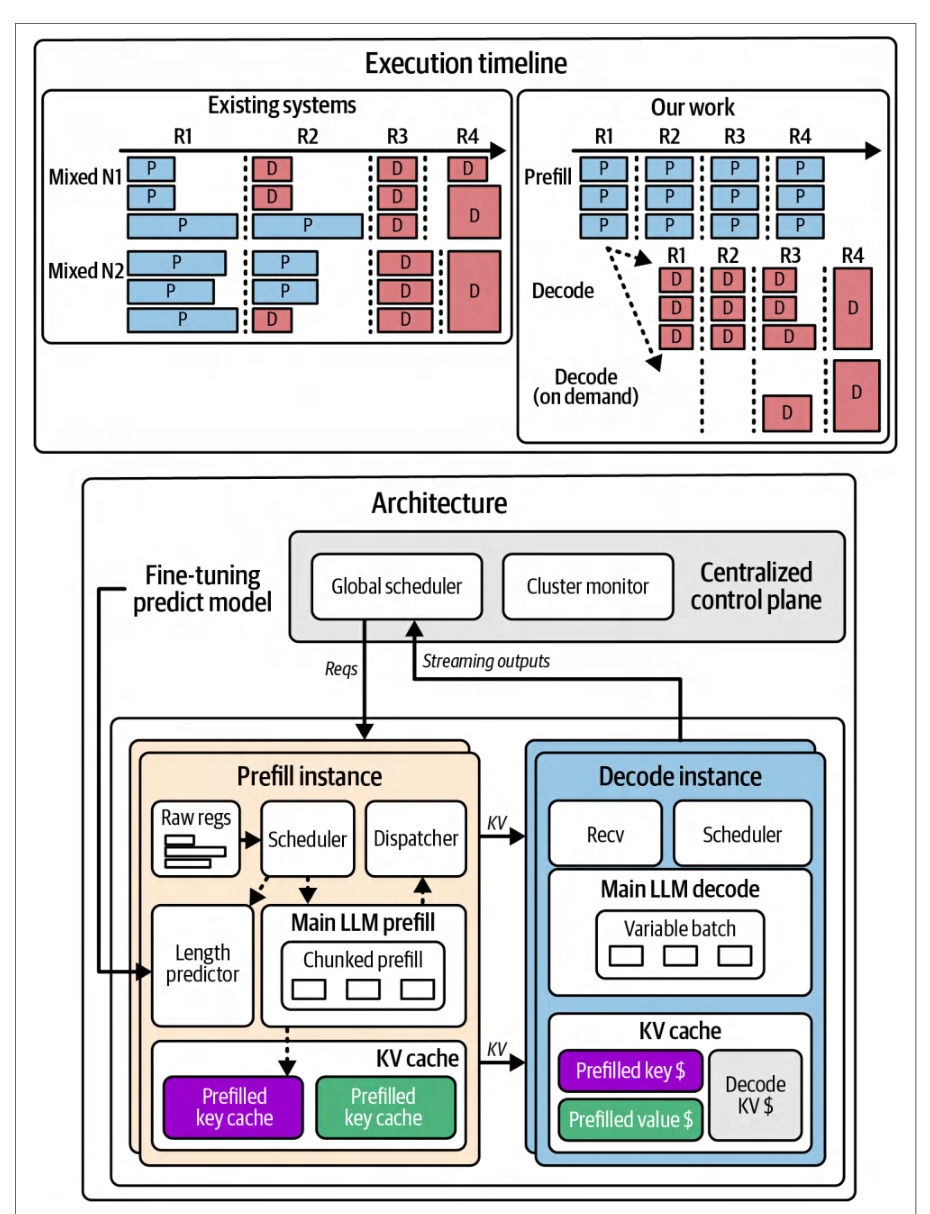
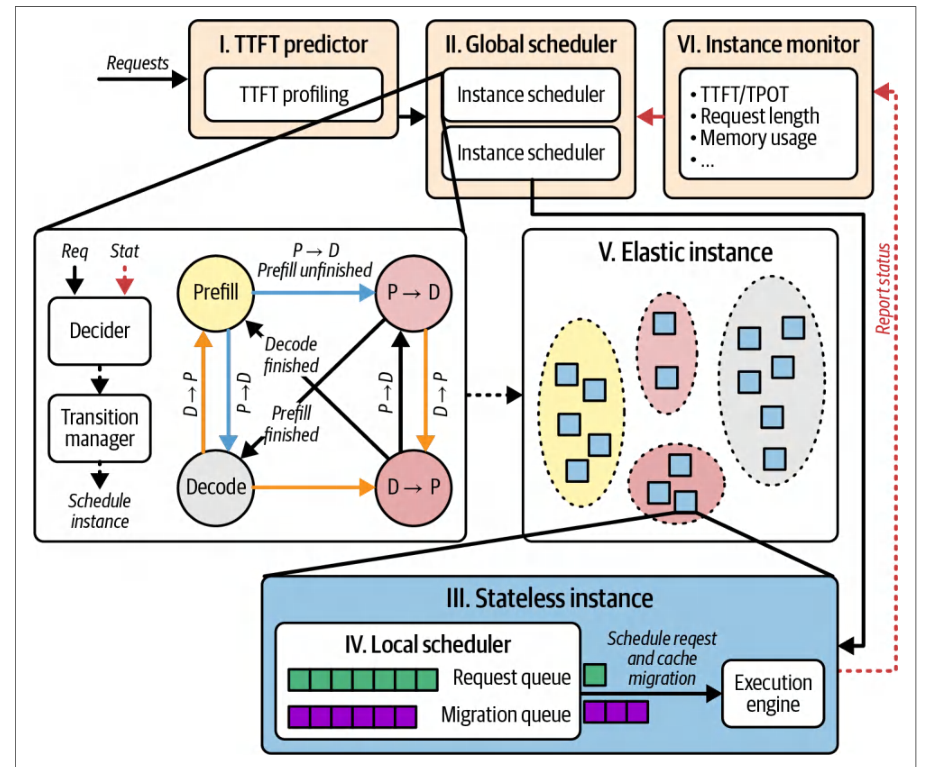
Arrow 的自适应实例伸缩
Arrow’s adaptive instance scaling
Another technique for dynamic resource scheduling is Arrow (not to be confused with the popular Arrow data format). This is an adaptive instance scaling technique that leverages the fact that disaggregated systems often have a lagging response to workload changes. For instance, if the distribution of input versus output changes, the static number of prefill versus decode workers doesn’t immediately adjust. This causes a temporary loss of goodput since one side becomes a bottleneck.另一种动态资源调度技术是 Arrow(不要与流行的 Arrow 数据格式混淆)。这是一种自适应实例伸缩技术,它利用了这样一个事实:解耦系统对工作负载变化的响应往往存在滞后。例如,如果输入与输出的分布发生变化,预填充与解码工作进程的静态数量不会立即调整。这会导致有效吞吐的暂时损失,因为其中一侧成为瓶颈。
Arrow continuously analyzes the workload by measuring input token rate versus output token rate—and the backlog in each worker pool in the cluster. It then dynamically adjusts the allocation of workers, as shown in Figure 18-10.Arrow 通过测量输入 token 速率与输出 token 速率——以及集群中每个工作进程池的积压情况——来持续分析工作负载。随后它会动态调整工作进程的分配,如图 18-10 所示。
In a cloud environment, this could mean spinning up additional decode instances when output load increases. You can also scale down decode in favor of more prefill instances if an input-heavy workload is detected.在云环境中,这可能意味着在输出负载增加时启动额外的解码实例。如果检测到输入密集型工作负载,你也可以缩减解码、转而增加预填充实例。
Arrow’s design includes both request scheduling to decide which node handles which requests (similar to other scheduling techniques) and instance scheduling to decide when to launch or shut down instances of either prefill or decode.Arrow 的设计同时包含请求调度(决定哪个节点处理哪些请求,与其他调度技术类似)和实例调度(决定何时启动或关闭预填充或解码实例)。
Arrow treats the number of prefill and decode workers as a tunable parameter that can be adjusted and scaled in near-real-time. Arrow’s design brings an autoscaler logic inside the LLM inference scheduler.Arrow 将预填充与解码工作进程的数量视为可调参数,可以在近实时内调整和伸缩。Arrow 的设计把自动伸缩器逻辑引入到 LLM 推理调度器内部。
For instance, if a high volume of input-heavy but output-light requests come into the system, prefill nodes could become the bottleneck. In this case, Arrow would detect growing prefill queue times or rising TTFT percentiles and decide to convert some decode workers into prefill workers—or launch extra prefill instances to handle the surge.例如,如果大量输入密集但输出较少的请求进入系统,预填充节点可能成为瓶颈。在这种情况下,Arrow 会检测到预填充队列时间增长或 TTFT 百分位上升,并决定将部分解码工作进程转换为预填充工作进程——或启动额外的预填充实例来应对这波高峰。
Conversely, if a wave of output-heavy requests with very long answers (e.g., reasoning chains) comes in, the decode cluster might start lagging, as indicated by TPOT rising and a long decode queue forming. In this case, Arrow could allocate more GPU workers to the decoding phase—perhaps by temporarily idling some prefill nodes if prompt arrivals have slowed. Otherwise, it could just add new decode nodes.反之,如果涌入一批输出密集、答案很长的请求(例如推理链),解码集群可能开始滞后,表现为 TPOT 上升并形成较长的解码队列。在这种情况下,Arrow 可以给解码阶段分配更多 GPU 工作进程——如果提示到达已经放缓,也许可以临时让一些预填充节点空闲。否则,它也可以直接新增解码节点。
In a static, on-premises cluster with a fixed number of GPUs, dynamic scaling will involve task reallocation by instructing a few GPUs that were assigned to prefill to switch roles and join the decode pool for a bit of time. This is feasible if each compute node is configured to run as both a prefill worker and a decode worker.在 GPU 数量固定的静态本地集群中,动态伸缩将涉及任务重新分配:指示少数原本分配给预填充的 GPU 切换角色,暂时加入解码池。如果每个计算节点都配置为既能作为预填充工作进程又能作为解码工作进程运行,这是可行的。
There may be overhead to switching roles since the model may need to load different model partitions for different parallelism strategies or quantization choices, etc. Some designs keep all model weights loaded on every GPU and just feed them different tasks depending on the need. This effectively treats the cluster as a flexible pool where, at any given moment, some fraction of workers are doing prefill and others are doing decode.切换角色可能存在开销,因为模型可能需要为不同的并行策略或量化选择等加载不同的模型分区。有些设计将全部模型权重保留在每块 GPU 上,只是根据需要向它们喂送不同的任务。这实际上把集群视为一个灵活的池,在任意时刻,一部分工作进程在做预填充,另一部分在做解码。
This starts to resemble a unified cluster with time-sharing but at a coarse granularity in which one node dedicates some time to performing prefill tasks, then switches to performing decode tasks.这开始类似于一个带时分复用的统一集群,但粒度较粗:一个节点先花一些时间执行预填充任务,然后切换到执行解码任务。
In cloud deployments, dynamic scaling can also mean interfacing with an autoscaler like the Kubernetes Horizontal Pod and Cluster Autoscalers to add or remove pods and nodes for each role. For instance, Arrow could trigger new prefill pods to start if the load is consistently high there. This leads to a fully elastic, disaggregated prefill and decode inference cluster that grows or shrinks each side as needed.在云部署中,动态伸缩也可能意味着与 Kubernetes Horizontal Pod Autoscaler 和 Cluster Autoscaler 之类的自动伸缩器对接,为每种角色增加或移除 pod 和节点。例如,如果预填充侧负载持续很高,Arrow 可以触发新的预填充 pod 启动。这形成一个完全弹性的解耦预填充与解码推理集群,各侧按需增长或收缩。
In practice, scaling up new GPU pods can take tens of seconds or more. As such, the system may need to shed load while waiting for capacity. This is how Mooncake handles this situation, as we discuss next.在实践中,扩容新的 GPU pod 可能需要数十秒甚至更久。因此,系统可能需要在等待容量的同时进行降载。Mooncake 正是这样处理这种情况的,我们接下来讨论。
Mooncake 的自适应策略
Mooncake adaptive strategies
Apart from Arrow, the Mooncake system also highlights adaptive strategies. Mooncake introduced a prediction-based admission control called early rejection, which is somewhat complementary—managing demand versus managing supply.除了 Arrow 之外,Mooncake 系统还突出了自适应策略。Mooncake 引入了名为*提前拒绝*(early rejection)的基于预测的准入控制,它在某种程度上是互补的——管理需求与管理供给。
Specifically, if the system predicts it doesn’t have enough capacity to handle a new request within SLO, it will reject that request rather than accept the request and potentially violate the SLO. This is a form of dynamic load shedding rather than scaling, but it aims to prevent overload.具体来说,如果系统预测自身没有足够容量在 SLO 内处理新请求,它就会拒绝该请求,而不是接受该请求并可能违反 SLO。这是一种动态*减载*(load shedding)而非扩缩容,但其目标是防止过载。
We already covered Mooncake’s early rejection approach in the previous section. The point here is that adaptation can happen on the supply side by adding more resources or reallocating them—as well as on the demand side by throttling or rejecting some requests.我们在上一节已经介绍了 Mooncake 的提前拒绝方法。这里的要点是,自适应既可以发生在供给侧——通过增加或重新分配资源——也可以发生在需求侧——通过限流或拒绝部分请求。
The key benefit of dynamic scaling is maintaining high goodput across workload variations. By automatically tuning the prefill-to-decode ratio, the system avoids extended periods of mismatch in which GPUs on one side are idle while the other side is overloaded.动态扩缩容的关键优势在于在工作负载变化时保持高有效吞吐。通过自动调节预填充与解码的比例,系统可以避免长时间的不匹配状态——一侧的 GPU 空闲,而另一侧过载。
Ideally, both types of nodes are utilized evenly. This improves latency by alleviating bottlenecks as soon as they form—and also raises efficiency since you’re not paying for a bunch of idle GPUs of one type while the other type is overloaded. Instead, resources are reallocated or tasks shifted to keep things balanced.理想情况下,两类节点都能被均衡利用。这可以在瓶颈刚一形成时就予以缓解,从而改善时延;同时也提升了效率,因为你不必为一堆空闲的某一类 GPU 付费,而另一类却处于过载状态。取而代之的是,资源被重新分配或任务被迁移,以保持均衡。
In terms of outcomes, an adaptive system might be able to claim something like, “After applying adaptive scaling, the system maintained > 90% SLO compliance across traffic patterns that a static system could not, and it handled X% more requests during a spike by quickly shifting resources.”从结果来看,自适应系统或许可以这样宣称:“在应用自适应扩缩容之后,系统在静态系统无法应对的各类流量模式下仍保持了 > 90% 的 SLO 达标率,并且在流量尖峰期间通过快速迁移资源多处理了 X% 的请求。”
Specifically, Arrow’s results mention an up to 5.6× higher request serving rate versus a nonadaptive system in a scenario with an extremely shifting workload. Typical improvements were lower but still significant. The exact improvement depends on how dramatic the workload changes are.具体而言,Arrow 的结果提到,在工作负载剧烈变化的场景中,相比非自适应系统,其请求服务速率最高提升 5.6×。典型提升幅度较低,但仍然显著。确切的提升取决于工作负载变化的剧烈程度。
All of this shows that disaggregation removes the phase interference issue. And dynamic disaggregation removes the next constraint of phase imbalance caused by a fixed allocation. To implement such adaptivity, the scheduler needs to monitor metrics continuously, including the prefill queue length, decode queue length, and the TTFT/TPOT percentiles. These metrics are often fed into control dashboards using Prometheus and custom controllers in a K8s deployment. Algorithms can then automate the decision making.所有这些都表明,解耦消除了阶段干扰问题。而动态解耦则消除了下一个约束——由固定分配导致的阶段不均衡。要实现这种自适应,调度器需要持续监控各项指标,包括预填充队列长度、解码队列长度以及 TTFT/TPOT 分位数。在 K8s 部署中,这些指标通常通过 Prometheus 和自定义控制器送入控制面板。随后,算法可以自动完成决策。
Sophisticated inference systems use predictive models like ARIMA and other fore-casting techniques to foresee surges and predict traffic shifts using time-of-day patterns. If a spike of long outputs is predicted at 9 p.m. due to historically known usage patterns, the scheduler could preemptively allocate more decode capacity just in time. The overall goal is to maintain a high fraction of requests served within SLO—and without manual intervention and reconfiguration.成熟的推理系统会使用 ARIMA 等预测模型以及其他预测技术,利用一天中不同时段的模式来预见流量激增并预测流量变化。如果根据历史上已知的使用模式预测到晚上 9 点会出现长输出激增,调度器就可以抢先、及时地分配更多解码容量。总体目标是在无需人工干预和重新配置的情况下,保持高比例的请求在 SLO 内得到服务。
动态资源扩缩容
Dynamic resource scaling
Building on the idea of predictive scheduling, dynamic resource scaling is specifically about changing the distribution of resources between prefill and decode in response to load. For example, Arrow’s adaptive instance scheduling adjusts the number of prefill versus decode workers continuously. Here are some ways to balance the load in an inference system:在预测性调度思想的基础上,动态资源扩缩容具体指的是根据负载改变预填充与解码之间的资源分布。例如,Arrow 的自适应实例调度会持续调整预填充工作进程与解码工作进程的数量。以下是在推理系统中平衡负载的几种方式:
- Elastic instances弹性实例
- In Kubernetes or similar, you can define an autoscale policy for each deployment. For example, you can specify that you want to maintain average prefill GPU utilization at 70%. If GPU utilization goes higher, the system will add a pod or node to the prefill worker pool. If it goes lower and decode utilization remains high, the system can move one pod from prefill to decode. This could be rule-based or algorithmic, such as solving for the most optimal configuration at each interval to choose new X and Y counts.在 Kubernetes 或类似系统中,可以为每个 deployment 定义自动扩缩容策略。例如,可以指定希望将预填充阶段的 GPU 平均利用率维持在 70%。如果 GPU 利用率升高,系统会向预填充工作池添加一个 pod 或节点。如果利用率降低而解码利用率仍然很高,系统可以将一个 pod 从预填充迁移到解码。这可以是基于规则的,也可以是算法驱动的,例如在每个时间间隔求解最优配置,以选择新的 X 和 Y 数量。
- Instance “flip” mechanism实例“翻转”机制
- The TetriInfer paper describes an “instance flip” in which some nodes can flip roles if needed. This requires that the model be loaded, sharded, and quantized properly to handle both roles.TetriInfer 论文描述了一种“实例翻转”(instance flip),即某些节点在需要时可以翻转角色。这要求模型被正确加载、分片和量化,以胜任两种角色。
- Statelessness for elasticity无状态化以实现弹性
- Arrow leverages stateless instances. As such, no long-lived session state is stored on the worker. This way, they can be reassigned freely. The KV cache of active requests complicates flipping a decode node to prefill if it’s mid-token-generation, so you often have to wait until the decode finishes its task before switching roles.Arrow 采用无状态实例。因此,工作节点上不存储长生命周期的会话状态。这样一来,它们可以被自由地重新分配。活跃请求的 KV 缓存会使解码节点在 token 生成中途翻转为预填充变得复杂,因此通常必须等待解码完成其任务后才能切换角色。
- Stability and oscillation稳定性与振荡
- Rapidly switching roles can lead to oscillation and thrashing. As such, it’s common to enforce some minimum amount of time required for a role to avoid flipping too frequently.频繁切换角色会导致振荡和抖动(thrashing)。因此,通常会强制要求某个角色维持一段最短时间,以避免切换过于频繁。
Apart from load balancing, another aspect to consider is multitenancy or mixed workloads. If the cluster serves different models or tasks, you can even repurpose GPUs between them based on demand—and beyond a single model’s scope.除负载均衡外,另一个需要考虑的方面是多租户或混合负载。如果集群服务于不同的模型或任务,甚至可以根据需求在它们之间重新调配 GPU——这已超出单个模型的范围。
Disaggregation’s modular configuration allows using idle decode GPUs to run another smaller model’s inference tasks. This is an extension that is not yet mainstream as of this writing, but it’s conceptually possible as inference engines evolve and become more flexible in their designs.解耦的模块化配置允许使用空闲的解码 GPU 来运行另一个较小模型的推理任务。截至本文写作时,这一扩展尚未成为主流,但随着推理引擎的演进及其设计变得更加灵活,它在概念上是可行的。
The bottom line is that an ultrascale inference system requires a feedback loop to continually match resource allocation to the current workload. TetriInfer, Arrow, Mooncake, and others show significant improvements when using such a feedback loop and adapting to load changes. This highlights that while disaggregation removes interference, adaptive disaggregation removes imbalance. Both are needed for the best performance under dynamic conditions.归根结底,超大规模推理系统需要一个反馈回路,以持续使资源分配与当前负载相匹配。TetriInfer、Arrow、Mooncake 等在采用此类反馈回路并适应负载变化时展现出显著改进。这凸显出:解耦消除了干扰,而自适应解耦消除了不均衡。在动态条件下要获得最佳性能,两者都不可或缺。
关键要点
Key Takeaways
This chapter covered various techniques, such as unified megakernels, efficient memory allocations, fast data transfers, prefill/decode disaggregation, KV cache pools, dynamic scaling, and continuous SLO awareness. Here are some key takeaways:本章涵盖了多种技术,例如统一巨型内核(unified megakernels)、高效显存分配、快速数据传输、预填充/解码解耦、KV 缓存池、动态扩缩容以及持续的 SLO 感知。以下是一些关键要点:
- Accelerate the decode phase加速解码阶段
- The decode phase can be greatly accelerated using fused attention kernels including FlashMLA, ThunderMLA, and FlexDecoding. These kernels can improve single-token throughput and GPU utilization.使用融合注意力内核(包括 FlashMLA、ThunderMLA 和 FlexDecoding)可以大幅加速解码阶段。这些内核可以提升单 token 吞吐量和 GPU 利用率。
- Treat the KV cache as a first-class citizen将 KV 缓存视为一等公民
- Share the KV cache across GPUs using disaggregation. Reuse prefixes to avoid redundant computation. These are enabled by global cache pools and hashing.使用解耦在多个 GPU 之间共享 KV 缓存。复用前缀以避免冗余计算。这些能力由全局缓存池和哈希实现。
- Strive for near-zero overhead between prefill and decode workers力求预填充与解码工作节点之间的开销接近于零
- Leverage high-speed GPU-to-GPU transfers with GPUDirect RDMA and NIXL. Overlap compute/transfer to achieve near-zero overhead between prefill and decode workers.借助 GPUDirect RDMA 和 NIXL 实现高速的 GPU 到 GPU 传输。重叠计算与传输,以实现预填充与解码工作节点之间接近于零的开销。
- Embrace specialized hardware and parallelism for each phase为每个阶段采用专用硬件与并行方式
- Disaggregating prefill and decode allows specialized hardware and parallelism per phase. For example, use high-compute GPUs or multi-GPU nodes for prefill. And use memory-rich GPUs or single GPUs for decode. The goal is to reduce cost and increase throughput.将预填充与解码解耦,可以为每个阶段配置专用硬件与并行方式。例如,预填充使用高算力 GPU 或多 GPU 节点,解码使用大显存 GPU 或单 GPU。目标是降低成本并提升吞吐量。
- Use adaptive and dynamic algorithms to optimize the system使用自适应与动态算法优化系统
- Adaptive scheduling and SLO-aware control (e.g., early rejection and dynamic scaling) are necessary to maintain latency guarantees under varying load—and to fully utilize all GPUs without overload.自适应调度与 SLO 感知的控制(例如提前拒绝和动态扩缩容)对于在负载变化时维持时延保证是必要的,同时也能在不超载的前提下充分利用所有 GPU。
结语
Conclusion
Ultrascale LLM inference requires a holistic approach, including both high-level adaptive resource management and low-level kernel and memory optimizations. By combining the techniques presented in this chapter, a highly optimized inference deployment can achieve maximum throughput on modern hardware while meeting strict latency guarantees.超大规模 LLM 推理需要整体性的方法,既包括高层的自适应资源管理,也包括底层的内核与内存优化。结合本章介绍的各项技术,经过高度优化的推理部署可以在现代硬件上实现最大吞吐量,同时满足严格的时延保证。
As hardware continues to evolve and GPUs (e.g., increased memory and specialized inference cores) and software frameworks become more sophisticated (e.g., dynamic routing and flexible role assignments), these optimizations will compound and become even more powerful. This will allow inference engines to efficiently handle even larger models, longer contexts, and more users.随着硬件持续演进,GPU(例如更大的显存和专用推理核心)与软件框架变得日益成熟(例如动态路由和灵活的角色分配),这些优化将相互叠加并变得更加强大。这将使推理引擎能够高效处理更大的模型、更长的上下文和更多的用户。