面向推理的解耦预填充与解码扩展
Chapter 17. Scaling Disaggregated Prefill and Decode for Inference
As mentioned in an earlier chapter, LLM inference can be divided into two distinct phases: the prefill phase and the decode phase. The prefill phase processes the input prompt to produce the model’s internal key-value (KV) cache for that prompt, while the decode phase generates output tokens one by one—or a few at a time, in the case of speculative decoding—using those cached values.正如前面某一章所述,LLM 推理可分为两个截然不同的阶段:预填充阶段与解码阶段。预填充阶段处理输入提示词,为该提示词生成模型内部的键值(KV)缓存;解码阶段则利用这些缓存值逐个生成输出 token——在投机解码(speculative decoding)的情况下则是一次生成若干个。
These two phases have fundamentally different performance characteristics. The prefill phase is compute bound, involves heavy matrix multiplications over potentially thousands of tokens in parallel, and consumes a significant amount of FLOPS. In contrast, the decode phase is memory I/O bound, reads the large KV cache for each token generation, writes new values, and stresses memory bandwidth. In simpler terms, prefill is a high-throughput, parallel workload, whereas decode is a sequential, latency-sensitive workload.这两个阶段具有根本不同的性能特征。预填充阶段受计算限制(compute bound),涉及对可能多达数千个 token 并行执行大量矩阵乘法,消耗可观的 FLOPS。相比之下,解码阶段受内存 I/O 限制(memory I/O bound),每次生成 token 都要读取庞大的 KV 缓存、写入新值,对显存带宽造成压力。简单来说,预填充是高吞吐的并行负载,而解码是顺序的、对时延敏感的负载。
Early LLM serving systems treated the two phases as one monolithic pipeline on the same hardware. As such, they typically favored the prefill phase by prioritizing throughput using request batching. However, as interactive applications grew, latency metrics like time to first token (TTFT, or prefill latency for all tokens) and time per output token (TPOT, or decode latency per token) became as important as raw throughput. It’s difficult for a single GPU-based inference engine to optimize both TTFT and TPOT simultaneously when serving both phases together.早期的 LLM 服务系统将这两个阶段视为同一硬件上的单一整体流水线。因此,它们通常通过请求批处理优先保障吞吐量,从而偏向预填充阶段。然而,随着交互式应用的发展,诸如首 token 时延(TTFT,即所有 token 的预填充时延)和每输出 token 时延(TPOT,即每个 token 的解码时延)这类时延指标,变得与原始吞吐量同等重要。当同时服务两个阶段时,单一基于 GPU 的推理引擎很难同时优化 TTFT 和 TPOT。
Batching many requests will improve throughput but will worsen TTFT since every request waits for the slowest prefill. It will also impact TPOT since the decode steps will get backlogged behind new-prompt prefills.对大量请求进行批处理会提升吞吐量,但会恶化 TTFT,因为每个请求都要等待最慢的预填充完成。它还会影响 TPOT,因为解码步骤会积压在新提示词的预填充之后。
Monolithic inference systems must choose between improving (reducing) time to first token at the cost of slower subsequent token generation—or improving (increasing) per-token throughput while subjecting new requests to high initial latency. In extreme cases, one long prompt can completely tie up the GPU, which would block all other prompt prefill work for other users. And then, once decoding begins, the one-token-at-a-time processing would leave the GPU’s cores idle between each token generation.单体式推理系统必须在两者之间取舍:要么以牺牲后续 token 生成速度为代价改善(降低)首 token 时延,要么提升(增加)每 token 吞吐量却让新请求承受很高的初始时延。在极端情况下,一个长提示词就能完全占满 GPU,从而阻塞其他用户所有其他提示词的预填充工作。而一旦开始解码,一次只处理一个 token 的方式又会让 GPU 的核心在每次 token 生成之间处于空闲状态。
To address these issues, researchers and engineers looked for ways to decouple the two phases. The key insight is that prefill and decode do not actually need to run on the same hardware—or even the same type of hardware.为解决这些问题,研究人员和工程师们寻找将两个阶段解耦的方法。关键洞见在于:预填充与解码实际上并不需要运行在同一硬件上——甚至不需要运行在同一类型的硬件上。
Disaggregating the prefill and decode phases means assigning them to different resources that are each specialized for the needs of that specific phase. This idea was pioneered by systems in a paper on DistServe, which demonstrated that by eliminating interference between the phases, one can meet strict latency requirements for both TTFT and TPOT simultaneously.将预填充与解码阶段解耦,意味着把它们分配到各自专用于该阶段需求的不同资源上。这一思路由 DistServe 论文中的系统率先提出,该论文证明:通过消除两个阶段之间的相互干扰,可以同时满足 TTFT 和 TPOT 的严格时延要求。
DistServe’s evaluation showed the potential for serving 7.4× more requests within strict latency service-level objectives (SLOs) compared to a state-of-the-art baseline without prefill/decode disaggregation. As such, industry frameworks began to experiment with separate prefill and decode servers.DistServe 的评估显示,与未做预填充/解码解耦的最先进基线相比,在严格的服务等级目标(SLO)下可服务的请求量提升至 7.4 倍。因此,业界框架开始尝试使用独立的预填充服务器与解码服务器。
The open source vLLM library introduced disaggregated operation in conjunction with LMCache and other components. NVIDIA’s Dynamo implements disaggregated prefill and decode with dynamic routing and autoscaling and publicly documents operational details. Many providers and open frameworks implement or evaluate disaggregation. For instance, to meet strict latency SLOs, industry-scale serving systems from OpenAI, Meta, and xAI have reportedly adopted this disaggregated approach. As such, disaggregated prefill and decode is standard practice for LLM inference at scale.开源 vLLM 库联合 LMCache 及其他组件引入了分离式运行模式。NVIDIA 的 Dynamo 通过动态路由与自动扩缩实现预填充与解码的解耦,并公开记录了运维细节。许多服务提供商和开源框架都实现或评估了解耦方案。例如,为满足严格的时延 SLO,据报道 OpenAI、Meta 和 xAI 的工业级服务系统都已采用这种解耦方式。因此,预填充与解码解耦已成为大规模 LLM 推理的标准实践。
At ultrascale, large inference deployments can involve hundreds of thousands or even millions of GPUs serving billions of requests. In these environments, the cost and performance benefits of disaggregation are massive.在超大规模(ultrascale)下,大型推理部署可能涉及数十万甚至数百万块 GPU,服务数十亿次请求。在这些环境中,解耦带来的成本与性能收益是巨大的。
By splitting the workload, you can optimize each phase in isolation and avoid one of them becoming the bottleneck for the other. The remainder of this chapter explores how to design and operate a disaggregated prefill/decode inference system at extreme scale.通过拆分工作负载,你可以独立优化每个阶段,并避免其中一个阶段成为另一个阶段的瓶颈。本章余下部分将探讨如何在极端规模下设计与运维解耦的预填充/解码推理系统。
In this chapter, we will explore scheduling algorithms to route requests between prefill and decode workers, techniques to maintain quality of service (QoS) under heavy load, and mechanisms that make this separation efficient. We’ll explore everything from high-speed interconnects to specialized decoding kernels. We will also discuss heterogeneous hardware strategies that use different GPU types for each phase.本章将探讨在预填充工作节点与解码工作节点之间路由请求的调度算法、在高负载下维持服务质量(QoS)的技术,以及使这种分离变得高效的机制。我们将从高速互连一直探讨到专用解码内核。此外,我们还将讨论为每个阶段使用不同 GPU 类型的异构硬件策略。
为何要做预填充-解码解耦
Why Prefill-Decode Disaggregation?
Modern interactive LLM services often target TTFT latency < 200–300 ms for p99 (99% of requests). This is nearly impossible to guarantee without separating the prefill work since a one-size-fits-all approach to LLM serving leaves significant performance on the table.现代交互式 LLM 服务通常以 p99(99% 的请求)的 TTFT 时延 < 200–300 ms 为目标。如果不把预填充工作分离出去,这几乎无法保证,因为“一刀切”的 LLM 服务方式会白白损失可观的性能。
For context, the MLPerf v5.0’s (2025) inference benchmark for Llama2 70B (70 billion parameters) aimed for p99 (99th percentile) SLOs of ~450 ms TTFT and 40 ms TPOT latency. For Llama 3.1 405B (405 billion parameters), the benchmark aimed for ~6 seconds TTFT and 175 ms for TPOT. Specifically, these SLOs reflect p99 TTFT and p99 TPOT targets for Llama 2 Chat 70B and Llama 3.1 405B Instruct.作为参考,MLPerf v5.0(2025)针对 Llama2 70B(700 亿参数)的推理基准以约 450 ms 的 TTFT 和 40 ms 的 TPOT 时延作为 p99(第 99 百分位)SLO 目标。对于 Llama 3.1 405B(4050 亿参数),该基准的目标是约 6 秒的 TTFT 和 175 ms 的 TPOT。具体而言,这些 SLO 反映的是 Llama 2 Chat 70B 与 Llama 3.1 405B Instruct 的 p99 TTFT 与 p99 TPOT 目标。
Consider a scenario in which one user’s request has an extremely long prompt on the order of many thousands of tokens—and another user’s request has a very short prompt. Without disaggregated prefill and decode, if these requests arrive around the same time, the long prompt’s prefill computation will block the GPU for an extended period.设想这样一个场景:一个用户的请求带有长达数千个 token 量级的极长提示词,而另一个用户的请求提示词非常短。如果没有解耦的预填充与解码,当这两个请求几乎同时到达时,长提示词的预填充计算会在相当长的时间内占住 GPU。
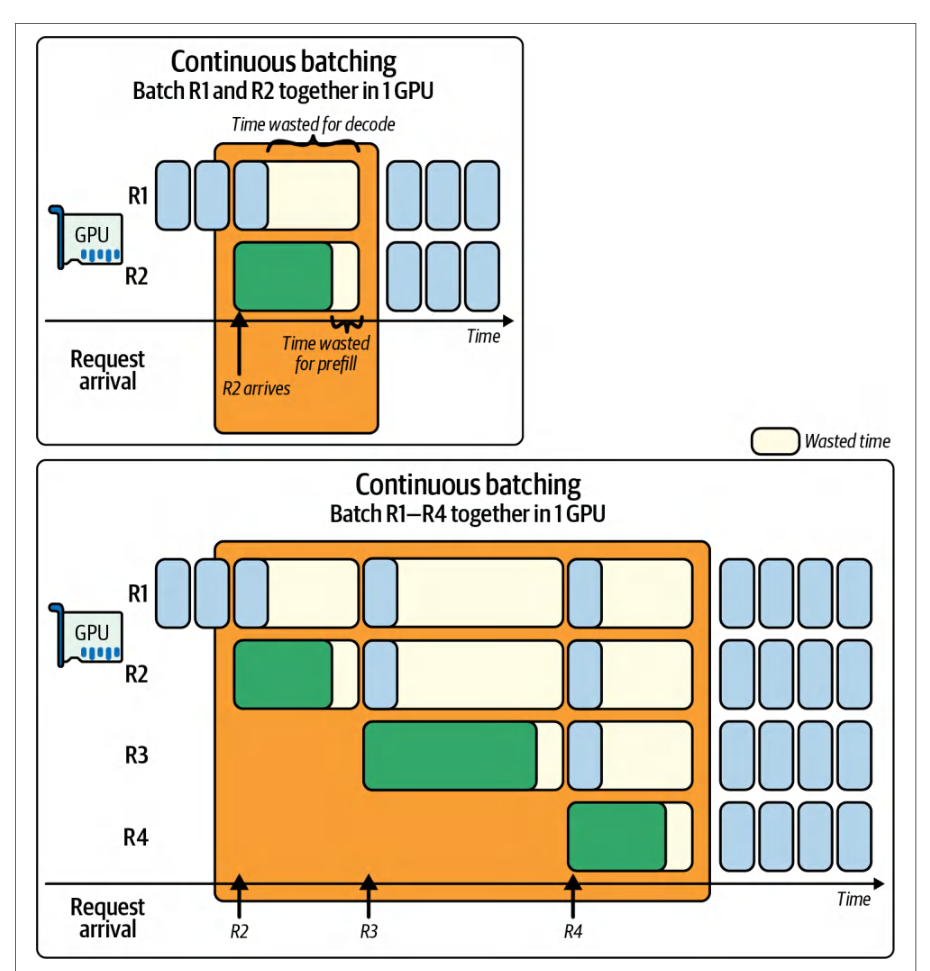
Without disaggregation, the second request with the short prompt needs to wait an unnecessarily long time before even starting their decode. This is called interference since the prefill work for one request delays the decode work of another. Interference between prefill and decode is shown in Figure 17-1 in the context of continuous batching.在没有解耦的情况下,第二个短提示词请求需要等待不必要地长的时间,才能开始其解码。这被称为*干扰*(interference),因为一个请求的预填充工作延迟了另一个请求的解码工作。图 17-1 在连续批处理(continuous batching)的语境下展示了预填充与解码之间的干扰。
Under a simple FIFO scheduling strategy, long prompts can amplify tail latency for everyone. In general, long or compute-heavy prefills at the front of the queue will block shorter, lighter requests behind them. This is called head-of-line blocking, and it leads to poor utilization, latency outliers, and unhappy end users.在简单的 FIFO 调度策略下,长提示词会放大所有人的尾时延。一般而言,队列前端的冗长或计算密集的预填充会阻塞其后更短、更轻量的请求。这被称为*队头阻塞*(head-of-line blocking),它会导致利用率低下、时延离群值和最终用户的不满。
In a flexible disaggregated architecture, it’s possible to send a large prompt prefill to the dedicated pool of compute-optimized prefill workers, while a lightweight prompt prefill can be sent to the decode workers directly—bypassing the prefill workers. This type of flexibility allows shorter tokens to not suffer from head-of-line blocking. This maximizes overall throughput and minimizes latency tail effects.在灵活的解耦架构中,可以将大提示词的预填充发送到专用的、面向计算优化的预填充工作节点池,而轻量提示词的预填充则可以直接发送到解码工作节点——绕过预填充工作节点。这种灵活性使较短的 token 不必遭受队头阻塞。这最大化了整体吞吐量,并最小化了时延尾部效应。
解耦的优势
Advantages of Disaggregation
Disaggregation has two primary advantages: reduced interference and phase-specific optimizations. Let’s discuss each of these next.解耦有两个主要优势:减少干扰,以及针对各阶段的专门优化。下面我们逐一讨论。
减少干扰
Reduced interference
With disaggregation, prefill tasks no longer contend with decode tasks on the same device. A busy decode worker, generating many tokens, won’t prevent another user’s prompt from being processed, and vice versa.采用解耦后,预填充任务不再与解码任务在同一设备上争抢资源。一个忙于生成大量 token 的解码工作节点,不会妨碍另一位用户的提示词得到处理,反之亦然。
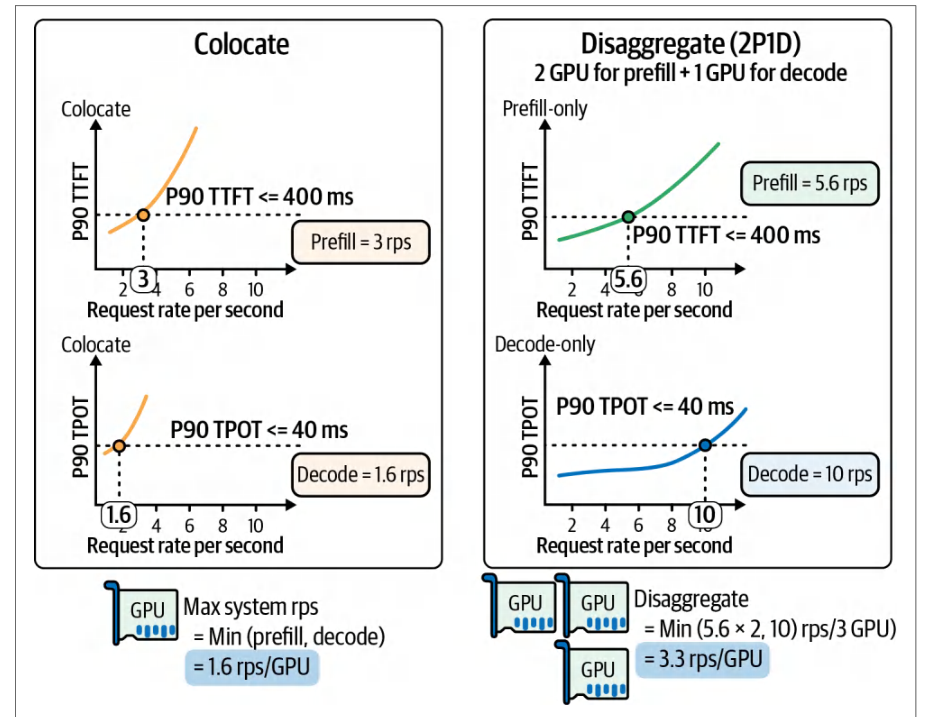
Dedicated resources for each stage mean a long prompt’s computation won’t block another user’s token generation. In practice, this produces more predictable latency. Figure 17-2 shows the comparison between colocated and disaggregated prefill and decode. This experiment is described in more detail in the DistServe paper and subsequent blog post by the authors.每个阶段拥有专用资源,意味着长提示词的计算不会阻塞另一位用户的 token 生成。在实践中,这会带来更可预测的时延。图 17-2 展示了同机部署与解耦的预填充和解码之间的对比。该实验在 DistServe 论文及作者后续的博客文章中有更详细的描述。
Here, the SLO is set to 0.4 seconds for P90 TTFT and 0.04 seconds for P90 TPOT (e.g., horizontal line in Figure 17-2). The colocated system can support only ~3 requests per second (RPS) of goodput within the given TTFT latency bounds. And it can sustain only 1.6 RPS within the given TPOT latency bounds. As such, the goodput of the colocated configuration is only 1.6 RPS since both the TTFT and TPOT latency SLOs need to be met.此处 SLO 设定为 P90 TTFT 0.4 秒、P90 TPOT 0.04 秒(即图 17-2 中的水平线)。在给定的 TTFT 时延界限内,同机部署系统只能支撑约 3 请求/秒(RPS)的有效吞吐;在给定的 TPOT 时延界限内,它只能维持 1.6 RPS。因此,由于必须同时满足 TTFT 和 TPOT 两项时延 SLO,同机部署配置的有效吞吐仅为 1.6 RPS。
After disaggregating the two stages and assigning two prefill workers (two GPUs) and a single decode worker (one GPU), called a 2P1D configuration, both the prefill and decode workers achieve better overall RPS than the colocated configuration with a single GPU. Specifically, the prefill worker reaches ~5.6 RPS and the decode worker achieves ~10 RPS spread across the three GPUs. As such, the goodput for the 2P1D configuration is 3.3 RPS per GPU.将两个阶段解耦,并分配两个预填充工作节点(两块 GPU)和一个解码工作节点(一块 GPU),即所谓的 2P1D 配置,之后预填充与解码工作节点所达到的整体 RPS 均优于单 GPU 的同机部署配置。具体而言,预填充工作节点达到约 5.6 RPS,解码工作节点达到约 10 RPS,分摊在三块 GPU 上。因此,2P1D 配置的有效吞吐为每 GPU 3.3 RPS。
The 3.3 RPS per GPU is calculated by taking the minimum of the RPS of the prefill workers (5.6 RPS × 2 = 11.2 RPS) and the decode worker (10 RPS). This is 10 RPS total across all three GPUs. As such, we have to divide the RPS by the number of GPUs, or 3 in this case. Under the configured SLOs, this system’s goodput result is 10 RPS ÷ 3 GPUs = 3.3 RPS per GPU.每 GPU 3.3 RPS 的计算方法是:取预填充工作节点的 RPS(5.6 RPS × 2 = 11.2 RPS)与解码工作节点的 RPS(10 RPS)中的最小值。这就是三块 GPU 合计的 10 RPS。因此,需要将该 RPS 除以 GPU 数量,此处为 3。在配置的 SLO 下,该系统的有效吞吐结果为 10 RPS ÷ 3 GPU = 每 GPU 3.3 RPS。
This isolation can also improve tail latencies as well. Empirically, systems that disaggregate show tighter latency distributions—and avoid the long tails seen in monolithic systems. By eliminating cross-phase interference, each phase meets its SLO more reliably—and with more predictable consistency.这种隔离同样可以改善尾部时延。经验表明,采用解耦的系统呈现出更集中的时延分布,并避免了单体系统中常见的长尾。通过消除跨阶段干扰,每个阶段都能更可靠地满足其 SLO,且一致性更可预测。
Now, you should also be asking, “Is the 3× cost worth the 2× improvement?” And you would be right to ask that. Additional tuning is required to make this solution more cost-effective, but it shows the right direction to tighten latency distributions and improve goodput. You need to decide based on your workload. Disaggregation is a popular option to meet goodput RPS needs.此时你也应该会问:“3 倍的成本是否值得 2 倍的提升?”这样问是对的。要让该方案更具成本效益,还需要额外的调优,但它指明了收窄时延分布、提升有效吞吐的正确方向。你需要根据自身工作负载来决策。解耦是满足有效吞吐 RPS 需求的一种流行选择。
阶段专属优化
Phase-specific optimizations
Phase-specific optimizations let each phase use the hardware and parallelism that suits it best. The prefill phase, for instance, is compute bound. As such, you’d typically increase tensor parallelism to drive peak FLOPS on a high-FLOPS GPU. Additionally, modern GPUs provide lower precision modes (FP8 and FP4) that can increase throughput for the compute-heavy prefill phase.阶段专属优化让每个阶段使用最适合它的硬件与并行方式。例如,预填充阶段是计算受限的。因此,通常会提高张量并行度,以在高 FLOPS 的 GPU 上驱动峰值 FLOPS。此外,现代 GPU 提供更低精度的模式(FP8 和 FP4),可提升计算密集的预填充阶段的吞吐量。
In contrast, the decode phase is memory-bandwidth-bound and suffers from cross-GPU synchronization overhead. So it’s most efficient with little or no tensor parallelism (often TP=1) as it relies more on fused kernels to increase arithmetic intensity—as well as high memory throughput GPUs.相比之下,解码阶段受显存带宽限制,并承受跨 GPU 同步开销。因此它在很少甚至不使用张量并行(通常是 TP=1)时效率最高,因为它更多依赖融合内核来提升算术强度——同时也依赖高显存吞吐量的 GPU。
In a monolith you’d have to pick one type of GPU and one parallelism strategy for both phases, which is suboptimal for at least one of the phases. Disaggregation, on the other hand, lets you independently tune each phase for maximum efficiency.在单体部署中,你必须为两个阶段选定同一种 GPU 类型和同一种并行策略,这至少对其中一个阶段而言是次优的。而解耦则让你可以独立调优每个阶段,以获得最大效率。
Splitting phases also opens the door to heterogeneous clusters in which different GPU types are assigned to prefill and decode roles for optimal cost-performance. For example, using compute-optimized GPUs for prompt prefill and memory-optimized GPUs for token generation can produce better throughput per dollar than a homogeneous deployment.拆分阶段还为异构集群打开了大门:把不同类型的 GPU 分别分配给预填充和解码角色,以获得最优的性价比。例如,用计算优化型 GPU 处理提示词预填充、用内存优化型 GPU 处理 token 生成,相比同构部署可以带来更高的每美元吞吐量。
We will explore the idea of heterogeneous clusters later in the chapter. We’ll show how using high-end GPUs for prompts and cheaper GPUs for generation can lead to significant cost savings at scale.我们将在本章后文探讨异构集群这一思路。我们会展示:用高端 GPU 处理提示词、用更便宜的 GPU 做生成,在大规模下可以带来显著的成本节省。
In summary, disaggregation removes cross-interference and enables specialized treatment of each phase. The expected results include tighter latency distributions since no more long tails are caused by mismatched prompt sizes, improved throughput under latency constraints (goodput), and better overall resource utilization.总之,解耦消除了相互干扰,并使得每个阶段都能得到专门化的处理。预期结果包括:时延分布更集中,因为不再有由提示词长度不匹配导致的长尾;在时延约束下的吞吐量(有效吞吐)提升;以及整体资源利用率的改善。
Next, let’s discuss how to actually implement a disaggregated serving system, including the system architecture, communication, and scheduling policies that decide how to fully utilize the disaggregated cluster.接下来,我们讨论如何真正实现一个解耦服务系统,包括系统架构、通信,以及决定如何充分利用解耦集群的调度策略。
解耦的预填充与解码集群池
Disaggregated Prefill and Decode Cluster Pools
In a disaggregated deployment, we maintain two (or more) pools of workers such that one set of GPUs is dedicated to prefill prompt processing and another set is dedicated to token generation. These workers can be on separate nodes or racks in a data center—or even in separate data centers if the interconnect is fast enough. (Note: keeping prefill and decode within the same data center is the practical design choice to achieve realistic SLOs.)在解耦部署中,我们维护两个(或更多)工作节点池,使一组 GPU 专用于预填充的提示词处理,另一组专用于 token 生成。这些工作节点可以位于数据中心内不同的节点或机架上——如果互连足够快,甚至可以位于不同的数据中心。(注意:把预填充和解码保持在同一数据中心内,是实现现实可行 SLO 的务实设计选择。)
The worker pools communicate over a network to hand off the model’s KV cache produced by the prefill to whichever GPU will perform the decode. A scheduler, or router, coordinates this communication.各工作节点池通过网络通信,把预填充产生的模型 KV 缓存移交给将要执行解码的那块 GPU。由调度器(或称路由器)协调这一通信。
Consider a configuration in which the model weights are loaded on two groups of GPU servers. One group, the prefill workers, handles prompts and computes the KV cache. The other group, the decode workers, handles token generation using the KV caches generated from the prefill workers.考虑这样一种配置:模型权重被加载到两组 GPU 服务器上。一组是预填充工作节点,负责处理提示词并计算 KV 缓存。另一组是解码工作节点,使用预填充工作节点生成的 KV 缓存来完成 token 生成。
The two worker groups typically communicate using a high-speed interconnect (e.g., NVLink/NVSwitch and InfiniBand) and zero-copy GPU-to-GPU transfers with RDMA. In practice, these transfers use GPUDirect RDMA or UCX and can be correlated in Nsight Systems alongside CUDA kernels, NVLink activity, storage metrics, and InfiniBand switch metrics for end-to-end validation.这两组工作节点通常通过高速互连(例如 NVLink/NVSwitch 和 InfiniBand)以及基于 RDMA 的零拷贝 GPU 到 GPU 传输进行通信。在实践中,这些传输使用 GPUDirect RDMA 或 UCX,并可在 Nsight Systems 中与 CUDA 内核、NVLink 活动、存储指标和 InfiniBand 交换机指标一起关联查看,以进行端到端验证。
When the system receives a new request, it typically receives it on the decode worker. This is called a decode-centric design. This is preferred because the prefill workers are already compute bound with the KV computations.当系统收到新请求时,通常由解码 worker 接收。这称为*以解码为中心的设计*。之所以偏好这种设计,是因为预填充 worker 已经因 KV 计算而处于计算受限状态。
By having the decode workers handle the client I/O, routing, and session state management, the inference system avoids overloading the prefill workers. Also, centraliz-ing request ingress on the decode nodes simplifies network management, autoscaling, and policy enforcement.通过让解码 worker 处理客户端 I/O、路由和会话状态管理,推理系统可避免使预填充 worker 过载。此外,将请求入口集中在解码节点上,可简化网络管理、自动扩缩容和策略执行。
After the decode worker receives the requests, it decides whether to do the prefill itself or “offload” it to the prefill worker pool. If it decides to offload to the prefill worker pool, the decode worker will later receive the KV results back and then continue with decoding and generating the next token.解码 worker 收到请求后,会决定是自己执行预填充,还是将其“卸载”到预填充 worker 池。如果决定卸载到预填充 worker 池,解码 worker 稍后会收到返回的 KV 结果,然后继续解码并生成下一个 token。
Next is a snippet from a simplified NVIDIA Dynamo cluster configuration that defines two roles that use NVIDIA’s Inference Xfer Library (NIXL) for GPUDirect RDMA-based KV cache transfers to let one GPU write into another GPU’s memory directly over the network:下面是一段简化的 NVIDIA Dynamo 集群配置片段,其中定义了两个角色,它们使用 NVIDIA 的 Inference Xfer Library(NIXL)进行基于 GPUDirect RDMA 的 KV 缓存传输,使一块 GPU 能够通过网络直接写入另一块 GPU 的内存:
roles:
  - name: prefill_worker     # 预填充 worker 角色
    model_path: models/llm-70b
    instance_count: 4        # 4 个预填充 worker
    gpu_type: B200           # B200 Blackwell 计算受限的预填充
  - name: decode_worker      # 解码工作节点角色
    model_path: models/llm-70b
    instance_count: 8        # 8 个解码工作节点
    gpu_type: B300           # B300 Blackwell Ultra 高内存解码
roles:
  - name: prefill_worker     # Prefill worker role
    model_path: models/llm-70b
    instance_count: 4        # 4 prefill workers
    gpu_type: B200           # B200 Blackwell compute-bound prefill
  - name: decode_worker      # Decode worker role
    model_path: models/llm-70b
    instance_count: 8        # 8 decode workers
    gpu_type: B300           # B300 Blackwell Ultra high-memory decode
In this configuration, we have four prefill workers using B200 GPUs (adequate compute for compute-heavy prefills) and eight decode workers using B300 GPUs (high HBM capacity for heavy memory-bound decodes). Mixing B200s and B300s helps to match their FLOPS and HBM capacity characteristics while minimizing cost. Both roles will use NIXL and GPUDirect RDMA to transfer the KV cache blocks. NIXL abstracts transport for GPU-to-GPU data movement over NVLink and RDMA NICs. It also provides connectors for GPUDirect Storage so that KV cache pages can be read from (or written to) different storage tiers.在此配置中,我们有四个使用 B200 GPU 的预填充 worker(为计算密集的预填充提供充足算力)和八个使用 B300 GPU 的解码 worker(为显存密集的解码提供高 HBM 容量)。混合使用 B200 和 B300 有助于匹配它们的 FLOPS 与 HBM 容量特性,同时将成本降至最低。两个角色都将使用 NIXL 和 GPUDirect RDMA 传输 KV 缓存块。NIXL 抽象了通过 NVLink 和 RDMA 网卡进行 GPU 到 GPU 数据移动的传输层。它还为 GPUDirect Storage 提供连接器,从而可以从不同存储层级读取(或写入)KV 缓存页。
Under the hood, when this system runs, each decode worker registers a region of its GPU memory so that prefill workers can write directly into it using RDMA. Typically, memory-registration metadata such as NIXL descriptors are exchanged at startup or on first contact. This way, for each remote prefill task, only a small identifier needs to be sent rather than a full memory address structure.在底层,当该系统运行时,每个解码 worker 会注册其 GPU 显存的一个区域,以便预填充 worker 可以使用 RDMA 直接写入其中。通常,诸如 NIXL 描述符之类的显存注册元数据会在启动时或首次接触时交换。这样,对于每个远程预填充任务,只需发送一个小标识符,而无需发送完整的显存地址结构。
For instance, Dynamo uses etcd for worker discovery and leases. Workers register the necessary memory handles with the router or control plane so that peers can obtain the descriptors when needed. The prefill workers will retrieve them on first use. This way, a prefill request can include just an ID for the target KV buffer, making control messages lightweight.例如,Dynamo 使用 etcd 进行 worker 发现和租约管理。worker 向路由器或控制平面注册必要的内存句柄,以便对等方在需要时获取描述符。预填充 worker 将在首次使用时获取它们。这样,预填充请求只需包含目标 KV 缓冲区的 ID,从而使控制消息保持轻量。
Furthermore, NVIDIA Dynamo’s NIXL implementation provides a high throughput RDMA and storage abstraction for inference data movement and includes plugins for NVLink, UCX-based fabric, and GPUDirect Storage. As such, prefill workers can write KV blocks directly into decode GPU memory.此外,NVIDIA Dynamo 的 NIXL 实现为推理数据移动提供了高吞吐量的 RDMA 和存储抽象,并包含针对 NVLink、基于 UCX 的 fabric 以及 GPUDirect Storage 的插件。因此,预填充 worker 可以直接将 KV 块写入解码 GPU 显存。
This architecture decouples scaling for each phase. If you find that prefill is the throughput bottleneck due to many concurrent long prompts, for instance, you can add more prefill workers to increase prompt processing capacity.该架构将各阶段的扩缩容解耦。例如,如果你发现由于大量并发长提示词导致预填充成为吞吐量瓶颈,就可以增加更多预填充工作节点来提升提示词处理能力。
If decode becomes the bottleneck due to many users generating long outputs, for instance, you would scale out decode workers. Because decode and prefill are separated, scaling one doesn’t directly interfere with the other.例如,如果由于大量用户生成长输出导致解码成为瓶颈,就应当横向扩展解码工作节点。由于解码与预填充相互分离,扩展其中一个不会直接干扰另一个。
Systems like NVIDIA Dynamo support dynamic, runtime-configurable disaggregation such that you can add or remove prefill workers on the fly—without stopping the cluster. New prefill workers simply register and start pulling tasks from the queue. If a prefill worker leaves the cluster for whatever reason (crash, restart, autoscale event, network partition, etc.), the decode workers will temporarily do more local prefills to compensate.NVIDIA Dynamo 这类系统支持动态的、可在运行时配置的解耦,因此你可以在运行中增加或移除预填充工作节点——无需停止集群。新的预填充工作节点只需注册,然后开始从队列中拉取任务。如果某个预填充工作节点因任何原因(崩溃、重启、自动扩缩容事件、网络分区等)离开集群,解码工作节点会临时承担更多本地预填充以作补偿。
NVIDIA Dynamo’s distributed runtime uses etcd for worker discovery and leases. Its Planner component can scale workers by revoking leases or launching new workers which are auto-discovered. This dynamic flexibility is crucial at ultrascale when load will often fluctuate. When this happens, you’ll want to swap workers between roles as needed.NVIDIA Dynamo 的分布式运行时使用 etcd 进行工作节点发现与租约管理。其 Planner 组件可以通过撤销租约或启动会被自动发现的新工作节点来扩缩容。在负载经常波动的超大规模场景下,这种动态灵活性至关重要。当这种情况发生时,你会希望按需在角色之间调换工作节点。
预填充工作节点设计
Prefill workers design
Prefill workers, or prompt servers, are the compute nodes dedicated to executing the initial prompt prefill processing phase of requests. This section discusses how prefill nodes are architected to handle the heavy computation efficiently—and how they balance latency versus throughput for KV cache population under load.预填充工作节点,即*提示词服务器*,是专门执行请求初始提示词预填充处理阶段的计算节点。本节讨论预填充节点如何架构以高效处理繁重计算——以及在负载下如何为 KV 缓存填充平衡时延与吞吐量。
Because the prefill workload is computationally intensive, prefill nodes should use GPUs with high FLOPS and be optimized for large matrix multiplications. Each prefill task feeds n input tokens through all model layers.由于预填充工作负载计算密集,预填充节点应使用高 FLOPS 的 GPU,并针对大型矩阵乘法进行优化。每个预填充任务将 n 个输入 token 依次送入所有模型层。
The prefill workers will use thousands of GPU threads in parallel—and across many GPU nodes, if available. They use familiar parallelism techniques, including tensor parallelism and pipeline parallelism, to reduce TTFT.预填充工作节点会并行使用数千个 GPU 线程——如果可用,还会跨多个 GPU 节点。它们使用熟悉的并行技术,包括张量并行与流水线并行,以降低 TTFT。
Memory management. Memory-wise, prefill nodes need to load the full model weights and also allocate KV cache for the prompt. This KV cache is then transferred to the decode workers, as we’ll see in a bit.内存管理。 在内存方面,预填充节点需要加载完整的模型权重,并为提示词分配 KV 缓存。随后该 KV 缓存会被传输到解码工作节点,我们稍后会看到。
Prefill populates GPU memory with model parameters and the working activations of the model’s forward pass with the prompt inputs. Once the KV cache is created, it’s immediately sent to the decode workers. The KV cache doesn’t persist long in the prefill node’s memory.预填充会将模型参数以及模型使用提示词输入进行前向传播时的工作激活值填充到 GPU 显存中。KV 缓存一旦创建,就会立即发送给解码工作节点。KV 缓存在预填充节点的显存中不会长期驻留。
If a model is extremely large or a prompt is extremely long, prefill may require tensor or parallel splits across GPUs due to memory limitations. Prefill servers should be flexible with their parallelism strategies (data, tensor, pipeline, expert (MoE), and context) to meet latency targets.如果模型极大或提示词极长,受内存限制,预填充可能需要跨 GPU 进行张量切分或并行切分。预填充服务器应灵活采用其并行策略(数据、张量、流水线、专家(MoE)与上下文并行),以满足时延目标。
Some inference frameworks preallocate a big chunk of GPU memory for prefills to use as working space. This reduces overall memory fragmentation and buffer allocation time.一些推理框架会为预填充预分配一大块 GPU 显存作为工作空间。这可以减少整体显存碎片与缓冲区分配时间。
Optimizing for latency versus throughput. When tuning a disaggregated prefill cluster, you face a fundamental trade-off between minimizing the TTFT for each individual prompt and maximizing overall requests per second (RPS), or reducing TPOT, under heavy load.时延与吞吐量的优化权衡。 在调优解耦预填充集群时,你会面临一个根本性权衡:在重负载下,是在最小化每个单独提示词的 TTFT 与最大化整体每秒请求数(RPS)(或降低 TPOT)之间取舍。
Disaggregated systems handle this trade-off by supporting different scheduling policies for a latency-first approach versus a throughput-first approach. Let’s describe each of these approaches next:解耦系统通过为时延优先方法与吞吐量优先方法支持不同的调度策略,来应对这一权衡。下面我们逐一描述这些方法:
- Latency-first approach时延优先方法
- To reduce TTFT, prefill nodes should process prompts as soon as they arrive— and with little to no batching. In this mode, you avoid waiting for other requests to fill a batch. As such, every prompt starts execution immediately and finishes as fast as possible—assuming available GPUs in the cluster.为降低 TTFT,预填充节点应在提示到达时立即处理——并且几乎不进行批处理甚至完全不批处理。在此模式下,无需等待其他请求来凑满一个批次。因此,每个提示都会立即开始执行并尽快完成——前提是集群中有可用的 GPU。
The downside of this latency-first approach is lower GPU utilization since you are using small or no batches. As such, GPUs often sit idle, and your system will serve fewer concurrent requests for a given cluster size. In this case, you can either over-provision your prefill cluster capacity or use a tiny batch size of 1 to guarantee strict latency SLOs for your requests.这种时延优先方法的缺点是 GPU 利用率较低,因为使用的是小批次或不使用批次。因此,GPU 经常处于空闲状态,在给定集群规模下系统能服务的并发请求更少。在这种情况下,你可以超额配置预填充集群容量,或者使用大小为 1 的极小批大小,以保证请求的严格时延 SLO。
- Throughput-first approach吞吐量优先方法
- If peak throughput, or RPS, and minimal TPOT are your priorities, you should batch prompts into larger groups to fully load each GPU. By accumulating 8–32如果峰值吞吐量(即 RPS)和最小 TPOT 是你的优先目标,就应将提示聚合成更大的组,以充分压满每个 GPU。通过将 8–32
prompts into a single batch, you raise arithmetic intensity and keep the GPU compute units busy. This will increase the overall throughput.个提示累积到单个批次中,可以提高算术强度并让 GPU 计算单元保持忙碌。这将提升整体吞吐量。
The downside to the throughput-first approach is that each request incurs a batching delay equal to the time it takes to collect the batch. The larger the batch size, the longer the delay.吞吐量优先方法的缺点是,每个请求都会产生等于收集该批次所需时间的批处理延迟。批大小越大,延迟越长。
For extreme throughput inference system configurations, you can choose to assign multiple GPUs per request using either data parallelism or pipeline parallelism.对于极致吞吐量的推理系统配置,你可以选择通过数据并行或流水线并行,为每个请求分配多个 GPU。
With data parallelism, the entire model is replicated on each GPU. The batch is split into minibatches across the GPUs. Each GPU performs a forward pass on its subset of data through its complete copy of the model. The output is then aggregated from all the GPUs for the final output.在数据并行中,整个模型会在每个 GPU 上复制一份。批次被拆分为多个小批次分配到各 GPU 上。每个 GPU 用其完整的模型副本对各自的数据子集执行一次前向传播。随后汇总所有 GPU 的输出以得到最终输出。
Data parallelism aggregates memory bandwidth and compute power across all of the GPUs to increase per-batch performance. However, it reduces maximum parallelism to the total # of GPUs ÷ GPUs per request. This reduces your overall concurrent request capacity. This can leave resources idle if the system uses too many GPUs per single request. This will create an imbalance between throughput and concurrency.数据并行聚合所有 GPU 的显存带宽与算力,以提升单批次性能。然而,它会把最大并行度降低为 GPU 总数 ÷ 每请求 GPU 数。这降低了整体并发请求容量。如果系统为单个请求使用过多 GPU,就会造成资源闲置。这会在吞吐量与并发度之间造成失衡。
Pipeline parallelism divides the model’s layers into sequential stages on different GPUs, such as GPU 0 and GPU 1. As soon as GPU 0 finishes its stage for microbatch 0, it forwards activations to GPU 1 and begins stage 1 for microbatch 1. This assembly-line pattern keeps all GPUs busy on different chunks of work.流水线并行将模型的层划分为位于不同 GPU(例如 GPU 0 和 GPU 1)上的顺序阶段。一旦 GPU 0 完成微批次 0 的阶段,它就把激活值转发给 GPU 1,并开始微批次 1 的阶段 1。这种流水线模式让所有 GPU 都忙于不同的工作块。
Pipeline parallelism increases per-batch throughput, but it adds inter-GPU communication overhead and pipeline “bubbles” if the microbatch size or stage splits are not carefully balanced.流水线并行提升了单批次吞吐量,但如果微批大小或阶段划分没有仔细平衡,它会带来 GPU 间通信开销和流水线“气泡”。
Ultimately, each additional GPU that you dedicate will increase throughput but decrease how many requests you can handle at once—given a fixed-size cluster. You can always scale out the GPU cluster, but assuming a fixed cluster size, you should choose your configuration based on whether latency SLOs or throughput SLOs are most important to your use case.最终,在固定规模的集群下,你每多投入一块 GPU,吞吐量就会提升,但同时能处理的请求数会减少。你随时可以横向扩展 GPU 集群,但在假定集群规模固定的情况下,应根据你的用例最看重时延 SLO 还是吞吐量 SLO 来选择配置。
Latency-aware scheduling and batching. Disaggregated systems incorporate the latency-aware scheduling policies mentioned earlier to balance these factors. For instance, they might guarantee single-request execution—and not batch requests—unless load is high enough that combining a small number of requests won’t violate the TTFT target.时延感知的调度与批处理。 解耦系统会采用前面提到的时延感知调度策略来平衡这些因素。例如,它们可能保证单请求执行——而不对请求做批处理——除非负载高到足以让合并少量请求不会违反 TTFT 目标。
Many cluster designs include an SLO constraint in the scheduler. For instance, if p90 TTFT must be ≤ X ms, the system will choose the largest batch size or parallelism strategy that still meets the SLO for a typical prompt size.许多集群设计会在调度器中加入 SLO 约束。例如,如果 p90 TTFT 必须 ≤ X ms,系统会选择在典型提示长度下仍能满足该 SLO 的最大批大小或并行策略。
Another strategy is adaptive batching windows. For instance, at low load, it can run requests immediately using a batch size of 1. And at higher loads, the system can allow microbatches of requests arriving within a small time window, such as 2–10 ms. This way, a slight delay can produce a big GPU utilization win—but only when it’s needed and tolerable.另一种策略是自适应批处理窗口。例如,在低负载时,它可以以批大小为 1 立即执行请求。而在较高负载下,系统可以允许将在一个小时间窗口(例如 2–10 ms)内到达的请求组成微批。这样一来,轻微的延迟就能带来 GPU 利用率的巨大收益——但仅在需要且可容忍的时候。
Many inference engines favor latency for their prefill workers. Systems often execute prompt tasks as soon as possible and even tolerate some GPU underutilization, because a fast first token significantly improves user experience.许多推理引擎为其预填充工作节点优先考虑时延。系统通常会尽快执行提示任务,甚至容忍一定程度的 GPU 利用率不足,因为快速产出首个 token 能显著改善用户体验。
It’s common to provision more prefill capacity than needed for an average load. This way, the prefill cluster absorbs bursts of prompts without latency spikes. In the next chapter, we will discuss adaptive mechanisms to rebalance resources on the fly so that neither the prefill nor the decode workers become a bottleneck over time.常见做法是按超出平均负载所需来配置预填充容量。这样,预填充集群就能吸收突发提示而不出现时延尖峰。下一章我们将讨论动态重新平衡资源的自适应机制,使预填充与解码工作节点都不会随时间推移成为瓶颈。
Modern orchestrators like Kubernetes can automatically scale each tier. For example, if prefill GPU utilization stays high and decode is low, the orchestrator can trigger an autoscaling event to add prefill pods (or nodes)—and possibly even remove some decode pods/nodes.像 Kubernetes 这样的现代编排器可以自动扩缩每个层级。例如,如果预填充的 GPU 利用率持续偏高而解码偏低,编排器可以触发自动扩缩事件来增加预填充 pod(或节点)——甚至可能移除一些解码 pod/节点。
Another option is to implement priority queues such that short prompts are scheduled on a separate fast lane with less batching. Long, batchable prompts go to a throughput-optimized queue. NVIDIA Dynamo supports latency classes in scheduling. You can emulate this by tagging requests and having different batching windows per class.另一种选择是实现优先级队列,使短提示被调度到单独的快速通道上,采用更少的批处理。长的、可批处理的提示则进入吞吐量优化的队列。NVIDIA Dynamo 在调度中支持时延类别。你可以通过给请求打标签,并为每个类别设置不同的批处理窗口来模拟这一行为。
The key takeaway is that prefill workers prioritize quick turnaround. Disaggregation lets us do this without harming decode performance since decode is running on a different set of workers. We might “waste” some prefill GPU cycles during low-traffic periods, but we maintain low TTFT during peak traffic periods. It’s a worthwhile trade-off for interactive services.关键要点是:预填充工作节点优先考虑快速周转。解耦让我们能够做到这一点而不损害解码性能,因为解码运行在另一组工作节点上。在低流量时段,我们可能会“浪费”一些预填充 GPU 周期,但在高峰流量时段我们保持了低 TTFT。对于交互式服务而言,这是值得的权衡。
解码工作节点设计
Decode workers design
Decode workers, or generation servers, are dedicated to the autoregressive decode phase. Once a prompt’s KV cache is ready, it is sent to a decode worker, which uses the KV cache to produce the remaining output tokens as quickly as possible to maintain a low TPOT latency.解码工作节点,或称*生成服务器*,专用于自回归解码阶段。一旦某个提示的 KV 缓存准备就绪,它就会被发送到解码工作节点,后者利用该 KV 缓存尽快生成剩余的输出 token,以维持较低的 TPOT 时延。
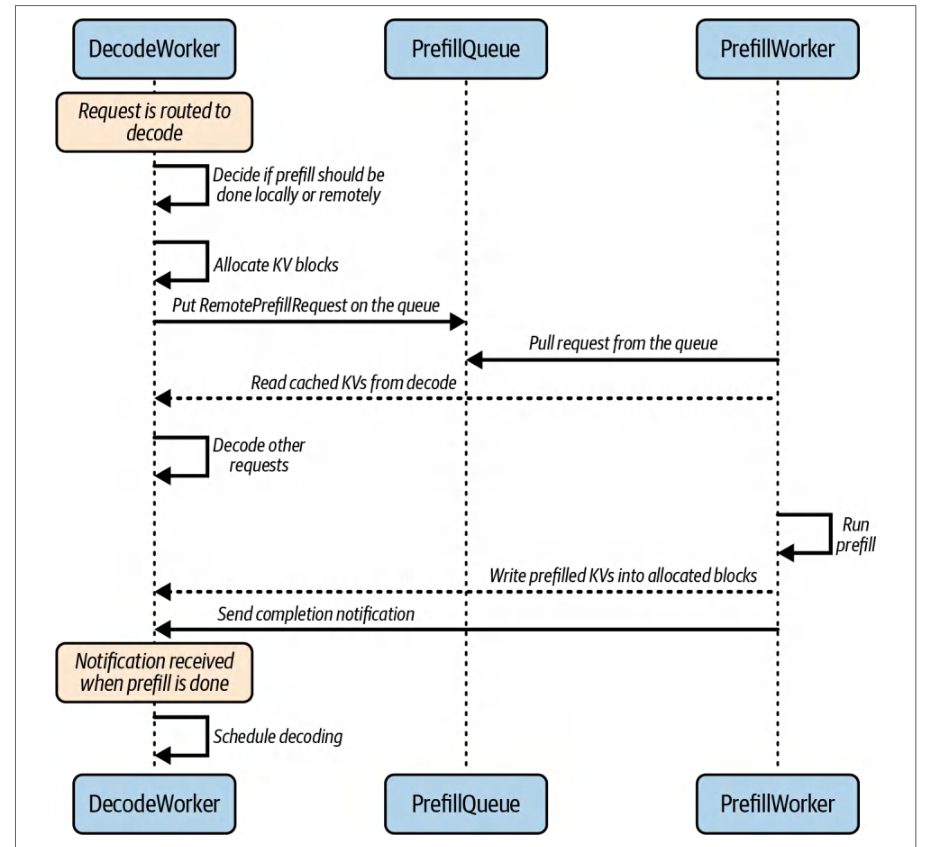
If a request is initially routed to the decode worker, as in Figure 17-3, it must first decide if the prefill should be done locally or remotely using a disaggregated router. If it decides to prefill remotely, it will push the prefill request into a prefill queue to be picked up by the prefill worker.如果请求最初被路由到解码工作节点(如图 17-3 所示),它必须首先借助解耦路由器决定预填充应在本地还是远程完成。如果决定远程预填充,它就会把预填充请求推入预填充队列,由预填充工作节点取走处理。
The prefill worker continuously pulls from the prefill queue, reads any KV blocks cached in the prefix cache, and computes the prefill operations. It then writes the KV blocks back to the decode worker, which completes the decoding.预填充工作节点持续从预填充队列中拉取请求,读取前缀缓存中已缓存的 KV 块,并计算预填充操作。随后它把 KV 块写回解码工作节点,由后者完成解码。
The decode worker design is focused on handling many concurrent sequence generations efficiently—as well as managing the memory footprint of the KV cache. In this section, we describe how decode servers achieve high throughput using techniques like continuous batching and clever memory management tricks. These help to reduce TPOT latency and increase scalability—especially for long sequences. Let’s start by detailing the KV cache transfer between the two stages.解码工作节点(decode worker)的设计重点在于高效处理大量并发的序列生成,同时管理 KV 缓存的显存占用。本节介绍解码服务器如何借助连续批处理(continuous batching)等技术和巧妙的内存管理手段实现高吞吐量。这些手段有助于降低 TPOT 时延并提升可扩展性,对长序列尤为如此。我们先详细说明两个阶段之间的 KV 缓存传输。
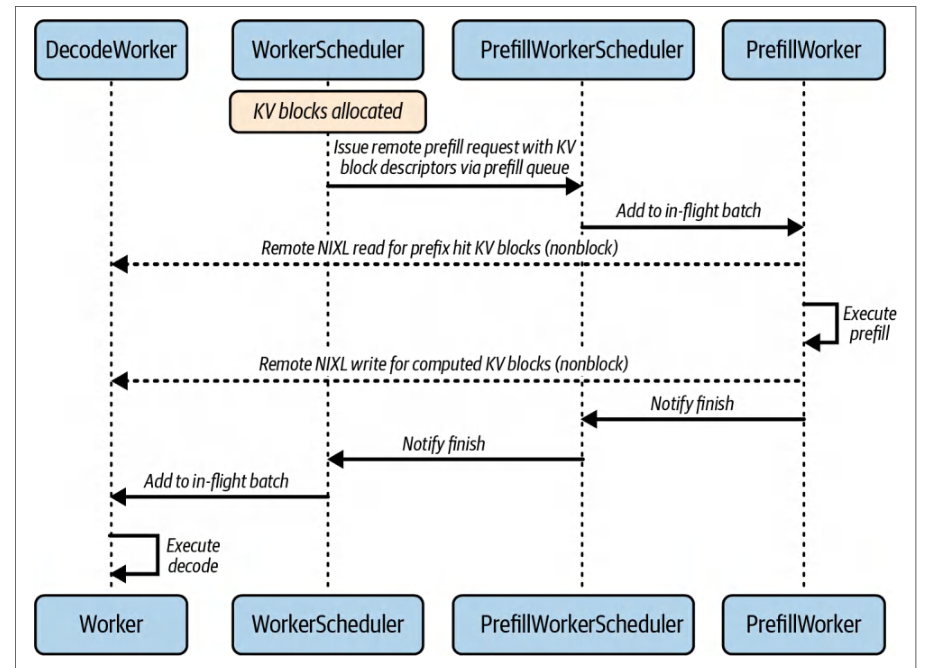
KV cache transfer between prefill and decode. High-performance disaggregation requires moving KV cache data as efficiently as possible between the prefill and decode workers. By using libraries like NIXL (described in Chapter 4) for direct GPU-to-GPU transfers, we can avoid CPU involvement and utilize nonblocking operations. This way, while one GPU is transferring KV data, it can also service other forward-pass requests without waiting for the transfer to complete.预填充与解码之间的 KV 缓存传输。 高性能解耦要求在预填充与解码工作节点之间尽可能高效地搬运 KV 缓存数据。借助 NIXL(第 4 章介绍)等库进行 GPU 到 GPU 的直接传输,可以避免 CPU 参与并使用非阻塞操作。这样一来,一块 GPU 在传输 KV 数据的同时,还能处理其他前向传播请求,而无需等待传输完成。
Consider a user request that arrives at a decode worker. In this case, the decode worker’s scheduler allocates the necessary KV blocks and adds a remote prefill request to the prefill queue. This prefill request contains the identifiers for those KV blocks. This interaction is shown in Figure 17-4.假设一个用户请求到达解码工作节点。此时,解码工作节点的调度器会分配所需的 KV 块,并向预填充队列添加一个远程预填充请求。该预填充请求包含这些 KV 块的标识符。这一交互过程如图 17-4 所示。
The prefill worker uses NIXL to perform direct remote GPU memory reads and writes over the selected transport. This avoids CPU copies and enables nonblocking progress. As soon as the prefill worker completes the prefill request, the decode worker’s scheduler adds a corresponding decode request to its own decode pipeline. This allows compute and data movement to overlap seamlessly. Make sure to use preregistered peer memory with large pinned window sizes to minimize re-registration churn. You can verify zero-copy transfer overlap with the Nsight Systems timeline.预填充工作节点使用 NIXL,通过选定的传输方式直接对远端 GPU 显存执行读写。这避免了 CPU 拷贝,并支持非阻塞推进。预填充工作节点一旦完成预填充请求,解码工作节点的调度器就会把相应的解码请求加入自己的解码流水线。这使得计算与数据搬运能够无缝重叠。务必使用已预注册的对端显存(peer memory)并设置较大的锁页窗口大小,以尽量减少重复注册带来的开销。你可以借助 Nsight Systems 时间线验证零拷贝传输的重叠情况。
When validating end-to-end data movement and overlap, it’s recommended to profile with Nsight Systems using trace flags. For InfiniBand link telemetry, add --nic-metrics=true for HCA/NIC counters and --ib-switch-metrics-device=<GUIDs> for switch counters. These will capture switch metrics and sample host/device activity. Together, this will produce correlated CUDA kernels, UCX activity, storage metrics, and network behavior. Following is a unified command that enables CUDA/UCX tracing and collects CPU activity, GPU metrics, storage metrics, and InfiniBand switch telemetry:在验证端到端数据搬运与重叠情况时,建议使用跟踪标志(trace flags)配合 Nsight Systems 进行性能剖析。对于 InfiniBand 链路遥测,可添加 --nic-metrics=true 以采集 HCA/NIC 计数器,添加 --ib-switch-metrics-device=<GUIDs> 以采集交换机计数器。这些选项会捕获交换机指标并采样主机/设备活动。综合起来,就能生成相互关联的 CUDA 内核、UCX 活动、存储指标和网络行为数据。下面是一条统一命令,可启用 CUDA/UCX 跟踪,并采集 CPU 活动、GPU 指标、存储指标和 InfiniBand 交换机遥测:
nsys profile --trace=cuda-hw,osrt,nvtx,ucx,gds \
  --trace-fork-before-exec=true \
  --cuda-event-trace=true \
  --cuda-graph-trace=node \
  --cuda-memory-usage=true \
  --sample=cpu \
  --gpu-metrics-device=all \
  --nic-metrics=true \
  --ib-switch-metrics-device=<GUIDs> \
  --storage-metrics --storage-devices=all \
  --gds-metrics=driver \
  -o nsys_reports/prefill_decode \
  <your_launch_here>
Continuous batching. Decode servers rely heavily on continuous batching, also known as iteration-level batching. Unlike the prefill phase, which performs large matrix-matrix computations, the decoding phase performs many small computations since each new token generation is a relatively small vector-matrix computation since the individual token is represented as a vector.连续批处理。 解码服务器高度依赖连续批处理,也称为*迭代级批处理*(iteration-level batching)。预填充阶段执行的是大型矩阵-矩阵计算,而解码阶段则执行大量小规模计算:由于单个 token 以向量表示,每个新 token 的生成都是一次相对较小的向量-矩阵计算。
To avoid low GPU utilization for small, per-token workloads, decode workers can batch together multiple input sequences to create larger matrix-matrix computations (e.g., multiple token generations) at each iteration. This increases the arithmetic intensity for each decode task.为避免小规模、逐 token 的工作负载导致 GPU 利用率偏低,解码工作节点可以在每次迭代中将多个输入序列批处理在一起,构成更大规模的矩阵-矩阵计算(例如多个 token 的生成)。这会提高每个解码任务的算术强度。
For example, suppose 32 different text-generation requests are mid-stream and ready to generate their next token. Instead of computing 32 separate, single-token forward passes, a continuous batching scheduler will combine the requests and perform one forward pass that generates 32 tokens (one per sequence) in parallel.例如,假设有 32 个不同的文本生成请求正处于生成中途,并准备生成它们的下一个 token。连续批处理(continuous batching)调度器不会计算 32 次独立的单 token 前向传播,而是将这些请求合并,执行一次前向传播,并行生成 32 个 token(每个序列一个)。
This way, matrix multiplications see an effective batch size of 32, which keeps the GPU compute units busy. The challenge is that not all sequences request a token at the exact same time. Some may finish early, and others may start late.这样一来,矩阵乘法看到的有效批大小为 32,从而使 GPU 计算单元保持忙碌。挑战在于,并非所有序列都在完全相同的时刻请求 token。有些可能提前结束,另一些则可能较晚开始。
Remember that you can batch across different requests and users. Most modern inference servers will automatically group decode steps from different users’ requests if the sequences have the same context length at that moment. This effectively performs batched decoding on the fly. Consider such solutions for maximizing decode throughput.请记住,你可以跨不同请求和用户进行批处理。大多数现代推理服务器会自动将不同用户请求的解码步骤分组,前提是这些序列在那一刻具有相同的上下文长度。这实际上是在运行过程中动态执行批量解码。为最大化解码吞吐量,可以考虑此类方案。
Continuous batching addresses the issue of sequences requesting tokens at different times by dynamically updating the batch size at each step. Specifically, at each step, a continuous batching strategy will gather all sequences that are ready for a next token at that moment and batch them into a single decode step.连续批处理通过在每一步动态更新批大小,解决了序列在不同时刻请求 token 的问题。具体而言,在每一步,连续批处理策略会收集该时刻所有已准备好生成下一个 token 的序列,并将它们合并为一次解码步骤。
If new requests finish prefill and become ready while the decode is in progress, they will join the next batch without waiting an arbitrary long idle period. This is in contrast to static batching, which will wait to gather a full batch before decoding.如果新请求在解码进行期间完成预填充并准备就绪,它们会加入下一批次,而无需等待一段任意长的空闲时间。这与静态批处理形成对比——静态批处理会等待凑满一个完整批次后才开始解码。
If a sequence finishes by hitting an end-of-text token or a sequence-length limit, it is removed from subsequent batches immediately. If a sequence is not yet ready—perhaps it’s a long prompt still being processed in prefill—it won’t be included until it becomes ready.如果某个序列因遇到文本结束 token 或达到序列长度上限而结束,它会立即从后续批次中移除。如果某个序列尚未就绪——也许是一个仍在预填充阶段处理的长提示——那么在它就绪之前不会被纳入。
Effectively, with continuous batching, the batch size on each iteration can fluctuate. However, the server is always trying to maximize the batch size to include whatever sequences are available at that time—up to a limit. This achieves high utilization while minimizing per-token waiting time.实际上,采用连续批处理时,每次迭代的批大小会波动。不过,服务器始终在尝试最大化批大小,以纳入当时所有可用的序列——直至某个上限。这样既能实现高利用率,又能最小化每个 token 的等待时间。
Continuous batching makes sure that decode GPU workers never sit idle. They are always working on available requests. This maximizes their throughput under latency constraints by keeping the GPU busy—even as individual sequences await new tokens.连续批处理确保解码 GPU 工作节点永不空闲。它们始终在处理可用的请求。通过让 GPU 保持忙碌——即使在单个序列等待新 token 时也是如此——从而在时延约束下最大化吞吐量。
Similarly, Microsoft’s DeepSpeed and NVIDIA’s TensorRT-LLM inference engines implement continuous or in-flight batching with paged KV caches to keep GPU utilization high during decoding. Specifically, DeepSpeed combines multiple generation requests, and TensorRT-LLM uses a scheduler to group decoding tasks across streams.类似地,Microsoft 的 DeepSpeed 和 NVIDIA 的 TensorRT-LLM 推理引擎通过分页 KV 缓存实现连续批处理或飞行中批处理(in-flight batching),以在解码期间保持高 GPU 利用率。具体而言,DeepSpeed 会合并多个生成请求,而 TensorRT-LLM 使用调度器跨流对解码任务进行分组。
In a disaggregated decode cluster, continuous batching becomes even more powerful. Since decode GPUs handle only generation, they can devote 100% of their cycles to this continuous loop without ever being interrupted by a large, bespoke prompt task. This leads to smoother throughput metrics—especially under load.在解耦的解码集群中,连续批处理变得更加强大。由于解码 GPU 只负责生成,它们可以将 100% 的周期投入到这一连续循环中,而不会被大型的定制提示任务打断。这带来更平稳的吞吐量指标——尤其是在高负载下。
Under high load, a decode node might have tens or hundreds of sequences concurrently active. It can batch a large number of them at each iteration. This will maximize hardware utilization.在高负载下,一个解码节点可能同时有数十甚至数百个活跃序列。它可以在每次迭代中批处理其中大量序列。这将最大化硬件利用率。
And under low load, even if only one sequence is active, the decode worker can immediately generate the token. It doesn’t have to wait to fill a batch. In this case, the GPU will be underutilized for that moment, but the latency for that single sequence remains low. As such, continuous batching handles both extremes: at high concurrency it’s efficient, and at low concurrency it’s responsive. This is a good balance of high throughput and low latency.而在低负载下,即使只有一条序列处于活跃状态,解码 worker 也能立即生成 token。它不必等待凑满一个批。此时 GPU 会暂时处于低利用率状态,但该单条序列的时延仍然很低。因此,连续批处理(continuous batching)兼顾了两种极端情况:高并发时高效,低并发时响应迅速。这是高吞吐量与低时延之间的良好平衡。
Grouping variable-length sequences. Handling variable-length sequences in LLM inference requires careful scheduling and batching to avoid wasted computation and memory. Mixing short and long prompts in one batch leads to padding overhead— sometimes up to 50% padding relative to the number of tokens. This wastes scarce GPU and network resources.对变长序列进行分组。 在 LLM 推理中处理变长序列需要精心的调度与批处理,以避免浪费计算和内存。将短提示与长提示混在同一个批中会带来填充开销——相对于 token 数量,填充有时高达 50%。这会浪费稀缺的 GPU 与网络资源。
When you batch prompts of differing lengths together, every shorter sequence must be padded to match the longest one. This padding introduces “no-op” tokens that still consume GPU cycles, memory bandwidth, and inter-GPU or network transfers. In some cases, padding can account for up to half of all tokens in common generative AI workloads. This significantly reduces inference efficiency.当你把长度不同的提示批处理在一起时,每条较短的序列都必须填充到与最长序列一致。这种填充引入了“空操作”token,它们仍然消耗 GPU 周期、显存带宽以及 GPU 间或网络传输。在某些情况下,在常见的生成式 AI 工作负载中,填充可占到全部 token 的一半。这显著降低了推理效率。
A straightforward solution is to group requests into buckets based on sequence length. This way, each batch contains sequences of similar sizes. Using static-length buckets like 0–512 tokens, 513–1,024 tokens, etc., fixes the batch boundaries and minimizes padding overhead.一个直接的解决方案是按序列长度将请求分组到不同的桶中。这样,每个批都包含大小相近的序列。使用诸如 0–512 个 token、513–1,024 个 token 等定长桶,可以固定批的边界并最小化填充开销。
vLLM’s decode scheduler maintains a rotating pool of SequenceGroup instances (each prompt is a SequenceGroup). The scheduler advances each group after a fixed token budget per decode iteration. As soon as a SequenceGroup is done processing its chunk, it leaves the pool, and a new SequenceGroup joins the pool. This keeps the pipeline continuously full of work—without relying on static padding buckets or underutilizing GPUs.vLLM 的解码调度器维护一个由 SequenceGroup 实例组成的轮转池(每个提示是一个 SequenceGroup)。调度器在每次解码迭代中按固定的 token 预算推进每个组。一旦某个 SequenceGroup 处理完自己的分块,它就离开该池,同时一个新的 SequenceGroup 加入该池。这使流水线持续充满工作——而无需依赖静态填充桶,也不会让 GPU 处于低利用率状态。
These batching and scheduling techniques align well with disaggregated prefill-decode deployments with separate prefill and decode clusters. Using this deployment configuration, the separate decode nodes can use techniques like continuous batching to minimize TPOT variance under strict SLOs. Meanwhile, the dedicated prefill nodes can be tuned independently for maximum input-processing throughput and minimum TPOT.这些批处理与调度技术非常契合采用独立预填充集群与解码集群的解耦预填充-解码部署。使用这种部署配置,独立的解码节点可以采用连续批处理等技术,在严格的 SLO 下最小化 TPOT 波动。与此同时,专用的预填充节点可以独立调优,以获得最大的输入处理吞吐量和最小的 TPOT。
NVIDIA’s Programmatic Dependent Launch (PDL) and device-initiated CUDA Graph Launch (discussed in Chapter 12) are used to reduce per-token launch overhead, overlap work, and eliminate bubbles between decode iterations. These features are generally enabled through the framework rather than manually in application code.NVIDIA 的编程式依赖启动(Programmatic Dependent Launch,PDL)与设备发起的 CUDA 图启动(device-initiated CUDA Graph Launch)(在第 12 章讨论)用于降低每 token 的启动开销、重叠工作,并消除解码迭代之间的气泡。这些特性通常通过框架启用,而不是在应用代码中手动启用。
When using device-launched graphs, instantiate with cudaGraphInstantiateFlagDe viceLaunch and keep nodes on a single device. Use PDL to overlap dependent kernels at the end of a step (e.g., decode iteration). This further trims per-token launch bubbles.使用设备启动的图时,请以 cudaGraphInstantiateFlagDe viceLaunch 实例化,并将节点保持在单个设备上。使用 PDL 在一个步骤(例如解码迭代)末尾重叠相互依赖的内核。这进一步削减了每 token 的启动气泡。
By combining length-bucketing, continuous batching, disaggregation, PDL, and device-initiated CUDA Graphs, modern inference systems like vLLM, SGLang, and NVIDIA Dynamo can achieve both high throughput and low latency—even for wildly varying prompt lengths. And they do this without impacting resource efficiency or scalability.通过结合长度分桶、连续批处理、解耦、PDL 以及设备发起的 CUDA 图,vLLM、SGLang 和 NVIDIA Dynamo 等现代推理系统即使在提示长度差异极大的情况下,也能同时实现高吞吐量与低时延。而且它们在做到这一点的同时不影响资源效率或可扩展性。
Memory management for the KV cache. Because decoding involves attending to the entire sequence seen so far—including previously decoded tokens—KV cache memory is a critical resource for decode workers. Each sequence stores key and value tensors for each transformer layer—and each past token. Figure 17-5 shows an example KV cache being shared across different requests.KV 缓存的内存管理。 由于解码需要关注到目前为止已见到的整个序列——包括此前已解码的 token——因此 KV 缓存内存是解码工作节点(decode worker)的关键资源。每个序列都会为每个 Transformer 层、每个历史 token 存储键张量和值张量。图 17-5 展示了一个在不同请求之间共享 KV 缓存的示例。
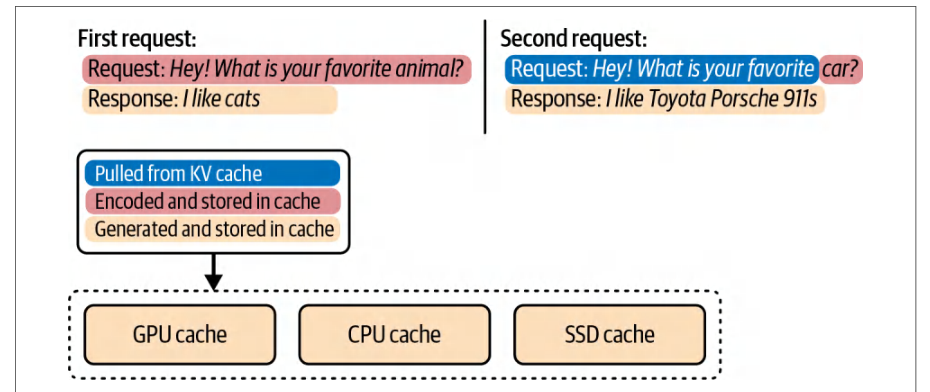
For large models and long sequences, KV memory grows linearly with tokens and depends on attention layout and dtype. A practical estimate is bytes_per_token = 2 x n_layers x n_kv_heads x head_dim x bytes_per_element. (Note: the 2 x accounts for keys and values per token per layer.)对于大模型和长序列,KV 内存随 token 数线性增长,并取决于注意力布局与 dtype。一个实用的估算方式是 bytes_per_token = 2 x n_layers x n_kv_heads x head_dim x bytes_per_element。(注:2 x 对应每层每个 token 的键与值。)
Consider a Llama-class 13B model with 40 layers, 40 attention heads (head dimension is 128), and FP16. For a 4,096-token context with standard multi-headed attention (MHA), the KV size is ~0.819 MB/token or ~3.36 GB total. With FP8 KV, that becomes ~1.68 GB.以 Llama 级别的 13B 模型为例,40 层、40 个注意力头(头维度为 128)、FP16。在标准多头注意力(MHA)下,4,096 token 上下文的 KV 大小约为 0.819 MB/token,总计约 3.36 GB。若使用 FP8 KV,则约为 1.68 GB。
With grouped-query attention (GQA) with 8 query groups (n_kv_heads = 8), the 4,096-token KV is ~0.671 GB at FP16 and ~0.336 GB at FP8. And for multi-query attention (MQA) with 1 kv head, it is ~0.084 GB at FP16.若采用分组查询注意力(GQA)且 n_kv_heads = 8(8 个查询组),4,096 token 的 KV 在 FP16 下约为 0.671 GB,在 FP8 下约为 0.336 GB。而对于只有 1 个 kv 头的多查询注意力(MQA),FP16 下约为 0.084 GB。
A GPU serving many concurrent sequences can quickly approach its memory limits purely due to KV cache storage—in addition to the model weights. As such, make sure your decode workers use such an optimized memory allocator to prevent GPU memory exhaustion when many long sequences are in flight. The following are strategies that decode workers use to manage KV memory efficiently:一个服务大量并发序列的 GPU,仅 KV 缓存存储(还不算模型权重)就可能迅速逼近其内存上限。因此,请确保解码工作节点使用此类优化的显存分配器,以便在大量长序列同时在途时避免 GPU 显存耗尽。以下是解码工作节点用于高效管理 KV 内存的策略:
- Paged GPU memory allocator分页 GPU 显存分配器
- vLLM’s PagedAttention mechanism is a prime example—it partitions the KV cache into fixed-size pages and can swap inactive pages to CPU memory. In addition to vLLM, paged KV memory managers are implemented in SGLang and NVIDIA TensorRT-LLM. NVIDIA Dynamo builds on these techniques. These systems also layer external KV tiers using DRAM and NVMe. And they can schedule recomputation versus I/O to balance bandwidth. This is common in projects like LMCache and other similar libraries and runtimes.vLLM 的 PagedAttention 机制就是一个典型例子——它将 KV 缓存划分为固定大小的页,并可将不活跃的页交换到 CPU 内存。除 vLLM 外,SGLang 和 NVIDIA TensorRT-LLM 也实现了分页 KV 内存管理器。NVIDIA Dynamo 在这些技术之上构建。这些系统还使用 DRAM 和 NVMe 构建外部 KV 层级。并且它们可以调度重计算与 I/O 之间的取舍,以平衡带宽。这在 LMCache 及类似库和运行时项目中很常见。
- High-memory GPUs and custom allocators高内存 GPU 与自定义分配器
- Decode servers often use GPUs with large HBM capacity (e.g., Blackwell B200’s 180 GB HBM and Blackwell B300’s 288 GB HBM) to store the KV cache. Additionally, systems like vLLM and NVIDIA TensorRT-LLM use optimized memory managers that allocate KV memory in fixed-size pages to reduce fragmentation, enable efficient prefix reuse across requests, and manage hundreds of sequences of varying lengths. This efficiently shares memory without causing excessive fragmentation and waste.解码服务器通常使用具备大容量 HBM 的 GPU(例如 Blackwell B200 的 180 GB HBM 和 Blackwell B300 的 288 GB HBM)来存储 KV 缓存。此外,vLLM 和 NVIDIA TensorRT-LLM 等系统使用优化的显存管理器,以固定大小的页分配 KV 显存,从而减少碎片、实现跨请求的高效前缀复用,并管理数百个长度各异的序列。这样可以在不产生过多碎片和浪费的情况下高效共享内存。
- KV cache offloading (e.g., paging out)KV 缓存卸载(例如分页换出)
- When GPU memory fills up, the decode workers can offload older KV blocks to CPU RAM or colder storage such as NVMe. For instance, if a sequence generates 1,000 tokens, but not all of them are currently needed right away, some earlier tokens’ KV can be moved to host CPU memory.当 GPU 显存被占满时,解码工作节点可以把较旧的 KV 块卸载到 CPU 内存或 NVMe 等更冷的存储介质。例如,如果一个序列生成了 1,000 个 token,但并非所有这些 token 当前都立即需要,那么可以把一些较早 token 的 KV 移到主机 CPU 内存中。
When they’re needed, they can be brought back into GPU memory on demand. Offloading introduces a bit of a latency penalty when the tokens are needed for attention, so you should be careful when using offload. Decode servers often try to prefetch or overlap data transfer so that paging in KV data won’t impact generation as much.当需要用到它们时,可以按需把它们重新取回 GPU 显存。当这些 token 需要参与注意力计算时,卸载会带来一定的时延代价,因此使用卸载时应格外谨慎。解码服务器通常会尝试预取或重叠数据传输,从而让 KV 数据的分页调入对生成过程的影响尽可能小。
- Context limits and compression上下文长度限制与压缩
- Some deployments impose a hard limit on the number of decoded tokens, or output sequence length. This is an application-level trade-off that caps the KV cache size and avoids unbounded growth. KV compression can also reduce KV memory required per token. For instance, storing KV at lower precision (FP16, FP8, INT8) can greatly reduce the memory usage.有些部署会对解码 token 的数量或输出序列长度施加硬性限制。这是一种应用层面的权衡,它限定了 KV 缓存的大小,避免其无界增长。KV 压缩也可以降低每个 token 所需的 KV 内存。例如,以更低的精度(FP16、FP8、INT8)存储 KV 可以大幅减少显存占用。
Another example is using multiquery attention (MQA), in which heads share a KV vector per token. This reduces the KV size proportional to the number of heads. This is a model architecture change that directly lowers the KV footprint. Grouped query attention (GQA) and DeepSeek’s Multi-Latent Attention (MLA) also help reduce the size of the KV cache.另一个例子是使用多查询注意力(MQA),其中各注意力头对每个 token 共享一个 KV 向量。这使 KV 大小按注意力头数量成比例地减小。这是一种直接降低 KV 占用量的模型架构改动。分组查询注意力(GQA)和 DeepSeek 的多潜在注意力(MLA)同样有助于减小 KV 缓存的大小。
| Routing strategy路由策略 | Description描述 |
|---|---|
| Round robin轮询 | Routes to each node one by one逐个路由到每个节点 |
| Least requests最少请求 | Routes to the worker with the fewest active requests路由到活跃请求最少的工作节点 |
| Prefix aware前缀感知 | Uses the request’s prefix to select a worker使用请求的前缀来选择工作节点 |
| KV awareKV 感知 | Routes to the worker whose KV cache best matches the request路由到 KV 缓存与请求最匹配的工作节点 |
- Memory hierarchy in disaggregation解耦架构中的内存层级
- Another advantage of the disaggregated design is that the decode cluster’s GPU memory is fully dedicated to storing model weights + KV cache. It’s also not trying to handle large prompt prefill computations, which, on a monolithic serving system, would consume a lot of extra memory temporarily during prefill.解耦设计的另一个优势在于,解码集群的 GPU 显存完全专用于存储模型权重 + KV 缓存。它也不必处理大规模的提示词预填充计算——在单体服务系统中,这类计算会在预填充期间临时占用大量额外显存。
Each decode GPU typically loads the full model weights—unless using model parallelism—and then uses the remaining memory for KV storage. For instance, if model weights take 70 GB of a GPU’s memory and the GPU has 180 GB total, about 122 GB is left for KV.每块解码 GPU 通常加载完整的模型权重(除非采用模型并行),然后将剩余内存用于 KV 存储。例如,若模型权重占用某块 GPU 显存中的 70 GB,而该 GPU 总内存为 180 GB,则约 122 GB 可用于 KV。
This directly impacts roughly how many tokens × sequences can be in-flight on that GPU. Disaggregation doesn’t eliminate KV memory issues, but by separating roles, you can choose decode node types that optimize for memory capacity and memory bandwidth.这直接决定了该 GPU 上大致能有多少 token × 序列同时在处理中。解耦并不会消除 KV 内存问题,但通过分离角色,你可以选择针对显存容量和显存带宽进行优化的解码节点类型。
With the cluster configured this way, you need to decide when to offload a prefill to the prefill worker pool—or when to do it locally on the decode worker. Offloading has overhead, including queueing delays, network transfers, etc. As such, it should be used only when it will actually help latency. The decision is made by a routing policy, described next.集群按此方式配置后,你需要决定何时将预填充卸载到预填充工作节点池,何时在解码工作节点本地完成。卸载存在开销,包括排队延迟、网络传输等。因此,只有在确实有助于改善时延时才应使用。该决策由路由策略做出,下文将予以介绍。
解耦路由与调度策略
Disaggregated Routing and Scheduling Policies
Not every request needs to be offloaded to a prefill worker. In fact, doing so when unnecessary would add overhead and not a lot of benefit. As such, a disaggregated inference system uses a routing policy to conditionally disaggregate and use the remote prefill path only when it is likely to help. Table 17-1 shows a high-level summary of routing strategies, including KV-aware and prefix-aware routing.并非每个请求都需要卸载到预填充工作节点。事实上,在不必要时这样做只会增加开销,收益甚微。因此,解耦推理系统使用路由策略,仅在可能带来收益时才有条件地解耦并走远程预填充路径。表 17-1 给出了路由策略的高层概览,包括 KV 感知路由和前缀感知路由。
| Factor因素 | Description描述 | Effect on routing decision对路由决策的影响 |
|---|---|---|
| Prompt提示词 | Number of tokens in the input输入中的 token 数量 | Long prompts ⇒ more compute → offload prefill if length exceeds长提示词 ⇒ 更多计算 → 若长度超过则卸载预填充 |
| length长度 | prompt (after any prefix caching).提示词(经过任何前缀缓存后)。 | threshold. Short prompts ⇒ do locally.阈值。短提示词 ⇒ 本地执行。 |
| Prefix cache前缀缓存 | Extent of prompt already in the提示词已有多少位于 | Large prefix cache hit (most of prompt cached) ⇒ prefill is effectively大量前缀缓存命中(大部分提示词已缓存)⇒ 预填充实际上 |
| hit命中 | decode worker’s KV cache (from previous requests).解码工作节点的 KV 缓存(来自之前的请求)。 | shorter and more memory bound → do locally. If no cache hits (all new tokens) ⇒ heavy compute → offload likely beneficial.更短且更受内存限制 → 本地执行。若无缓存命中(全部为新 token)⇒ 计算繁重 → 卸载可能有益。 |
| Prefill预填充 | Number of pending tasks in the待处理任务数量在 | If the queue is long (prefill workers lagging) ⇒ avoid offloading new若队列很长(预填充工作节点滞后)⇒ 避免卸载新的 |
| queue队列 | global prefill queue (how busy全局预填充队列(有多忙 | requests (do locally). If the queue is empty or light ⇒ prefill workers have请求(本地执行)。如果队列为空或负载较轻 ⇒ 预填充工作进程有 |
| length长度 | the prefill workers are).预填充工作进程有多忙)。 | capacity → offload if other conditions are met.容量 → 如果满足其他条件则卸载。 |
| Decode解码 | Current load on the local decode本地解码上的当前负载 | If the decode GPU is busy with many decode streams, offloading helps如果解码 GPU 忙于许多解码流,卸载有助于 |
| worker load工作进程负载 | worker (ongoing decode tasks, etc.).工作进程(正在进行的解码任务等)。 | parallelism (freeing up the GPU from heavy compute). If decode is mostly idle and the prefill queue is backed up, do local prefill to use available capacity.并行度(将 GPU 从繁重计算中释放出来)。如果解码大多空闲且预填充队列积压,则执行本地预填充以利用可用容量。 |
| Latency SLO时延 SLO | Priority or tightness of the的优先级或紧迫程度 | Urgent low-latency requirement ⇒ might offload to ensure prompt is紧急的低时延需求 ⇒ 可能卸载以确保提示词 |
| urgency紧急程度 | request’s latency requirement.请求的时延要求。 | computed ASAP (especially if local decode is busy). Relaxed requirements might just run locally to save resources (see “QoS and early rejection policies” on page 792).尽快完成计算(尤其是在本地解码繁忙时)。较宽松的要求则可能直接在本地运行以节省资源(参见第 792 页的“QoS 与提前拒绝策略”)。 |
The disaggregated router runs for each new request on the decode worker that initially receives the request. And it makes a quick decision to either prefill locally or prefill remotely on the prefill worker pool.解耦路由器在最初接收请求的解码工作节点上为每个新请求运行,并快速做出决策:是在本地执行预填充,还是在预填充工作节点池上远程执行预填充。
路由因素
Routing factors
The decision to offload prefill to the prefill worker pool can be based on several factors related to the request and the system state. Common routing factors include current queue lengths, GPU memory availability, and even specialization since certain GPUs are better for certain models or prompt types.将预填充卸载到预填充工作节点池的决策,可以基于与请求和系统状态相关的多个因素。常见的路由因素包括当前队列长度、GPU 显存可用量,甚至还包括专用化程度,因为某些 GPU 更适合特定模型或特定类型的提示词。
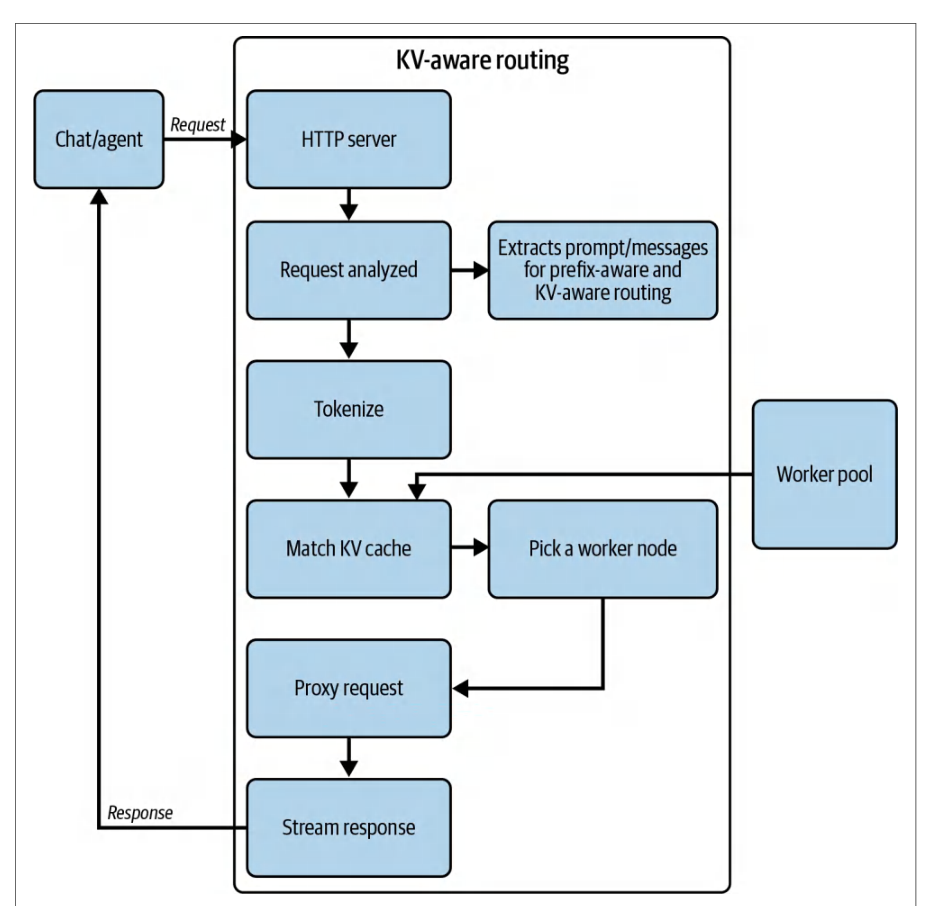
Advanced routers like vLLM’s KV cache-aware router also consider cache locality. They will route a request to a decode worker that already holds some of its prefix in cache. Figure 17-6 shows how an example KV-cache-aware router moves a request through the system based on data received from KV cache events emitted by the workers.像 vLLM 的 KV 缓存感知路由器这样的高级路由器还会考虑缓存局部性。它们会把请求路由到已在其缓存中持有该请求部分前缀的解码工作节点。图 17-6 展示了一个示例 KV 缓存感知路由器如何根据各工作节点发出的 KV 缓存事件所提供的数据,在系统中移动请求。
The goal is to route in a way that maximizes cache hits and balances load. Table 17-2 summarizes some key factors that influence the routing decision in a typical disaggregated design.目标是以最大化缓存命中并均衡负载的方式进行路由。表 17-2 汇总了典型解耦设计中影响路由决策的一些关键因素。
These factors will prefer to offload only requests that will benefit from the remote execution. These include long and compute-heavy prompts. Meanwhile, short and cache-hitting prompts are handled locally to minimize overhead. The thresholds are tunable. Each factor in Table 17-2 addresses a particular trade-off, as described next:这些因素会倾向于只卸载那些能从远程执行中获益的请求。这类请求包括长且计算密集的提示词。与此同时,短小且能命中缓存的提示词则在本地处理,以尽量降低开销。这些阈值是可调的。表 17-2 中的每个因素都对应一项特定的权衡,具体如下所述:
- Prompt length提示词长度
- We don’t want to waste time offloading trivial prompts. The overhead of remote execution, even if small, isn’t worth it for a five-token prompt, for instance, since the decode GPU can handle that quickly on its own. Offloading is reserved for heavy prompts in which the decode GPU would otherwise be tied up for a long time.我们不希望把时间浪费在卸载琐碎的提示词上。例如,对于一个只有五个 token 的提示词,远程执行的开销即使很小也不值得,因为解码 GPU 自己就能很快处理完。卸载只保留给那些重负载提示词,否则解码 GPU 会被长时间占用。
- Prefix cache前缀缓存
- Modern inference systems often implement a KV cache that can store the KV pairs for previously seen context, such as earlier turns of a conversation or repeated boilerplate system prompts. If a new request’s prompt has a long prefix that overlaps with a prompt that has already been processed, the decode worker may already have that prefix’s KV data in memory. In that case, it needs to compute only the remainder of the prompt for the cache-miss portion.现代推理系统通常会实现 KV 缓存,用于存储此前已见上下文的 KV 对,例如对话的先前轮次或重复出现的样板系统提示词。如果新请求的提示词具有与已处理过的提示词相重叠的长前缀,解码工作节点可能已在内存中持有该前缀的 KV 数据。此时,它只需为缓存未命中的部分计算提示词的剩余内容。
If the remaining part is short, the benefit of offloading is reduced. Also, if the entire prompt is already cached due to a complete prefix hit, then no prefill computation is needed at all. The decode can proceed immediately using the cached state. The router takes this into account by effectively considering effective prompt length = (prompt_length – prefix_cached_length).如果剩余部分很短,卸载带来的收益就会减少。此外,如果由于完全前缀命中而整个提示词都已被缓存,则完全不需要预填充计算。解码可以直接使用缓存状态继续进行。路由器会考虑这一点,实际采用的有效提示词长度为(prompt_length – prefix_cached_length)。
A large prefix hit not only reduces compute needed but also means a lot of KV data would have to be transferred to a prefill worker and back, which is pointless. Hence, such requests are kept local and leverage the cache.大幅前缀命中不仅减少了所需计算量,还意味着大量 KV 数据本需传输到预填充工作节点再传回,这是毫无意义的。因此,此类请求保持在本地并利用缓存。
- Prefill queue length预填充队列长度
- This essentially measures the load of the prefill worker cluster. If the prefill workers are overwhelmed with many tasks waiting, sending yet another task their way could hurt TTFT more than it helps since the request would just sit in the queue. In those cases, decode workers are instructed to temporarily do more work themselves.这实质上衡量的是预填充工作节点集群的负载。如果预填充工作节点被大量等待中的任务压垮,再向它们发送一个任务对 TTFT 的伤害可能大于帮助,因为该请求只会滞留在队列中。在这种情况下,解码工作节点会收到指令,暂时自行承担更多工作。
This creates a natural load-shedding mechanism for the prefill cluster since the system gracefully degrades back toward local computation when the dedicated prefill tier is at capacity. When the prefill queue is short again and workers are caught up, offloading resumes for long prompts. This dynamic equilibrium is one reason disaggregation performs well across a variety of conditions.这为预填充集群形成了一种自然的减载机制:当专用预填充层达到容量上限时,系统会平滑地退化回本地计算。当预填充队列再次变短、工作节点跟上进度后,长提示词的卸载便会恢复。这种动态平衡是解耦在多种条件下表现良好的原因之一。
- Decode worker load解码工作节点负载
- While not always explicitly coded as such, the router inherently helps distribute the workload. If a decode worker is already busy decoding many streams, it can still offload new incoming prompts. This is good, as, otherwise, that GPU would have to juggle heavy compute and decoding concurrently—possibly slowing down both.虽然并不总是显式地如此编码,但路由器本身就有助于分散工作负载。如果某个解码工作节点已经在解码许多流,它仍然可以卸载新到达的提示词。这是好事,否则该 GPU 将不得不同时兼顾繁重计算与解码——可能使两者都变慢。
Conversely, if decode GPUs are free because the system is very lightly loaded, they could handle longer prefills locally. In practice, an idle decode GPU is also likely to have an empty prefill queue since the overall load is low. The conditions already cover this case indirectly. But some implementations might include a direct check on local GPU utilization to decide whether prefill-offload is needed or not.反之,如果由于系统负载很轻而解码 GPU 空闲,它们可以在本地处理更长的预填充。在实践中,空闲的解码 GPU 也很可能拥有空的预填充队列,因为整体负载很低。前述条件已间接覆盖了这种情况。但某些实现可能会直接检查本地 GPU 利用率,以决定是否需要进行预填充卸载。
- Latency SLO and priority时延 SLO 与优先级
- In systems with mixed SLAs or priority classes, the routing can be modified to improve QoS. For a high-priority request that must have the fastest TTFT, one might bypass queue checks and immediately offload so that it starts computing immediately—even if the decode GPU is free. In this case, the system can reserve that decode worker for a different high-priority decode task.在具有混合 SLA 或优先级类别的系统中,可以修改路由以改善 QoS。对于必须获得最快 TTFT 的高优先级请求,可以绕过队列检查并立即卸载,使其立刻开始计算——即使解码 GPU 空闲也是如此。在这种情况下,系统可以将该解码工作节点保留给另一个高优先级解码任务。
Alternatively, if a request is low priority, the system might choose not to use prefill cluster resources at all. Instead, it will just let it happen locally on the decode worker—or even delay it. We revisit priority request handling in “QoS and early rejection policies” on page 792, but just know that the basic router can be extended with these types of considerations.或者,如果请求是低优先级的,系统可能选择完全不使用预填充集群资源。相反,它只会让预填充在解码工作节点上本地进行——甚至将其延迟。我们会在第 792 页的“QoS 与提前拒绝策略”中重新讨论优先级请求的处理,但只需知道,基本路由器可以扩展以纳入这类考量。
The specific threshold values and weights used in the routing policy should be determined empirically. For instance, you might find that prompts under 50 tokens are faster to compute locally on a given type of GPU (e.g., Blackwell B200), whereas larger prompts benefit from offload.路由策略中使用的具体阈值和权重应通过实验确定。例如,你可能会发现,在给定类型的 GPU(如 Blackwell B200)上,少于 50 个 token 的提示词在本地计算更快,而更大的提示词则受益于卸载。
As new hardware is released, the thresholds might change since newer GPUs have higher FLOPS and more memory bandwidth. As such, the break-even prompt length for offload might become a bit higher since a single B200 can handle more tokens fully on the decode worker, for instance.随着新硬件的发布,这些阈值可能会发生变化,因为更新的 GPU 具有更高的 FLOPS 和更大的显存带宽。因此,卸载的盈亏平衡提示长度可能会略微提高,例如,单个 B200 就能在解码工作节点(decode worker)上完整处理更多 token。
PREFILL_
The outcome of effective routing is that the system achieves the best of both worlds. Short prompts are faster TTFT due to running locally—and they incur no extra overhead. Longer prompts get the benefits of parallelism since prefill and decode happen in parallel on different GPUs. Also, the prefill worker pool is utilized only when needed—and it avoids getting flooded when it can’t keep up.有效路由的结果是系统兼得两者之长。短提示由于在本地运行,TTFT 更快,而且不产生额外开销。较长的提示则受益于并行性,因为预填充和解码在不同的 GPU 上并行进行。此外,预填充工作节点池只在需要时才被使用,从而避免在其无法跟上时被请求淹没。
This type of conditional strategy was crucial in the DistServe prototype and in modern inference servers like vLLM and Dynamo. This allows them to improve useful throughput under latency constraints (goodput) rather than just raw throughput.这种条件式策略在 DistServe 原型以及 vLLM、Dynamo 等现代推理服务器中至关重要。它使这些系统能够在时延约束下提升有用吞吐量(有效吞吐,goodput),而不只是原始吞吐量。
代码中的动态路由策略示例
Example dynamic routing policy in code
In practice, the routing policy can be implemented as a simple conditional check. The code here shows a simplified version of this routing logic:在实践中,路由策略可以实现为一个简单的条件判断。下面的代码展示了该路由逻辑的简化版本:
# 运行在解码 worker 上的卸载预填充决策
# (针对 B200/B300 调优)
def should_offload_prefill(prompt_length: int,
# Offload prefill decision running on a decode worker
# (B200/B300 tuned)
def should_offload_prefill(prompt_length: int,
                           prefix_cached_length: int,
                           prefill_queue_size: int,
                           decode_active_reqs: int,
                           ttft_slo_ms: int = 500) -> bool:
    # 前缀 KV 命中后的有效预填充
    eff_len = max(0, prompt_length - prefix_cached_length)
    # 可调参数(保留在配置中;此处仅为清晰展示)
    PREFILL_LENGTH_THRESHOLD = 256  # 参见 split_policy.prompt_length_threshold
    PREFILL_QUEUE_MAX        = 10   # 参见 autoscale/prefill 队列长度指引
    DECODE_LOAD_THRESHOLD    = 8    # 活跃的解码流
    long_prefill = (eff_len >= PREFILL_LENGTH_THRESHOLD)
    prefill_available = (prefill_queue_size < PREFILL_QUEUE_MAX)
    # 当预填充计算密集时优先选择远程
    # 且资源池有余量。
    if long_prefill and prefill_available:
        return True
    # 若本地解码繁忙且预填充长度中等,
    # 通过卸载释放解码资源。
    if decode_active_reqs >= DECODE_LOAD_THRESHOLD and eff_len >= 64:
        return True
    # 否则将预填充保留在本地
    # (开销更低 / 缓存局部性更好)。
    return False
                           prefix_cached_length: int,
                           prefill_queue_size: int,
                           decode_active_reqs: int,
                           ttft_slo_ms: int = 500) -> bool:
    # Effective prefill after prefix KV hits
    eff_len = max(0, prompt_length - prefix_cached_length)
    # Tunables (kept in config; shown here for clarity)
    PREFILL_LENGTH_THRESHOLD = 256  # see split_policy.prompt_length_threshold
    PREFILL_QUEUE_MAX        = 10   # see autoscale/prefill queue-length guidance
    DECODE_LOAD_THRESHOLD    = 8    # active decode streams
    long_prefill = (eff_len >= PREFILL_LENGTH_THRESHOLD)
    prefill_available = (prefill_queue_size < PREFILL_QUEUE_MAX)
    # Prefer remote when prefill is compute-heavy
    # and the pool has capacity.
    if long_prefill and prefill_available:
        return True
    # If local decode is busy and prefill is moderately long,
    # free decode via offload.
    if decode_active_reqs >= DECODE_LOAD_THRESHOLD and eff_len >= 64:
        return True
    # Otherwise keep prefill local
    # (lower overhead / better cache locality).
    return False
In this pseudo-code, PREFILL_LENGTH_THRESHOLD is a system-tuned parameter, such as 50 or 100 tokens, that defines what counts as a “long” prompt. PREFILL_QUEUE_MAX is a threshold beyond which the prefill worker pool is considered saturated, specifically if there are too many outstanding tasks.在这段伪代码中,PREFILL_LENGTH_THRESHOLD 是一个由系统调优的参数,例如 50 或 100 个 token,用于定义什么样的提示算作“长”提示。PREFILL_QUEUE_MAX 是一个阈值,超过该阈值即认为预填充工作节点池已饱和,具体来说就是未完成的任务过多时。
The decode worker calls should_offload_prefill() as soon as it receives a new request. If the function returns True, the decode worker will package the prompt into a message and push it onto the global prefill task queue. It then performs other work while waiting for the KV cache result to return.解码工作节点一收到新请求就调用 should_offload_prefill()。如果该函数返回 True,解码工作节点会把提示打包成一条消息,推送到全局预填充任务队列。随后它在等待 KV 缓存结果返回的同时执行其他工作。
If should_offload_prefill() returns False, the decode worker immediately performs the prefill computation itself. This way, if prefill workers start lagging behind, new requests will fall back to local computation to avoid queuing delays. It’s a form of adaptive routing that balances the load between decode and prefill pools.如果 should_offload_prefill() 返回 False,解码工作节点会立即自行执行预填充计算。这样一来,如果预填充工作节点开始落后,新请求就会回退到本地计算,以避免排队时延。这是一种自适应路由,用于在解码池和预填充池之间平衡负载。
动态路由策略配置示例
Example dynamic routing policy configuration
In a production deployment, the routing policy should be configured through a file or UI rather than hard-coded. For instance, NVIDIA’s Dynamo allows specifying complex routing and autoscaling rules in a JSON or YAML config. Here is a simplified example of a Dynamo Planner JSON that encapsulates some of the policy logic:在生产部署中,路由策略应当通过文件或 UI 配置,而不是硬编码。例如,NVIDIA 的 Dynamo 允许在 JSON 或 YAML 配置中指定复杂的路由和自动扩缩容规则。下面是一个简化的 Dynamo Planner JSON 示例,其中封装了部分策略逻辑:
model: ...
split_policy:
  prompt_length_threshold: 256
  prefix_cache_weight: 10.0
  queue_length_weight: 1.5
  decode_load_weight: 0.5
  enable_hotspot_prevention: true
cache:
  reuse_prefix: true
  min_cache_hit_ratio: 0.75
autoscale:
  prefill:
    min_replicas: 4
    max_replicas: 12
    scale_up:   { queue_length: 8,  gpu_utilization: 80 }
    scale_down: { queue_length: 2,  gpu_utilization: 40 }
  decode:
    min_replicas: 8
    max_replicas: 24
    scale_up:   { queue_length: 16, kv_cache_usage: 75 }
    scale_down: { queue_length: 4,  kv_cache_usage: 30 }
qos:
  enable_early_rejection: true
  low_priority_threshold_ms: 500
  reject_on_slo_violation: true
Here, the configuration defines a split_policy with a prompt_length_threshold of 256 tokens. It also specifies weights for factors like cache hit, queue length, decode load, and others. It also configures autoscale behavior for both prefill and decode roles, including how to scale up or down based on queue lengths, GPU utilization, and KV cache usage.这里的配置定义了一个 split_policy,其 prompt_length_threshold 为 256 个 token。它还指定了缓存命中、队列长度、解码负载等因素的权重。此外,它为预填充和解码两种角色都配置了 autoscale 行为,包括如何根据队列长度、GPU 利用率和 KV 缓存使用量进行扩容或缩容。
In addition, it can apply some QoS rules like early rejection and tune what threshold to consider a request “slow.” In practice, Dynamo’s router reads this JSON at startup—or fetches it dynamically—to dictate each routing decision for requests spread across the entire cluster.此外,它还可以应用一些 QoS 规则,例如提前拒绝,并调整判定请求“缓慢”的阈值。在实践中,Dynamo 的路由器在启动时读取该 JSON——或动态获取它——以此决定分布在整个集群中的每个请求的路由决策。
容量感知路由
Capacity-aware routing
As mentioned in the previous section, NVIDIA Dynamo supports dynamic routing policy. An implementation of this dynamic routing capability is Dynamo GPU Planner. The planner uses metrics like TTFT, TPOT, and the estimated cost of KV cache transfer to decide to modify routing—or even reallocate/scale phase-specific GPUs— to reduce bottlenecks and adapt to shifts in the workload. This allows the system to maintain high performance during heavy surges in demand, as shown in Figure 17-7.如上一节所述,NVIDIA Dynamo 支持动态路由策略。Dynamo GPU Planner 就是这种动态路由能力的一种实现。该规划器利用 TTFT、TPOT 以及 KV 缓存传输的预估成本等指标,决定修改路由——甚至重新分配/扩缩容各阶段专用的 GPU——以缓解瓶颈并适应工作负载的变化。这使系统能够在需求激增时仍保持高性能,如图 17-7 所示。
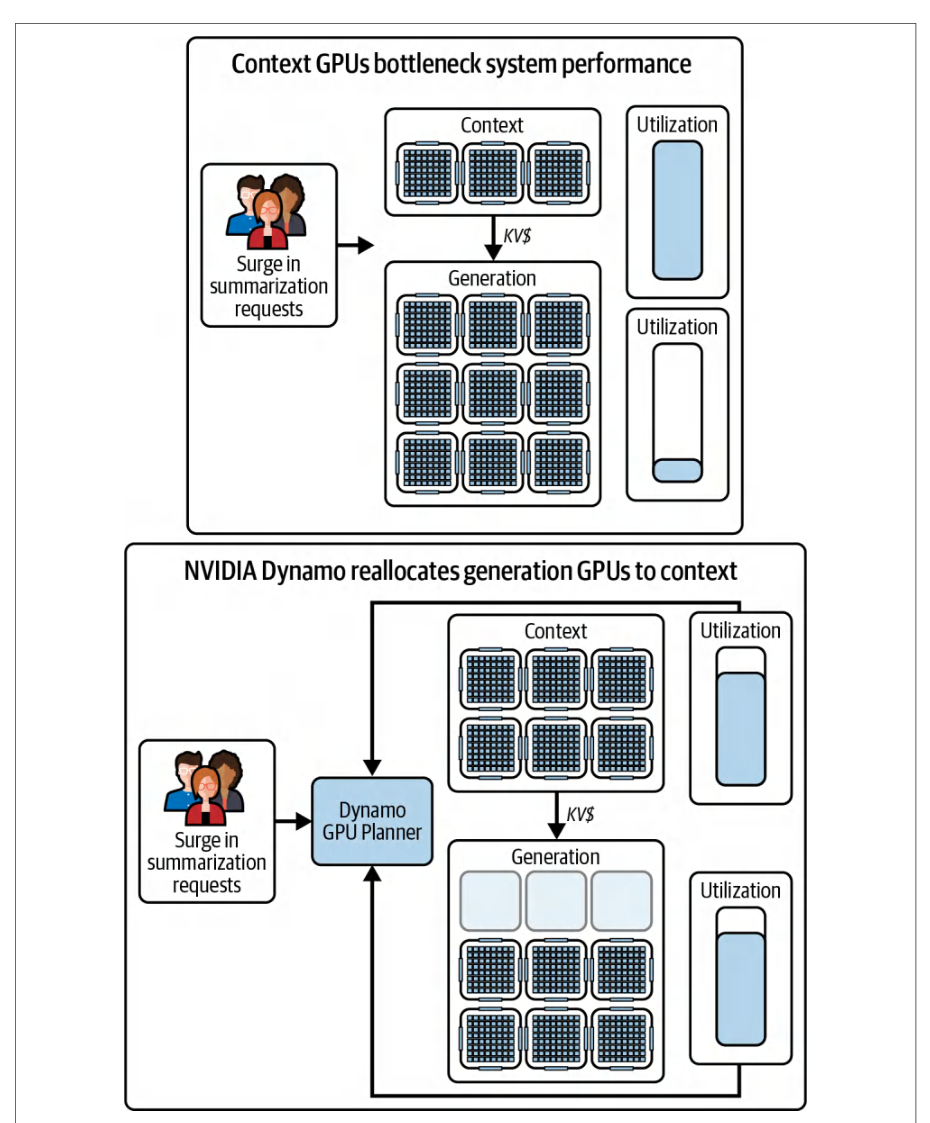
Here, Dynamo’s Planner chooses to shift more GPUs to the prefill (context) phase because of an influx of large summarization prompts that require a heavy amount of prefill (large inputs) relative to decode (small summary outputs).在这里,由于大量摘要类提示涌入,这些请求相对于解码(简短的摘要输出)需要大量的预填充(大输入),因此 Dynamo 的 Planner 选择将更多 GPU 调配到预填充(上下文)阶段。
In contrast, if there is an influx of reasoning requests, the Planner can choose to reallocate GPUs to the decode phase since reasoning requests generate a lot of output tokens relative to the number of input tokens. In other cases, the Planner might choose to handle the request in a traditional monolithic fashion in which the prefill and decode happen on the same GPU worker node.相反,如果涌入的是推理类请求,Planner 可以选择将 GPU 重新分配到解码阶段,因为推理请求相对于输入 token 数量会产生大量输出 token。在其他情况下,Planner 可能选择以传统的单体方式处理请求,即预填充与解码在同一台 GPU worker 节点上完成。
In short, a component like NVIDIA’s Dynamo Planner can automate this decision process by constantly monitoring real-time metrics and comparing them to application-level SLOs like TTFT and TPOT latencies. Using this information, Dynamo Planner can dynamically determine whether to serve a request with full disaggregation, no disaggregation, or somewhere in between with more or fewer GPU resources allocated to each prefill/decode phase. The resulting adaptive system optimizes resource utilization across prefill and decode workloads—and meets aggressive performance targets.简而言之,像 NVIDIA 的 Dynamo Planner 这样的组件可以通过持续监控实时指标,并将其与应用级 SLO(如 TTFT 和 TPOT 时延)进行比较,来自动化这一决策过程。利用这些信息,Dynamo Planner 可以动态决定是以完全解耦、非解耦,还是介于两者之间的方式服务请求,并为每个预填充/解码阶段分配或多或少的 GPU 资源。由此形成的自适应系统可优化预填充与解码工作负载的资源利用率——并达成激进的性能目标。
时延感知路由
Latency-aware routing
The inference router can go beyond a simple threshold rule and use a more sophisticated latency score model to pick the best worker for each request. For instance, it might continuously compute a latency cost for each potential worker based on real-time metrics like how busy it is, how much memory is used, whether it has relevant cache, etc. It then sends the request to the worker with the lowest latency cost, for instance.推理路由器可以超越简单的阈值规则,使用更精细的时延评分模型为每个请求挑选最佳 worker。例如,它可以基于实时指标(如该 worker 有多繁忙、使用了多少内存、是否持有相关缓存等)持续计算每个候选 worker 的时延成本。然后,它把请求发送给时延成本最低的 worker。
Let’s assume that the worker with the lowest latency cost is the freest and most preferable worker. A simple latency cost function might be as shown here:假设时延成本最低的 worker 就是最空闲、最合适的 worker。一个简单的时延成本函数可能如下所示:
# 优先选择成本更低者
latency_cost = 0.7 * (occupancy_percent)
  + 0.3 * (active_req_count)
# Lower cost is preferable
latency_cost = 0.7 * (occupancy_percent)
  + 0.3 * (active_req_count)
This particular latency cost function more heavily weighs the occupancy of the GPU. This correlates to how much work the GPU is currently doing. Secondarily, it correlates to how many requests are currently in flight on that engine. A new request would be sent to the engine with the lowest latency cost.这个特定的时延成本函数对 GPU 占用率赋予更高的权重。占用率与 GPU 当前正在承担的工作量相关。其次,它与该引擎上当前正在处理的请求数相关。新请求会被发送到延迟成本最低的引擎。
The weights, 0.7 and 0.3 in this example, could be tuned based on empirical data. If KV memory usage is found to be a big predictor of slowdowns due to lots of data to swap or higher memory bandwidth usage, you would want to weigh it more heavily.本例中的权重 0.7 和 0.3 可以基于经验数据进行调整。如果发现 KV 显存使用量是导致变慢的重要预测因素(因为需要换入换出大量数据或显存带宽占用更高),就应当赋予它更高的权重。
A more advanced routing policy might include additional factors. For example, you can incorporate some of the following into your latency cost function:更高级的路由策略可能会纳入更多因素。例如,你可以将以下部分因素纳入时延成本函数:
| Factor因素 | Interpretation含义 | Impact on latency cost对时延成本的影响 |
|---|---|---|
| KV occupancy (%)KV 占用率(%) | Higher = more memory pressure越高 = 显存压力越大 | +3+3 |
| (occupancy_percent)(occupancy_percent) | ||
| Active requests count活跃请求数 | More in flight = potential queuing在途请求越多 = 越可能排队 | +1+1 |
| (active_req_count)(active_req_count) | ||
| KV cache matchKV 缓存匹配 | Engine already has the needed prefix KV引擎已具备所需的前缀 KV | –10 (large negative)–10(较大负值) |
| (cache_match_flag)(cache_match_flag) | ||
| Memory bandwidth %显存带宽 % | High = memory bus is busy高 = 内存总线繁忙 | +0.5+0.5 |
| (mem_bw_percent)(mem_bw_percent) | ||
| Recent KV use近期 KV 使用 | Prefix was used on this engine recently该引擎最近使用过此前缀 | –1–1 |
| (recent_prefix_flag)(recent_prefix_flag) |
- Exact cache match availability精确缓存匹配可用性
- If a worker already has the needed prefix KV in its cache, a prefix hit, then it can serve the request much faster. In this case, the system can assign a large negative weight to reduce the latency cost and prefer this worker since lower is better in this scenario.如果某个工作进程的缓存中已经存有所需的前缀 KV,即前缀命中(prefix hit),那么它就能更快地服务该请求。在这种情况下,系统可以赋予一个较大的负权重来降低时延代价,并优先选择该工作进程,因为在此场景下数值越低越好。
- KV occupancyKV 占用率
- Higher memory usage means the GPU is busier. In this case, the system assigns a positive weight to increase the latency cost and encourage the router to avoid this worker since lower is more preferable in this scenario.显存占用越高,说明 GPU 越繁忙。在这种情况下,系统会赋予一个正权重来提高时延代价,促使路由器避开该工作进程,因为在此场景下数值越低越可取。
- Active requests活跃请求数
- More parallel requests mean potential context-switching overhead, so this adds to the latency cost, which avoids this worker.并行请求越多,意味着潜在的上下文切换开销越大,因此这会增加时延代价,从而避开该工作进程。
- Memory bandwidth utilization显存带宽利用率
- If a GPU is currently using a lot of its memory bandwidth by handling many long sequences, for instance, adding more work will just slow things down. This would increase the latency cost and discourage the system from choosing this worker.如果某个 GPU 当前因处理大量长序列而占用了大量显存带宽,那么再给它增加工作只会拖慢速度。这会提高时延代价,促使系统不选择该工作进程。
- Recent KV use近期 KV 使用
- If the exact prefix was used recently on a worker engine—and the cache is “warm”—this will likely improve performance since the KV is still in an L2 cache or currently on its way from a prefill worker. In this case, you might include a small negative weight to reduce the latency cost and prefer this worker since it recently saw the prefix.如果某个工作引擎最近使用过该精确前缀——缓存处于“热”状态——那么性能很可能会提升,因为该 KV 仍位于 L2 缓存中,或正从预填充工作进程传输过来。在这种情况下,可以加入一个小的负权重来降低时延代价,并优先选择该工作进程,因为它最近见过该前缀。
Table 17-3 summarizes this type of advanced routing policy configuration. It lists some factors and example costs.表 17-3 总结了这类高级路由策略配置,其中列出了一些因素和示例代价。
Let’s modify the latency cost calculation with these additional metrics. The router now calculates a composite latency cost, as shown here:让我们用这些额外的指标来修改时延成本的计算。路由器现在会计算一个综合时延成本,如下所示:
# 优先选择成本更低者
def latency_cost(occupancy_percent: float,
                 active_reqs: int,
                 cache_match_flag: bool,
                 mem_bw_percent: float,
                 recent_prefix_flag: bool) -> float:
    return (
        3.0 * occupancy_percent
      + 1.0 * active_reqs
      - 10.0 * int(cache_match_flag)
      + 0.5 * mem_bw_percent
      - 1.0 * int(recent_prefix_flag)
    )
# Lower cost is preferable
def latency_cost(occupancy_percent: float,
                 active_reqs: int,
                 cache_match_flag: bool,
                 mem_bw_percent: float,
                 recent_prefix_flag: bool) -> float:
    return (
        3.0 * occupancy_percent
      + 1.0 * active_reqs
      - 10.0 * int(cache_match_flag)
      + 0.5 * mem_bw_percent
      - 1.0 * int(recent_prefix_flag)
    )
Prefill and decode clusters might even use slightly different formulas. For prefill, a cache hit (e.g., prefix already computed) might be even more valuable to factor in, whereas for decoding, memory bandwidth or available KV space might dominate the decision.预填充集群和解码集群甚至可能使用略有不同的公式。对于预填充,缓存命中(例如前缀已经计算过)可能更值得纳入考量;而对于解码,显存带宽或可用 KV 空间可能主导决策。
The router needs telemetry from each worker. This includes metrics like its waiting queue length, KV cache usage, memory utilization, etc., so that the latency cost can be updated continuously.路由器需要来自每个工作节点的遥测数据。这包括其等待队列长度、KV 缓存使用量、显存利用率等指标,以便持续更新时延成本。
The outcome is that the system can dynamically route traffic to where it will have the least impact on latency. Under low load, all workers have low scores, and it may not matter which one is chosen, as any worker can handle the request quickly.结果是,系统可以动态地将流量路由到对时延影响最小的位置。在低负载下,所有工作节点的得分都很低,选择哪一个可能并不重要,因为任何工作节点都能快速处理该请求。
Under high load, however, the router effectively load-balances by sending new work to the workers that are most free. This will also take advantage of data locality (cache hits) to reduce work. This reduces both average and tail latencies because work is less likely to pile up behind busy engines when others are free.然而在高负载下,路由器实际上是在做负载均衡,把新工作发送给最空闲的工作节点。这还会利用数据局部性(缓存命中)来减少工作量。这同时降低了平均时延和尾部时延,因为当其他引擎空闲时,工作不太可能堆积在繁忙的引擎后面。
Earlier, we saw how factoring in cache hits can cause the router to choose a slightly busier server if it has relevant data cached. This results in faster service for that request. The score function quantitatively captures this trade-off.前面我们看到,将缓存命中纳入考量,可能使路由器选择一个稍微更繁忙、但缓存了相关数据的服务器。这会为该请求带来更快的服务。评分函数定量地刻画了这一权衡。
NVIDIA Dynamo performs a similar but opposite calculation in which higher is better. Specifically, it computes a remote prefill score, and if the score exceeds a threshold, it will offload to the prefill worker pool. Here is an example YAML snippet that configures the system to use conditional disaggregation if the calculated score is above a configurable remote_prefill_min_score value:NVIDIA Dynamo 执行类似但方向相反的计算,其中得分越高越好。具体来说,它会计算一个远程预填充得分,如果该得分超过阈值,就会卸载到预填充工作节点池。下面是一个 YAML 片段示例,它将系统配置为:当计算出的得分高于可配置的 remote_prefill_min_score 值时,使用条件式解耦:
disaggregated_router:
  enable: true
  policies:
    - metric: prefill_length   # 前缀缓存命中后的提示词长度
      threshold: 256
disaggregated_router:
  enable: true
  policies:
    - metric: prefill_length   # Prompt length after prefix cache hit
      threshold: 256
      action: prefer_remote    # 若提示词超过 256 个 token,则卸载预填充
      weight: 0.7
    - metric: prefill_queue_depth  # 排队等待预填充工作节点的请求
      threshold: 10
      action: prefer_local     # 若队列长度超过 10,则倾向于本地预填充
      weight: 0.3
  remote_prefill_min_score: 0.5  # 总体阈值决定是否远程预填充
      action: prefer_remote    # if prompt > 256 tokens, offload prefill
      weight: 0.7
    - metric: prefill_queue_depth  # requests queued for prefill workers
      threshold: 10
      action: prefer_local     # if queue > 10, lean toward prefill locally
      weight: 0.3
  remote_prefill_min_score: 0.5  # overall threshold decide remote prefill
Here, the router computes a score based on prefill_length and prefill_ queue_depth. In this case, if the prompt is longer than 256 tokens, it votes to pre fill_remote and offload the prefill. This part of the score calculation carries a weight of 0.7, as configured here.在这里,路由器基于 prefill_length 和 prefill_ queue_depth 计算得分。在这种情况下,如果提示词长度超过 256 个 token,它就投票给 pre fill_remote,将预填充卸载出去。这部分得分计算的权重为 0.7,即此处配置的值。
But if the prefill queue is very deep with more than 10 waiting tasks, as configured here, it will vote to prefill_local with a weight of 0.3, as configured here. If the combined score is greater than remote_prefill_min_score, or 0.5 in this case, Dynamo will offload the prefill. Otherwise, it will keep the prefill local and not offload it.但如果预填充队列非常深、有超过 10 个等待任务(如此处所配置),它就会投票给 prefill_local,权重为 0.3(如此处所配置)。如果综合得分大于 remote_prefill_min_score(在此例中为 0.5),Dynamo 就会卸载预填充。否则,它会将预填充保留在本地,不进行卸载。
多路径推理(竞速)
Multipath inference (racing)
Multipath inference, or sending the same request to two different model sizes or two different routes, is used for high reliability. It’s essentially racing to the fastest result and is often called racing. Google’s and Meta’s production systems are known to race models to reduce tail latency. It’s a costly but effective technique.多路径推理,即把同一个请求发送到两个不同规模的模型或两条不同的路由,用于实现高可靠性。它本质上是竞相取得最快的结果,通常被称为*竞速*。众所周知,Google 和 Meta 的生产系统会对模型进行竞速以降低尾部时延。这是一种成本高昂但有效的技术。
跨工作节点的多分支并行投机解码
Multibranch, parallel speculative decoding across workers
As discussed in Chapter 15, some advanced inference servers support speculative decoding. Remember that speculative decoding generates multiple token branches in parallel, discarding those that are not the most ideal.如第 15 章所述,一些高级推理服务器支持投机解码(speculative decoding)。请记住,投机解码会并行生成多个 token 分支,并丢弃那些不是最理想的分支。
While not a direct part of disaggregation, speculative decoding can be layered on top of the router’s decision-making process. For instance, the system could detect an uncertain speculative decoding branch and send multiple speculative requests to different decode workers in parallel. This would generate multiple speculative next-token branches and mask the unpredictability in token-branch generation. This trades extra compute for lower latency for generations with unpredictable branches.虽然推测解码并非解耦的直接组成部分,但它可以叠加在路由器的决策过程之上。例如,系统可以检测出某个不确定的推测解码分支,并将多个推测请求并行发送到不同的解码工作进程(worker)。这会生成多个推测性的下一 token 分支,从而掩盖 token 分支生成过程中的不可预测性。这以额外的计算换取更低的时延,适用于分支不可预测的生成过程。
If implemented, the router would coordinate these speculative efforts and then merge results. Resource usage would need to be bound to avoid overwhelming the cluster, but multipath inference is worth noting as a potential optimization for ultra-latency-aware inference, at the expense of additional, potentially wasted compute and memory-bandwidth cluster resources.若付诸实现,路由器将协调这些推测工作,然后合并结果。资源使用需要受到约束,以免压垮集群,但多路径推理值得关注,它是一种面向极致时延敏感推理的潜在优化手段,代价是额外且可能被浪费的计算与显存带宽集群资源。
In summary, a latency-aware router ensures each request is sent to the optimal place, considering both current load and potential speedups like cache reuse. It acts as the “brain” of a distributed serving system, working in concert with the lower-level scheduling on each GPU. Together with global scaling and KV caching strategies, it forms a comprehensive approach to maximize goodput and minimize latency.总之,时延感知路由器确保每个请求被发送到最优位置,同时考虑当前负载与缓存复用等潜在加速因素。它充当分布式服务系统的“大脑”,与每块 GPU 上更低层的调度协同工作。结合全局扩缩容与 KV 缓存策略,它构成了一套最大化有效吞吐、最小化时延的完整方法。
QoS 与提前拒绝策略
QoS and early rejection policies
QoS policies prioritize or throttle certain requests to meet latency targets. Early rejection, also called admission control, can refuse low-priority queries when the system is saturated. This way, it preserves resources and SLOs, such as latency for other requests.QoS 策略对特定请求进行优先级排序或限流,以满足时延目标。提前拒绝(early rejection)也称为*准入控制*,可以在系统饱和时拒绝低优先级查询。这样就能保住资源与 SLO,例如其他请求的时延。
Modern systems do this based on a queue time threshold. For example, if a request has sat in queue > X ms, it might be better to reject it or offload it to a lower-tier service rather than let it severely violate the SLO. This kind of QoS guard is increasingly common for mission-critical inference systems.现代系统基于*排队时间阈值*来实现这一点。例如,如果某个请求已在队列中等待超过 X ms,那么与其让它严重违反 SLO,不如拒绝它或将其卸载到更低层级的服务。这类 QoS 防护在关键任务推理系统中越来越常见。
In ultrascale inference systems, QoS mechanisms are needed to maintain tail latency guarantees under heavy load. Even with an optimized disaggregated cluster configuration, if load exceeds capacity, requests will start queuing and latencies will rise.在超大规模推理系统中,需要 QoS 机制来在重负载下维持尾时延保证。即便采用经过优化的解耦集群配置,一旦负载超出容量,请求就会开始排队,时延随之上升。
Rather than allowing latency SLOs to be violated for all requests, a well-designed system will prefer to shed load gracefully. It can do this by rejecting or deferring some requests, especially lower-priority ones, when it is clear that serving them would break the latency guarantees for others.与其让所有请求都违反时延 SLO,设计良好的系统更倾向于优雅地卸载负载。当明确服务某些请求会破坏其他请求的时延保证时,系统可以拒绝或推迟部分请求,尤其是低优先级请求。
This is analogous to how web servers return HTTP 503 “overloaded” errors under extreme load. For LLM serving, we might proactively refuse or down-sample requests if we can’t guarantee serving them in time. Here are a few components to QoS in the context of prefill/decode disaggregation:这类似于 Web 服务器在极端负载下返回 HTTP 503“overloaded”错误。对于 LLM 服务,如果我们无法保证及时服务某些请求,就可以主动拒绝或对请求降采样。以下是预填充/解码解耦场景下 QoS 的几个组成部分:
- Latency SLO tracking时延 SLO 跟踪
- The system should be aware of target TTFT and TPOT goals. For instance, the first token must return within 200 ms 99% of the time. Using internal telemetry, each decode worker can estimate the current TTFT for a new request if it were to be accepted right now and based on current queue lengths, etc. It can similarly estimate TPOT if another decode stream is added.系统应当清楚目标 TTFT 与 TPOT。例如,首个 token 必须在 200 ms 内返回,且 99% 的情况下都要满足。借助内部遥测,每个解码 worker 可以基于当前队列长度等,估算一个新请求若此刻被接受时的当前 TTFT。它同样可以估算再增加一条解码流时的 TPOT。
- Admission control (early rejection)准入控制(提前拒绝)
- Before a request is fully accepted and assigned, the system can perform a check to see if admitting this request will overload the system or violate SLOs. If yes, it can在请求被完全接受并分配之前,系统可以执行检查,判断接纳该请求是否会使系统过载或违反 SLO。如果是,它可以
reject the request immediately with a “server busy, try later” type of response. This is called early rejection. In practice, you can use a global view of system load or simply a single node’s heuristic to trigger the early rejection.立即拒绝该请求,并返回“服务器繁忙,请稍后再试”之类的响应。这称为*提前拒绝*。在实践中,你可以使用系统负载的全局视图,或仅凭单个节点的启发式规则来触发提前拒绝。
OpenAI’s public API, for instance, returns an error if the backlog is too high. It does this rather than violate the latency commitment. Some providers dynamically lower the maximum generation length during peak load. This effectively trades off answer quality for latency.例如,OpenAI 的公共 API 在积压过多时会返回错误。它宁可这样做,也不愿违反时延承诺。一些提供商会在峰值负载期间动态降低最大生成长度。这实际上是用回答质量换取时延。
- Prioritization优先级划分
- Not all requests are equal. Some requests might be high priority if they come from paying customers or critical services, for instance. Others might be lower if they’re from free-tier users or background jobs. The system can incorporate priority into scheduling decisions. For instance, a decode worker’s scheduler could serve high-priority decode tasks first. Or the prefill task queue could be ordered by priority. If things get busy, low-priority tasks may wait longer or be fast-failed in favor of high-priority ones.并非所有请求都是平等的。例如,来自付费客户或关键服务的请求可能是高优先级的;而来自免费层用户或后台作业的请求则可能优先级较低。系统可以把优先级纳入调度决策。例如,解码工作器的调度器可以优先服务高优先级的解码任务;或者预填充任务队列可以按优先级排序。当系统繁忙时,低优先级任务可能等待更久,或者被快速失败,以让位于高优先级任务。
- Graceful degradation优雅降级
- If the system starts to get overloaded, instead of outright rejecting requests, it could degrade service for less important ones. For instance, it might use smaller models for less important requests, truncate their prompts, or cap the number of output tokens. One simple approach is to temporarily reduce the maximum allowed prompt length or output length for lower-tier requests when load is high.如果系统开始过载,它可以对不太重要的请求降级服务,而不是直接拒绝请求。例如,它可以对不太重要的请求使用更小的模型、截断其提示,或限制输出 token 的数量。一种简单的做法是:在高负载时,临时降低较低层级请求所允许的最大提示长度或输出长度。
In the context of disaggregation, one interesting form of graceful degradation is to temporarily disable remote prefilling for lower-priority requests when the system is under stress. Since remote prefill uses additional cluster resources to optimize latency, one could decide that low-priority queries should just do local prefill and use only the decode worker resources. This would produce a slower response for these requests, but it frees up the prefill workers for high-priority queries.在解耦的语境下,一种有趣的优雅降级形式是:当系统承受压力时,临时对低优先级请求禁用远程预填充。由于远程预填充会使用额外的集群资源来优化时延,因此可以决定让低优先级查询只做本地预填充,仅使用解码工作器的资源。这会使这些请求的响应变慢,但能为高优先级查询释放预填充工作器。
For instance, an inference server could tag each request with a priority and have the router ignore the should_offload_prefill logic for low-priority requests when prefill workers are busy with high-priority tasks.例如,推理服务器可以给每个请求打上优先级标签,并让路由器在预填充工作器忙于高优先级任务时,对低优先级请求忽略 should_offload_prefill 逻辑。
Here is an example of an early rejection policy. This could run on each decode worker before processing a requestor even upstream on an LLM gateway:下面是一个提前拒绝策略的示例。它可以在每个解码工作器上、处理请求之前运行,也可以在更上游的 LLM 网关上运行:
# 基于预估时延与优先级进行提前拒绝
from dataclasses import dataclass
class QoSController:
    def __init__(self, ttft_slo_ms: int = 500):
        self.ttft_slo_ms = ttft_slo_ms
    def admit_request(self, priority: str) -> bool:
# Early rejection based on estimated latency and priority
from dataclasses import dataclass
class QoSController:
    def __init__(self, ttft_slo_ms: int = 500):
        self.ttft_slo_ms = ttft_slo_ms
    def admit_request(self, priority: str) -> bool:
        # 队列长度与每请求平均值由指标系统提供
        est_ttft = (get_current_prefill_queue_length()
                    * get_avg_prefill_time_per_req()
                    + get_current_decode_queue_length()
                    * get_avg_decode_time_per_req())
        if est_ttft > self.ttft_slo_ms and priority.lower() == "low":
            # 拒绝低优先级请求以保护 SLO
            return False
        return True
        # The queue length and per-request averages are fed by the metrics system
        est_ttft = (get_current_prefill_queue_length()
                    * get_avg_prefill_time_per_req()
                    + get_current_decode_queue_length()
                    * get_avg_decode_time_per_req())
        if est_ttft > self.ttft_slo_ms and priority.lower() == "low":
            # reject low priority request to protect SLOs
            return False
        return True
Here, we estimate TTFT by looking at how many prefill tasks are queued since each will add some delay, as well as how many decode tasks are ahead. Note that decode tasks typically overlap, so this is a rough estimate. If the estimated TTFT exceeds the allowed maximum, the SLO, then for a low-priority request we reject it and return False from the should_offload_prefill function.这里,我们通过查看队列中有多少预填充任务(每个都会增加一定延迟)以及前面有多少解码任务来估算 TTFT。注意,解码任务通常是重叠的,因此这只是一个粗略估计。如果估算的 TTFT 超过允许的最大值(即 SLO),那么对于低优先级请求,我们就拒绝它,并从 should_offload_prefill 函数返回 False。
For a high-priority request, we still accept it and perhaps sacrifice some other queued work, if necessary. A more sophisticated approach is to preempt a low-priority request that’s already queued to make room for the new high-priority one. This is often implemented by maintaining separate queues per priority level.对于高优先级请求,我们仍然接受它,必要时甚至可以牺牲一些其他已排队的工作。更精细的做法是抢占一个已经排队的低优先级请求,为新的高优先级请求腾出空间。这通常通过为每个优先级维护独立的队列来实现。
Diving a bit deeper, in the preceding example, the avg_prefill_time_per_req() and avg_decode_time_per_req() functions compute the values on the fly using an exponential moving average of the observed per-request prefill and decode durations. They’re normalized by the number of prompt tokens (prefill) and generated tokens (decode). And for inputs of varying length, the engine extrapolates by multiplying these per-token averages by the actual token count for each request.再深入一点,在前面的示例中,avg_prefill_time_per_req() 和 avg_decode_time_per_req() 函数使用观测到的每请求预填充与解码时长的指数移动平均实时计算这些值。它们分别按提示 token 数(预填充)和生成 token 数(解码)进行归一化。对于长度可变的输入,引擎会将每个 token 的平均值乘以每个请求的实际 token 数来进行外推。
The
get_current_prefill_queue_length() and
get_current_decode_queue_
length() functions retrieve the number of pending prefill and decode tasks tracked by the scheduler’s internal queues. These values are maintained by the scheduler.length() 函数获取调度器内部队列所跟踪的待处理预填充任务与解码任务的数量。这些值由调度器维护。
These per-token timing estimates are refreshed in real time using the scheduler loop, which, by default, updates every second from using /metrics endpoint. This captures dynamic workload changes.这些每 token 的耗时估计由调度器循环实时刷新,默认情况下每秒通过 /metrics 端点更新一次。这样就能捕捉工作负载的动态变化。
Early rejection and prioritization make sure that when the system nears saturation, it fails in a controlled manner rather than collapsing. Users with the most important requests continue to get served within the provided SLO. Meanwhile, less important traffic is shed.提前拒绝与优先级划分确保当系统接近饱和时,它以受控的方式失败,而不是崩溃。拥有最重要请求的用户仍能在给定的 SLO 内获得服务。同时,不太重要的流量被丢弃。
In many production deployments, implementing this requires coordination with the LLM gateway layer. Specifically, the gateway might return a specific error code or return a code indicating server-overload back to the client. The key is that the system keeps itself in a state where it can meet the latency promises for the work it does accept, rather than oversubscribing and missing SLOs for everyone.在许多生产部署中,实现这一点需要与 LLM 网关层协调。具体来说,网关可能会向客户端返回特定的错误码,或返回表示服务器过载的代码。关键在于系统要让自身保持在一种状态:对于它所接受的工作能够兑现时延承诺,而不是超额订阅并为所有人错失 SLO。
Another QoS consideration is adaptive generation limits. If the decode phase threatens to run too long and cause a TPOT SLO violation, the system might cut off the generation early. For instance, if a user requested 1,000 tokens but the system is under pressure, it might only allow 200 tokens to be generated and then stop. This leaves resources for other requests. QoS policies prioritize or throttle certain requests to meet latency targets; early rejection can refuse low-priority queries when the system is saturated to preserve SLA for others.另一个 QoS 考量是自适应生成上限。如果解码阶段有运行过久、导致 TPOT SLO 违规的风险,系统可能会提前截断生成。例如,如果用户请求了 1,000 个 token,但系统正承受压力,它可能只允许生成 200 个 token 然后停止。这为其他请求留出了资源。QoS 策略对某些请求进行优先级排序或限流,以满足时延目标;提前拒绝可以在系统饱和时拒绝低优先级查询,从而为其他请求保住 SLA。
In short, disaggregation reduces inherent interference, but load spikes can still overwhelm any fixed capacity. QoS mechanisms complement the disaggregation architecture by making sure it delivers on its latency promises. Early rejection will reject or deprioritize some work to protect the latency of the rest of the requests.简而言之,解耦降低了固有的相互干扰,但负载尖峰仍可能压垮任何固定容量。QoS 机制补充了解耦架构,确保其兑现时延承诺。提前拒绝会拒绝或降低某些工作的优先级,以保护其余请求的时延。
When building ultrascale systems, these policies are as important as core performance optimizations. Without them, a flood of requests could ruin all attempts to improve performance by creating huge queues and slowdowns.在构建超大规模系统时,这些策略与核心性能优化同等重要。没有它们,海量请求会形成巨大的队列并造成速度下降,从而毁掉所有提升性能的努力。
解耦预填充与解码的可扩展性
Scalability of Disaggregated Prefill and Decode
Another aspect of scalability is how performance holds as more nodes are added. The disaggregated approach, by design, scales relatively linearly in many respects. You can add more prefill nodes to handle more prompt throughput. And you can add more decode nodes to handle more token-generation throughput.可扩展性的另一个方面是随着节点增加,性能如何保持。解耦方法在设计上于许多方面都能相对线性地扩展。你可以增加更多预填充节点来处理更高的提示吞吐量,也可以增加更多解码节点来处理更高的 token 生成吞吐量。
The main challenge is balancing them. Adaptive schedulers become even more important as scale increases. This is because the chance of an imbalance, such as a shifting traffic pattern, is much higher in a large system. A dynamic ratio configuration allows clusters to rebalance the ratio of prefill and decode on the fly.主要挑战在于平衡二者。随着规模增大,自适应调度器变得更加重要。这是因为在大型系统中,出现失衡(例如流量模式发生变化)的概率要高得多。动态比例配置允许集群即时重新平衡预填充与解码的比例。
Another consideration is multimodel serving. Disaggregation allows you to share decode capacity between models if their decoding characteristics are similar. For instance, if model A and model B are hosted on the same cluster, you can dedicate some decode workers to handle both types of models. This is particularly useful when hosting different LoRA adapters that reuse the same base model architecture.另一个考量是多模型服务。如果多个模型的解码特性相似,解耦允许它们在彼此之间共享解码容量。例如,如果模型 A 和模型 B 托管在同一集群上,你可以指定一些解码工作节点同时处理这两类模型。当托管复用同一基础模型架构的不同 LoRA 适配器时,这一点尤其有用。
This would give you a super flexible, multitenant, multimodel, prefill-decode-disaggregated inference server system. This is beyond our scope, but just know that disaggregation’s modularity gives you this type of flexibility. You can have a common decode pool for multiple models, each with its own prefill frontend.这将为你带来一个极其灵活、多租户、多模型、预填充-解码解耦的推理服务器系统。这超出了本书的范围,但只需知道解耦的模块化能带来这种灵活性。你可以为多个模型设置一个公共解码池,每个模型各有自己的预填充前端。
Finally, let’s analyze tail latency in very large systems. As ultrascale inference systems scale out to thousands and millions of GPU nodes, it becomes harder and harder to control tail latency. This is because with more servers, the chance that one fails is much higher.最后,让我们分析超大型系统中的尾时延。当超大规模推理系统扩展到数千乃至数百万个 GPU 节点时,控制尾时延变得越来越困难。这是因为服务器越多,其中某一台发生故障的概率就越高。
Disaggregation can help here, too. Isolating prefill tasks on one node and decode tasks on another means a slow node on one side won’t drastically impact tasks on the other side.解耦在这里同样有帮助。将预填充任务隔离在一个节点上、解码任务隔离在另一个节点上,意味着某一侧的慢节点不会对另一侧的任务造成剧烈影响。
Techniques like early rejection, two-level scheduling, and KV cache reuse, discussed in this chapter, can help to mitigate stragglers. For instance, caching large parts of a request’s context means that one slow operation won’t slow down the whole generation as much—because a lot of the computation was already done.本章讨论的提前拒绝、两级调度和 KV 缓存复用等技术有助于缓解掉队者(stragglers)。例如,缓存请求上下文的大部分内容意味着某一次缓慢的操作不会那么严重地拖慢整个生成过程——因为大量计算已经完成。
In summary, disaggregated systems are more robust at scale when properly configured and tuned. These systems can maintain consistent latency even as concurrent requests grow into the millions and billions. By removing one interference factor and adding adaptability, the tail latency distribution improves —or, at least, won’t degrade as fast with load.总之,解耦系统在正确配置和调优后,在大规模场景下更为稳健。即使并发请求增长到数百万乃至数十亿,这些系统也能保持稳定的时延。通过消除一个干扰因素并增加适应性,尾部时延分布得到改善——或者至少不会随负载增长而那么快地恶化。
关键要点
Key Takeaways
The techniques covered in this chapter, from high-speed RDMA transfers of KV cache to dynamic routing algorithms and QoS policies, have proven to be essential components for large-scale production inference workloads. Here are the key takeaways:本章介绍的技术——从 KV 缓存的高速 RDMA 传输到动态路由算法和 QoS 策略——已被证明是大规模生产推理工作负载的关键组成部分。以下是关键要点:
- Eliminate prefill-decode interference to improve latency消除预填充与解码之间的干扰以改善时延
- Separating prefill and decode phases removes interference and head-of-line blocking. This yields tighter latency distributions since long prompts won’t delay shorter prompts. This also lets each phase meet its latency SLO reliably.将预填充与解码阶段分离可消除干扰和队头阻塞。由于长提示词不会延迟较短的提示词,时延分布因此更加集中。这也让每个阶段都能可靠地满足各自的时延 SLO。
- Optimize each phase independently独立优化每个阶段
- Prefill (prompt processing) is compute bound and benefits from maximum parallelism and high FLOPS. It prefers high-compute GPUs and techniques like FP8/FP4 reduced precision to minimize TTFT. Decode (token generation) is memory bound and benefits from high-memory bandwidth GPUs and techniques like continuous batching to maximize throughput per token. Disaggregation allows different hardware and parallelism settings for each phase. A fixed, one-size-fits-all configuration does not allow this.预填充(提示词处理)是计算受限的,受益于最大程度的并行和高 FLOPS。它更适合高算力 GPU 以及 FP8/FP4 低精度等技术,以最小化 TTFT。解码(token 生成)是显存受限的,受益于高显存带宽 GPU 以及连续批处理等技术,以最大化每个 token 的吞吐量。解耦允许为每个阶段设置不同的硬件和并行配置。固定的、一刀切的配置则无法做到这一点。
- Leverage the KV cache充分利用 KV 缓存
- It’s common to use a KV cache to avoid recomputing prompt prefills. A smart router can decide if a new request should be offloaded to a prefill worker or handled directly on the decode worker. The routing policy should consider prompt length, cache hits, and cluster load.使用 KV 缓存来避免重复计算提示词预填充是常见做法。智能路由器可以决定新请求应卸载到预填充工作节点,还是直接在解码工作节点上处理。路由策略应考虑提示词长度、缓存命中和集群负载。
- Route intelligently智能路由
- Modern inference servers like vLLM, SGLang, and NVIDIA Dynamo use a mul-tifactor scoring algorithm to route prefill and decode requests to maximize throughput and maintain adequate latency. Many frameworks also refer to TPOT as* inter-token latency* (ITL) in schedulers and dashboards. It’s recommended to track TTFT (p50/p95/p99) and ITL/TPOT (p50/p95/p99) separately for prefill versus decode nodes. This way, performance regressions are easier to debug during upgrades, for instance. For example, they will skip remote prefill if the prefill servers are saturated or if the prompt is short.vLLM、SGLang 和 NVIDIA Dynamo 等现代推理服务器使用多因子评分算法来路由预填充和解码请求,以最大化吞吐量并维持足够的时延。许多框架在调度器和仪表板中也将 TPOT 称为*inter-token latency*(ITL)。建议分别针对预填充节点和解码节点跟踪 TTFT(p50/p95/p99)与 ITL/TPOT(p50/p95/p99)。这样一来,例如在升级期间就更容易排查性能回退。例如,如果预填充服务器已饱和或提示词较短,它们会跳过远程预填充。
- Use QoS to maintain SLAs at scale使用 QoS 在大规模下维持 SLA
- Apply admission control and prioritization under heavy load. It’s best to fast-fail excess or low-priority requests than to let the system’s latency explode for everyone. Real-world systems implement early rejection by returning “busy” errors or a degraded response length—to guarantee that 99th-percentile latency stays under a given threshold. Disaggregation and QoS together prevent overload cascades—even in billion-request-per-day scenarios.在高负载下应用准入控制和优先级划分。与其让系统的时延对所有人都急剧恶化,不如快速失败掉多余的或低优先级的请求。真实系统通过返回“busy”错误或降低响应长度来实现提前拒绝——以保证第 99 百分位时延保持在给定阈值之下。解耦与 QoS 相结合可以防止过载级联——即使在每天数十亿请求的场景中也是如此。
结语
Conclusion
Disaggregated prefill and decode is now common in modern high-scale LLM inference. Virtually all major AI providers like Meta, Amazon, NVIDIA, Google, and OpenAI (or “MANGO”) have embraced some form of disaggregated architecture in their large-scale LLM deployments.解耦式预填充与解码如今在现代大规模 LLM 推理中已十分常见。几乎所有主要 AI 提供商,如 Meta、Amazon、NVIDIA、Google 和 OpenAI(合称“MANGO”),都已在其大规模 LLM 部署中采用了某种形式的解耦架构。
While most of these companies do not publish their complete production architecture, there are numerous open source implementations (e.g., vLLM, SGLang, NVIDIA’s Dynamo) that demonstrate this approach and its benefits. Disaggregated PD produces higher goodput, or useful throughput under latency constraints, and better cost-efficiency than monolithic designs.尽管这些公司大多并未公开其完整的生产架构,但有大量开源实现(例如 vLLM、SGLang、NVIDIA 的 Dynamo)展示了这一方法及其优势。与单体式设计相比,解耦式 PD 能带来更高的有效吞吐——即时延约束下的有用吞吐量——以及更好的成本效益。
In the next chapter, we’ll continue combining modern GPU and networking hardware with more advanced scheduling and caching optimizations to serve multi-trillion-parameter model LLMs to billions of users without sacrificing latency or blowing up costs.在下一章中,我们将继续把现代 GPU 与网络硬件同更先进的调度与缓存优化结合起来,在不牺牲时延、也不使成本失控的前提下,为数十亿用户提供数万亿参数规模的 LLM 服务。