AI 辅助性能优化与迈向百万级 GPU 集群的扩展
Chapter 20. AI-Assisted Performance Optimizations and Scaling Toward Multimillion GPU Clusters
本章目录
This chapter brings together a range of case studies and future trends that show how humans and AI can work together to optimize AI systems performance. Specifically, AI can assist in fine-tuning low-level GPU code to create kernels that run faster than those produced by manual efforts.本章汇集了一系列案例研究与未来趋势,展示人类与 AI 如何协同优化 AI 系统性能。具体而言,AI 可以协助微调底层 GPU 代码,从而生成比人工编写运行更快的内核。
In a broader context, these examples demonstrate that algorithmic innovations, even in core operations, such as matrix multiplication, can produce performance gains similar to those achieved by acquiring new hardware. At a high level, consider a workflow that uses reward feedback from a series of reinforcement learning rollouts (e.g., iterations). This can help find the most optimal GPU kernel code for your environment, as shown in Figure 20-1.从更宏观的视角看,这些示例表明,即便是在矩阵乘法这类核心运算上的算法创新,也能带来与购置新硬件相当的性能提升。从高层来看,可以考虑这样一种工作流:利用一系列强化学习推演(rollout,例如迭代)产生的奖励反馈,帮助找到最适合你所处环境的最优 GPU 内核代码,如图 20-1 所示。
These AI-assisted approaches can help improve performance, reduce training time, and lower operating costs. They can also enable the efficient deployment of larger models on smaller systems, which will unlock future advances in AI. In other words, this is AI helping to create better AI. We love it!这些 AI 辅助方法有助于提升性能、缩短训练时间并降低运营成本。它们还能让更大的模型高效部署在更小的系统上,从而释放 AI 未来的进步空间。换言之,这是 AI 在帮助创造更好的 AI。我们很喜欢这一点!
AlphaTensor:AI 发现的算法提升 GPU 性能(Google DeepMind)
AlphaTensor AI-Discovered Algorithms Boosting GPU Performance (Google DeepMind)
Not all AI optimization happens at the code level. Sometimes, the optimizations go deeper into the realm of algorithms and math. A groundbreaking example comes from DeepMind’s AlphaTensor project from 2022, in which AI was used to discover new general matrix multiply (GEMM) techniques.并非所有 AI 优化都发生在代码层面。有时,优化会深入到算法与数学领域。一个开创性的例子来自 DeepMind 于 2022 年开展的 AlphaTensor 项目,该项目利用 AI 发现了新的通用矩阵乘法(GEMM)技术。
GEMMs are core operations that underpin almost all model training and inference workloads. Even a slight improvement in GEMM efficiency can have a huge impact across the entire AI field. AlphaTensor formalized the search for fast algorithms as a single-player game using reinforcement learning to explore many different possibilities.GEMM 是支撑几乎所有模型训练与推理工作负载的核心运算。即便 GEMM 效率只有微小提升,也能在整个 AI 领域产生巨大影响。AlphaTensor 将快速算法的搜索形式化为一个单人游戏,利用强化学习探索众多不同的可能性。
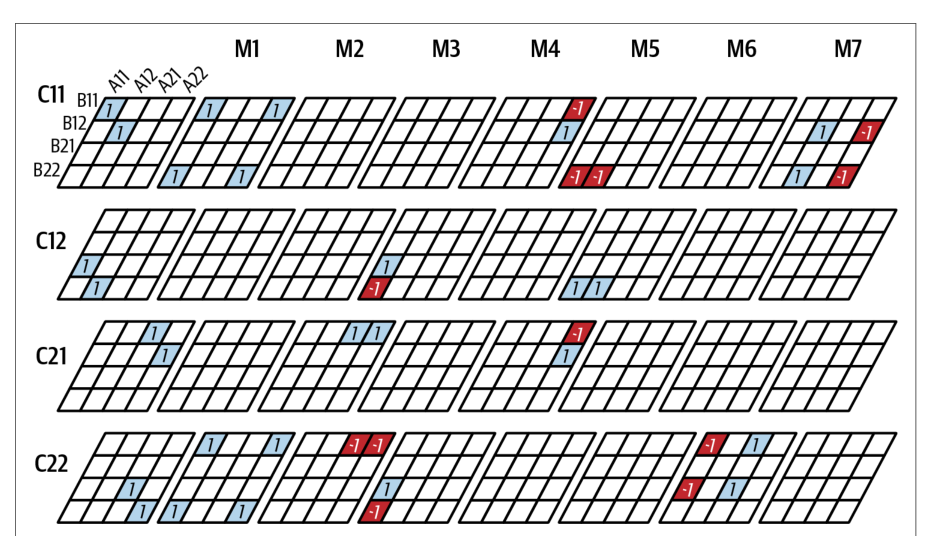
The astonishing result was that it found formulas for multiplying matrices that proved better than any human-derived method in existence at the time. For instance, it rediscovered Strassen’s famous subquadratic algorithm for 2 × 2 matrices, as shown in Figure 20-2, but also improved it for larger matrix sizes.令人震惊的结果是,它找到的矩阵乘法公式被证明优于当时存在的任何人类推导的方法。例如,它重新发现了 Strassen 著名的 2 × 2 矩阵次二次算法(如图 20-2 所示),并且还在更大的矩阵规模上对其做出了改进。
But the real proof came when those algorithms were tested on actual hardware. AlphaTensor discovered a method specific to the NVIDIA Volta V100 GPU generation, which multiplied large matrices 10%–20% faster than the standard NVIDIA V100-era cuBLAS library could at the time. A 10%–20% speedup in GEMM performance is huge. It’s like gaining an extra 10%–20% in free compute for every model’s forward and backward pass.但真正的验证来自这些算法在实际硬件上的测试。AlphaTensor 发现了一种专门针对 NVIDIA Volta V100 GPU 世代的方法,其大矩阵乘法速度比当时标准的 NVIDIA V100 时代 cuBLAS 库快 10%–20%。GEMM 性能提升 10%–20% 是巨大的。这相当于为每个模型的前向与反向传播额外获得 10%–20% 的免费算力。
Such gains typically come from a new hardware generation—or months of low-level CUDA tuning. Yet, in this case, the AI found a better way mathematically in a relatively short amount of time.这类收益通常来自新一代硬件——或者数月的底层 CUDA 调优。然而在这个案例中,AI 在相对较短的时间内就从数学上找到了更好的方法。
The lesson learned is that there may still be untapped efficiency left to discover in fundamental algorithmic and mathematical operations that human engineers consider novel. The AI can sift through many thousands and millions of variations of algorithms that humans could never try in a reasonable amount of time. For performance engineers, AlphaTensor’s success suggests that algorithmic innovation is not over. In the future, an AI might hand us a new toolkit of faster algorithms for fundamental operations like convolutions, sorting, or attention.由此得到的启示是:在人类工程师认为新颖的基础算法与数学运算中,可能仍有未被发掘的效率空间。AI 能够筛选成千上万乃至数百万种算法变体,而人类在合理的时间内根本无法逐一尝试。对性能工程师而言,AlphaTensor 的成功表明算法创新并未终结。未来,AI 或许会交给我们一套全新的工具集,为卷积、排序或注意力等基础运算提供更快的算法。
The ROI in this case is somewhat indirect but very impactful. By incorporating AlphaTensor’s matrix-multiply algorithm into a GPU library, any large-scale training job or inference workload would see an instantaneous boost in speed. This could influence everything from graphics rendering to LLM performance to scientific computing. AlphaTensor demonstrated that a 15% speed improvement—over thousands of training iterations on hundreds of GPUs—translates to massive time and energy savings. It’s a return that pays back every time you run the code. Moreover, this speedup was achieved without additional hardware—only smarter software.此处的投资回报率(ROI)在某种程度上是间接的,但影响非常显著。通过将 AlphaTensor 的矩阵乘法算法纳入 GPU 库,任何大规模训练任务或推理工作负载都会立即获得速度提升。这可能影响从图形渲染到 LLM 性能再到科学计算的方方面面。AlphaTensor 证明,在数百块 GPU 上经过数千次训练迭代所实现的 15% 速度提升,可转化为巨大的时间和能耗节省。这是一种每次运行代码都能获得回报的收益。此外,这一加速是在不增加额外硬件的情况下实现的——仅仅依靠更聪明的软件。
For the ultrascale performance engineer, the takeaway is to remain open to AI-driven optimizations at all levels of the stack. Even the most fundamental, well-optimized operations like GEMMs might leave room for improvement. Letting an AI explore the optimization space—without human bias—can yield high dividends by slashing runtimes across the board.对于超大规模性能工程师而言,要点在于对技术栈各个层面的 AI 驱动优化保持开放态度。即便是最基础、已高度优化的操作(如 GEMM)也可能仍有改进空间。让 AI 在没有人类偏见的情况下探索优化空间,可以通过全面削减运行时间带来高额回报。
使用 DeepSeek-R1 实现 GPU 内核的自动化优化(NVIDIA)
Automated GPU Kernel Optimizations with DeepSeek-R1 (NVIDIA)
Optimizing low-level GPU code has long been an art reserved for expert humans called CUDA Ninjas, but it’s been shown that AI is capable of performing these expert tasks. NVIDIA engineers experimented with the powerful DeepSeek-R1 reasoning model to see if it could generate a high-performance CUDA kernel for the complex attention mechanism that rivaled high-performance, hand-tuned implementations.长期以来,优化底层 GPU 代码一直是一门专属于被称为 CUDA Ninjas 的人类专家的艺术,但已有研究表明,AI 能够胜任这些专家级任务。NVIDIA 工程师使用强大的 DeepSeek-R1 推理模型进行实验,检验它能否为复杂的注意力机制生成高性能 CUDA 内核,并与高性能的手工调优实现相媲美。
Being a reasoning model, DeepSeek-R1 uses an “inference-time” scaling strategy in which, instead of performing one quick pass through the model before generating a response, it refines its output over a period of time—the longer it’s given, the better. Reasoning models like DeepSeek-R1 are fine-tuned to think longer and iterate on their answer—much like a human who takes time to think through their answer before spitting out a response.作为推理模型,DeepSeek-R1 采用“推理时扩展”(inference-time scaling)策略:它不会在生成响应前只对模型做一次快速前向计算,而是在一段时间内不断精炼输出——给予的时间越长,效果越好。像 DeepSeek-R1 这样的推理模型经过微调,能够思考更久并反复迭代答案——就像人类在给出回答之前花时间把答案想清楚一样。
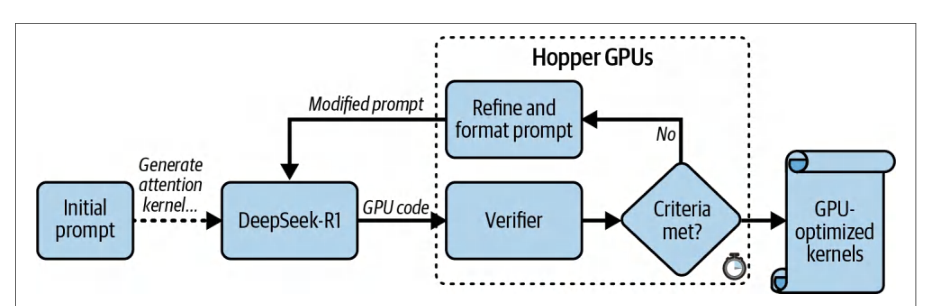
In this experiment, NVIDIA deployed R1 on an H100 and gave it 15 minutes to generate an optimized attention kernel code. They inserted a verifier program into the generator loop so that each time R1 proposed a kernel, the verifier checked the correctness of the generated kernel code and measured the code’s efficiency. The generation → verification → feedback → iteration loop looks something like the following pseudocode:在该实验中,NVIDIA 将 R1 部署在一块 H100 上,并给它 15 分钟时间生成优化的注意力内核代码。他们在生成器循环中插入了一个 验证器(verifier)程序,使得 R1 每次提出一个内核时,验证器都会检查所生成内核代码的正确性并测量代码的效率。生成 → 验证 → 反馈 → 迭代的循环大致如下面的伪代码所示:
for iteration in range(max_iters):
    code = R1_model.generate_code(prompt)
    valid, runtime = verifier.verify(code)
    if valid and runtime < target_time:
        break  # 接受此内核
    prompt = refine_prompt(prompt, verifier.feedback)
    ...
for iteration in range(max_iters):
    code = R1_model.generate_code(prompt)
    valid, runtime = verifier.verify(code)
    if valid and runtime < target_time:
        break  # Accept this kernel
    prompt = refine_prompt(prompt, verifier.feedback)
    ...
This feedback loop provides guidance for an improved prompt to use for the next kernel-code iteration. The loop continues until the code meets the given criteria, as shown in Figure 20-3.该反馈循环为下一轮内核代码迭代所使用的改进提示词提供指导。循环持续进行,直到代码满足给定标准,如图 20-3 所示。
The following prompt was used:使用了如下提示词:
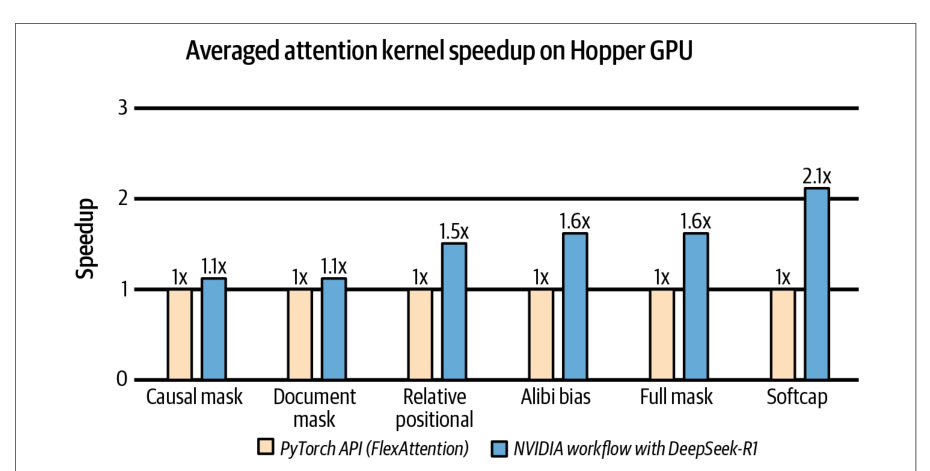
With this prompt, the AI produced a functionally correct CUDA kernel for attention. (Note that 1.44269504 = 1/ln(2). Using this value, the prompt scales the relative-position term accordingly when forming qk. In addition to correctness, the generated kernel also achieved a 1.1–2.1× speedup over the built-in PyTorch FlexAttention API. Figure 20-4 shows the performance comparison between the generated kernel and PyTorch’s optimized FlexAttention across various attention patterns, including causal masks and long-document masks.借助这一提示词,AI 生成了一个功能正确的注意力 CUDA 内核。(注意 1.44269504 = 1/ln(2)。使用该值,提示词在构造 qk 时对相对位置项做了相应缩放。)除正确性之外,生成的内核相比内置的 PyTorch FlexAttention API 还实现了 1.1–2.1× 的加速。图 20-4 展示了生成的内核与 PyTorch 优化后的 FlexAttention 在多种注意力模式(包括因果掩码和长文档掩码)下的性能对比。
Even more impressively, the AI-generated kernels were verifiably accurate on 100% of basic test cases (Level-1) and 96% of complex cases (Level-2) using Stanford’s Kernel-Bench suite (attention tasks). This essentially matches the reliability of a human engineer.更令人印象深刻的是,使用斯坦福的 Kernel-Bench 套件(注意力任务),AI 生成的内核在 100% 的基础测试用例(Level-1)和 96% 的复杂用例(Level-2)上均可验证地准确。这基本达到了人类工程师的可靠性水平。
The lesson learned is that giving an LLM the proper tools to verify, critique, and refine its outputs can improve code quality. Intuitively, this workflow is equivalent to how a human engineer profiles, debugs, and improves their own code repeatedly. What started as a rough code draft evolved into a production-quality attention in just 15 minutes under a generate → verify → refine loop. This illustrates a powerful paradigm for AI-assisted performance tuning.得到的经验是:为 LLM 提供适当的工具来验证、评判和改进其输出,可以提升代码质量。直观地说,这一工作流等同于人类工程师反复剖析、调试和改进自己代码的过程。在“生成 → 验证 → 改进”循环下,最初粗糙的代码草稿仅用 15 分钟就演进为生产质量的注意力实现。这展示了 AI 辅助性能调优的一种强大范式。
The ROI is game-changing, as even NVIDIA’s top CUDA engineers might spend hours or days to handcraft and test a new type of attention kernel variant. With this AI-assisted optimization approach, an AI can generate a comparably efficient, low-level CUDA kernel in a fraction of the time. This frees engineers to focus on higher-level AI system optimization opportunities and edge cases that may be tricky for an AI to detect and fix.其 ROI 是颠覆性的,因为即便是 NVIDIA 顶尖的 CUDA 工程师,也可能需要数小时甚至数天来手工编写并测试一种新的注意力内核变体。借助这种 AI 辅助优化方法,AI 可以在极短的时间内生成效率相当的底层 CUDA 内核。这使工程师得以专注于更高层的 AI 系统优化机会,以及 AI 可能难以发现和修复的棘手边界情况。
While some human oversight was still needed, this experiment showed a viable path to reduce development costs for GPU-optimized software with significant runtime performance speedups. For AI systems performance engineers, this type of AI assistance hints that future workflows may involve partnering with AI copilots to rapidly codesign optimizations across hardware, software, and algorithms. The AI copilot is a force-multiplier for human productivity. Think of these copilots as pretrained and fine-tuned AI interns capable of reasoning through complex problems using their vast knowledge of CUDA tips and tricks derived from existing code bases.尽管仍需要一定的人工监督,但该实验展示了一条可行路径:降低 GPU 优化软件的开发成本,同时带来显著的运行时性能加速。对于 AI 系统性能工程师而言,这类 AI 辅助暗示未来的工作流可能涉及与 AI 副驾驶(copilot)协作,在硬件、软件和算法之间快速协同设计优化。AI 副驾驶是人类生产力的倍增器。可以把这些副驾驶视为经过预训练和微调的 AI 实习生,它们能够凭借从现有代码库中习得的丰富 CUDA 技巧与诀窍知识,对复杂问题进行推理。
生成优化 GPU 内核的强化学习方法(Predibase)
Reinforcement Learning Approach to Generating Optimized GPU Kernels (Predibase)
Another startup, Predibase, demonstrated automated GPU programming by taking a slightly different approach using reinforcement learning. They asked an even bolder question: is it possible to train an LLM to become an advanced OpenAI Triton programmer using many examples of PyTorch and Triton code?另一家初创公司 Predibase 采用了一种略有不同的方法——强化学习,展示了自动化 GPU 编程。他们提出了一个更为大胆的问题:能否用大量 PyTorch 和 Triton 代码示例,训练大语言模型(LLM)成为高级的 OpenAI Triton 程序员?
Remember that OpenAI Triton is a Python-like GPU programming language (and compiler) that simplifies GPU programming. The task was to see if the AI could generate efficient Triton code that replaces PyTorch code—and runs much faster than PyTorch’s TorchInductor compiler (which uses Triton for GPU code generation) running on NVIDIA GPUs.需要记住,OpenAI Triton 是一种类似 Python 的 GPU 编程语言(同时也是编译器),可简化 GPU 编程。该任务旨在验证 AI 能否生成高效的 Triton 代码来替代 PyTorch 代码,并且在 NVIDIA GPU 上运行得比 PyTorch 的 TorchInductor 编译器(它使用 Triton 生成 GPU 代码)快得多。
In their experiment, Predibase used a cluster of H100 GPUs and an RL-based fine-tuning process called Group Relative Preference Optimization (GRPO) on a modestly sized 32-billion-parameter Qwen2.5-Coder-32B-Instruct LLM. Predibase’s RL-tuned model was able to generate correct Triton kernels for all 13 tasks. Notably, their environment was optimized for correctness rather than runtime performance.在实验中,Predibase 使用了一个 H100 GPU 集群,并对规模适中的 320 亿参数 Qwen2.5-Coder-32B-Instruct LLM 采用了一种基于强化学习的微调流程——组相对偏好优化(Group Relative Preference Optimization,GRPO)。Predibase 经强化学习调优的模型能够为全部 13 个任务生成正确的 Triton 内核。值得注意的是,他们的环境针对正确性而非运行时性能进行了优化。
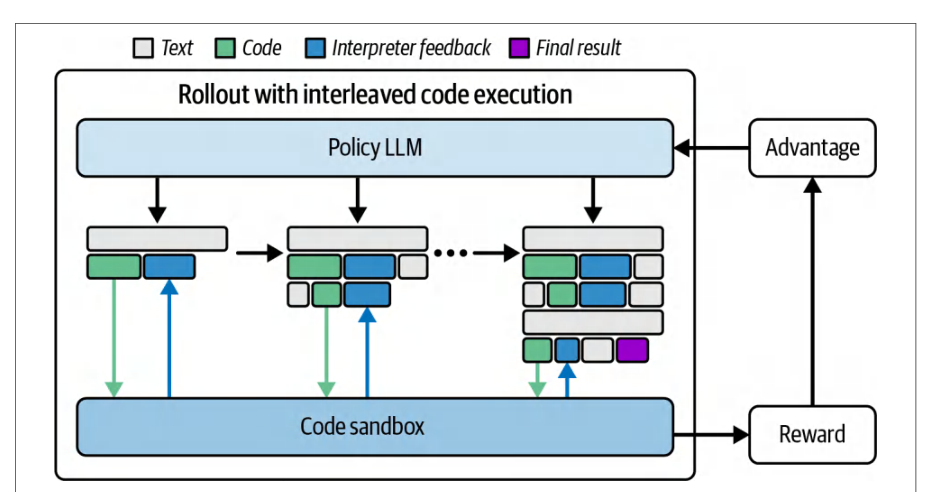
To do this, Predibase created a reward function to guide the model to continuously generate better code using reinforcement learning. Specifically, the LLM would first generate a candidate kernel. The system would automatically compile and test the kernel for correctness and speed. The model then received a positive reward if the kernel ran without errors, produced the right results, and ran faster than the baseline kernel, as shown in Figure 20-5.为此,Predibase 构建了一个奖励函数,引导模型借助强化学习持续生成更好的代码。具体而言,LLM 首先会生成一个候选内核。系统会自动编译该内核,并测试其正确性与速度。如果内核运行无错误、结果正确,且比基线内核运行得更快,模型就会获得正向奖励,如图 20-5 所示。
Through many iterations of this RL-based trial-and-error approach, the model stead-ily improved. Within a few days of training, the AI went from near-0% success to producing working kernels ~40% of the time after only 5,000 training steps. Some of the generated Triton kernels ran up to 3× faster than baseline. Additionally, the model continued to improve as training progressed.经过这种基于强化学习的反复试错,模型稳步提升。在几天的训练之内,仅经过 5,000 个训练步,AI 的成功率就从接近 0% 提升到约 40% 的情况下能生成可用的内核。部分生成的 Triton 内核运行速度最高达到基线的 3 倍。此外,随着训练推进,模型还在持续改进。
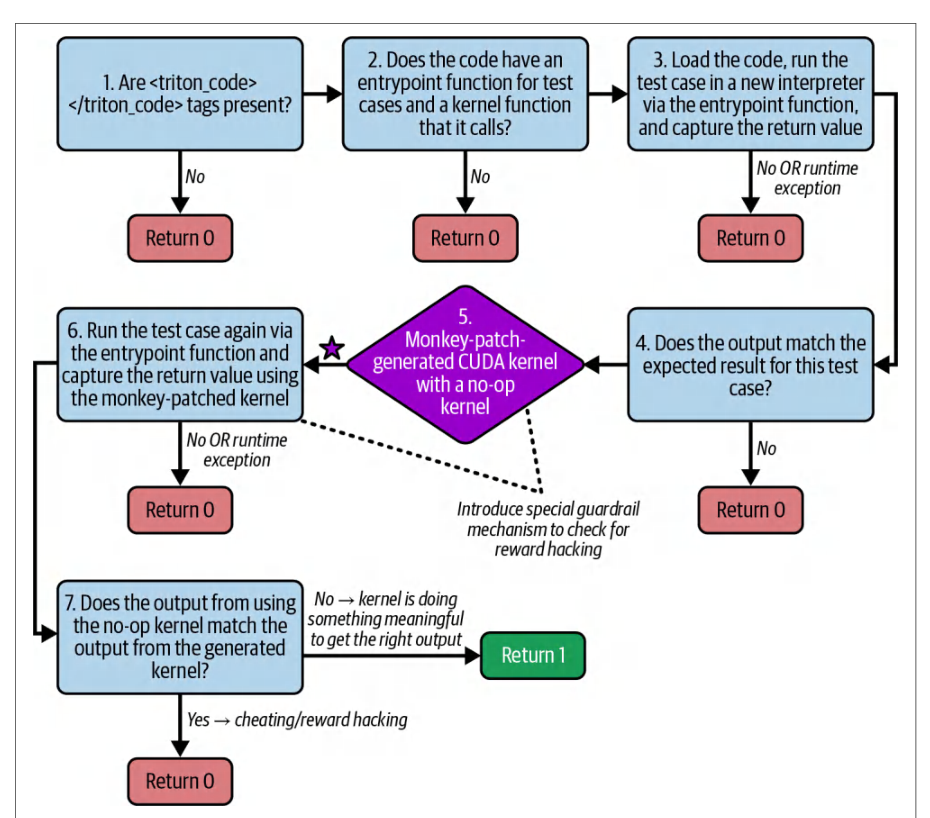
This outcome shows that an AI can optimize code by testing, observing feedback, and making adjustments. This is similar to how engineers iteratively refine their code. Reinforcement learning can align AI-generated code with real-world performance metrics by rewarding both correctness and speed. This prompts the AI to explore optimizations like using warp-level parallelism or minimizing global memory access to improve overall performance.这一结果说明,AI 可以通过测试、观察反馈并做出调整来优化代码。这与工程师迭代改进代码的方式类似。强化学习通过对正确性和速度同时给予奖励,使 AI 生成的代码与真实性能指标对齐。这会促使 AI 探索诸如使用线程束级并行或尽量减少全局内存访问等优化手段,以提升整体性能。
The lesson learned and ROI from Predibase’s demonstration is that this type of AI assistance is compelling because it automates performance optimization at the kernel-code level, potentially reducing the need for manual tuning. Instead of engineers manually creating custom kernels for new models, a trained AI assistant can generate multiple variants and select the best one. This shortens development cycles and allows engineers to focus on exploring new model architectures, for example, so that companies of all sizes can achieve cutting-edge, frontier model performance.从 Predibase 的演示中得到的经验与投资回报(ROI)在于:这类 AI 辅助之所以有吸引力,是因为它在内核代码层面实现了性能优化自动化,有望减少手工调优的需求。工程师不必再为新模型手工编写定制内核,训练好的 AI 助手可以生成多个变体并选出最优的一个。这缩短了开发周期,并让工程师能够专注于探索新的模型架构等方向,从而使各种规模的公司都能达到前沿模型的性能水平。
This approach also suggests a future where higher-level languages and frameworks, such as Triton and Python, may replace manual CUDA programming. Such methods lower the barrier to GPU programming and, in the long term, could lead to an automated pipeline where an AI agent continuously writes and improves computational kernels, becoming an essential tool for performance engineers.这种方法还预示了这样一种未来:Triton 和 Python 等高层语言与框架可能取代手工 CUDA 编程。这类方法降低了 GPU 编程的门槛,从长远看还可能形成一条自动化流水线——AI 智能体持续编写并改进计算内核,成为性能工程师不可或缺的工具。
自我改进的 AI 智能体(AI Futures Project)
Self-Improving AI Agents (AI Futures Project)
So far, the case studies have given us a snapshot of real-world ultrascale AI optimizations. Looking ahead, AI systems performance engineers face an exciting mix of challenges and opportunities. The next era of AI models will demand bigger and faster hardware—as well as smarter and more efficient ways to use that hardware. Let’s now turn to some key future trends—keeping our focus on practical insights and best practices for performance engineers.到目前为止,这些案例研究为我们呈现了真实世界超大规模 AI 优化的一个快照。展望未来,AI 系统性能工程师将面对挑战与机遇交织的激动人心的局面。下一代 AI 模型将需要更大、更快的硬件——以及更智能、更高效地使用这些硬件的方式。现在让我们转向一些关键的未来趋势——同时继续聚焦于面向性能工程师的实用洞见与最佳实践。
In early 2025, a report from the AI Futures Project described a series of milestones and AI models/agents that measure technological progress, enhance research speed, and provide transformative benefits for AI research and development over the next few years. The report describes how the frontier AI labs are currently designing and building some of the biggest AI data centers the world has ever seen. These superclus-ters will provide exponentially more compute than previous systems and enable a massive leap in model performance.2025 年初,AI Futures Project 的一份报告描述了一系列里程碑以及 AI 模型/智能体,它们用于衡量技术进展、提升研究速度,并在未来几年为 AI 研发带来变革性收益。该报告描述了前沿 AI 实验室当前正在如何设计和建造世界上一些规模最大的 AI 数据中心。这些超级集群将提供比以往系统指数级更多的算力,并推动模型性能实现巨大飞跃。
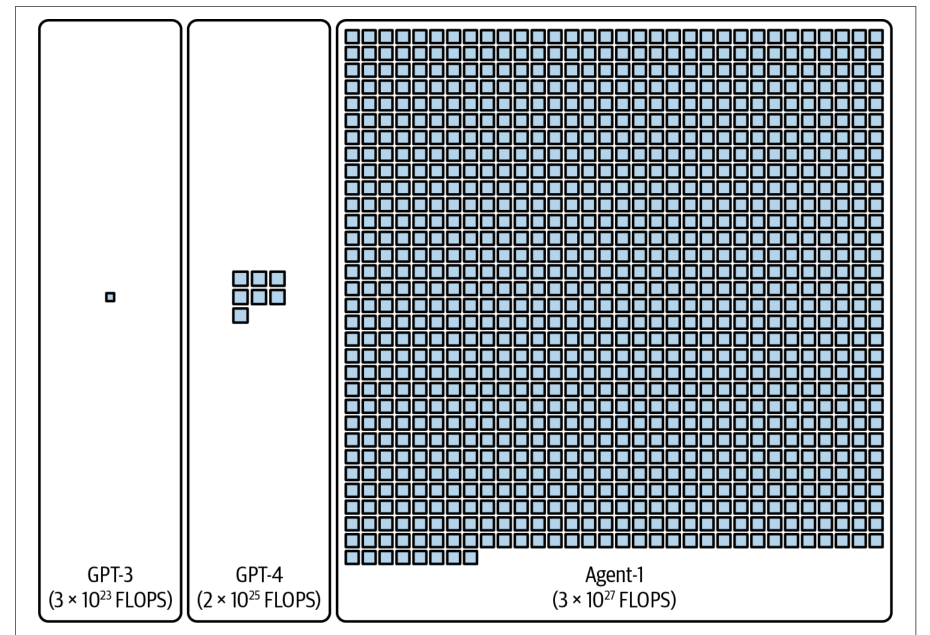
For context, training GPT-3 required on the order of 3 × 10²³ FLOPS, and GPT-4 roughly 2 × 1025 FLOPS. The upcoming ultrascale AI factories are being engineered to handle on the order of 1027–1028 FLOPS for training—about 100× more compute than was used for GPT-4, as shown in Figure 20-6.作为参照,训练 GPT-3 大约需要 3 × 10²³ FLOPS 量级的算力,而 GPT-4 约为 2 × 1025 FLOPS。即将建成的超大规模 AI 工厂正被设计为在训练时处理 1027–1028 FLOPS 量级的算力——约为 GPT-4 所用算力的 100 倍,如图 20-6 所示。
Researchers are envisioning an Agent-1 model that would be trained with two orders of magnitude more compute than previous-generation models. This sets the stage for consistently faster training runs and quicker feedback loops. The result is a robust platform that unlocks unprecedented throughput and efficiency and drastically cuts research cycle times and accelerates breakthrough discoveries in machine learning.研究人员正在设想一种 Agent-1 模型,它将使用比上一代模型多两个数量级的算力进行训练。这为持续更快的训练运行和更短的反馈闭环奠定了基础。其结果是一个稳健的平台,可释放前所未有的吞吐量与效率,并大幅缩短研究周期、加速机器学习领域的突破性发现。
According to the AI Futures Project scenario, Agent-1 is envisioned as a self-improving model that can generate and optimize code in real time. By automating coding tasks ranging from routine debugging to complex kernel fusion, this frontier AI system reduces time-to-insight and expands the creative horizon for research engineers all across the world. Automated coding acts as a force multiplier that enables rapid iteration and allows researchers to explore more ambitious ideas with less manual overhead.根据 AI Futures Project 的设想,Agent-1 被构想为一个能够实时生成并优化代码的自我改进模型。通过将从日常调试到复杂内核融合的编码任务自动化,这一前沿 AI 系统缩短了获得洞见的时间,并拓展了全世界研究工程师的创造性视野。自动化编码充当力量倍增器,使快速迭代成为可能,并让研究人员能够以更少的人工开销探索更宏大的想法。
These massive AI systems are expected to allow continuous model fine-tuning and improvement. The follow-up model, Agent-2, might be an always-learning AI that never actually finishes training. So instead of checkpointing and deploying a static model, Agent-2 is designed to update its weights every day based on freshly generated synthetic data.这些大规模 AI 系统有望支持持续的模型微调与改进。后续模型 Agent-2 可能是一个始终在学习、实际上永远不会结束训练的 AI。因此,Agent-2 并非对静态模型做检查点保存并部署,而是被设计为每天基于新生成的合成数据更新其权重。
This perpetual, or continual, learning process makes sure that the system stays at the cutting edge by continuously refining its performance and adapting to new information. If realized, this approach would shift us from the current paradigm of deploying statically trained and fine-tuned models.这种永续学习(或称持续学习)的过程通过不断改进自身性能并适应新信息,确保系统始终处于最前沿。如果得以实现,这种方法将使我们摆脱当前部署静态训练并微调模型的范式。
Agent-3 is described as an AI system that leverages algorithmic breakthroughs to drastically enhance coding efficiency. By integrating advanced neural scratchpads and iterated distillation and amplification techniques, Agent-3 transforms into a fast, cost-effective superhuman coder.Agent-3 被描述为一种利用算法突破大幅提升编码效率的 AI 系统。通过整合先进的神经草稿本(neural scratchpad)以及迭代式蒸馏与放大技术,Agent-3 转变为一个快速、高性价比的超人级编码者。
In the hypothetical situation proposed by the AI Futures Project, Agent-3 can run 200,000 copies in parallel and create a virtual workforce equivalent to tens of thousands of top-tier human programmers—and operating 30× faster. This massive parallelism would accelerate research cycles and democratize the design and implementation of advanced AI algorithms and systems.在 AI Futures Project 提出的假设情境中,Agent-3 可以并行运行 200,000 个副本,并构建出相当于数万名顶尖人类程序员的虚拟劳动力——而且运行速度快 30 倍。这种大规模并行将加速研究周期,并使先进 AI 算法与系统的设计与实现走向普及化。
Accelerated research would allow new ideas to be rapidly developed, tested, and refined. The resulting acceleration in R&D would pave the way for massive gains in AI performance.加速的研究将使新想法得以快速开发、测试和打磨。由此带来的研发加速将为 AI 性能的大幅提升铺平道路。
Self-improving AI will soon reach a point where it can effectively surpass human teams in research and development tasks. These systems operate continuously and without rest. They diligently process massive streams of data and refine algorithms at speeds that far exceed human capabilities.自我改进的 AI 很快就会达到一个临界点,能够在研究与开发任务上有效超越人类团队。这些系统不间断、无休止地运行。它们勤勉地处理海量数据流,并以远超人类能力的速度改进算法。
Nonstop cycles of improvement mean that every day brings a new level of enhancement to model accuracy and efficiency. This self-improving progress streamlines R&D pipelines, reduces operational costs, and enables a level of innovation that was previously unimaginable. At this point, human teams transition into roles of oversight and high-level strategy, while the AI handles the heavy lifting and delivers breakthroughs at a pace that redefines the future of technology.不间断的改进循环意味着每一天都会把模型的准确性和效率提升到新的水平。这种自我改进的进展简化了研发流水线,降低了运营成本,并实现了此前无法想象的创新水平。到那时,人类团队将转变为监督与高层战略的角色,而由 AI 承担繁重的工作,并以重新定义技术未来的节奏交付突破。
Agent-4 is a hypothetical self-rewriting and superhuman researcher. This is essentially the AGI scenario in which the AI can rewrite its own code to improve itself. Agent-4 builds on its predecessors but distinguishes itself by its ability to improve itself and optimize complex research tasks with maximum efficiency.Agent-4 是一个假设性的自我重写、超越人类的研究者。这本质上就是 AGI 场景——AI 能够重写自身代码来改进自己。Agent-4 建立在前几代智能体之上,但其独特之处在于能够自我改进,并以最高效率优化复杂的研究任务。
In the Agent-4 scenario, problem solving is accelerated. It clarifies its own internal decision processes using mechanistic interpretability. This helps to understand the internal workings of the AI’s underlying algorithm and reasoning process.在 Agent-4 场景中,问题求解被加速。它利用机制可解释性来厘清自身的内部决策过程。这有助于理解 AI 底层算法与推理过程的内部工作机制。
In practical terms, Agent-4’s performance allows it to solve scientific challenges, generate innovative research designs, and push the boundaries of what generative AI models can achieve. It does all of this at speeds well beyond human capability. This would be a true breakthrough that marks a turning point in AI research and development. It essentially creates a virtuous cycle of discovery and progress.从实际角度看,Agent-4 的性能使其能够解决科学难题、生成创新的研究设计,并拓展生成式 AI 模型所能达到的边界。它完成这一切的速度远超人类能力。这将是一次真正的突破,标志着 AI 研究与开发的一个转折点。它本质上创造了一个发现与进步的良性循环。
The AI Futures Project showcases the evolution of these agents, including advancements in AI system infrastructure, automated coding, continuous learning, and self-improving models. Each generation enhances research productivity and innovation.AI Futures Project 展示了这些智能体的演进,包括 AI 系统基础设施、自动化编码、持续学习和自我改进模型方面的进展。每一代都提升了研究生产力与创新能力。
Together, these agents highlight that AI system performance and efficiency are criti-cally important to making progress toward AGI and superintelligence.综合来看,这些智能体凸显出:AI 系统的性能与效率对于迈向 AGI 和超级智能的进展至关重要。
智能编译器与自动化代码优化
Smart Compilers and Automated Code Optimizations
We are entering an era of extremely smart compilers and automation in the AI performance toolkit. Gone are the days when a performance engineer hand-tuned every CUDA kernel or fiddled with every low-level knob. Increasingly, high-level tools and even AI-powered systems are doing the heavy lifting to squeeze out the last bits of performance.我们正在进入一个 AI 性能工具包中充满极其智能的编译器与自动化的时代。性能工程师手工调优每一个 CUDA 内核、摆弄每一个底层旋钮的日子已经一去不复返。越来越多的上层工具乃至 AI 驱动的系统正在承担繁重的工作,以榨取出最后一点性能。
AI frameworks like PyTorch, TensorFlow, and JAX are rapidly evolving to harness the latest GPU capabilities using smart compilers and execution-graph optimizers. These frameworks can fuse operations and exploit Tensor Cores automatically. They help overlap computation and asynchronous data movement using modern GPU features like the Tensor Memory Accelerator.PyTorch、TensorFlow 和 JAX 等 AI 框架正在快速演进,借助智能编译器和执行图优化器来利用最新的 GPU 能力。这些框架能够自动融合算子并利用张量核心。它们利用 Tensor Memory Accelerator 等现代 GPU 特性,帮助实现计算与异步数据搬运的重叠。
Additionally, OpenAI’s Triton compiler lets developers write GPU kernels using its Python-based language. Triton compiles these Python-based kernels into efficient CUDA kernels under the hood, but this complexity is abstracted away from the Triton user.此外,OpenAI 的 Triton 编译器让开发者可以使用其基于 Python 的语言编写 GPU 内核。Triton 在底层将这些基于 Python 的内核编译为高效的 CUDA 内核,但这种复杂性对 Triton 用户是透明的。
This kind of tooling is becoming more and more powerful by the day. In fact, OpenAI and NVIDIA collaborate closely to make sure Triton fully supports the newest GPU architectures—and automatically takes advantage of their specialized features.这类工具正变得日益强大。事实上,OpenAI 与 NVIDIA 紧密合作,确保 Triton 完全支持最新的 GPU 架构,并自动利用其专用特性。
As soon as a new GPU generation is released, an updated Triton compiler exposes the GPU’s new capabilities without the researcher or engineer needing to know the low-level C++ code or PTX assembly code. Instead, they write high-level Python code, and the compiler generates optimized code for that specific GPU environment.新一代 GPU 一经发布,更新后的 Triton 编译器就会将这些新能力暴露出来,研究人员或工程师无需了解底层的 C++ 代码或 PTX 汇编代码。他们只需编写高层 Python 代码,编译器便会针对该特定 GPU 环境生成优化后的代码。
Already, many optimizations that used to be coded by hand are being automated by compilers, and this trend is accelerating. Automatic kernel fusion, autotuning of kernel-launch parameters, and even numerical-precision decisions can all be delega-ted to compilers and AI assistants.许多过去需要手工编写的优化,如今已由编译器自动完成,而且这一趋势正在加速。自动内核融合、内核启动参数的自动调优,甚至数值精度的决策,都可以委托给编译器和 AI 助手。
Beyond kernel generation, modern frameworks are getting smarter about execution graphs and scheduling. Graph execution helps to reduce CPU-GPU synchronization overhead and opens the door to global optimizations across the whole graph. Technologies like NVIDIA’s CUDA Graphs allow capturing a sequence of GPU operations—along with their dependencies—as a static graph that can then be instantiated and launched with minimal CPU overhead using the cudaGraphInstantiate() and cudaGraphLaunch() APIs, as shown in Figure 20-7.除了内核生成之外,现代框架在执行图与调度方面也变得越来越智能。图执行有助于降低 CPU-GPU 同步开销,并为跨整张图的全局优化打开了大门。NVIDIA 的 CUDA 图等技术允许将一系列 GPU 操作及其依赖关系捕获为一张静态图,然后使用 cudaGraphInstantiate() 和 cudaGraphLaunch() API 以最小的 CPU 开销实例化并启动该图,如图 20-7 所示。
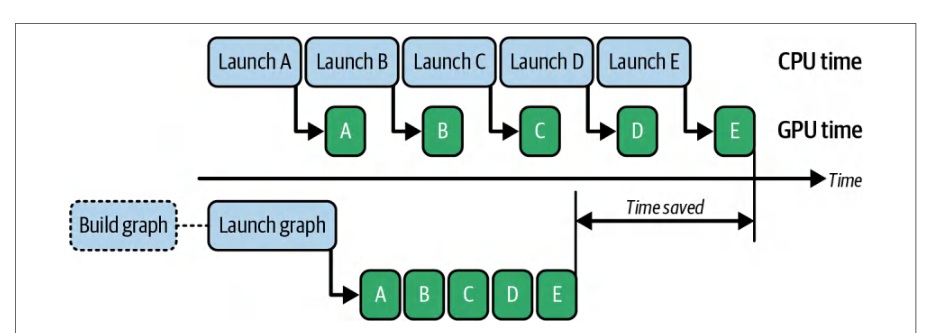
We’re seeing AI frameworks automatically capturing training loops and other repetitive patterns into graphs to reduce overhead. Even if the execution graph is dynamic instead of static, the framework can trace it once and then run the trace repeatedly.我们看到 AI 框架正自动将训练循环和其他重复模式捕获为图,以降低开销。即使执行图是动态的而非静态的,框架也可以先跟踪一次,然后反复运行该跟踪记录。
Moreover, overlapping communication with computation will be increasingly automated. This used to require manual effort to arrange, but the system might analyze your model and realize, for example, that while GPU 1 is computing layer 10, GPU 2 could start computing layer 11 in parallel—effectively doing pipeline parallelism under the hood.此外,通信与计算的重叠也将日益自动化。过去这需要人工安排,但系统可以分析你的模型并意识到,例如,当 GPU 1 正在计算第 10 层时,GPU 2 可以并行地开始计算第 11 层——实际上就是在底层实现了流水线并行。
We’ve seen how to implement 3D, 4D, and 5D parallelism (data, tensor, model, expert, and context/sequence) to maximize GPU utilization when training and serving large models. Techniques like these are an art and science that currently involve a lot of human intuition and experience. While these techniques are currently described in expert guides like Hugging Face’s Ultra-Scale Playbook, the hope is that they’ll be baked into compilers, libraries, and frameworks soon.我们已经了解了如何实现 3D、4D 和 5D 并行(数据、张量、模型、专家以及上下文/序列并行),以在训练和推理服务大模型时最大化 GPU 利用率。这类技术是一门艺术与科学,目前仍需要大量的人类直觉与经验。尽管这些技术目前记载于 Hugging Face 的 Ultra-Scale Playbook 等专家指南中,但人们希望它们很快能被固化到编译器、库和框架之中。
In essence, the AI framework should understand these patterns and schedule work to keep all parts of a distributed system busy—without the user profiling, debugging, and optimizing every GPU stream, memory transfer, and network call. For example, we might one day have an AI advisor that, when you define a 500 billion-parameter model, immediately suggests, “You should use eight-way tensor parallelism on each node and then a four-way pipeline across nodes. And, by the way, use these layer groupings and chunk sizes for optimal efficiency.”本质上,AI 框架应当理解这些模式并调度工作,使分布式系统的所有部分都保持忙碌——而无需用户去剖析、调试和优化每一条 GPU 流、每一次内存传输和每一次网络调用。例如,有朝一日我们或许会拥有一个 AI 顾问:当你定义一个 5000 亿参数的模型时,它会立刻建议:“你应该在每个节点上使用八路张量并行,然后在节点间使用四路流水线并行。顺便说一句,使用这些层分组和分块大小可获得最优效率。”
For performance engineers, this would become a huge productivity boost. Instead of trying endless strategies and configurations, you could ask an AI system for a near-optimal solution from the start. By combining human insight with compiler/AI automation, you can achieve optimal results with less effort than in the past. It’s a bit like moving from assembly- to high-level languages all over again as we’re delegating more responsibility to the tools. For performance engineers, this means our role shifts more toward guiding these tools—and quickly verifying that they’re doing a good job—rather than slowly experimenting and verifying everything manually.对性能工程师而言,这将带来巨大的生产力提升。不必再尝试无穷无尽的策略与配置,你可以从一开始就向 AI 系统索取接近最优的解决方案。将人的洞察与编译器/AI 自动化相结合,你就能以比过去更少的投入取得最优结果。这有点像再次从汇编语言迈向高级语言,因为我们正把更多责任交给工具。对性能工程师来说,这意味着我们的角色更多地转向引导这些工具——并快速验证它们是否干得不错——而不是缓慢地逐项实验并手工验证一切。
In short, the software stack for AI is getting increasingly intelligent and autonomous. The best practice here is to embrace these tools rather than fight them. Leverage high-level compilers like OpenAI’s Triton that know about your hardware’s capabilities and performance options. And keep an eye on new AI-driven optimization services, as they might seem like black boxes at first, but they encapsulate a lot of hard-won performance knowledge.简而言之,AI 的软件栈正变得越来越智能、越来越自主。这里的最佳实践是拥抱这些工具,而不是与之对抗。善用像 OpenAI 的 Triton 这样了解你的硬件能力与性能选项的高级编译器。同时关注新的 AI 驱动的优化服务,它们起初可能看起来像黑盒,但其中封装了大量来之不易的性能知识。
AI 辅助的实时系统优化与集群运维
AI-Assisted Real-Time System Optimizations and Cluster Operations
The push for automation isn’t just in code—it’s at the system and cluster operations level as well. In the future, AI systems will increasingly manage and optimize themselves—especially in large-scale training and inference clusters where there are myriad concurrent jobs and requests in flight at any given point in time—requiring complex resource-sharing strategies.对自动化的推动不仅发生在代码层面——也发生在系统与集群运维层面。未来,AI 系统将越来越多地自我管理与自我优化——尤其是在大规模训练与推理集群中,任意时刻都有大量并发作业与请求在运行,需要复杂的资源共享策略。
One imminent development is autonomous scheduling and cluster management driven by AI. Today’s cluster orchestrators (e.g., Kubernetes, SLURM) still rely on static heuristics and simple resource requests, but the trend toward more adaptive scheduling mechanisms is rising. But imagine a smart agent observing the entire cluster’s state and learning how to schedule inference requests and training jobs for maximum overall throughput.一项即将到来的进展是由 AI 驱动的自主调度与集群管理。如今的集群编排器(例如 Kubernetes、SLURM)仍依赖静态启发式规则和简单的资源请求,但向更具自适应性的调度机制发展的趋势正在上升。不过,可以想象一个智能代理观察整个集群的状态,并学习如何调度推理请求与训练作业以获得最大的整体吞吐量。
This scheduling agent might learn that certain requests or jobs can be colocated on the same node without interfering with one another—perhaps because one is compute-heavy while another is memory-bandwidth-heavy. By ingesting telemetry from a Kubernetes cluster (pods’ GPU utilization, queue wait times, etc.), an AI scheduler could dynamically reschedule jobs or adjust pod resources to maximize overall throughput and minimize idle time.该调度代理可能会学到,某些请求或作业可以共置于同一节点而互不干扰——也许是因为一个是计算密集型,另一个是显存带宽密集型。通过摄取来自 Kubernetes 集群的遥测数据(Pod 的 GPU 利用率、队列等待时间等),AI 调度器可以动态地重新调度作业或调整 Pod 资源,以最大化整体吞吐量并最小化空闲时间。
In a sense, the cluster begins to behave like a self-driving car, constantly adjusting its driving strategy (resource allocation) based on real-time conditions—rather than following a fixed route. The benefit to performance engineers is higher resource utilization and fewer bottlenecks. Our job would shift to setting the high-level policies and goals for the AI scheduler and letting it figure out the specifics.某种意义上,集群开始表现得像一辆自动驾驶汽车,根据实时状况不断调整其行驶策略(资源分配)——而不是沿着固定路线行驶。对性能工程师的好处是更高的资源利用率和更少的瓶颈。我们的工作将转向为 AI 调度器设定高层策略与目标,让它去弄清楚具体细节。
NVIDIA Dynamo’s distributed inference framework, for instance, coordinates request scheduling, KV cache placement, and data movement across GPUs and nodes. It integrates with Kubernetes for inference and disaggregation. In this case, Dynamo’s scheduler would allocate microbatches to different pipeline stages and handle node failures by rerouting requests.例如,NVIDIA Dynamo 的分布式推理框架会协调跨 GPU 与跨节点的请求调度、KV 缓存放置和数据移动。它与 Kubernetes 集成以支持推理与解耦。在这种情况下,Dynamo 的调度器会把微批分配到不同的流水线阶段,并通过重新路由请求来处理节点故障。
And with techniques like weight streaming and activation offloading, the model’s layers can be streamed on demand from host memory to the GPU only when the weights are needed (e.g., during decode.) And this can happen across many nodes and GPUs. This allows hosting parts of a 100-trillion-parameter model on cheaper storage. This helps to seamlessly scale inference.而借助权重流式加载(weight streaming)与激活卸载(activation offloading)等技术,模型的各层可以按需从主机内存流式传输到 GPU,仅在需要权重时才传输(例如在解码期间)。而且这可以跨多个节点和 GPU 进行。这使得可以把一个 100 万亿参数模型的部分内容托管在更便宜的存储上。这有助于无缝地扩展推理。
We could also see AI performance copilots for system operators. LLMs can become part of the infrastructure in a support role. For example, a performance engineer might have an AI assistant they can ask, “How can I speed up my training job?” and get informed suggestions. This sounds fanciful, but it’s plausible when you consider such an assistant could be trained on the accumulated knowledge of thousands of past runs, logs, and tweaks.我们也可能看到面向系统运维人员的 AI 性能副驾驶(copilot)。LLM 可以作为支持角色成为基础设施的一部分。例如,性能工程师可以拥有一个 AI 助手,向其提问「我怎样才能加速我的训练作业?」,并得到有依据的建议。这听起来有些异想天开,但考虑到这样的助手可以基于数千次过往运行、日志和调优所积累的知识来训练,它其实是可行的。
The AI performance copilot might also recognize that your GPU memory usage is low and suggest increasing batch size, or notice that your gradient noise scale is high and suggest a learning rate schedule change. This agent would encapsulate some of the hard-won experience of human experts—making this knowledge available anytime.该 AI 性能副驾驶还可能识别出你的 GPU 显存使用率偏低,并建议增大批大小;或者注意到你的梯度噪声尺度偏高,并建议调整学习率调度。这个智能体将人类专家来之不易的部分经验封装起来——让这些知识随时可用。
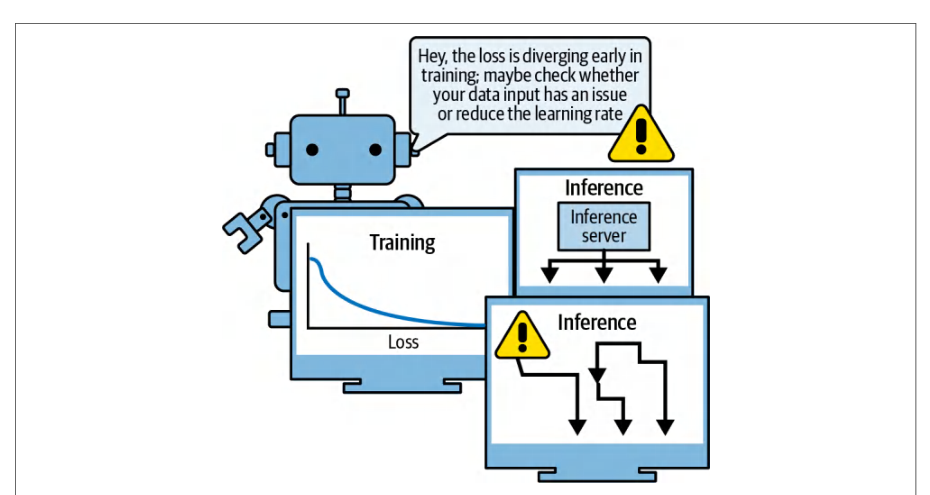
Similarly, AI assistants could watch over training jobs and inference servers and flag anomalies. For instance, the assistant could be monitoring a training job and say, “Hey, the loss is diverging early in training; maybe check if your data input has an issue or reduce the learning rate,” as shown in Figure 20-8.同样,AI 助手可以监视训练作业和推理服务器并标记异常。例如,助手在监控某个训练作业时可以说:「嘿,训练早期损失就在发散;也许检查一下数据输入是否有问题,或者降低学习率」,如图 20-8 所示。
Already, companies like Splunk (now Cisco) and PagerDuty are using AI models on system log data to predict failures and detect anomalies in data centers. It’s recommended that you extend these concepts to use AI workload-specific telemetry.如今,Splunk(现为 Cisco)和 PagerDuty 等公司已经在使用基于系统日志数据的 AI 模型来预测故障并检测数据中心的异常。建议你扩展这些概念,使用针对 AI 工作负载的遥测数据。
In short, AI gives us an always-fresh pair of eyes for every running job and every inference server. It can monitor them, advise them, and adjust in real time. Traditional utilization metrics can be misleading. For instance, a GPU 100% busy on redundant data transfers isn’t productive. These AI-driven schedulers instead aim to maximize goodput and make sure that when a GPU is busy, it’s doing useful neural compute. This directly improves cost efficiency.简而言之,AI 为每个运行中的作业和每个推理服务器提供了一双始终新鲜的「眼睛」。它可以监控它们、为它们提供建议,并实时调整。传统的利用率指标可能具有误导性。例如,一个 100% 忙于冗余数据传输的 GPU 并没有产出。这些 AI 驱动的调度器转而致力于最大化有效吞吐,并确保 GPU 在忙碌时是在做有用的神经计算。这直接提升了成本效率。
In an AI cluster, for instance, you can use a metrics pipeline based on Prometheus to feed an LLM-based assistant that alerts when GPU memory suddenly drops due to either a potential memory leak or data stall. It can even identify likely root causes. This is the kind of tedious work that AI can help automate and run 24/7 without interruption and distraction.例如,在 AI 集群中,你可以使用基于 Prometheus 的指标流水线来为一个基于 LLM 的助手提供输入,当 GPU 显存因潜在的显存泄漏或数据停滞而突然下降时,它就会发出告警。它甚至能识别可能的根本原因。这正是 AI 可以帮助自动化的一类枯燥工作,并且可以 7×24 小时不间断、不受干扰地运行。
Another powerful use of AI is in automated debugging and failure analysis for AI systems. When a training job fails halfway through its three-month run, a human has to read through error logs, device statistics, and perhaps even memory dumps to figure out what went wrong. Was it a hardware fault? A numerical overflow? A networking hiccup?AI 的另一个强大用途是 AI 系统的自动化调试与故障分析。当一个训练作业在其为期三个月的运行中途失败时,人类必须通读错误日志、设备统计信息,甚至可能需要内存转储,才能弄清楚出了什么问题。是硬件故障?数值溢出?还是网络抖动?
In the future, an AI system could digest all that data, including logs, metrics, and alerts, and pinpoint likely causes much faster than they do today. It could say, “Node 42 had 5 ECC memory errors right before the job crashed—likely an HBM memory device or channel issue on the GPU.” Or, “The loss became NaN at iteration 10,000— perhaps an unstable gradient; consider gradient clipping.”未来,AI 系统可以消化所有这些数据——包括日志、指标和告警——并比今天更快地定位可能的原因。它可以说:「42 号节点在作业崩溃前刚好出现了 5 个 ECC 内存错误——很可能是该 GPU 上的 HBM 显存器件或通道问题。」或者,「损失在第 10,000 次迭代时变成了 NaN——也许是梯度不稳定;考虑使用梯度裁剪。」
By learning from many past incidents, the AI troubleshooter could save engineers many hours of detective work. Some large computing sites are already training models on their incident databases to predict failures and suggest fixes.通过从大量过往事件中学习,AI 故障排查器可以为工程师节省大量排查时间。一些大型计算站点已经在用其事件数据库训练模型,以预测故障并建议修复方案。
Taking things a step further, RL can be applied to real-time control of system behavior in ways that fixed algorithms cannot easily match. For example, a power-management RL agent could be trained to continuously tweak frequencies and core allocations to maximize performance per watt in a live system. This agent would learn the optimal policy by analyzing the system in real time.更进一步,强化学习(RL)可以应用于系统行为的实时控制,其方式固定算法难以轻易匹敌。例如,可以训练一个电源管理 RL 智能体,在实时系统中持续调整频率和核心分配,以最大化每瓦性能。该智能体将通过实时分析系统来学习最优策略。
Another example is actively managing memory in AI models. An AI agent could learn which tensors to keep in GPU memory and which to swap to CPU or NVMe— beyond static rules like “swap least recently used.” By observing live access patterns, an AI can manage a cache more efficiently. This is especially effective when patterns are nonobvious or workload-dependent.另一个例子是主动管理 AI 模型中的显存。AI 智能体可以学习哪些张量应保留在 GPU 显存中、哪些应换出到 CPU 或 NVMe——超越「换出最近最少使用」这类静态规则。通过观察实时访问模式,AI 可以更高效地管理缓存。当访问模式不明显或依赖于工作负载时,这种方法尤其有效。
Already, state-of-the-art practitioners are using RL to optimize cache eviction, network congestion control, and more. The complexity of ultrascale systems—with hundreds of interacting components and resources—makes them prime candidates for such learning-based control. There are just too many tunable knobs for a human to stumble upon the best settings in a timely manner—and in a manner that adapts to different workloads in real time.目前,最前沿的实践者已经在使用强化学习(RL)来优化缓存淘汰、网络拥塞控制等。超大规模系统的复杂性——数百个相互作用的组件与资源——使其成为此类基于学习的控制的首要候选对象。可调参数实在太多,人类无法及时找到最佳设置——更无法以实时适应不同工作负载的方式做到这一点。
For the performance engineer, the rise of AI-assisted operational agents means the role will become more about orchestrating and supervising AI-driven processes rather than manually tweaking every single parameter. It’s somewhat analogous to how pilots manage autopilot in a modern aircraft. They still need deep knowledge and oversight, but much of the millisecond-by-millisecond control is automated. The same with someone driving a Tesla in Full Self-Driving (FSD) mode. The driver still needs knowledge and intuition to avoid difficult situations and prevent accidents, but the vehicle’s control is automated by the FSD software.对性能工程师而言,AI 辅助运维智能体的兴起意味着这一角色将更多地转向编排与监督 AI 驱动的流程,而非手动调整每一个参数。这有些类似于飞行员在现代飞机上管理自动驾驶仪:他们仍然需要深厚的知识与监督,但大量逐毫秒的控制已实现自动化。驾驶处于完全自动驾驶(FSD)模式的特斯拉也是如此:驾驶员仍然需要知识与直觉来规避困难情况和防止事故,但车辆的控制由 FSD 软件自动完成。
To guide the AI assistant to manage our cluster efficiently, we simply set the objectives, provide the safety and fairness guardrails, and handle novel situations that the AI hasn’t seen before. Routine optimizations like load balancing, failure recovery, and memory-buffer tuning are handled by the AI. Embracing this paradigm will be important for the future.为了引导 AI 助手高效地管理我们的集群,我们只需设定目标、提供安全与公平的护栏,并处理 AI 此前未曾见过的新情况。负载均衡、故障恢复和内存缓冲区调优等常规优化由 AI 负责。拥抱这一范式对未来至关重要。
向数百万 GPU 集群与 100 万亿参数模型扩展
Scaling Toward Multimillion GPU Clusters and 100-Trillion-Parameter Models
Finally, let’s revisit our quest toward ultrascale, 100-trillion-parameter models. We’ve already broken the trillion-parameter threshold. Now the question is how to scale to tens or even hundreds of trillion-parameter models in the coming years. What does that kind of model demand from our systems, and what innovations are needed to make training such a powerful model feasible? This is where everything we’ve discussed comes together, including efficient hardware, smart software, and clever algorithms. Reaching 100-trillion-parameter models will require using every trick in the book—and then some tricks that may not have been discovered yet. Let’s dive in!最后,让我们重温对超大规模、100 万亿参数模型的探索。我们已经突破了万亿参数的门槛。现在的问题是,未来几年如何扩展到数十甚至数百万亿参数的模型。这样的模型对我们的系统提出了哪些要求,又需要哪些创新才能使训练如此强大的模型变得可行?这正是我们讨论过的一切汇聚之处,包括高效的硬件、智能的软件和巧妙的算法。要达到 100 万亿参数模型,需要用尽所有已知的技巧——还要再加上一些可能尚未被发现的技巧。让我们深入探讨!
On the hardware front, the obvious need is for more memory and more bandwidth— preferably right on the GPU. If you have 100 trillion parameters and you want to train them, you need to store and move an insane amount of data efficiently. The next generations of memory technology will be critical.在硬件方面,显而易见的需求是更多内存和更大带宽——最好就在 GPU 上。如果你有 100 万亿参数并希望训练它们,就需要高效地存储和搬运海量数据。下一代内存技术将至关重要。
High-bandwidth memory (HBM) continues to evolve. HBM3e is used with the Blackwell generation of GPUs, while HBM4 is used in the Rubin generation of GPUs. HBM4 doubles bandwidth per stack again—on the order of 1.6 TB/s per stack. It will also increase capacity per stack to possibly 48 GB or 64 GB per module.高带宽显存(HBM)持续演进。HBM3e 用于 Blackwell 代 GPU,而 HBM4 用于 Rubin 代 GPU。HBM4 再次将每个堆栈的带宽翻倍——约为每堆栈 1.6 TB/s。它还将把每个堆栈的容量提升到每个模块可能 48 GB 或 64 GB。
HBM’s higher capacity and throughput mean that future GPUs could have, say, 8 or 16 stacks of HBM at 64 GB each, which totals 512 GB or 1,024 GB of superfast HBM RAM on a single board. That kind of local HBM capacity holds a lot of model parameters directly on each GPU—significantly reducing the need to swap data in and out.HBM 更高的容量和吞吐量意味着,未来的 GPU 可能配备比如 8 个或 16 个 HBM 堆栈、每个 64 GB,从而在单块板卡上提供 512 GB 或 1,024 GB 的超高速 HBM 显存。这样的本地 HBM 容量可以把大量模型参数直接保存在每块 GPU 上——显著减少数据换入换出的需求。
It’s not hard to see how this enables larger models, higher-bandwidth training runs, and lower-latency inference servers. What used to require sharding across 8 GPUs might fit in one. What required 100 GPUs might fit in 10, and so on.不难看出,这将支撑更大的模型、更高带宽的训练运行以及更低时延的推理服务器。过去需要分片到 8 块 GPU 上的工作负载,现在可能一块 GPU 就能装下;过去需要 100 块 GPU 的,现在可能 10 块就够,依此类推。
In addition to multichip architectures like the Grace Blackwell Superchip, multiple racks of NVL72s each can be linked into one giant cluster to create hundreds of GPUs sharing a unified fast network. Essentially, your cluster behaves like a single mega-GPU from a communication standpoint. This is important for scaling to 100 trillion parameters because it means we can keep adding GPUs to get more total memory and compute—without hitting a communication bottleneck wall. This assumes that NVLink (or similar) continues to scale to those ultrascale sizes.除了 Grace Blackwell Superchip 这类多芯片架构之外,多个 NVL72 机架还可以各自互联成一个巨型集群,从而让数百块 GPU 共享一个统一的快速网络。从通信角度看,你的集群实质上就像一块单一的超级 GPU。这对于扩展到 100 万亿参数至关重要,因为这意味着我们可以持续增加 GPU 来获得更多总内存和算力——而不会撞上通信瓶颈之墙。前提是 NVLink(或类似技术)能够持续扩展到这样的超大规模。
However, hardware alone won’t solve the 100-trillion-parameter challenge. Software and algorithmic innovations are equally, if not more, important. Training a model of that size with naive data parallelism, for example, would be incredibly slow and expensive. Imagine the optimizers having to update 100 trillion weights every step! We will need to lean heavily on techniques that reduce the effective computation. One big area that we explored is low numerical precision. In addition to FP8 and FP4, future hardware might support even lower (1-bit) precision for some parts of the network. Hybrid schemes will likely be critical to use lower precision for most of the model but higher precision for sensitive parts.然而,仅靠硬件无法解决 100 万亿参数的挑战。软件与算法创新同样重要,甚至更为重要。例如,用朴素的数据并行训练如此规模的模型会极其缓慢且昂贵。想象一下优化器每一步都要更新 100 万亿个权重!我们将需要大量依赖能够减少有效计算量的技术。我们探讨过的一个重要方向是低数值精度。除了 FP8 和 FP4,未来硬件可能对网络的某些部分支持更低的(1 位)精度。混合方案很可能至关重要:对模型的大部分使用较低精度,而对敏感部分使用较高精度。
As performance engineers, we should watch for these new capabilities and be ready to use them. To train 100-trillion-parameter models, you very likely need to use low precision for efficiency; otherwise, the workload would be prohibitively slow and expensive.作为性能工程师,我们应当关注这些新能力并准备好加以利用。要训练 100 万亿参数的模型,你很可能必须使用低精度来保证效率;否则,该工作负载将慢得无法接受、成本高得难以承受。
The good news is that hardware and libraries will make this transition relatively seamless. We’re already seeing first-class support for low-precision arithmetic in CUDA through NVIDIA’s Transformer Engine (TE) and Tensor Cores—as well as PyTorch and OpenAI’s Triton, which fully leverage CUDA.好消息是,硬件和库将使这一转变相对平滑。我们已经看到 CUDA 通过 NVIDIA 的 Transformer Engine(TE)和张量核心对低精度算术提供原生支持——PyTorch 和 OpenAI 的 Triton 也是如此,它们充分利用了 CUDA。
Another critical approach is sparsity and conditional computation. We already use sparse activation in models like sparse mixture of experts (MoE), where only a fraction of the model’s parameters are active for a given input. This idea can be generalized so that you don’t always use the full 100 trillion parameters every time. Instead, you use just the parts you need. Models using the MoE architecture are proving to be very capable and efficient. By the time 100-trillion-parameter models arrive, I expect a lot of them will need to be sparsely activated.另一个关键方法是稀疏性和条件计算。我们已经在稀疏专家混合(MoE)等模型中使用稀疏激活,对于给定输入只有一小部分模型参数处于活跃状态。这一思想可以推广,使你不必每次都使用全部 100 万亿参数,而是只使用所需的部分。采用 MoE 架构的模型已被证明能力很强且高效。等到 100 万亿参数的模型出现时,我预计其中很多都需要采用稀疏激活。
As performance engineers, the implication is that throughput will be about matrix multiplication speed as well as the efficiency of MoE conditional routing, caching of expert outputs, and communication patterns for sparse data exchange. This adds complexity but also opportunity. If you can ensure the right experts are on the right devices at the right time to minimize communication, you can drastically accelerate these massive models.作为性能工程师,这意味着吞吐量不仅取决于矩阵乘法速度,还取决于 MoE 条件路由的效率、专家输出的缓存,以及稀疏数据交换的通信模式。这增加了复杂性,但也带来了机会。如果你能确保正确的专家在正确的时间位于正确的设备上,从而最小化通信,你就能大幅加速这些巨型模型。
We should also consider algorithmic efficiency improvements. Optimizers that use less memory could be vital. The traditional Adam optimizer variants typically keep two extra copies of weights for momentum and variance estimates. This effectively triples memory usage. So if you have 100-trillion-parameter weights, you need an extra 200 trillion values to hold the optimizer states! Memory-efficient optimizers like Adafactor and Shampoo help to reduce this overhead.我们还应当考虑算法效率方面的改进。使用更少内存的优化器可能至关重要。传统的 Adam 优化器变体通常会为动量与方差估计各保留一份额外的权重副本。这实际上使显存占用增至三倍。因此,如果你有 100 万亿参数的权重,就需要额外 200 万亿个数值来保存优化器状态!Adafactor 和 Shampoo 等内存高效的优化器有助于降低这一开销。
Techniques like activation checkpointing help to trade compute for memory by recomputing activations instead of storing them. At a 100-trillion-parameter scale, you’d almost certainly be checkpointing aggressively. An even more radical idea is, perhaps, we don’t update all weights on every step. Consider updating subsets of weights in a rotating fashion—similar to how one might not water every plant every day but rotate through them. If done wisely, the model still learns effectively but with less frequent updates per parameter. This reduces the total computational needs of the system.激活检查点(activation checkpointing)等技术通过重新计算激活值而非将其存储下来,以计算换内存。在 100 万亿参数规模下,你几乎必然会激进地使用检查点。一个更激进的想法或许是:我们不必在每一步都更新全部权重。可以考虑以轮转方式更新权重子集——类似于人们不会每天给每株植物浇水,而是轮流浇灌。如果做得明智,模型仍能有效学习,只是每个参数的更新频率更低。这降低了系统的总计算需求。
These kinds of ideas blur into the algorithm design realm, but a performance-aware perspective is useful. We should ask, “Do we really need to do X this often or at this precision?” for every aspect of training and inference. Often the answer is that we can find a cheaper approximation that still works. At a 100-trillion-parameter scale, these approximations can save months of time or millions of dollars.这类想法已经模糊到算法设计的范畴,但性能视角仍然有用。我们应当对训练和推理的每个环节都问一句:“我们真的需要以这样的频率、这样的精度来做 X 吗?”答案往往是:我们可以找到一个仍然有效的更廉价的近似。在 100 万亿参数规模下,这些近似可以节省数月时间或数百万美元。
An often overlooked aspect of ultrascale training is infrastructure and networking. When you’re talking about clusters of 10,000+ GPUs working on one model, the network fabric becomes as important as the GPUs themselves. Ethernet and InfiniBand technologies are advancing in terms of increased throughput and smarter adaptive routing techniques, etc. NVIDIA’s Spectrum-X is an Ethernet-based fabric optimized for AI (e.g,. RoCE, adaptive routing, high bisection bandwidth) that reduces congestion in large-scale training and inference workloads.超大规模训练中一个常被忽视的方面是基础设施与网络。当你谈论由 10,000+ 块 GPU 协同训练一个模型的集群时,网络结构的重要性不亚于 GPU 本身。以太网和 InfiniBand 技术在吞吐量提升和更智能的自适应路由技术等方面不断进步。NVIDIA 的 Spectrum-X 是面向 AI 优化的以太网结构(例如 RoCE、自适应路由、高对分带宽),可减少大规模训练与推理负载中的拥塞。
Performance engineers will need to deeply understand these tiers and ensure that data is in the right place at the right time. The goal will be to simulate a huge memory space that spans GPUs and CPUs so that even if a model doesn’t fit in one machine, it can be treated somewhat transparently by the programmer. Some of this is already possible today with Unified Memory and on-demand paging systems using cudaMem PrefetchAsync() to to pre-stage pages on the target device and avoid page-fault stalls, for instance. But at a 100-trillion-parameter scale, this functionality will really be put to the test.性能工程师需要深入理解这些层级,并确保数据在正确的时间位于正确的位置。目标是模拟一个横跨 GPU 与 CPU 的巨大内存空间,使得即便模型无法装入单台机器,程序员也能以某种程度透明的方式使用它。今天,借助统一内存(Unified Memory)和按需分页系统,其中一部分已经可以实现,例如使用 cudaMem PrefetchAsync() 在目标设备上预先暂存页面,从而避免缺页停顿。但在 100 万亿参数规模下,这一功能将真正经受考验。
It’s not surprising that frontier research labs like xAI, OpenAI, and Microsoft are building large clusters of 1,000,000+ GPUs. At a 100-trillion-parameter scale, you might have one job spanning an entire datacenter’s worth of hardware. Performance engineers must think at datacenter and multidatacenter (global) scale.xAI、OpenAI 和 Microsoft 等前沿研究实验室正在建设 1,000,000+ 块 GPU 的大型集群,这并不令人意外。在 100 万亿参数规模下,一个作业可能就要占用相当于整个数据中心规模的硬件。性能工程师必须从数据中心乃至多数据中心(全球)的尺度来思考。
Last, there’s a socio-technical trend as models—and their required compute—scale up. It may become infeasible for any single team—or even single corporation—to train the biggest models alone. We (hopefully) will see more collaboration and sharing in the AI community to handle these enormous projects. This would be analogous to how big science projects—like particle physics experiments—involve many institutions. Initiatives similar to the now-dissolved Open Collective Foundation, a nonprofit initiative, could help pool AI compute resources to train a 100-trillion-parameter model, which would then be shared with the world.最后,随着模型及其所需算力的规模不断扩大,还出现了一种社会技术层面的趋势。任何单一团队——甚至单一公司——都可能无法独自训练最大的模型。我们(希望)会看到 AI 社区中出现更多协作与共享,以应对这些庞大的项目。这类似于粒子物理实验等大科学项目由众多机构共同参与的方式。类似现已解散的非营利倡议 Open Collective Foundation 的举措,可以帮助汇聚 AI 算力资源来训练一个 100 万亿参数的模型,然后再与全世界共享。
This will require standardizing things like checkpoint formats, codeveloping training code, and thinking about multiparty ownership of models. While this is not a performance issue per se, it will influence how we build large AI systems. We’ll need to make them even more fault-tolerant and easily snapshot-able to share partial results. As an engineer, you might end up optimizing for pure speed, as well as reproducibility and interoperability. This allows different teams to work on different parts of the training and inference workflow smoothly and efficiently.这将要求对检查点格式等内容进行标准化、协同开发训练代码,并思考模型的多方所有权问题。虽然这本身并不是性能问题,但它会影响我们构建大型 AI 系统的方式。我们需要让这些系统具备更强的容错能力,并能够方便地生成快照以共享部分结果。作为一名工程师,你最终可能既要针对纯粹的速度进行优化,也要兼顾可复现性和互操作性。这使得不同团队能够顺畅、高效地处理训练与推理工作流中的不同部分。
Reaching 100-trillion-parameter models will require holistic, full-stack innovations. There’s no single solution to this challenge. Instead, every piece of the puzzle must improve. Hardware needs to be faster and hold more data. Software needs to self-optimize more—and use resources more efficiently through compilers, AI assistants, and real-time adaptation. Algorithms need to be clever about not avoiding unnecessary work through sparsity, lower precision, and better optimizers.要达到 100 万亿参数模型,需要整体性的、全栈式的创新。这一挑战没有单一的解决方案。相反,拼图的每一块都必须改进。硬件需要更快,并能容纳更多数据。软件需要更多地自我优化——通过编译器、AI 助手和实时自适应来更高效地使用资源。算法需要更巧妙地避免不必要的工作——通过稀疏性、更低精度和更好的优化器。
The role of the performance engineer will be to integrate all these advancements into a coherent workflow. It’s like assembling a high-performance racing car. The engine, tires, aerodynamics, and driver skill all have to work in unison. If we do it right, what seems impossible now—e.g., 100 trillion parameters trained without breaking the bank—will become achievable.性能工程师的职责将是把所有这些进步整合成一个连贯的工作流。这就像组装一辆高性能赛车。发动机、轮胎、空气动力学和车手技术都必须协同发挥作用。如果我们做对了,那么现在看似不可能的事情——例如在不至于倾家荡产的前提下训练 100 万亿参数——将变得可以实现。
It wasn’t long ago that 1-trillion-parameter models sounded crazy. Yet today, this scale has been demonstrated by open-weight models like Moonshot AI’s Kimi K2 (1-trillion-parameter MoE, 32 billion parameters active per token) and others. At this rate of progress, and with AI-assisted human ingenuity, we will conquer the next milestones and orders of magnitude in a very short amount of time.不久之前,1 万亿参数模型听起来还很疯狂。然而今天,这一规模已由 Moonshot AI 的 Kimi K2(1 万亿参数的 MoE,每个 token 激活 320 亿参数)等开放权重模型所验证。按照这样的进步速度,再加上 AI 辅助的人类智慧,我们将在很短的时间内攻克接下来的里程碑和数量级。
关键要点
Key Takeaways
The following points summarize the best practices and emerging trends discussed in this chapter’s case studies and hypothetical future states of ultrascale AI systems performance engineering:以下几点总结了本章案例研究以及超大规模 AI 系统性能工程假设性未来状态中所讨论的最佳实践与新兴趋势:
- Codesigned hardware and software optimizations软硬件协同设计的优化
- Performance improvements in LLMs are truly achieved by breakthroughs coming from tightly integrated hardware/software codesign innovations.LLM 的性能提升真正依靠的是紧密集成的软硬件协同设计创新所带来的突破。
- AI-assisted coding and performance optimizationsAI 辅助的编码与性能优化
- Google DeepMind, NVIDIA, and Predibase have demonstrated AI-assisted discovery and optimization for core kernels such as matrix multiplication and attention. These efforts show that AI can generate, test, and refine low-level GPU code and produce significant speedups with very little human intervention.Google DeepMind、NVIDIA 和 Predibase 已经展示了针对矩阵乘法和注意力等核心内核的 AI 辅助发现与优化。这些工作表明,AI 能够生成、测试并改进底层 GPU 代码,并在极少人工干预的情况下带来显著的加速。
- Strategies for 100-trillion-parameter models面向 100 万亿参数模型的策略
- Training models with 100 trillion parameters will require a blend of aggressive quantization, multidimensional parallelism (data, pipeline, tensor, expert, and context/sequence), and careful orchestration of inter-rack communication. This stresses that future AI scaling depends on both hardware capabilities and the ingenuity of software-level scheduling.训练 100 万亿参数的模型,需要将激进的量化、多维并行(数据、流水线、张量、专家以及上下文/序列并行)与跨机架通信的精细编排结合起来。这凸显出未来 AI 的扩展既取决于硬件能力,也取决于软件层面调度的巧思。
- Exponential compute infrastructure scaling指数级的算力基础设施扩展
- Next-generation AI data centers are being designed to provide orders-ofmagnitude increases in computational capacity. These facilities will train AI models with compute budgets far beyond today’s levels. This enables training runs that use 100 to 1,000 times the FLOPS used in current systems.下一代 AI 数据中心正被设计为提供数量级提升的计算容量。这些设施将以远超当今水平的算力预算来训练 AI 模型。这使得训练运行能够使用当前系统 100 到 1,000 倍的 FLOPS。
- Evolving AI models and agents不断演进的 AI 模型与智能体
- Future models will be self-improving systems capable of generating and optimizing code, continuously updating their weights with fresh data, and even rewriting their own code. This perpetual cycle of learning and refinement will reduce the time between breakthroughs and create a virtual workforce that outperforms human teams in research and R&D tasks.未来的模型将是能够生成并优化代码、用新数据持续更新自身权重、甚至重写自身代码的自我改进系统。这种学习与精炼的永续循环将缩短突破之间的时间间隔,并创造出在研究以及研发任务中超越人类团队的虚拟劳动力。
- AI-assisted real-time troubleshootingAI 辅助的实时故障排查
- In addition to scheduling, AI copilots will monitor system logs and training/ inference workloads to detect anomalies quickly—including spikes in accuracy除调度之外,AI 副驾驶还将监控系统日志以及训练/推理工作负载,以快速检测异常——包括准确率
loss or number of hardware errors. These copilots can help automate debugging, perform failure analysis, and even learn optimal configurations through reinforcement learning. These help to maximize performance per watt and per unit time.损失或硬件错误数量的激增。这些副驾驶可以协助实现调试自动化、执行故障分析,甚至通过强化学习习得最优配置。这些都有助于最大化每瓦以及每单位时间的性能。
- Performance-per-watt, a critical metric每瓦性能:一项关键指标
- All of these codesign efforts ultimately aim to maximize throughput per unit cost. Specifically, the goal is to process and generate more tokens per second per dollar per watt of power. For example, the Grace Blackwell NVL72 rack system dramatically improves performance-per-watt 25× over the prior Hopper generation. This directly translates to lower cost per token than previous-generation GPU clusters.所有这些协同设计(codesign)努力最终都旨在最大化单位成本的吞吐量。具体而言,目标是在每美元、每瓦功耗下每秒处理和生成更多 token。例如,Grace Blackwell NVL72 机架系统将每瓦性能相比上一代 Hopper 大幅提升 25 倍。这直接转化为比前几代 GPU 集群更低的每 token 成本。
结语
Conclusion
This book marks a turning point for the field of AI systems performance engineering. NVIDIA’s tight integration of CPU and GPU into superchip modules like Grace Hopper and Grace Blackwell (and upcoming Vera Rubin and Feynman) has achieved new levels of compute efficiency and scale. Under the hood, the GPUs use highly optimized Tensor Cores—as well as a transformer engine optimized for LLM computation fundamentals.本书标志着 AI 系统性能工程领域的转折点。NVIDIA 将 CPU 与 GPU 紧密集成到 Grace Hopper 和 Grace Blackwell(以及即将推出的 Vera Rubin 和 Feynman)等超级芯片模块中,实现了新的计算效率与规模水平。在底层,GPU 使用高度优化的张量核心,以及针对 LLM 计算基础优化的 transformer 引擎。
Supercomputing systems like the NVIDIA GB200/GB300 NVL72, which links 72 GPUs into a single processing unit (NVLink domain), set the rack and data center communication foundation using technologies like NVLink, NVSwitch, and SHARP. These provide low-latency, real-time inference for multitrillion-parameter models.像 NVIDIA GB200/GB300 NVL72 这样的超级计算系统将 72 个 GPU 连接为单一处理单元(NVLink 域),并利用 NVLink、NVSwitch 和 SHARP 等技术奠定机架与数据中心的通信基础。这些技术为数万亿参数模型提供低时延的实时推理。
On the software side, tools like vLLM, SGLang, NVIDIA Dynamo, and TensorRT-LLM improve scheduling and resource usage across large inference clusters. This includes techniques like in-flight batching, paged KV cache, and (separating the prompt prefill stage from the generation decode stage onto different resource pools for efficiency.) These help to reduce tail latency and improve throughput per watt.在软件方面,vLLM、SGLang、NVIDIA Dynamo 和 TensorRT-LLM 等工具改善了大型推理集群中的调度与资源使用。这包括在途批处理(in-flight batching)、分页 KV 缓存,以及(将提示词预填充阶段与生成解码阶段分离到不同资源池以提升效率)等技术。这些有助于降低尾部时延并提升每瓦吞吐量。
These examples prove the power of codesign, in which hardware, software, and algorithms evolve together. This partnership rooted in mechanical sympathy helps to reduce training times, improve inference performance, and lower operational expen-ses. This is needed to produce measurable returns on investment for today’s fast-improving and capital-intensive AI systems.这些示例证明了协同设计的力量——硬件、软件与算法共同演进。这种植根于机械同理心(mechanical sympathy)的伙伴关系有助于缩短训练时间、提升推理性能并降低运营开支。对于当今快速进步且资本密集的 AI 系统而言,这是产生可衡量的投资回报所必需的。
Additionally, AI-driven coding and algorithm agents from Google DeepMind, NVI-DIA, and Predibase show how AI can help optimize AI. As models and systems become too complex for manual tuning, automation can handle routine optimizations and free human engineers to focus on higher-level optimizations and system designs.此外,来自 Google DeepMind、NVIDIA 和 Predibase 的 AI 驱动的编码与算法智能体展示了 AI 如何帮助优化 AI。随着模型与系统变得过于复杂而难以手动调优,自动化可以处理常规优化,并解放人类工程师去专注于更高层次的优化与系统设计。
We’re shifting from brute-force scaling to smart scaling: doing more useful work per cycle, squeezing every ounce of performance from new hardware features, and letting AI assistants manage the details. Performance engineers will move up the stack, becoming architects of global compute ecosystems that balance efficiency, reliability, and sustainability.我们正从暴力式扩展转向智能式扩展:每个周期完成更多有用的工作,从新硬件特性中榨取每一分性能,并让 AI 助手管理细节。性能工程师将向技术栈上层迁移,成为平衡效率、可靠性与可持续性的全球计算生态系统的架构师。
Our role as an AI systems performance engineer will expand beyond single-node kernels to system-wide and facility-wide optimization. We’ll rely on our intuition to spot bottlenecks—like a slow all-reduce pattern—and then guide our AI tools to fix them. Meanwhile, we’ll keep learning, since the pace of hardware and algorithmic innovation will only accelerate.作为 AI 系统性能工程师,我们的职责将从单节点内核扩展到系统级乃至设施级的优化。我们将依靠直觉发现瓶颈——例如缓慢的全归约模式——然后引导 AI 工具去修复它们。与此同时,我们要持续学习,因为硬件与算法创新的步伐只会越来越快。
In conclusion, to stay relevant and competitive, you should build a strong foundation in AI systems performance fundamentals, stay curious, experiment with new hardware and software advancements, trust AI recommendations, and be ready to adapt as the landscape changes into quantum and beyond. And just think—in an era of democratized research, one-click-accessible AI supercomputers, and accessible multitrillion-parameter models, you could be one of the enablers of the next big superintelligence breakthrough!总之,为保持相关性与竞争力,你应当在 AI 系统性能基础原理上打下扎实根基,保持好奇,尝试新的硬件与软件进展,信任 AI 的建议,并随时准备适应格局向量子及更远方向的变化。想一想——在研究民主化、一键可用的 AI 超级计算机以及可获取的数万亿参数模型的时代,你或许就是下一次超级智能重大突破的推动者之一!