AI 系统硬件概述
Chapter 2. AI System Hardware Overview
本章目录
- CPU 与 GPU 超级芯片
- NVIDIA Grace CPU
- NVIDIA Blackwell “双裸片” GPU
- NVIDIA GPU 张量核心与 Transformer 引擎
- 流多处理器、线程与线程束
- 超大规模网络:将多块 GPU 视为一体
- NVLink 与 NVSwitch
- 多 GPU 编程
- 使用 NVIDIA SHARP 进行网络内聚合
- 多机架与存储通信
- 预集成机架设备
- 共封装光学:网络硬件的未来
- 计算密度与功耗需求
- 液冷与风冷
- 实践中的性能监控与利用率
- 共享与调度
- 硬件升级的投资回报率
- 未来展望:NVIDIA 路线图
- Blackwell Ultra 与 Grace Blackwell Ultra
- Vera Rubin 超级芯片 (2026)
- Rubin Ultra 与 Vera Rubin Ultra(2027)
- Feynman GPU(2028)与每年翻倍
- 关键要点
- 结语
Imagine condensing a supercomputer’s worth of AI hardware into a single rack. NVIDIA’s latest architecture does exactly that. In this chapter, we dive into how NVIDIA fused CPUs and GPUs into powerful superchips and then wired dozens of them together with ultrafast interconnects to create an AI supercomputer-in-a-box. We’ll explore the fundamental hardware building blocks—the Grace CPU and Blackwell GPU—and see how their tight integration and enormous memory pool make life easier for AI engineers.想象将相当于超级计算机的 AI 硬件浓缩到单个机架中。NVIDIA 的最新架构正是如此。在本章中,我们将深入探讨 NVIDIA 如何将 CPU 和 GPU 融合为强大的*超级芯片(Superchip)*,然后用超高速互连将数十个这样的芯片连接起来,打造一台盒式 AI 超级计算机。我们将探索基本硬件构建模块——Grace CPU 和 Blackwell GPU——并了解它们的紧密集成和巨大内存池如何让 AI 工程师的工作更轻松。
Then we’ll expand outward to the networking fabric that links 72 of these GPUs as if they were one machine. Along the way, we’ll highlight the leaps in compute performance, memory capacity, and efficiency that give this system its superpowers. By the end, you’ll appreciate how this cutting-edge hardware enables training and serving multi-trillion-parameter models that previously seemed impossible.随后,我们将向外扩展到网络结构,它将 72 个这样的 GPU 连接起来,仿佛它们是一台机器。在此过程中,我们将重点介绍赋予该系统超能力的计算性能、显存容量和效率方面的飞跃。最后,你将体会到这种尖端硬件如何支持训练和服务此前看似不可能的数万亿参数模型。
CPU 与 GPU 超级芯片
The CPU and GPU Superchip
NVIDIA’s approach to scaling AI starts at the level of a single, combined CPU + GPU superchip module. Beginning with the Hopper generation, NVIDIA started packaging an ARM-based CPU together with one or more GPUs in the same unit, tightly linking them with a high-speed interface. The result is a single module that behaves like a unified computing engine.NVIDIA 扩展 AI 的方法从单个组合的 CPU + GPU 超级芯片模块开始。从 Hopper 一代开始,NVIDIA 开始将基于 ARM 的 CPU 与一个或多个 GPU 封装在同一单元中,并通过高速接口将它们紧密连接。其结果是一个表现得像统一计算引擎的单个模块。
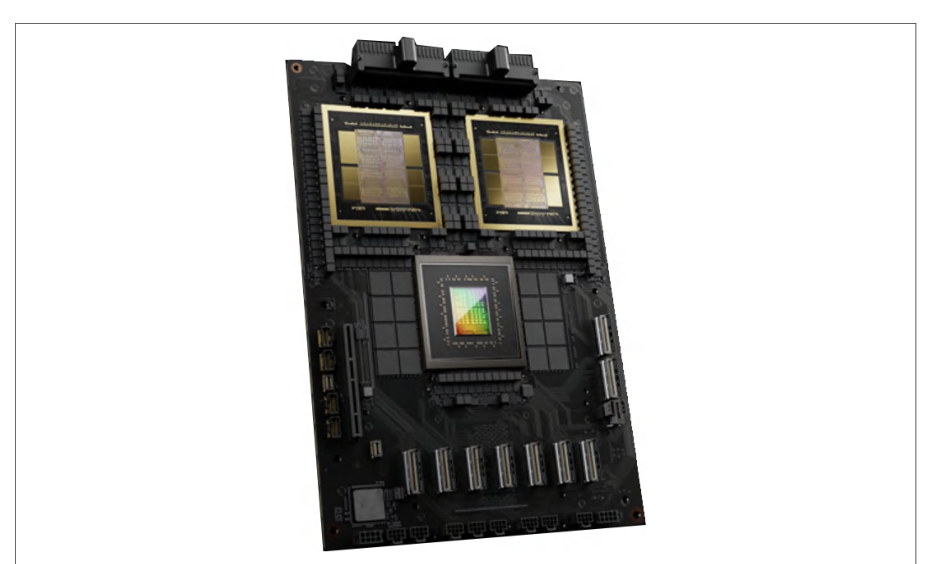
The first implementation of the superchip was Grace Hopper (GH200), which pairs one Grace CPU with one Hopper GPU. Next came the Grace Blackwell (GB200) Superchip, which pairs one Grace CPU with two Blackwell GPUs in the same package. The Grace CPU sits in the center of the module, surrounded by two Blackwell GPU dies, as shown in Figure 2-1.超级芯片的首个实现是 Grace Hopper(GH200),它将一个 Grace CPU 与一个 Hopper GPU 配对。接下来是 Grace Blackwell(GB200)超级芯片,它将一个 Grace CPU 与两个 Blackwell GPU 封装在同一封装中。Grace CPU 位于模块中央,周围环绕着两个 Blackwell GPU 裸片,如图 2-1 所示。
In a traditional system, the CPU and GPU have separate memory pools and communicate over a relatively slow bus (like PCIe), which means data has to be copied back and forth. NVIDIA’s superchip eliminates that barrier by connecting the CPU and GPUs with a custom high-speed link called NVLink-C2C (chip-to-chip).在传统系统中,CPU 和 GPU 拥有独立的内存池,并通过相对较慢的总线(如 PCIe)通信,这意味着数据必须来回复制。NVIDIA 的超级芯片通过名为 NVLink-C2C(芯片到芯片)的定制高速链路连接 CPU 和 GPU,从而消除了这一障碍。
NVLink-C2C provides up to ~900 GB/s between the Grace CPU and the Blackwell GPUs in GB200 Superchips. By comparison, PCIe Gen5 x16 (Blackwell B200) is about 64 GB/s per direction, and PCIe Gen6 x16 (Blackwell Ultra B300) is about 128 GB/s per direction. NVLink-C2C’s interconnect speed is an order of magnitude faster than typical PCIe. And, importantly, it is cache-coherent.在 GB200 超级芯片中,NVLink-C2C 在 Grace CPU 与 Blackwell GPU 之间提供高达约 900 GB/s 的带宽。相比之下,PCIe Gen5 x16(Blackwell B200)每个方向约为 64 GB/s,PCIe Gen6 x16(Blackwell Ultra B300)每个方向约为 128 GB/s。NVLink-C2C 的互连速度比典型 PCIe 快一个数量级。而且,重要的是,它具有缓存一致性。
Cache coherency means the CPU and GPU share a coherent, unified memory architecture. As such, they always see the same values. In practice, the Grace CPU and Blackwell GPUs on a superchip can all access one another’s memory directly as if it were one huge memory pool. The GPU can read or write data stored in the CPU’s memory, and vice versa, without needing explicit copies. This unified memory architecture is often called Unified CPU-GPU Memory or Extended GPU Memory (EGM) by NVIDIA, and it effectively blurs the line between CPU memory and GPU memory.缓存一致性意味着 CPU 和 GPU 共享一致的统一内存架构。因此,它们始终看到相同的值。实际上,超级芯片上的 Grace CPU 和 Blackwell GPU 都可以直接访问彼此的内存,仿佛它们是一个巨大的内存池。GPU 可以读取或写入存储在 CPU 内存中的数据,反之亦然,而无需显式复制。NVIDIA 通常将这种统一内存架构称为统一 CPU-GPU 显存或扩展 GPU 显存(EGM),它有效地模糊了 CPU 内存与 GPU 显存之间的界限。
Each Grace Blackwell Superchip carries a tremendous amount of memory. The Grace CPU comes with hundreds of gigabytes of LPDDR5X DRAM attached, and each Blackwell GPU has its own high-speed, high-bandwidth memory (HBM) stacks.每个 Grace Blackwell 超级芯片都承载大量内存。Grace CPU 附带数百 GB 的 LPDDR5X DRAM,每个 Blackwell GPU 都有自己高速、高带宽内存(HBM)堆栈。
In the GB200 Superchip, the Grace CPU provides up to ~480 GB of LPDDR5X at up to ~500 TB/s, and the two Blackwell GPUs together contribute up to ~384 GB of HBM3e memory (192 total GB per GPU). In total, a GB200 Superchip exposes roughly ~900 GB of memory of coherent, unified memory accessible by the GPUs and CPUs in a unified address space.在 GB200 超级芯片中,Grace CPU 提供高达约 480 GB 的 LPDDR5X,带宽高达约 500 TB/s,两个 Blackwell GPU 合计提供高达约 384 GB 的 HBM3e 显存(每个 GPU 总计 192 GB)。总体而言,GB200 超级芯片提供约 900 GB 的一致统一内存,GPU 和 CPU 可在统一地址空间中访问。
To put it simply, each superchip has nearly a terabyte of fast, unified memory at its disposal. This is a game changer for giant AI models. In older systems, a single GPU might be limited to < 100 GB of memory, which meant models larger than that had to be partitioned or offloaded to slower storage. Here, a GPU can seamlessly utilize the CPU’s memory as an extension.简而言之,每颗超级芯片(superchip)都拥有近 1 TB 的快速统一内存可供调用。这对超大规模 AI 模型而言是颠覆性的改变。在较早的系统中,单块 GPU 的内存可能被限制在 < 100 GB,超过这一规模的模型就必须进行划分或卸载到较慢的存储上。而在这里,GPU 可以无缝地将 CPU 的内存用作扩展。
If a neural network layer or a large embedding table doesn’t fit in the GPU’s local HBM, it can reside in the CPU’s memory, and the GPU will still be able to work with it across NVLink-C2C. From a programmer’s perspective, the unified virtual address space and coherence simplify correctness. However, for performance, one should explicitly manage placement and memory movement using techniques such as asynchronous prefetch and staged pipelines. Accessing LPDDR5X using NVLink-C2C has higher latency and roughly an order-of-magnitude lower bandwidth than accessing HBM directly.如果某个神经网络层或大型嵌入表(embedding table)无法完全放入 GPU 本地的 HBM,它可以驻留在 CPU 的显存中,GPU 仍能通过 NVLink-C2C 对其进行操作。从程序员的角度看,统一虚拟地址空间和一致性(coherence)让正确性更容易保证。但在性能方面,应当显式地管理数据放置与显存移动,采用异步预取和分阶段流水线等技术。通过 NVLink-C2C 访问 LPDDR5X 比直接访问 HBM 时延更高,带宽大约低一个数量级。
GPU memory is still much faster and closer to the GPU cores than CPU memory— you can think of the CPU memory as a large but somewhat slower extension. Accessing data in LPDDR5X isn’t as quick as HBM on the GPU. It’s on the order of 10× lower bandwidth and higher latency. A smart runtime will keep the most frequently used data in HBM and use the CPU’s LPDDR5X for overflow or less speed-critical data. The key point is that overflow no longer requires going out to NVMe SSD or across a network.GPU 显存仍然比 CPU 内存快得多,也距离 GPU 核心更近——你可以把 CPU 内存看作一个大容量但稍慢的扩展。访问 LPDDR5X 中的数据不如访问 GPU 上的 HBM 那样快,带宽大约低 10 倍,时延也更高。智能的运行时系统会把最常用的数据保留在 HBM 中,而将 CPU 的 LPDDR5X 用于存放溢出数据或对速度要求不那么苛刻的数据。关键在于,溢出数据不再需要写到 NVMe SSD 或跨越网络传输。
The GPU can fetch from CPU RAM at perhaps 900 GB/s (450 GB/s per direction), which, while slower than HBM, is much faster than fetching from NVMe SSD storage. This flexibility is critical, as it means a model that is, say, 500 GB in size (too large for a single GPU’s HBM) can still be placed entirely within one superchip module with access to a combined 192 (180 usable) GB in HBM and ~500 GB of CPU memory. This model can run without partitioning the model across multiple GPUs. The GPU would just transparently pull the extra data from CPU memory when needed.GPU 从 CPU 内存读取数据的速率约为 900 GB/s(每个方向 450 GB/s),这虽然慢于 HBM,却远快于从 NVMe SSD 存储读取。这种灵活性至关重要,因为这意味着一个例如 500 GB 大小的模型(对单块 GPU 的 HBM 而言太大)仍然可以完整地放置在一个超级芯片模块内,该模块拥有合计 192 GB(可用 180 GB)的 HBM 以及约 500 GB 的 CPU 内存。这一模型无需跨多块 GPU 进行划分即可运行。GPU 只需在需要时透明地从 CPU 内存中拉取额外数据。
In essence, memory size ceases to be a hard limit for fitting ultralarge models, as long as the total model fits within the combined CPU + GPU memory of the superchip. Many researchers have faced the dreaded “out of memory” errors when models don’t fit on a GPU—this architecture is designed to push that boundary out significantly.从本质上讲,只要整个模型能够装入超级芯片的 CPU + GPU 总显存,显存容量就不再是容纳超大规模模型的硬性限制。许多研究人员都曾遭遇过模型装不进 GPU 时令人头疼的“显存不足”(out of memory)错误——这一架构的设计目的就是显著地拓展这一边界。
NVIDIA Grace CPU
NVIDIA Grace CPU
The Grace CPU itself is no sloth. It’s an ARM Neoverse V2 CPU custom-designed by NVIDIA for bandwidth and efficiency. Its job in the superchip is to handle general-purpose tasks, preprocess and feed data to the GPUs, and manage the mountain of memory attached to it. It runs at a modest clock speed but makes up for it with huge memory bandwidth—up to ~500 GB/s to its LPDDR5X memory—and lots of cache, including over 100 MB of L3 cache.Grace CPU 本身也毫不逊色。它是一款由 NVIDIA 为带宽和能效而定制设计的 ARM Neoverse V2 CPU。它在超级芯片中的职责是处理通用任务、对数据进行预处理并供给 GPU,以及管理挂载在其上的海量内存。它的时钟频率并不高,但凭借巨大的显存带宽——访问其 LPDDR5X 内存最高可达约 500 GB/s——以及大量缓存(包括超过 100 MB 的 L3 缓存)加以弥补。
The philosophy is that the CPU should never become a bottleneck when shoveling data to the GPUs. It can stream data from storage or perform on-the-fly data transformations like tokenization or data augmentation—feeding the GPUs through NVLink-C2C very efficiently. If part of your workload is better on the CPU, the Grace cores can tackle that and make the results immediately accessible by the GPUs.其设计理念是:在向 GPU 输送数据时,CPU 绝不应成为瓶颈。它可以从存储中流式读取数据,或执行分词(tokenization)、数据增强等即时数据变换——通过 NVLink-C2C 非常高效地为 GPU 供给数据。如果你的工作负载中有一部分更适合在 CPU 上运行,Grace 核心可以承担这部分任务,并使 GPU 能够立即访问其结果。
This is a harmonious coupling in which the CPU extends the GPU’s capabilities in areas where GPUs are weaker, like random memory accesses or control-heavy code. And the GPUs accelerate the number-crunching where CPUs can’t keep up.这是一种和谐的耦合:CPU 在 GPU 相对较弱的领域(例如随机显存访问或控制流密集的代码)扩展了 GPU 的能力,而 GPU 则在 CPU 力不从心的数值计算方面提供加速。
The low-latency link between the CPU and GPUs means they can trade tasks without the usual overhead. For example, launching a GPU kernel from the CPU can happen much faster than on a traditional system, since the command doesn’t have to traverse a slow PCIe bus. The CPU and GPU are essentially on the same board. This is similar to calling a fast local function versus a slower remote function. Next, let’s talk about the Blackwell GPU, the brute-force engine of the superchip.CPU 与 GPU 之间的低时延链路意味着二者可以在没有常规开销的情况下交接任务。例如,从 CPU 启动 GPU 内核的速度可以比传统系统快得多,因为命令无需经过缓慢的 PCIe 总线。CPU 与 GPU 实际上位于同一块电路板上。这类似于调用快速的本地函数与较慢的远程函数之间的差别。接下来,让我们谈谈 Blackwell GPU——这款超级芯片的蛮力引擎。
NVIDIA Blackwell “双裸片” GPU
NVIDIA Blackwell “Dual-Die” GPU
Blackwell is NVIDIA’s codename for this GPU generation, and it represents a significant leap over the previous Hopper (H100) GPUs in both compute horsepower and memory. The Blackwell B200 and B300 “Ultra” GPU are not single chips. Instead, they use a multichip module (MCM) design with two GPU dies placed in a single module. As such, Blackwell is called a dual-die GPU (see Figure 2-2).Blackwell 是 NVIDIA 对这一代 GPU 的代号,它在算力与内存两方面都较前代 Hopper(H100)GPU 实现了显著飞跃。Blackwell B200 与 B300 “Ultra” GPU 并非单一芯片,而是采用多芯片模块(MCM)设计,将两个 GPU 裸片置于同一模块内。因此,Blackwell 被称为 双裸片(dual-die)GPU(见图 2-2)。
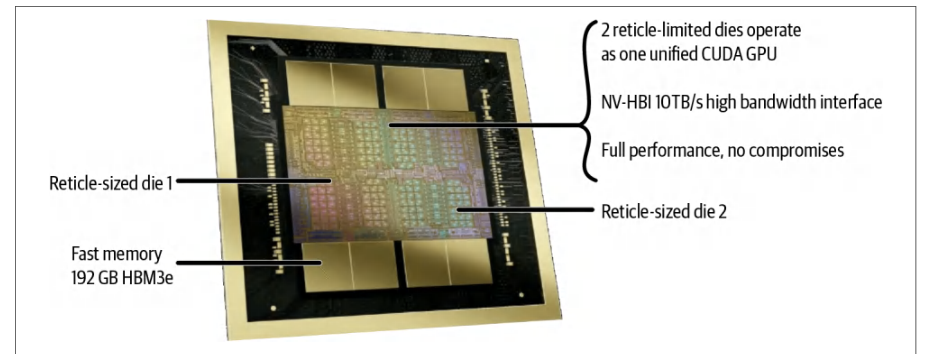
This chiplet approach splits what would normally be one enormous GPU into smaller GPU dies—linking them together with a superfast, on-package die-to-die interconnect. Why do this? Because a single monolithic die is limited by manufacturing because there’s a limit to how large you can make a chip on silicon. By combining two physical GPU dies into a single module, NVIDIA can double the total transistor budget for the module.这种 芯粒(chiplet)方法将原本会是一个庞大 GPU 的整体拆分为更小的 GPU 裸片,并通过超高速的封装内裸片间互连将它们连接在一起。为什么要这样做?因为单片式裸片(monolithic die)受制造工艺限制——在硅片上所能制造的芯片尺寸存在上限。通过将两个物理 GPU 裸片组合到单一模块中,NVIDIA 可以将该模块的晶体管总预算翻倍。
For the Blackwell B200 MCM, each GPU die has about 104 billion transistors and 96 GB HBM3e memory. The combined GPU module has around 208 billion transistors and 192 (180 usable) GB total memory per B200 GPU. By comparison, the Hopper H100 GPU had ~80 billion transistors and 80 GB HBM3 (versus Blackwell’s HBM3e) memory. As such, Blackwell’s B200 more than doubles transistor count and ~2.4× increases memory size.对于 Blackwell B200 MCM,每个 GPU 裸片拥有约 1040 亿个晶体管和 96 GB HBM3e 显存。组合后的 GPU 模块拥有约 2080 亿个晶体管,每块 B200 GPU 的总显存为 192 GB(可用 180 GB)。相比之下,Hopper H100 GPU 拥有约 800 亿个晶体管和 80 GB HBM3 显存(而 Blackwell 采用的是 HBM3e)。因此,Blackwell B200 的晶体管数量增加了一倍以上,显存容量提升约 2.4 倍。
Blackwell’s two GPU dies communicate using a specialized, high-speed 10 TB/s dieto-die interconnect called NV-HBI (High-Bandwidth Interface). This lets the two GPU dies in the module function as a single unified GPU. The software layer running on top of it sees only a single GPU.Blackwell 的两个 GPU 裸片通过名为 NV-HBI(High-Bandwidth Interface,高带宽接口)的专用高速裸片间互连进行通信,速率达 10 TB/s。这使得模块内的两个 GPU 裸片能够作为单一统一 GPU 工作。在其上运行的软件层看到的只是一块 GPU。
From the system’s perspective, a Blackwell GPU is one single module, or device, with a large pool of memory (192 [180 usable] GB HBM3e) and a ton of execution units, but under the hood it’s two chips working in tandem. NVIDIA’s software and scheduling ensure that work is balanced across the two GPU dies and memory accesses are coherent. This allows developers to largely ignore this complexity, as they appear as one GPU, as NVIDIA intended.从系统的视角来看,Blackwell GPU 是单一模块(即单一设备),拥有大容量显存(192 GB,可用 180 GB,HBM3e)和大量执行单元,但其内部实际上是两个芯片在协同工作。NVIDIA 的软件与调度机制确保工作在两个 GPU 裸片之间保持均衡,且显存访问保持一致性。这使得开发者可以在很大程度上忽略这种复杂性——正如 NVIDIA 所期望的,它们呈现为一块 GPU。
Each Blackwell B200 GPU module has 192 (180 usable) GB of HBM3e memory combined across the two GPU dies (96 GB each) and divided into 8-Hi stacks. An 8-Hi HBM3e stack is built by vertically stacking eight DRAM dies—each 3 GB—for a total of 24 GB per stack.每个 Blackwell B200 GPU 模块在两个 GPU 裸片上合计拥有 192 GB(可用 180 GB)HBM3e 显存(每个裸片 96 GB),并划分为 8-Hi 堆栈。一个 8-Hi HBM3e 堆栈由垂直堆叠的八个 DRAM 裸片构成——每个 3 GB——每个堆栈总计 24 GB。
The B200 GPU uses eight of these stacks (four per die) to provide 192 (180 usable) GB (192 GB = 8 stacks × 24 GB per stack) of on-package memory. This increases the per-GPU stack count and capacity compared to the previous generation Hopper GPUs—and gives more headroom for model parameters, activations, gradients, and input data.B200 GPU 使用八个这样的堆栈(每个裸片四个),提供 192 GB(可用 180 GB)的封装内内存(192 GB = 8 个堆栈 × 每堆栈 24 GB)。与前代 Hopper GPU 相比,这增加了每块 GPU 的堆栈数量与容量——并为模型参数、激活值、梯度和输入数据提供了更充裕的空间。
The memory is also faster, as Blackwell’s B200 HBM3e has an aggregate bandwidth up to roughly 8 TB/s per GPU. For comparison, the Hopper uses the previous generation HBM3, which delivers ~3.35 TB/s per GPU. As such, Blackwell’s memory bandwidth throughput is roughly 2.4× higher than Hopper’s.显存速度也更快,因为 Blackwell 的 B200 所采用的 HBM3e 每个 GPU 的总带宽高达约 8 TB/s。相比之下,Hopper 采用上一代 HBM3,每个 GPU 仅提供约 3.35 TB/s。因此,Blackwell 的显存带宽吞吐量约为 Hopper 的 2.4 倍。
Feeding data at 8 terabytes per second, the Blackwell GPU cores are kept busy crunching on huge matrices without frequently stalling to wait for data. NVIDIA also beefed up on-chip caching, as Blackwell has a total of 126 MB of L2 cache (63 MB per die). This cache is a small but ultrafast memory on the GPU that holds recently used data.以每秒 8 TB 的速率供给数据,Blackwell 的 GPU 核心得以持续忙碌地处理巨型矩阵,而无需频繁停顿等待数据。NVIDIA 还强化了片上缓存:Blackwell 拥有总计 126 MB 的 L2 缓存(每个裸片 63 MB)。该缓存是 GPU 上一种容量小但速度极快的存储器,用于保存最近使用过的数据。
By increasing the L2 cache size by more than 2.5× compared to Hopper’s 50 MB L2 cache, Blackwell can keep more of the neural network weights or intermediate results on chip, avoiding extra trips out to HBM. This again helps ensure the GPU’s compute units are seldom starved for data.与 Hopper 的 50 MB L2 缓存相比,Blackwell 将 L2 缓存容量提升了 2.5 倍以上,从而能够在片上保留更多神经网络权重或中间结果,避免额外往返访问 HBM。这同样有助于确保 GPU 的计算单元很少陷入数据饥饿。
Next, let’s show how the Blackwell GPU is paired with a dedicated set of reduced-precision Tensor Cores—as well as transformer-optimized hardware and software APIs from NVIDIA called the Transformer Engine. Frameworks, like PyTorch and inference engines like vLLM, support these optimizations by using libraries like CUDA, CUTLASS, and OpenAI’s Triton, which we talk about in later chapters.接下来,我们展示 Blackwell GPU 如何与一组专用的低精度张量核心相搭配,以及如何配合 NVIDIA 提供的针对 Transformer 优化的硬件与软件 API——Transformer 引擎(Transformer Engine)。PyTorch 等框架以及 vLLM 等推理引擎通过使用 CUDA、CUTLASS 和 OpenAI 的 Triton 等库来支持这些优化,这些库将在后续章节中讨论。
NVIDIA GPU 张量核心与 Transformer 引擎
NVIDIA GPU Tensor Cores and Transformer Engine
Speaking of compute units, Blackwell introduces enhancements specifically aimed at AI workloads. Central to this is NVIDIA’s Tensor Core technology and the Transformer Engine (TE). Tensor Cores are specialized units within each streaming multiprocessor (SM) of the GPU that can perform matrix multiplication operations at very high speed.说到计算单元,Blackwell 引入了专门面向 AI 工作负载的增强特性。其中核心是 NVIDIA 的张量核心技术与 Transformer 引擎(TE)。张量核心是 GPU 每个流多处理器(SM)内部的专用单元,能够以极高的速度执行矩阵乘法运算。
Tensor Cores were present in prior generations, but Blackwell’s Tensor Cores support even more numerical formats, including extremely low-precision ones like 8-bit and 4-bit floating point. The idea behind lower precision is simple. By using fewer bits to represent numbers, you can perform more operations at the same time—not to mention your memory goes further since fewer bits are used to represent the same numbers. This assumes that your algorithm can tolerate a little loss in numerical precision. These days, a lot of AI algorithms are designed with low-precision numerical formats in mind.张量核心在此前的几代产品中已经存在,但 Blackwell 的张量核心支持更多的数值格式,包括 8 位和 4 位浮点等极低精度格式。低精度背后的思路很简单:用更少的位来表示数字,便可以同时执行更多运算——更不用说表示相同的数字所用的位更少,显存空间也能得到更充分的利用。这前提是算法能够容忍一定的数值精度损失。如今,许多 AI 算法在设计之初就考虑了低精度数值格式。
NVIDIA pioneered the TE to automatically adjust and use mixed precision in deep learning where critical layers use higher precision (FP16 or BF16) and less critical layers use FP8. TE automatically optimizes the balance of precision with the goal of maintaining the model’s accuracy at the lower precision.NVIDIA 率先推出了 TE,用于在深度学习中自动调整并使用混合精度:关键层使用较高精度(FP16 或 BF16),而次要层使用 FP8。TE 会自动优化精度平衡,目标是在较低精度下维持模型的准确率。
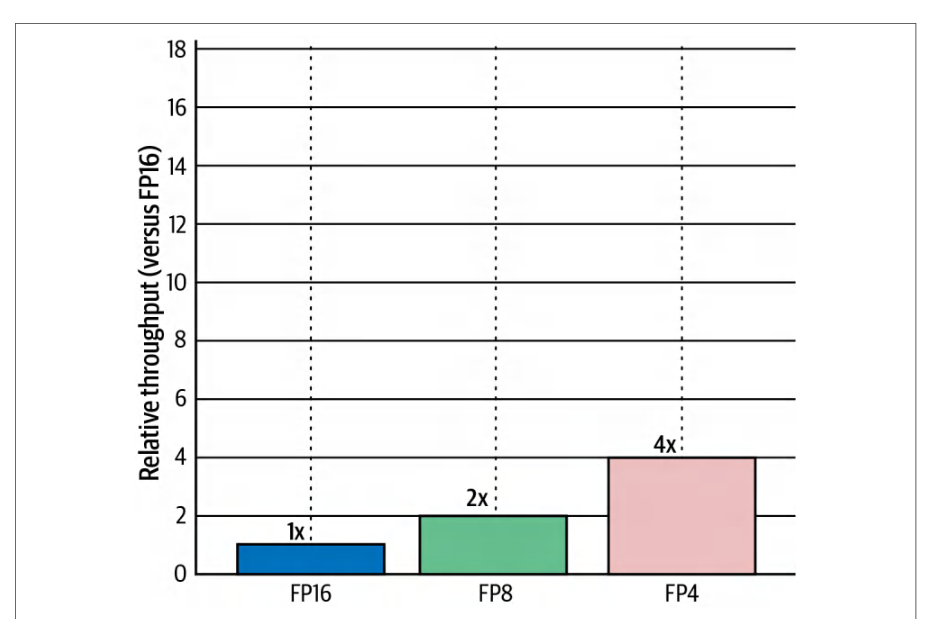
In the Hopper generation, the TE first introduced FP8 support, which doubled the throughput versus FP16. Blackwell takes it one step further by introducing NVIDIA FP4 (NVFP4), a 4-bit floating-point format that uses half the number of bits of FP8. FP4 is so small that it can potentially double the compute throughput of FP8. Figure 2-3 shows the relative speedup of FP8 and FP4 compared to FP16.在 Hopper 一代,TE 首次引入 FP8 支持,使吞吐量相比 FP16 翻倍。Blackwell 更进一步,引入了 NVIDIA FP4(NVFP4),这是一种 4 位浮点格式,使用的位数是 FP8 的一半。FP4 的位数如此之少,因而有望使 FP8 的计算吞吐量再翻一倍。图 2-3 展示了 FP8 和 FP4 相对于 FP16 的加速比。
An entire NVL72 rack (72 GPUs) has a theoretical Tensor Core throughput over 1.4 exaFLOPS (that’s 1.4 × 10¹⁸) in 4-bit precision. This is a mind-boggling number that puts this single rack in the realm of the world’s fastest supercomputers—albeit at low FP4 precision. Even if real-world workloads don’t always hit that peak, the capability is there, which is astonishing.一整台 NVL72 机架(72 个 GPU)在 4 位精度下的理论张量核心吞吐量超过 1.4 exaFLOPS(即 1.4 × 10¹⁸)。这是一个令人难以置信的数字,仅这一个机架就达到了全球最快超级计算机的量级——尽管是在低精度 FP4 下。即便真实世界的工作负载并不总能达到这一峰值,这种能力确实存在,这本身就令人惊叹。
Modern GPUs use a TE that adds NVFP4 support together with improved scaling and calibration. In practice, you adopt TE by using its kernels and modules in frameworks such as PyTorch. This way, FP8 and NVFP4 are applied when they preserve accuracy. This is not a fully automatic per-layer decision in all frameworks.现代 GPU 所使用的 TE 增加了对 NVFP4 的支持,并改进了缩放与校准。在实践中,用户通过在 PyTorch 等框架中使用 TE 的内核和模块来采用 TE。这样,当 FP8 和 NVFP4 能够保持精度时便会被采用。在所有框架中,这并非完全自动的逐层决策。
Advanced techniques include dynamically changing the precision for each layer of a neural network during training and inference. The goal is to use the lowest precision that will still preserve model accuracy for each of those layers. For example, the TE might keep the first layers of a neural net in FP16 since early layers can be sensitive to noise. But, based on heuristics, it could decide to use FP8 or FP4 for later layers that are more tolerant—or for giant embedding matrices where high precision isn’t as critical.先进技术包括在训练和推理期间动态改变神经网络每一层的精度,目标是在仍能保持模型精度的前提下,为每一层选用最低的精度。例如,Transformer Engine(TE)可能会将神经网络的前几层保持在 FP16,因为浅层可能对噪声敏感;但基于启发式规则,它可能决定对容忍度更高的后续层——或对高精度要求不那么关键的超大嵌入矩阵——采用 FP8 或 FP4。
All of this can happen under the hood in NVIDIA libraries and AI frameworks like PyTorch. As a user, you just enable mixed precision, and the result is a huge speedup that essentially comes “for free.” We’ll discuss mixed precision in Chapter 9, but just know that many LLMs today use mixed precision for this reason. These reduced precisions improve training speed compared to FP16 and FP32—and reduce accuracy loss. Blackwell was built to make FP8 and FP4 accessible and efficient.这一切都可以在 NVIDIA 库和 PyTorch 等 AI 框架的底层自动完成。作为用户,你只需启用混合精度,便能获得几乎“免费”的巨大加速。我们将在第 9 章讨论混合精度,但只需知道,如今许多大语言模型(LLM)正是出于这个原因使用混合精度。与 FP16 和 FP32 相比,这些更低的精度提升了训练速度——并降低了精度损失。Blackwell 的设计初衷就是让 FP8 和 FP4 易于使用且高效。
These reduced-precision formats reduce memory usage as well. Using FP4 halves the memory needed per parameter compared to FP8 (and FP8 halves FP16 memory usage), meaning you can pack an even larger model into the GPU’s memory.这些低精度格式还能减少显存占用。与 FP8 相比,使用 FP4 可将每个参数所需的内存减半(而 FP8 则将 FP16 的显存占用减半),这意味着你可以在 GPU 显存中装下更大的模型。
NVIDIA has effectively bet on AI’s future being in lower precision arithmetic and has given Blackwell the ability to excel at it. This is especially critical for inference serving of massive models, where throughput (tokens per second) and latency are paramount.NVIDIA 实际上是在押注 AI 的未来属于更低精度的算术运算,并赋予 Blackwell 在这一领域出类拔萃的能力。这对于超大规模模型的推理服务尤为关键,因为在这类场景中,吞吐量(每秒 token 数)和时延至关重要。
To illustrate the generational leap forward from Hopper to Blackwell, NVIDIA reported an H100-based system could generate only about 3.4 tokens per second per GPU for a large 1.8-trillion-parameter MoE model—with over 5 seconds of latency for the first token. This is too slow for interactive use.为了展示从 Hopper 到 Blackwell 的代际飞跃,NVIDIA 报告称,对于一个 1.8 万亿参数的大型混合专家(MoE)模型,基于 H100 的系统每 GPU 每秒仅能生成约 3.4 个 token,且首个 token 的时延超过 5 秒。这对于交互式使用来说太慢了。
The Blackwell-based system (NVL72) ran the same model with around 150 tokens per second per GPU and a low first-token latency of ~50 milliseconds. That is roughly 30× the real-time throughput improvement over the Hopper generation. The NVL72 allowed this massive model to serve real-time responses—opening it up to many more low-latency use cases.基于 Blackwell 的系统(NVL72)运行同一模型时,每 GPU 每秒可生成约 150 个 token,首个 token 时延低至约 50 毫秒。这相当于较 Hopper 一代约 30 倍的实时吞吐量提升。NVL72 使这一超大规模模型能够提供实时响应,从而将其拓展到更多低时延用例。
This speedup came from raw FLOPS, the combination of faster GPUs, lower precision (FP4) usage, and the NVLink interconnect keeping the GPUs fed with data. It underscores how a holistic design that spans across both compute and communication can translate into real-world performance gains.这一加速源自原始 FLOPS——它是更快的 GPU、更低精度(FP4)的使用,以及让 GPU 持续获得数据供给的 NVLink 互连三者的结合。这凸显了横跨计算与通信的整体式设计如何转化为真实世界的性能收益。
In essence, Blackwell GPUs are more powerful, smarter, and better fed with data than their predecessors. They chew through math faster, thanks to Tensor Cores, TE, and low precision. Additionally, the system architecture ensures that data is made available quickly thanks to huge memory bandwidth, large caches, and NVLink.从本质上讲,与前代相比,Blackwell GPU 更强大、更智能,并且数据供给更充足。得益于张量核心、TE 和低精度,它们能以更快的速度完成数学运算。此外,得益于巨大的显存带宽、大容量缓存和 NVLink,系统架构确保数据能够快速就位。
Before moving on, let’s quickly discuss the hierarchy inside the GPU, as this is useful to understand performance tuning later.在继续之前,我们先简要讨论 GPU 内部的层次结构,这对理解后文的性能调优很有帮助。
流多处理器、线程与线程束
Streaming Multiprocessor, Threads, and Warps
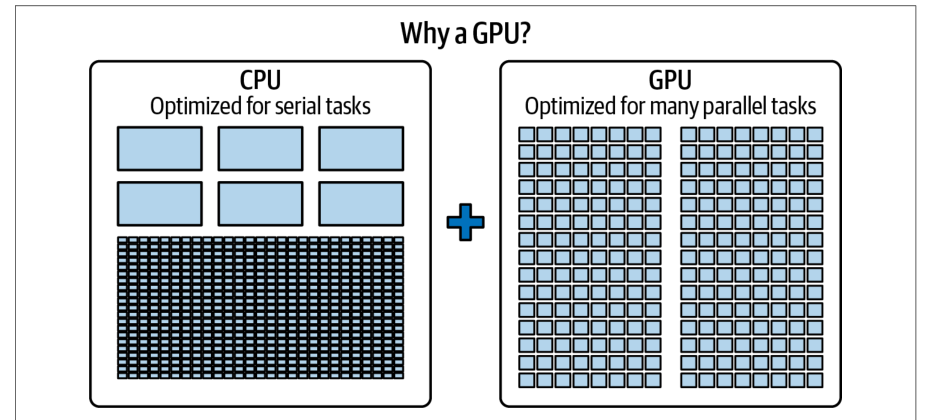
Each Blackwell GPU, like its predecessors, consists of many streaming multiprocessors (SMs). Think of these like the “cores” of the GPU, as shown in Figure 2-4.每块 Blackwell GPU 与其前代一样,由许多流多处理器(SM)组成。可以将它们视为 GPU 的“核心”,如图 2-4 所示。
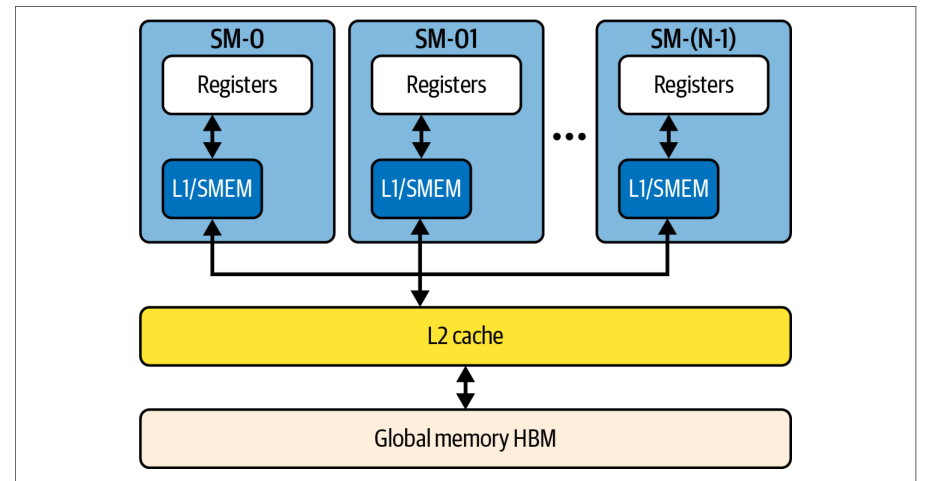
Each SM contains a bunch of arithmetic units (for FP32, INT32, etc.), Tensor Cores for matrix math, load/store units for memory operations, and some special function units for things like transcendental math. The GPU also has its own small pool of superfast memory, including registers, shared memory, and L1 cache.每个流多处理器(SM)包含若干算术单元(用于 FP32、INT32 等)、用于矩阵运算的张量核心、用于内存操作的加载/存储单元,以及一些用于超越函数运算等任务的特殊函数单元。GPU 还拥有自己的一小片超高速内存,包括寄存器、共享内存和 L1 缓存。
An SM executes threads in fixed-size groups known as warps, with each warp containing exactly 32 threads that execute the exact same instructions in lockstep. This is called the single instruction, multiple threads (SIMT) execution model.SM 以固定大小的分组来执行线程,这种分组称为*线程束*,每个线程束恰好包含 32 个线程,这些线程以锁步方式执行完全相同的指令。这称为单指令多线程(SIMT)执行模型。
SMs execute many active warps in parallel to help cover the latency of a thread waiting on data accessed from global memory. Consider an SM having dozens of warps (hundreds of threads) in flight concurrently. If one warp is waiting on a memory fetch, another warp can run. This is called latency hiding. We will revisit latency hiding throughout the book. This is a very important performance-optimization tool to have in your tuning toolbox.SM 并行执行许多活跃的线程束,以帮助掩盖线程等待从全局内存获取数据所产生的时延。设想一个 SM 上同时有数十个线程束(数百个线程)在并发执行。如果某个线程束正在等待一次内存读取,另一个线程束便可以运行。这称为*时延隐藏*(latency hiding)。我们将在全书中反复讨论时延隐藏。这是你的调优工具箱中一项非常重要的性能优化工具。
A high-end GPU like Blackwell will have hundreds of SMs. Each SM is capable of running thousands of threads concurrently. This is how we get tens of thousands of active threads onto a single GPU. All those SMs share a 126 MB L2 cache, as we mentioned earlier, and share the memory controllers that connect to the HBM. The memory hierarchy contains registers (per thread) → shared memory (per thread block, on each SM) → L1 cache (per SM) → L2 cache (shared across all SMs on the GPU) → HBM memory (off chip), as shown in Figure 2-5.像 Blackwell 这样的高端 GPU 拥有数百个 SM。每个 SM 能够并发运行数千个线程。我们正是通过这种方式在单个 GPU 上容纳数万个活跃线程的。如前文所述,所有这些 SM 共享一个 126 MB 的 L2 缓存,并共享连接到 HBM 的显存控制器。显存层次结构包含:寄存器(每线程)→ 共享内存(每线程块,位于每个 SM 上)→ L1 缓存(每 SM)→ L2 缓存(由 GPU 上所有 SM 共享)→ HBM 显存(片外),如图 2-5 所示。
For best performance, data needs to stay as high in that hierarchy as possible. If every operation went out to HBM even at 8 TB/s, the GPU would stall too often due to the increased latency of accessing off-chip memory. By keeping reusable data in SM local memory or L2 cache, the GPU can achieve enormous throughput. The Blackwell architecture’s doubling of cache and bandwidth is aimed exactly at keeping the GPU beast fed and happy.为获得最佳性能,数据应尽可能停留在该层次结构中较高的层级。即使 HBM 带宽达到 8 TB/s,如果每次操作都要访问 HBM,GPU 也会因访问片外显存时延的增加而频繁停顿。通过将可复用数据保存在 SM 本地内存或 L2 缓存中,GPU 可以实现巨大的吞吐量。Blackwell 架构将缓存和带宽翻倍,其目的正是让 GPU 这头猛兽吃饱并保持良好状态。
As performance engineers, we’ll see many examples where a kernel’s performance is bound by compute as well as memory traffic and throughput. NVIDIA clearly designed Blackwell so that, for many AI workloads, the balance between FLOPS and memory bandwidth is well-matched.作为性能工程师,我们会看到许多例子,其中内核的性能既受计算限制,也受内存流量和吞吐量限制。NVIDIA 对 Blackwell 的设计显然使得在许多 AI 工作负载下,FLOPS 与显存带宽之间的平衡匹配良好。
Blackwell’s design balances compute and memory so that for many AI kernels the GPUs can keep computing with minimal stalls. In practice, well-optimized dense math operations can reuse data from on-chip memory to approach peak FLOPS without being severely memory bound.Blackwell 的设计平衡了计算与内存,使得对于许多 AI 内核,GPU 能够以极少的停顿持续计算。在实践中,经过良好优化的稠密数学运算可以复用片上内存中的数据,从而接近峰值 FLOPS,而不会严重受内存限制。
All of this means that, given well-optimized code, the GPUs will often be busy computing rather than waiting on data. Note that certain operations like huge reductions or random memory accesses can still be memory bound, but the updated GPU, memory, and interconnect hardware make this a bit less of an issue.这一切意味着,只要代码经过良好优化,GPU 通常会忙于计算而不是等待数据。请注意,某些操作(如大规模归约或随机显存访问)仍可能受内存限制(memory bound),但更新后的 GPU、内存和互连硬件使这一问题有所缓解。
超大规模网络:将多块 GPU 视为一体
Ultrascale Networking Treating Many GPUs as One
Packing two GPUs and a CPU into a superchip gives us an incredibly powerful node. The next challenge is connecting many of these superchips together to scale out to even larger model training.将两块 GPU 和一个 CPU 封装进一颗超级芯片,造就了一个极其强大的节点。下一个挑战是将许多这样的超级芯片连接起来进行横向扩展,以支持更大规模的模型训练。
NVIDIA provides a large rack configuration using GB200/GB300 Superchips called the NVL72 system. NVL72 stands for a system with 72 Blackwell GPUs—and 36 Grace CPUs—all interconnected with NVLink. This is essentially an AI supercomputer in a single rack.NVIDIA 提供了一种使用 GB200/GB300 超级芯片的大型机架配置,称为 NVL72 系统。NVL72 指的是一个拥有 72 块 Blackwell GPU——以及 36 个 Grace CPU——并通过 NVLink 全部互连的系统。这实质上是单个机架内的一台 AI 超级计算机。
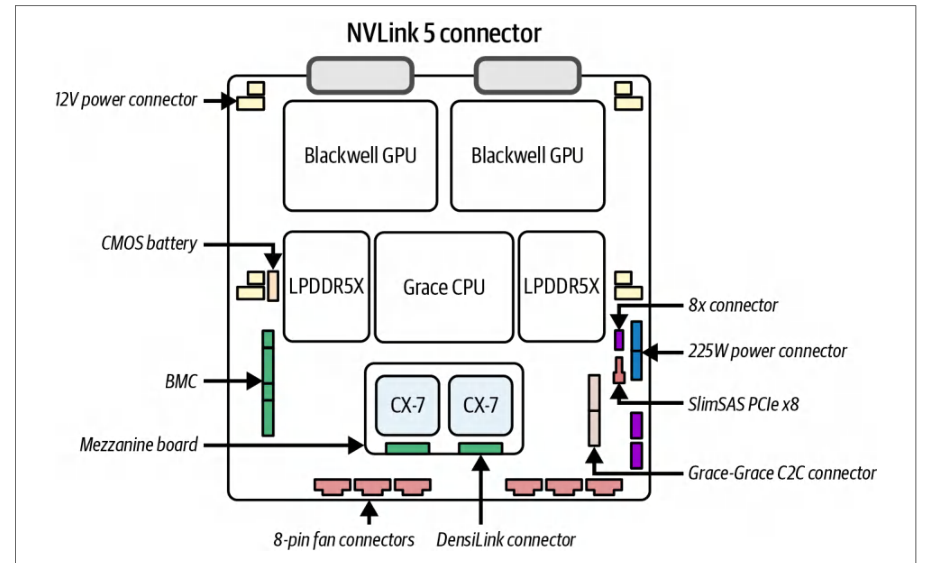
The GB200/GB300 NVL72 is built as 18 compute nodes in which each node contains two GB200/GB300 Superchips for a total of four Blackwell GPUs + two Grace CPUs per compute node, as shown in Figure 2-6.GB200/GB300 NVL72 由 18 个计算节点构成,每个节点包含两颗 GB200/GB300 超级芯片,因此每个计算节点共有 4 块 Blackwell GPU + 2 个 Grace CPU,如图 2-6 所示。
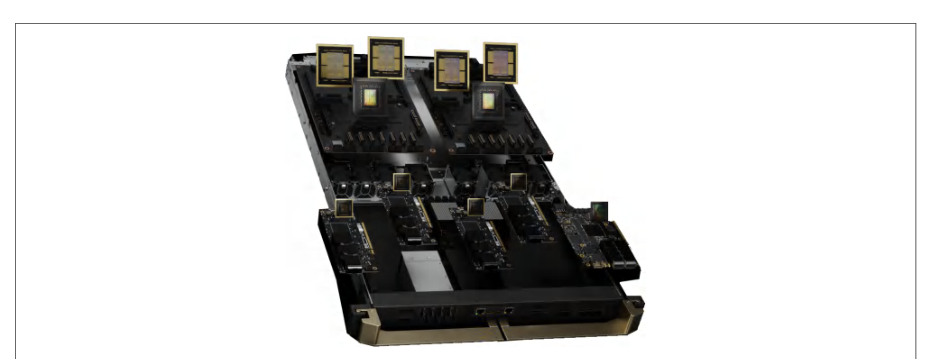
Here, each superchip module has one Grace CPU and two Blackwell GPUs (each B200 is a dual-die MCM). The NVL72 has 18 of these trays linked together. By connecting the 18 compute nodes together, the GB200/GB300 NVL72 links 72 Blackwell GPUs (18 nodes × 4 GPUs) and 36 Grace CPUs (18 nodes × 2 CPUs) together to form a powerful, unified CPU-GPU cluster.此处,每个超级芯片模块包含一个 Grace CPU 和两个 Blackwell GPU(每个 B200 为双裸片 MCM)。NVL72 由 18 个这样的托盘互连而成。通过将 18 个计算节点连接在一起,GB200/GB300 NVL72 将 72 个 Blackwell GPU(18 节点 × 4 GPU)和 36 个 Grace CPU(18 节点 × 2 CPU)连接起来,构成一个强大且统一的 CPU-GPU 集群。
The interesting thing about the NVL72 is that every GPU can talk to any other GPU through the NVLink Switch fabric at very high speed within a single NVLink domain. NVIDIA achieved this using a combination of NVLink 5 connections on the GPUs and a dedicated switch silicon called NVSwitch.NVL72 的有趣之处在于,在单个 NVLink 域内,每个 GPU 都可以通过 NVLink Switch 交换网络以极高的速度与任何其他 GPU 通信。NVIDIA 通过在 GPU 上采用 NVLink 5 连接,并结合名为 NVSwitch 的专用交换芯片,实现了这一点。
NVLink 与 NVSwitch
NVLink and NVSwitch
Each Blackwell GPU exposes 18 NVLink 5 ports. Aggregate bidirectional NVLink bandwidth is 1.8 TB/s per GPU (18 NVLink links × 100 GB/s bidirectional) with the NVL72 wiring all ports to the NVLink Switch System. Each NVLink switch tray delivers 144 NVLink ports at 100 GB/s. Across the nine trays, each GPU’s 18 NVLink 5 links are wired one per NVSwitch chip so the 72 GPUs are fully connected at full bisection bandwidth. The aggregate bidirectional NVLink 5 bandwidth is 1.8 TB/s per GPU (18 NVLink links × 100 GB/s bidirectional).每个 Blackwell GPU 提供 18 个 NVLink 5 端口。在 NVL72 将所有端口连接至 NVLink Switch System 的情况下,每个 GPU 的 NVLink 聚合双向带宽为 1.8 TB/s(18 条 NVLink 链路 × 100 GB/s 双向)。每个 NVLink 交换托盘提供 144 个 100 GB/s 的 NVLink 端口。在这九个托盘上,每个 GPU 的 18 条 NVLink 5 链路按每个 NVSwitch 芯片一条的方式布线,从而使 72 个 GPU 以全二分带宽实现全互联。每个 GPU 的 NVLink 5 聚合双向带宽为 1.8 TB/s(18 条 NVLink 链路 × 100 GB/s 双向)。
This is double the per-GPU NVLink bandwidth of the previous generation used by Hopper GPUs. The Hopper H100 uses 18 NVLink 4 ports but runs at half the speed of NVLink 5. Inter-GPU latency over NVLink is in the single-digit microsecond range.这是 Hopper GPU 所用上一代 NVLink 每 GPU 带宽的两倍。Hopper H100 采用 18 个 NVLink 4 端口,但速度仅为 NVLink 5 的一半。经 NVLink 的 GPU 间时延处于个位数微秒量级。
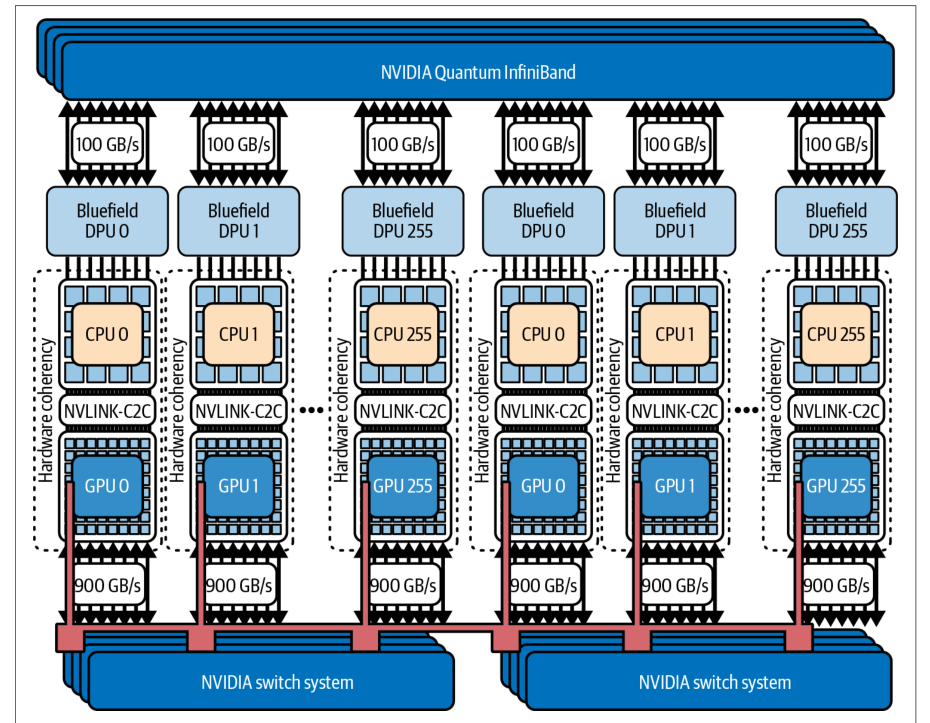
The GPUs are cabled in a network through NVSwitch chips. NVSwitch is essentially a switching chip similar to a network switch, but it’s built specifically for NVLink. This means any GPU can reach any other GPU through one switch stage in the NVLink Switch System at full bisection bandwidth. This one-stage property holds true within a single NVL72 rack because each GPU uses its 18 NVLink links to connect to the 18 NVSwitch chips, enabling a path through a single switch. Figure 2-7 shows an NVLink Switch tray used in NVL72.这些 GPU 通过 NVSwitch 芯片以线缆连接成网络。NVSwitch 本质上是一种类似于网络交换机的交换芯片,但它是专为 NVLink 构建的。这意味着在 NVLink Switch System 中,任何 GPU 都可以经过单级交换、以全二分带宽到达任何其他 GPU。这一单级交换特性在单个 NVL72 机架内成立,因为每个 GPU 使用其 18 条 NVLink 链路连接到 18 个 NVSwitch 芯片,从而形成经过单个交换机的路径。图 2-7 展示了 NVL72 中使用的一个 NVLink Switch 托盘。
Each switch tray contains two NVSwitch chips and multiple high-speed ports. The NVL72 rack comprises 9 such switch trays and 18 compute trays, as shown in每个交换托盘(switch tray)包含两颗 NVSwitch 芯片和多个高速端口。NVL72 机架包含 9 个这样的交换托盘和 18 个计算托盘,如图
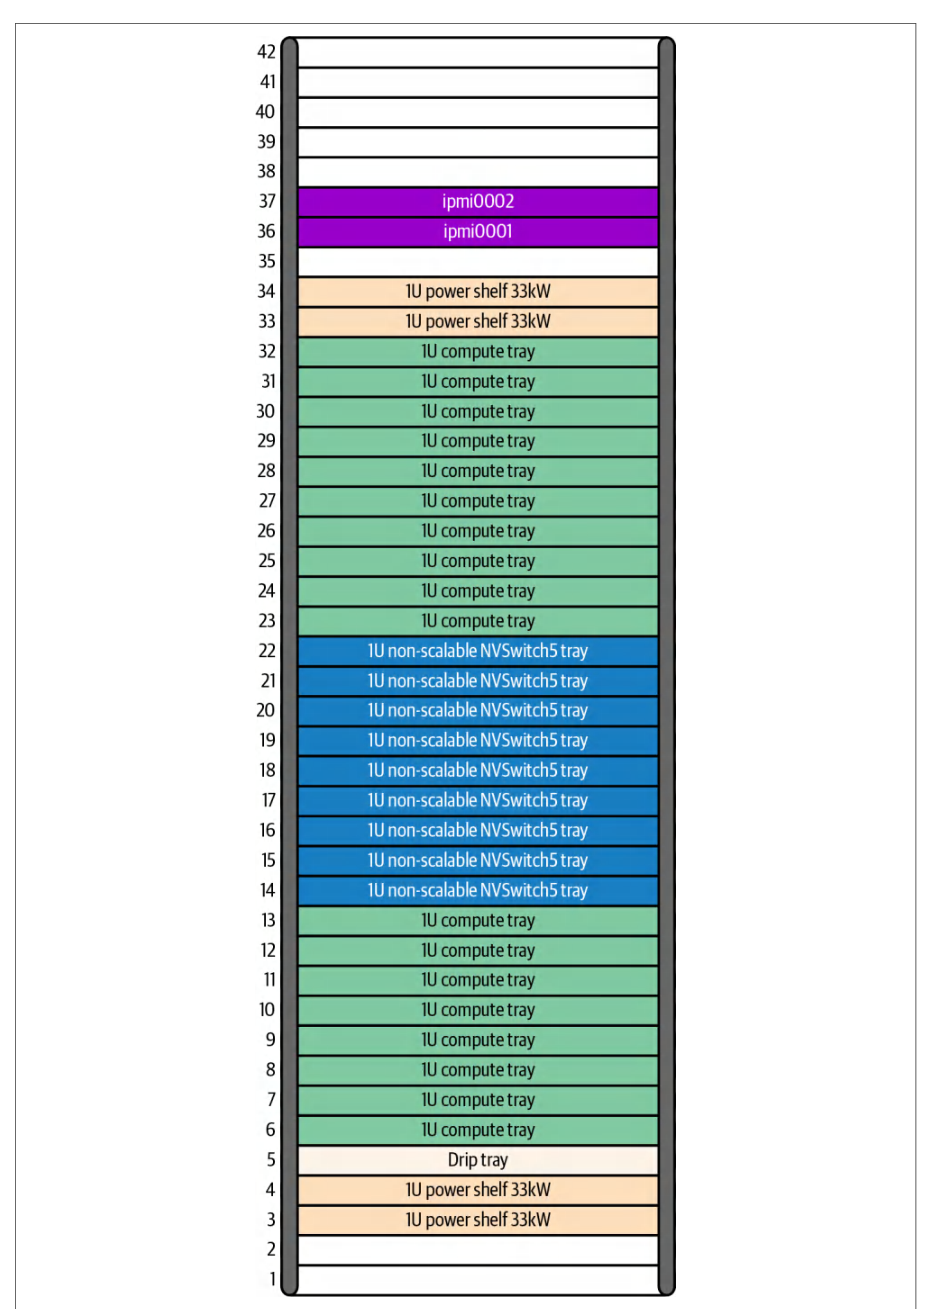
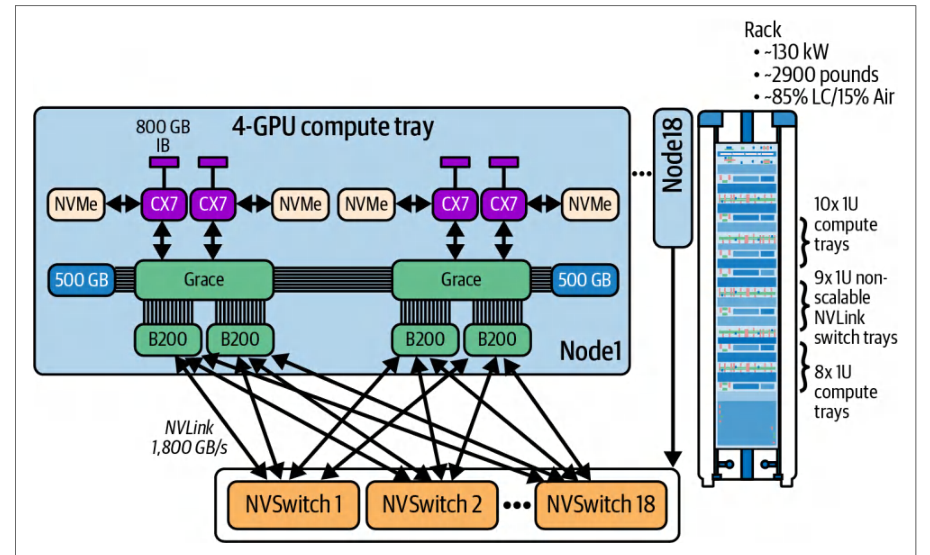
Since each of the 9 switch trays contains two NVSwitch chips, the total is 18 NVSwitch chips in the NVL72 system. The network is arranged as a full crossbar such that every GPU is connected to every NVSwitch, and every NVSwitch is connected to every GPU. This provides a high-bandwidth path between any pair of GPUs.由于 9 个交换托盘中的每一个都包含两个 NVSwitch 芯片,因此 NVL72 系统中共有 18 个 NVSwitch 芯片。该网络以全交叉开关(full crossbar)方式布置,使每个 GPU 都连接到每个 NVSwitch,且每个 NVSwitch 都连接到每个 GPU。这为任意一对 GPU 之间提供了高带宽路径。
Each switch tray exposes 144 NVLink ports to fully connect the 18 NVLink links on each GPU. Concretely, each GPU uses its 18 NVLink links to connect to the 18 NVSwitch chips (one link to each switch). This means any GPU can reach any other GPU in one hop (GPU → NVSwitch → GPU), with enormous bandwidth along the way. Figure 2-9 shows the full NVL72 architecture with 72 fully connected GPUs (36 GB200 superchips) and 18 NVSwitches.每个交换托盘提供 144 个 NVLink 端口,以完全连接每个 GPU 上的 18 条 NVLink 链路。具体而言,每个 GPU 使用其 18 条 NVLink 链路连接到 18 个 NVSwitch 芯片(每个交换芯片一条链路)。这意味着任何 GPU 都可以一跳到达任何其他 GPU(GPU → NVSwitch → GPU),且沿途带宽巨大。图 2-9 展示了完整的 NVL72 架构,包含 72 个全互联的 GPU(36 个 GB200 超级芯片)和 18 个 NVSwitch。
The aggregate bisection bandwidth across the entire 72-GPU network is about 130 TB/s within an NVL72 rack. For perspective, that is many times higher than even a top-end InfiniBand cluster of similar scale. The design exposes a fully connected, high-bandwidth fabric with a global address space across GPUs. This allows efficient collectives and one-sided operations while preserving explicit software control over synchronization and consistency.在整个 72 GPU 网络中,NVL72 机架内的聚合二分带宽约为 130 TB/s。作为参照,这比同等规模的顶级 InfiniBand 集群还要高出许多倍。该设计提供了一个全互联、高带宽且在 GPU 之间具有全局地址空间的互连网络。这使得高效的集合通信和单边操作成为可能,同时保留了对同步与一致性的显式软件控制。
多 GPU 编程
Multi-GPU Programming
From a programming model standpoint, one GPU can directly access another GPU’s memory over NVLink using peer-to-peer and partitioned global address space (PGAS) models such as NVIDIA SHMEM (NVSHMEM), NVIDIA’s GPU-accelerated OpenSHMEM implementation. There is a global address space, but GPU caches are not globally coherent across GPUs. Only the CPU–GPU path over NVLink-C2C is cache coherent. Software stacks such as NCCL and NVSHMEM provide the synchronization and ordering required for correct multi-GPU access. Combined, hardware cache coherency and software synchronization techniques allow the NVL72 to be seen as essentially one big GPU.从编程模型的角度来看,一个 GPU 可以通过 NVLink,借助点对点(peer-to-peer)和分区全局地址空间(PGAS)等模型直接访问另一个 GPU 的内存,例如 NVIDIA SHMEM(NVSHMEM)——NVIDIA 的 GPU 加速 OpenSHMEM 实现。系统存在全局地址空间,但 GPU 缓存在各 GPU 之间并非全局一致。只有通过 NVLink-C2C 的 CPU–GPU 路径才具备缓存一致性。NCCL 和 NVSHMEM 等软件栈提供了实现正确多 GPU 访问所需的同步与排序。硬件缓存一致性与软件同步技术相结合,使 NVL72 在本质上可以被视作一个大 GPU。
Remote direct memory access (RDMA) is a network technology that enables direct, zero-copy memory transfers between hosts across InfiniBand and RDMA over Converged Ethernet (RoCE) transports. Optional remote atomic operations are defined by the InfiniBand Trade Association (IBTA) for InfiniBand and RoCE.远程直接显存访问(RDMA)是一种网络技术,可在 InfiniBand 和基于融合以太网的 RDMA(RoCE)传输之上实现主机间直接的零拷贝内存传输。InfiniBand 贸易协会(IBTA)为 InfiniBand 和 RoCE 定义了可选的远程原子操作。
GPUDirect RDMA, NVIDIA’s implementation of the RDMA protocol, enables network interface controllers (NICs) to register GPU memory and perform RDMA directly to and from GPU memory using the nvidia-peermem driver. This allows GPUs to exchange data and execute atomic operations across nodes without involving the CPU. This allows NICs to perform direct DMA to and from GPU memory without staging through host RAM.GPUDirect RDMA 是 NVIDIA 对 RDMA 协议的实现,它使网络接口控制器(NIC)能够借助 nvidia-peermem 驱动注册 GPU 显存,并直接对 GPU 显存执行 RDMA 读写。这使 GPU 能够跨节点交换数据并执行原子操作,而无需 CPU 参与。这也使 NIC 能够直接对 GPU 显存执行 DMA,而无需经由主机 RAM 暂存。
Remote atomics and one-sided operations across nodes are provided by upper-layer libraries such as NVSHMEM, which implement these semantics over RDMA transports. Note that GPUDirect RDMA supplies the direct data path rather than the atomic APIs themselves. Distributed training and inference workloads need to synchronize and exchange information frequently across many GPUs.跨节点的远程原子操作和单边操作(one-sided operations)由 NVSHMEM 等上层库提供,这些库在 RDMA 传输之上实现了这些语义。请注意,GPUDirect RDMA 提供的是直接数据通路,而非原子操作 API 本身。分布式训练与推理工作负载需要在众多 GPU 之间频繁地同步和交换信息。
Traditionally, the GPUs are in different compute nodes and racks. As such, synchronization can happen over relatively slow network links like InfiniBand and Ethernet. This is often the bottleneck when scaling across many GPUs to support large AI models.传统上,这些 GPU 位于不同的计算节点和机架中。因此,同步可能需要通过 InfiniBand 和以太网等相对较慢的网络链路进行。在跨大量 GPU 扩展以支撑大型 AI 模型时,这往往是瓶颈所在。
With an NVL72 system, those exchanges happen over NVLink and NVSwitch at a superfast pace. This means you can scale your training job or inference cluster up to 72 GPUs with minimal communication overhead. And since the GPUs spend far less time waiting for data from one another, overall throughput scales near-linearly up to 72 GPUs.在 NVL72 系统中,这些交换通过 NVLink 和 NVSwitch 以极快的速度完成。这意味着你可以以极小的通信开销将训练作业或推理集群扩展至最多 72 个 GPU。而且,由于 GPU 用于等待彼此数据的时间大幅减少,整体吞吐量在扩展到 72 个 GPU 时接近线性增长。
In contrast, consider scaling the same job across a similarly sized 72-GPU H100 cluster of nine separate compute servers—each with eight Hopper H100 GPUs. This configuration requires InfiniBand, which will create network bottlenecks that greatly reduce the cluster’s scaling efficiency.相比之下,设想将同一作业扩展到规模相当的 72 GPU H100 集群上——该集群由九台独立计算服务器组成,每台配备八块 Hopper H100 GPU。这种配置需要使用 InfiniBand,而这会带来网络瓶颈,大幅降低集群的扩展效率。
Let’s analyze and compare the NVL72 and 72-GPU H100 clusters using concrete numbers. Within a single NVL72 rack, GPU-to-GPU bandwidth is up to 1.8 TB/s per GPU (bidirectional aggregate), and latency is on the order of 1–2 microseconds for a small message on the order of kilobytes. Large messages take longer and are typically bandwidth-limited. Across a conventional InfiniBand network, bandwidth per GPU might be more like 20–80 GB/s—depending on how many NICs and their speed— and latency is likely 5–10 microseconds or more.让我们用具体数字来分析和比较 NVL72 与 72 GPU H100 集群。在单个 NVL72 机架内,GPU 间带宽高达每 GPU 1.8 TB/s(双向聚合),对于千字节量级的小消息,时延在 1–2 微秒量级。大消息耗时更长,且通常受带宽限制。而在传统 InfiniBand 网络上,每 GPU 带宽可能更接近 20–80 GB/s——取决于 NIC 的数量及其速率——时延则可能在 5–10 微秒或更高。
The NVL72 network offers substantially higher per-GPU bandwidth and lower latency than host-NIC fabrics. Specifically, NVLink 5 provides about 1.8 TB/s of aggregate bandwidth per GPU, whereas modern host NICs provide about 50–100 GB/s per port at 400–800 Gb/s line rates. All of this decreases collective-operation overhead down from tens of percent down to just a few percent.与基于主机 NIC 的互联网络(fabric)相比,NVL72 网络提供了显著更高的每 GPU 带宽和更低的时延。具体而言,NVLink 5 为每 GPU 提供约 1.8 TB/s 的聚合带宽,而现代主机 NIC 在 400–800 Gb/s 线路速率下每端口约可提供 50–100 GB/s。这一切使集合通信操作的开销从百分之几十降至仅百分之几。
In practical terms, collective overhead is substantially lower within an NVLink-connected NVL72 system versus a traditional node-to-node fabric, but the exact fraction of iteration time is workload-dependent. For example, NVIDIA reported that a 1.8-trillion-parameter MoE model improved from about 3.4 tokens per second per GPU with over 5 seconds time to first token on H100 to about 150 tokens per second per GPU with roughly 50 ms time to first token on GB200 NVL72. This speedup is largely due to eliminating inter-GPU communication bottlenecks inside the NVL72 rack in addition to Blackwell’s higher compute throughput.从实际角度来看,在通过 NVLink 互连的 NVL72 系统中,集合通信开销远低于传统的节点间互连网络(fabric),但其占迭代时间的确切比例取决于工作负载。例如,NVIDIA 报告称,一个 1.8 万亿参数的 MoE 模型在 H100 上约为每 GPU 每秒 3.4 个 token、首 token 时延(time to first token)超过 5 秒,而在 GB200 NVL72 上提升至约每 GPU 每秒 150 个 token、首 token 时延约为 50 ms。这一加速主要归功于消除了 NVL72 机架内部的 GPU 间通信瓶颈,此外还得益于 Blackwell 更高的计算吞吐量。
Within a single NVL72 rack, communication is so fast that communication bottlenecks become low priority as they are almost completely eliminated, whereas communication in traditional InfiniBand and Ethernet clusters is often the primary bottleneck and needs careful optimization and tuning at the software level.在单个 NVL72 机架内,通信速度极快,通信瓶颈几乎被完全消除,因而不再是需要优先关注的问题;而在传统的 InfiniBand 和以太网集群中,通信往往是最主要的瓶颈,需要在软件层面进行细致的优化和调优。
In short, you should design and implement software that exploits the NVL72 configuration by keeping as much of the workload’s communication inside the rack (“intra-rack”) as possible to take advantage of the high-speed NVLink and NVSwitch hardware. Use the slower InfiniBand- or Ethernet-based communication between racks (“inter-rack”) only when absolutely necessary to scale beyond the NVL72’s compute and memory resources.简而言之,你应当设计并实现能够充分利用 NVL72 配置的软件,尽可能将工作负载的通信保留在机架内(“intra-rack”),以发挥高速 NVLink 和 NVSwitch 硬件的优势。只有在确有必要扩展到 NVL72 计算和内存资源之外时,才使用机架间(“inter-rack”)较慢的基于 InfiniBand 或以太网的通信。
使用 NVIDIA SHARP 进行网络内聚合
In-Network Aggregations with NVIDIA SHARP
Another hardware-enabled optimization is NVIDIA Scalable Hierarchical Aggregation and Reduction Protocol (SHARP). For NVLink Switch System racks, in-network reductions use SHARP engines integrated into NVSwitch ASICs to offload reductions and other collectives in-network (see Figure 2-10).另一种借助硬件实现的优化是 NVIDIA 可扩展分层聚合与归约协议(Scalable Hierarchical Aggregation and Reduction Protocol,SHARP)。对于 NVLink Switch System 机架,网络内归约利用集成在 NVSwitch ASIC 中的 SHARP 引擎,将归约和其他集合通信操作卸载到网络内执行(见图 2-10)。
The NVSwitch fabric combines partial results without the data needing to funnel through the GPUs. By offloading collective computations from the GPUs to the switch hardware itself, SHARP allows the GPUs to focus on more complex computations, lowers collective latencies, reduces the overall volume of data traversing the network, and increases system efficiency.NVSwitch 互连网络可在数据无需汇聚流经 GPU 的情况下合并部分结果。通过将集合通信计算从 GPU 卸载到交换硬件本身,SHARP 使 GPU 能够专注于更复杂的计算,降低集合通信时延,减少穿越网络的总体数据量,并提升系统效率。
SHARP’s increased efficiency means that during distributed training, the heavy lifting of aggregating gradients or synchronizing parameters is handled by the NVSwitch’s dedicated SHARP engines. The result is much more efficient scaling across both intra-rack and inter-rack configurations.SHARP 带来的效率提升意味着,在分布式训练期间,梯度聚合或参数同步等繁重工作由 NVSwitch 专用的 SHARP 引擎处理。其结果是在机架内和机架间两种配置下都能实现高效得多的扩展。
With SHARP, you’ll see near-linear performance improvements even as the number of GPUs grows. This in-network computing capability is especially critical for training ultralarge models, where every microsecond saved on collective operations can translate into substantial overall speedups.借助 SHARP,即使 GPU 数量不断增加,你也能看到近乎线性的性能提升。这种网络内计算能力对于训练超大规模模型尤为关键,因为在集合通信操作上节省的每一微秒都可能转化为可观的总体加速。
多机架与存储通信
Multirack and Storage Communication
Next, let’s discuss how an NVL72 rack talks to another NVL72—or to an external storage system like a shared filesystem. As we have shown, inside the NVL72 rack, NVLink covers all GPU-to-GPU traffic. But outside the rack, it relies on more traditional networking hardware.接下来,我们讨论一个 NVL72 机架如何与另一个 NVL72——或者与共享文件系统等外部存储系统——进行通信。如前文所示,在 NVL72 机架内部,NVLink 承载了所有 GPU 到 GPU 的流量;而在机架之外,则依赖较为传统的网络硬件。
Each compute node in NVL72 is equipped with high-speed Network Interface Cards and a Data Processing Unit (DPU). A DPU offloads, accelerates, and isolates networking, storage, security, and management tasks from the host CPU. By running these operations directly on the NIC, DPUs reduce CPU overhead and latency.NVL72 中的每个计算节点都配备高速网络接口卡(NIC)和数据处理单元(Data Processing Unit,DPU)。DPU 将网络、存储、安全和管理任务从宿主 CPU 上卸载、加速并隔离。通过直接在 NIC 上运行这些操作,DPU 降低了 CPU 开销和时延。
In the NVL72 design, the BlueField-3 DPU handles line-rate packet processing, RDMA, and NVMe over Fabrics (oF) operations. NVMe-oF is a protocol variant of NVMe that extends storage across network fabrics. As such, the DPU moves data directly between the network, storage, and GPU memory without CPU involvement. This maximizes overall system throughput and efficiency.在 NVL72 设计中,BlueField-3 数据处理器(DPU)负责线速数据包处理、RDMA 和 NVMe over Fabrics(oF)操作。NVMe-oF 是 NVMe 的一种协议变体,可将存储扩展到网络结构。因此,DPU 可在网络、存储和 GPU 显存之间直接移动数据,无需 CPU 参与。这最大化了整体系统吞吐量和效率。
GB200/GB300 NVL72 racks integrate with Quantum-X800 InfiniBand or Spectrum-X800 Ethernet fabrics. The compute trays commonly use four ConnectX-8 800 Gb/s NICs per node for high external bandwidth. BlueField-3 DPUs are used where in-network acceleration or offload is required for storage, security, and control-plane tasks.GB200/GB300 NVL72 机架与 Quantum-X800 InfiniBand 或 Spectrum-X800 Ethernet 网络结构集成。计算托盘通常每个节点使用四张 ConnectX-8 800 Gb/s 网络接口卡(NIC),以提供高外部带宽。在存储、安全和控制平面任务需要网络内加速或卸载时,使用 BlueField-3 DPU。
With four 800 Gb/s NICs, it is 3.2 Tbit/s per compute node and about 57.6 Tbit/s per rack (57.6 Tbit/s = 3.2 Tbit/s per node × 18 nodes). While this throughput is eye-popping, remember that when you exit the rack, you still need an ultrafast network. This way, multirack scaling isn’t bottlenecked at the rack boundary. NVIDIA calls these multirack deployments AI factories. And they’ve made sure that the NVL72 can plug into a larger network fabric using these four NICs per node.配备四张 800 Gb/s NIC 时,每个计算节点为 3.2 Tbit/s,每个机架约为 57.6 Tbit/s(57.6 Tbit/s = 3.2 Tbit/s/节点 × 18 节点)。尽管这一吞吐量惊人,但要记住,离开机架后仍然需要超高速网络。这样,多机架扩展不会在机架边界处成为瓶颈。NVIDIA 将这些多机架部署称为 AI 工厂。并且他们确保 NVL72 可以通过每个节点的四张 NIC 接入更大的网络结构。
The BlueField-3 DPU in each node helps offload networking tasks like RDMA, TCP/IP, and NVMe SSD storage access. This makes sure the Grace CPU isn’t bogged down managing network interrupts. The DPU essentially serves as a smart network controller, moving data directly between NICs and GPU memory using NVIDIA’s GPUDirect RDMA software. This does not require staging data through host memory or using any CPU cycles.每个节点中的 BlueField-3 DPU 有助于卸载 RDMA、TCP/IP 和 NVMe SSD 存储访问等网络任务。这确保 Grace CPU 不会被管理网络中断拖慢。DPU 本质上充当智能网络控制器,使用 NVIDIA 的 GPUDirect RDMA 软件在 NIC 和 GPU 显存之间直接移动数据。这不需要通过主机内存暂存数据或使用任何 CPU 周期。
BlueField DPUs avoid CPU involvement, which is especially useful when streaming large datasets from a storage server for large-scale training jobs. Specifically, the DPU can handle the transfer and deposit data directly into GPU memory—while the CPU focuses on other tasks like data preprocessing.BlueField DPU 避免 CPU 参与,这在为大规模训练任务从存储服务器流式传输大型数据集时尤其有用。具体而言,DPU 可以处理传输并将数据直接写入 GPU 显存,而 CPU 专注于数据预处理等其他任务。
In addition to providing performance-offload capabilities, the DPU supports secure multitenancy. It isolates network traffic for different jobs and users—acting as a smart firewall/switch on the node.除了提供性能卸载能力外,DPU 还支持安全多租户。它隔离不同任务和用户的网络流量,在节点上充当智能防火墙/交换机。
When scaling out to multiple NVL72 racks, NVIDIA uses Quantum-series InfiniBand switches. Multiple NVL72 racks can be interconnected using these InfiniBand switches to form a large cluster of NVL72 racks.在横向扩展到多个 NVL72 机架时,NVIDIA 使用 Quantum 系列 InfiniBand 交换机。多个 NVL72 机架可以通过这些 InfiniBand 交换机互连,形成大型 NVL72 机架集群。
For example, an 8-rack NVL72 totaling 576 GPUs is connected as one NVLink 5 domain using the NVLink Switch System. InfiniBand or Ethernet is then used to connect that NVLink domain to other domains (e.g., other NVL72 racks) or to external storage (though the performance for cross-rack InfiniBand or Ethernet communication will be lower than the intra-rack NVLink/NVSwitch communication).例如,一个由 8 个机架组成、总计 576 个 GPU 的 NVL72 系统使用 NVLink Switch System 连接为一个 NVLink 5 域。然后使用 InfiniBand 或 Ethernet 将该 NVLink 域连接到其他域(例如其他 NVL72 机架)或外部存储(尽管跨机架 InfiniBand 或 Ethernet 通信的性能会低于机架内 NVLink/NVSwitch 通信)。
In short, InfiniBand and Ethernet NICs such as NVIDIA’s ConnectX and BlueField DPU are typically used alongside NVLink. These provide high-bandwidth connectivity between racks and also offload protocols using in-network computing on DPUs.简言之,NVIDIA 的 ConnectX 和 BlueField DPU 等 InfiniBand 和 Ethernet NIC 通常与 NVLink 一起使用。这些设备提供机架之间的高带宽连接,并使用 DPU 上的网络内计算来卸载协议。
预集成机架设备
Preintegrated Rack Appliance
Because NVL72 is such a complex system, NVIDIA delivers it as a preintegrated rack “appliance” in a single cabinet. It comes assembled with all 18 compute nodes, all 9 NVSwitch units, internal NVLink cabling, power distribution, and a cooling system. The idea is that an organization can order this as a unit that is ready to go when it arrives. One simply connects the rack to facility power, hooks up the water cooling interfaces, connects the InfiniBand cables to your network, and powers it on.由于 NVL72 是一个如此复杂的系统,NVIDIA 将其作为单个机柜中的预集成机架“设备”交付。它出厂时已组装好全部 18 个计算节点、全部 9 个 NVSwitch 单元、内部 NVLink 布线、配电系统和冷却系统。其理念是,组织可以按单元订购,到货后即可使用。用户只需将机架连接到机房电源,接好水冷接口,将 InfiniBand 线缆连接到网络,然后上电即可。
The system is essentially ready for use out of the box, requiring only minimal setup to begin running AI workloads. There is no need to individually cable 72 GPUs with NVLink, as NVIDIA has already done this inside the rack for you. Even the liquid cooling setup is self-contained, as we’ll discuss soon.该系统基本上开箱即用,只需最少配置即可开始运行 AI 工作负载。无需为 72 个 GPU 逐一进行 NVLink 布线,因为 NVIDIA 已在机架内完成这项工作。即使是液冷配置也是自包含的,我们稍后将讨论。
This appliance approach accelerates deployment and ensures that the system is built correctly and validated by NVIDIA. The rack also includes its NVIDIA Base Command Manager cluster-management software—as well as the Simple Linux Utility for Resource Management (SLURM) and Kubernetes for cluster-job scheduling and orchestration.这种整机(appliance)方案加快了部署速度,并确保系统构建正确且经过 NVIDIA 验证。该机架还附带 NVIDIA Base Command Manager 集群管理软件,以及用于集群作业调度与编排的简单 Linux 资源管理工具(SLURM)和 Kubernetes。
In short, the NVL72 rack is designed to be dropped into your environment and ready to run production AI workloads right out of the box. It doesn’t need any manual installation or complex configuration.简而言之,NVL72 机架的设计目标就是直接部署到您的环境中,开箱即可运行生产级 AI 工作负载,无需任何手动安装或复杂配置。
共封装光学:网络硬件的未来
Co-Packaged Optics: Future of Networking Hardware
As networking data throughput rates climb to 800 Gbit/s, 1.6 Tbit/s, and beyond, NVIDIA has begun integrating silicon photonics and co-packaged optics (CPO) into its networking hardware. This includes the Quantum-X800 InfiniBand and Spectrum-X800 Ethernet platforms. These platforms ship with 800 Gb/s end-to-end connectivity and in-network computing features (e.g., SHARP). With CPO, the optical transmitters are integrated right next to the switch silicon. This drastically shortens electrical pathways, enabling even higher bandwidth links between racks, reducing power draw, and improving overall communication efficiency.随着网络数据吞吐率攀升至 800 Gbit/s、1.6 Tbit/s 甚至更高,NVIDIA 已开始将硅光子技术与共封装光学(CPO)集成到其网络硬件中,包括 Quantum-X800 InfiniBand 和 Spectrum-X800 以太网平台。这些平台出厂即配备 800 Gb/s 端到端连接以及网内计算特性(例如 SHARP)。借助 CPO,光发送器被直接集成在交换芯片旁边。这大幅缩短了电气通路,从而实现机架间更高带宽的链路、降低功耗,并提升整体通信效率。
In practical terms, technologies like CPO are paving the way to connect hundreds and thousands of racks (AI factories) into a single unified fabric in which inter-rack bandwidth is no longer the bottleneck. Such optical networking advancements are crucial to the high-performance, inter-rack bandwidth needed to ensure that the network can keep up with the GPUs at ultrascale.从实际应用来看,CPO 等技术正在为将成百上千个机架(AI 工厂)连接成单一统一的交换网络铺平道路,使机架间带宽不再成为瓶颈。此类光网络技术的进步,对于提供确保网络在超大规模下跟上 GPU 步伐所需的高性能机架间带宽至关重要。
To summarize, inside an NVL72 rack, NVIDIA uses NVLink and NVSwitch to create a blazingly fast, all-to-all connected network between 72 GPUs. These interconnects are so fast and uniform that the GPUs effectively behave like one unit for many collective operations. Beyond the rack, high-speed NICs (e.g., InfiniBand or Ethernet) connect the rack to other racks or to storage, with DPUs to manage data movement efficiently.总而言之,在 NVL72 机架内部,NVIDIA 利用 NVLink 和 NVSwitch 在 72 个 GPU 之间构建了一个极速的全互联网络。这些互连速度极快且高度一致,以至于在许多集合通信操作中,这些 GPU 实际上表现得如同一个整体。在机架之外,高速网卡(NIC,如 InfiniBand 或以太网)将该机架与其他机架或存储相连,并由 DPU 高效管理数据搬运。
The NVL72 is an immensely powerful standalone system and a basic building block for larger AI supercomputers or AI factories. The concept of an AI factory, a large-scale AI data center composed of multiple such racks, is now becoming reality. NVI-DIA partners with OEM and system vendors like HPE and Supermicro to supply the GB200 NVL72 systems. NVIDIA’s hardware and network roadmaps are squarely aimed at enabling the AI factory vision. In short, the NVL72 shows how far codesign can go as the GPU, networking, and physical-rack hardware are built hand in hand to scale to thousands and millions of GPUs as seamlessly and efficiently as possible.NVL72 是一个功能极其强大的独立系统,也是构建更大型 AI 超级计算机或 AI 工厂 的基础构件。AI 工厂的概念——由多个此类机架组成的大规模 AI 数据中心——如今正在成为现实。NVIDIA 与 HPE 和 Supermicro 等 OEM 厂商和系统供应商合作,提供 GB200 NVL72 系统。NVIDIA 的硬件和网络路线图正是瞄准了实现 AI 工厂这一愿景。简而言之,NVL72 展示了协同设计所能达到的高度:GPU、网络与机架物理硬件携手打造,以尽可能无缝、高效地扩展到数千乃至数百万个 GPU。
计算密度与功耗需求
Compute Density and Power Requirements
The NVL72 rack is incredibly dense in terms of compute, which means it draws a very high amount of power for a single rack. A fully loaded NVL72 can consume up to ~130 kW of power under max load. This is more than 2× NVIDIA’s previous generation AI rack, which consumed around 50–60 kW. Packing 72 bleeding-edgeNVL72 机架的计算密度极高,这意味着对于单个机架而言,其功耗也非常高。满载配置的 NVL72 在最大负载下功耗可达约 130 kW,是 NVIDIA 上一代 AI 机架(功耗约 50–60 kW)的 2 倍以上。将 72 颗最尖端的
GPUs—and all the supporting hardware—into one rack pushes the limits of what data center infrastructure can handle.GPU——以及所有配套硬件——塞进一个机架,已将数据中心基础设施的承受能力推向极限。
To supply 130 kW to the NVL72 rack, you can’t just use a single standard power feed. Data centers will typically provision multiple high-capacity circuits to feed this kind of power. For instance, a data center can deploy two fully independent power feeds. In this case, each feed is sized to carry the entire rack load in case of a failure on one of the feeds.要为 NVL72 机架提供 130 kW 电力,仅靠一条标准供电线路是不够的。数据中心通常会配置多条大容量供电回路来输送这种级别的电力。例如,数据中心可以部署两条完全独立的供电线路。在这种情况下,每条线路的容量都按承载整个机架负载来设计,以防其中一条线路发生故障。
If one feed goes offline, the remaining circuit can support the full 130 kW draw to avoid a blown circuit. This kind of redundancy is important protection. Otherwise, the power interruption could halt your multimonth training job.如果其中一条供电线路断电,剩余回路仍可支撑全部 130 kW 的功耗,从而避免电路烧毁。这种冗余是重要的保障措施;否则,供电中断可能导致长达数月的训练任务被迫中止。
Within the rack, power is distributed to the power supplies of each 1U compute node. The power is converted from AC to DC for the local electronics. Each compute node in the NVL72 contains two Grace Blackwell Superchips, which together consume on the order of 6 kW. With 18 compute nodes, the total power consumed is ~110 kW. The NVSwitch trays, network switches, air cooling, and water cooling pumps account for ~20 kW for a total of 130 kW consumed by the entire NVL72 rack.在机架内部,电力分配给每个 1U 计算节点的电源。电力由交流转换为直流,供本地电子元件使用。NVL72 中的每个计算节点包含两个 Grace Blackwell 超级芯片,二者合计功耗在 6 kW 量级。18 个计算节点的总功耗约为 110 kW。NVSwitch 托盘、网络交换机、风冷和水冷泵再消耗约 20 kW,整个 NVL72 机架的总功耗为 130 kW。
The current used at a typical data center in voltages (e.g., 415 V 3-phase AC) is massive, so everything is engineered for high amperage. Operators have to carefully plan to host such a rack, which often requires dedicated power distribution units (PDUs) and careful monitoring. Power transients are also a consideration, as 72 GPUs, when ramping from idle to full power, could rapidly draw tens of kW of power in just milliseconds. A good design will include capacitors or sequencing to avoid large voltage drops.在典型数据中心的电压下(例如 415 V 三相交流电),电流非常大,因此所有设计都要针对大电流进行。运营方必须经过仔细规划才能托管这样的机架,这通常需要专用的电源分配单元(PDU)和严密的监控。功率瞬变也是需要考虑的因素:72 个 GPU 从空闲提升到满功率时,可能在短短几毫秒内迅速汲取数十 kW 的功率。良好的设计会加入电容器或时序控制,以避免出现大的电压降。
The system might stagger the GPU boost clocks by tiny intervals so they don’t all spike at exactly the same microsecond, smoothing out the surge. These are the kind of electrical engineering details that go into making a 130 kW rack manageable.系统可能会以微小的时间间隔错开各 GPU 的加速时钟,使它们不会恰好在同一微秒内同时飙升,从而平抑浪涌。正是这类电气工程细节,才让一个 130 kW 的机架变得可控。
It’s not far-fetched to call this NVL72 rack, at the cutting edge of high-density compute, a mini power substation. Eight of these racks combined for 576 GPUs would draw nearly 1 MW of power (8 racks × 130 kW per rack), which is the entire capacity of a small data center! The silver lining is that although 130 kW is a lot in one rack, you are also getting a lot of work done per watt.将这台处于高密度计算最前沿的 NVL72 机架称作一座小型变电站,并不牵强。8 个这样的机架合计 576 个 GPU,将消耗近 1 MW 的功率(8 个机架 × 每机架 130 kW),这相当于一个小型数据中心的全部容量!好的一面是,尽管单个机架 130 kW 的功耗不小,但每瓦电力所完成的工作量也相当可观。
If one NVL72 replaces several racks of older equipment, the overall efficiency is better. But you definitely need the infrastructure to support that concentrated power draw. And any facility hosting the NVL72 racks must ensure they have adequate power capacity and cooling, as we will discuss next.如果一个 NVL72 能取代数个机架的旧设备,整体效率会更高。但你肯定需要相应的基础设施来支撑如此集中的电力汲取。而且,任何部署 NVL72 机架的设施都必须确保具备充足的电力容量和散热能力,我们将在下文讨论。
液冷与风冷
Liquid Cooling Versus Air Cooling
Cooling 130 kW in one rack is beyond the reach of traditional air cooling. Blowing air over 72 GPUs that each can dissipate ~1,200 watts would require hurricane-like airflow and would be extremely loud and inefficient—not to mention the hot air exhaust would be brutal. As such, liquid cooling is the only practical solution for the NVL72 rack running at this power density.在单个机架内冷却 130 kW 的热量,超出了传统风冷的能力范围。为 72 个各自可散发约 1,200 瓦热量的 GPU 吹送空气,需要飓风般的气流,而且会极其嘈杂、效率低下——更不用说排出的热风会有多么难以忍受。因此,液冷是以这种功率密度运行的 NVL72 机架唯一可行的解决方案。
The NVL72 is a fully liquid-cooled system. Each Grace Blackwell Superchip module and each NVSwitch chip has a cold plate attached. A cold plate is a metal plate with internal tubing that sits directly on the component. A water-based coolant liquid flows through the tubing to carry away heat. All these cold plates are linked by hoses, manifolds, and pumps that circulate the coolant throughout the system.NVL72 是一个全液冷系统。每个 Grace Blackwell 超级芯片模块和每个 NVSwitch 芯片都装有冷板(cold plate)。冷板是一块带有内部管路的金属板,直接贴合在元件上。水基冷却液流经管路带走热量。所有这些冷板通过软管、歧管和泵连接起来,使冷却液在整个系统中循环。
Typically, the rack will have quick-disconnect couplings for each node so you can slide a server in or out without spilling the coolant. The rack then has supply and return connections to the external facility’s chilled water system. Often, there’s a heat exchanger called a Coolant Distribution Unit (CDU) either built into the rack or immediately next to it. The CDU transfers heat from the rack’s internal coolant loop to the data center’s water loop.通常,机架会为每个节点配备快速接头,这样在插入或抽出服务器时不会泄漏冷却液。机架随后通过供水和回水接口连接到外部设施的冷冻水系统。通常还会有一个称为冷却液分配单元(Coolant Distribution Unit,CDU)的换热器,或内置于机架中,或紧邻机架放置。CDU 将热量从机架内部的冷却液回路传递到数据中心的水回路。
The facility provides chilled water at 20–30°C. The water absorbs the heat through the heat exchanger. The warmed-up water is then pumped back into the chillers or cooling towers to be cooled again. In modern designs, they might even run warm water cooling, in which chilled water comes into the system at 30°C and leaves at 45°C. The water can then be cooled by evaporative cooling towers without active refrigeration, improving overall efficiency. The point is, water, or a liquid coolant, can carry far more heat per unit of flow than air, so liquid cooling is vastly more effective when running at high watts in small spaces.设施提供 20–30°C 的冷冻水。水通过热交换器吸收热量。升温后的水随后被泵回冷水机组或冷却塔重新冷却。在现代设计中,甚至可能采用温水冷却,即冷冻水以 30°C 进入系统、以 45°C 离开。随后这些水可由蒸发式冷却塔冷却,无需主动制冷,从而提升整体效率。关键在于,水或液体冷却剂在单位流量下能带走的热量远超空气,因此在狭小空间内运行高功率负载时,液冷的效果要好得多。
By keeping the GPU and CPU temperatures much lower than they would be with air, liquid cooling reduces thermal GPU throttling. The GPUs can sustain their maximum clocks without hitting temperature limits. Also, running chips cooler improves reliability and even efficiency since power leakage is lower when running at lower temperatures.通过让 GPU 和 CPU 的温度远低于风冷条件下的水平,液冷减少了 GPU 的热降频。GPU 可以在不触及温度上限的情况下维持最高时钟频率。此外,芯片运行温度更低还能提升可靠性乃至效率,因为低温运行时功率漏电更少。
The NVL72 keeps GPU temps in the 50–70°C range under load, which is excellent for such power-hungry devices. The cold plates and coolant loops have been engineered very carefully to allow each GPU to dump 1,000 W and each CPU to dump 500 W into the system. In addition, the coolant flow rate has to be sufficient to remove that heat quickly. A rough estimate shows on the order of 150–200 liters per minute at a 10–12°C water temperature rise to dissipate about 130 kW.NVL72 在负载下将 GPU 温度保持在 50–70°C 区间,对于如此高功耗的设备而言非常出色。冷板和冷却液回路经过精心设计,使每个 GPU 可向系统排出 1,000 W、每个 CPU 可排出 500 W 的热量。此外,冷却液流速必须足以快速带走这些热量。粗略估算显示,在 10–12°C 的水温升下,需要约 150–200 升/分钟的流量才能耗散约 130 kW 的热量。
The system undoubtedly has sensors and controls for coolant temperature, pressure, and leak detection. If a leak is detected from its drip or pressure-loss sensors, the system can shut down or isolate that section quickly. It’s recommended to use self-sealing connections—and perhaps a secondary containment tray—to minimize the risk of leaking fluids.该系统无疑配备了针对冷却液温度、压力和泄漏检测的传感器与控制装置。如果其滴漏传感器或压力损失传感器检测到泄漏,系统可以迅速停机或隔离该区段。建议使用自密封接头——或许再加装二次围堵托盘——以将液体泄漏风险降到最低。
This level of liquid cooling in racks was once exotic, but it is now the standard for these large-scale AI clusters. Companies like Meta, xAI, and Google are adopting liquid cooling for their AI clusters because air cooling simply cannot support the large amount of power drawn from these systems.这种机架级液冷曾经十分罕见,但如今已成为这些大规模 AI 集群的标准配置。Meta、xAI 和 Google 等公司正在为其 AI 集群采用液冷,因为风冷根本无法支撑这些系统所汲取的巨大功率。
So while an NVL72 requires more facility complexity, including liquid-cooling loops, many data centers are now built with liquid cooling in mind. The NVL72 rack, with its built-in internal liquid cooling, can be connected directly to the cooling loop.因此,尽管 NVL72 需要更高的设施复杂度(包括液冷回路),如今许多数据中心在建设时已考虑到液冷。NVL72 机架内置内部液冷,可直接接入冷却回路。
One side effect of the internal liquid cooling is the weight of the rack. The NVL72 rack weighs on the order of 3,000 lbs (1.3–1.4 metric tons) when filled with hardware and coolant. This is extremely heavy for a rack, as it’s roughly the weight of a small car but concentrated on a few square feet of floor. Data centers with raised floors have to check that the floor can support this load, measured in pounds per square foot. Often, high-density racks are placed on reinforced slabs or supported by additional struts. Moving such a rack requires special equipment such as forklifts. This is all part of the deployment consideration, as you’re installing an AI supercomputer, which comes with its unique physical and logistical challenges.内部液冷的一个副作用是机架重量。装满硬件和冷却液后,NVL72 机架重约 3,000 磅(1.3–1.4 公吨)。这对机架而言极其沉重,大致相当于一辆小型汽车的重量,却集中在几平方英尺的地面上。采用架空地板的数据中心必须核查地板能否承受这一载荷(以磅/平方英尺计)。高密度机架通常被放置在加固的楼板上,或由额外的支撑柱承托。移动这样的机架需要叉车等专用设备。这些都是部署考量的一部分,因为你安装的是一台 AI 超级计算机,它自带独特的物理与物流挑战。
NVIDIA also integrates management and safety features in the form of a rack management controller that oversees things like coolant pumps, valve positions, and power usage, and monitors every node’s status. Administrators can interface with it to do things like update firmware across all nodes, or to shut down the system safely.NVIDIA 还以机架管理控制器的形式集成了管理与安全功能,由它监管冷却液泵、阀门位置和功耗等事项,并监控每个节点的状态。管理员可与其交互,执行诸如为所有节点更新固件或安全关闭系统等操作。
All these considerations illustrate that the NVL72 was codesigned with data center infrastructure in mind. NVIDIA worked on the compute architecture in tandem with system engineers who figured out power delivery and cooling, and in tandem with facility engineers who specified how to install and run these things. It’s not just about fast chips—it’s about delivering a balanced, usable system.上述所有考量都表明,NVL72 是与数据中心基础设施协同设计的。NVIDIA 在开发计算架构的同时,与负责解决供电和散热问题的系统工程师紧密协作,也与明确规定这些设备如何安装和运行的设施工程师紧密协作。这不仅仅关乎打造快速的芯片,更关乎交付一个均衡、可用的系统。
The payoff for this complexity is huge. By pushing the limits of power and cooling, an enormous, amount of compute is concentrated into a single rack and translates to a large amount of compute-per-watt. Yes, 130 kW is a lot of power, but per GPU or per trillion FLOP (TFLOP), it’s actually efficient compared to spreading the same GPUs across multiple racks with less efficient cooling.这种复杂性带来的回报是巨大的。通过将供电和散热推向极限,海量的算力被集中到单个机架中,并转化为可观的每瓦算力。没错,130 kW 是很大的功率,但按每块 GPU 或每万亿次浮点运算(TFLOP)来衡量,与将同样的 GPU 分散到多个散热效率较低的机架中相比,它实际上是高效的。
实践中的性能监控与利用率
Performance Monitoring and Utilization in Practice
When you have a machine this powerful, you want to make sure you’re getting the most out of it. Operating an NVL72 effectively requires careful monitoring of performance, utilization, and power. NVIDIA provides tools like Data Center GPU Manager (DCGM) that can track metrics on each GPU for things like GPU utilization percentage, memory usage, temperature, and NVLink throughput.当你拥有这样一台强大的机器时,你自然希望充分发挥它的效能。高效运营 NVL72 需要对性能、利用率和功率进行细致监控。NVIDIA 提供了 Data Center GPU Manager(DCGM)等工具,可以跟踪每块 GPU 的各项指标,例如 GPU 利用率百分比、显存使用量、温度以及 NVLink 吞吐量。
As a performance engineer, you’d keep an eye on these during training runs and inference workloads. Ideally, you want your GPUs to be near 100% utilized most of the time during a training job. If you see GPUs at 50% utilization, that means something is keeping them idle for half the time. Perhaps there is a data loading bottleneck or a synchronization issue.作为性能工程师,在训练运行和推理工作负载期间,你需要密切关注这些指标。理想情况下,你希望 GPU 在训练作业的大部分时间里都接近 100% 的利用率。如果你看到 GPU 的利用率只有 50%,那就意味着有某种因素使它们在一半的时间里处于空闲状态,也许是存在数据加载瓶颈,也许是存在同步问题。
Similarly, you can monitor the NVLink usage. If your NVLink links are saturating frequently, communication is likely the culprit. The BlueField DPUs and NICs have their own statistics that are monitored to ensure that you’re not saturating your storage links when reading data. Modern systems like the NVL72 expose this telemetry.同样,你也可以监控 NVLink 的使用情况。如果 NVLink 链路频繁达到饱和,那么通信很可能就是罪魁祸首。BlueField DPU 和网卡(NIC)各有自己的统计信息,对这些信息进行监控可以确保你在读取数据时不会使存储链路饱和。NVL72 这类现代系统会暴露这些遥测数据。
Power monitoring is also crucial. At ~130 kW, even a small inefficiency or misconfiguration can waste a lot of power and money. The system likely lets you monitor power draw per node or per GPU. Administrators might cap the power or clocks of GPUs if full performance isn’t needed, to save energy.功率监控同样至关重要。在约 130 kW 的量级下,哪怕是很小的低效或配置错误也会浪费大量电力和资金。系统应该可以让你监控每个节点或每块 GPU 的功耗。如果不需要全部性能,管理员可以限制 GPU 的功率或时钟频率,以节约能源。
NVIDIA GPUs allow setting power limits. For instance, if you’re running a smaller job that doesn’t need every last drop of performance, you could dial down GPU clocks to improve efficiency—measured in performance per watt—and still meet your throughput requirement. This could save kilowatts of power in the process. Over weeks of training, this can translate to significant savings and cost efficiency.NVIDIA GPU 允许设置功率上限。例如,如果你运行的是一个不需要榨干每一分性能的较小作业,可以调低 GPU 时钟频率来提高效率——以每瓦性能衡量——同时仍能满足吞吐量需求。在此过程中可以节省数千瓦的电力。在长达数周的训练过程中,这可以转化为可观的节省和成本效益。
共享与调度
Sharing and Scheduling
Another aspect is sharing and scheduling workloads on the NVL72. Rarely will every single job need all 72 GPUs. You might have multiple teams or multiple experiments running on subsets of GPUs. Using a cluster scheduler like SLURM or Kubernetes with NVIDIA’s plugins, you can carve out, say, 8 GPUs for one user, 16 GPUs for another user, and 48 GPUs for yet another user—all within the same rack.另一个方面是在 NVL72 上共享和调度工作负载。很少有作业需要用到全部 72 块 GPU。你可能让多个团队或多个实验在 GPU 的子集上运行。借助 SLURM 或 Kubernetes 等集群调度器以及 NVIDIA 的插件,你可以在同一个机架内划分出例如 8 块 GPU 给一位用户、16 块 GPU 给另一位用户、48 块 GPU 给第三位用户。
Furthermore, NVIDIA’s Multi-Instance GPU (MIG) feature lets you split a single physical GPU into smaller GPUs partitioned at the hardware level. For example, one Blackwell GPU with 180 GB of GPU memory could be split into smaller chunks to run many small inference jobs concurrently.此外,NVIDIA 的多实例 GPU(MIG)特性允许你将单个物理 GPU 拆分为在硬件层面分区的多个更小 GPU。例如,一块拥有 180 GB GPU 显存的 Blackwell GPU 可以被切分为更小的部分,从而并发运行许多小型推理作业。
Each Blackwell GPU supports up to seven fully isolated MIG instances. This allows one physical GPU to be partitioned into up to seven smaller GPUs with dedicated memory and SMs. MIG sizes are fixed by product generation. We will dive into the details of MIG partitions in the next chapter.每块 Blackwell GPU 最多支持七个完全隔离的 MIG 实例。这使得一块物理 GPU 可以被划分为最多七个拥有专用内存和流多处理器(SM)的更小 GPU。MIG 的规格大小由产品代际固定。我们将在下一章深入探讨 MIG 分区的细节。
In practice, with such a large GPU, MIG might be used for inference scenarios where you want to serve many models on one GPU. The presence of the BlueField DPU also enables secure multitenancy as the DPU can act as a firewall and virtual switch. This isolates network traffic for different jobs and users. This means an organization could safely let different departments or even external clients use partitions of the system without interfering with one another—similar to how cloud providers partition a big server for multiple customers with secure multitenant isolation.在实践中,对于这样一块大型 GPU,多实例 GPU(MIG)可能用于这样的推理场景:在一块 GPU 上服务多个模型。BlueField DPU 的存在还使安全多租户(multitenancy)成为可能,因为 DPU 可以充当防火墙和虚拟交换机,从而隔离不同作业和用户的网络流量。这意味着一个组织可以放心地让不同部门甚至外部客户使用系统的不同分区而互不干扰——类似于云提供商通过安全的多租户隔离将一台大型服务器划分给多个客户的方式。
From a cost perspective, a system like NVL72 is a multimillion dollar asset, and it could consume tens of thousands of dollars in electricity per month. So you really want to do as much useful work, or goodput, as possible. If it sits idle, that’s a lot of capital and operational cost wasted. This is why monitoring utilization over time is important. You might track GPU hours used versus available hours.从成本角度看,像 NVL72 这样的系统是一笔数百万美元的资产,每月可能消耗数万美元的电费。因此,你确实希望尽可能多地完成有用的工作,即有效吞吐(goodput)。如果它闲置不用,就会浪费大量资本和运营成本。这就是为什么持续监控利用率非常重要。你可以跟踪已使用的 GPU 小时数与可用小时数的对比。
If you find that the system is underutilized, you might want to consolidate workloads or offer it to additional teams for more projects. Some organizations implement a chargeback model where internal teams use their own budget to pay per GPU-hour of usage. This encourages efficient use and accounts for electricity and depreciation costs. Such transparency ensures that people value the resource.如果发现系统利用率不足,你可能希望整合工作负载,或将其提供给更多团队开展更多项目。一些组织实行内部计费(chargeback)模式,即内部团队用自己的预算按每 GPU 小时的使用量付费。这能鼓励高效使用,并将电力和折旧成本纳入核算。这种透明度确保人们珍视这一资源。
硬件升级的投资回报率
ROI of Upgrading Your Hardware
One might ask if it’s worth investing in this bleeding-edge hardware. When analyzing the return on investment (ROI), the answer often comes down to performance per dollar. If NVL72 can do the work of, say, four older-generation racks, it might actually save money long-term, both in hardware and power. Earlier in the chapter, we discussed how one Blackwell GPU could replace 2–3 Hopper GPUs in terms of throughput. This means if you upgrade, you might need fewer total GPUs for the same work.有人可能会问,投资这种最前沿的硬件是否值得。在分析投资回报率(ROI)时,答案往往归结为每美元性能。如果 NVL72 能完成相当于四个上一代机架的工作量,那么从长期来看,它在硬件和电力两方面实际上可能节省资金。本章前面讨论过,一块 Blackwell GPU 在吞吐量方面可以替代 2–3 块 Hopper GPU。这意味着如果进行升级,完成同样的工作所需的 GPU 总数可能更少。
Let’s analyze a quick case study. Suppose you currently have 100 H100 GPUs handling your workload. You could potentially handle it with 50 Blackwell GPUs because each is more than twice as fast (or more, using FP8/FP4). So you’d buy 50 instead of 100 GPUs. And even if each Blackwell costs more than an H100, buying half as many could be cost-neutral or better. Power-wise, 100 H100s might draw 70 kW, whereas 50 Blackwells might draw 50 kW for the same work. This is a notable power savings.我们来快速分析一个案例。假设你目前有 100 块 H100 GPU 在处理你的工作负载。由于每块 Blackwell GPU 的速度是 H100 的两倍以上(使用 FP8/FP4 时甚至更快),你或许只需 50 块 Blackwell GPU 就能处理这些工作。因此你只需购买 50 块而不是 100 块 GPU。即使每块 Blackwell 的价格高于 H100,购买一半的数量也可能使总成本持平甚至更低。在功耗方面,100 块 H100 可能消耗 70 kW,而 50 块 Blackwell 完成同样的工作可能只消耗 50 kW。这是相当可观的电力节省。
Over a year, that power difference saves tens of thousands of dollars. Additionally, fewer GPUs means fewer servers to maintain, which means less overhead in CPUs, RAM, and networking for those servers, providing even further savings. All told, an upgrade to new hardware can pay for itself in 1–2 years in some cases—especially if you have enough work to keep them busy 24 hours a day.一年下来,这一功耗差异可节省数万美元。此外,GPU 更少意味着需要维护的服务器更少,也就意味着这些服务器在 CPU、内存和网络方面的开销更少,从而带来进一步的节省。总而言之,在某些情况下,升级到新硬件可以在 1–2 年内收回成本——尤其是当你的工作量足以让它们每天 24 小时保持繁忙时。
The math obviously depends on exact prices and usage patterns, but the point is that the ROI for adopting the latest AI hardware can be very high for large-scale deployments. Besides the tangible ROI, there are soft benefits like using a single powerful system instead of many smaller ones that can simplify your system architecture. This simplification improves operational efficiency by lowering power consumption and reducing network complexity.这笔账显然取决于具体价格和使用模式,但关键在于,对于大规模部署而言,采用最新 AI 硬件的投资回报率可能非常高。除了有形的投资回报率之外,还有一些软性收益,例如用一个强大的系统替代许多较小的系统,从而简化系统架构。这种简化通过降低功耗和减少网络复杂性来提高运营效率。
For example, not having to split models across multiple older GPUs due to memory limits can simplify software and reduce engineering complexity. Also, having the latest hardware ensures you can take advantage of the newest software optimizations and keep up with competitors who also upgrade. Nobody wants to be left training and serving models at half the speed of rivals. Upgrading will improve your performance while simultaneously enabling larger models, faster iterations, and quicker responses.例如,不必因内存限制而将模型拆分到多块较旧的 GPU 上,这可以简化软件并降低工程复杂性。此外,拥有最新硬件能确保你利用最新的软件优化,并跟上同样在升级的竞争对手。没有人愿意在训练和服务模型时速度只有对手的一半。升级将提升你的性能,同时让你能够运行更大的模型、实现更快的迭代和更快的响应。
Running an NVL72 effectively is as much a software and management challenge as it is a hardware feat. The hardware gives you incredible potential, but it’s up to the engineers to harness the full power of the hardware by monitoring performance, keeping utilization high, and scheduling jobs smartly.高效运行 NVL72 既是一项硬件成就,也是一项软件与管理挑战。硬件提供了巨大的潜力,但工程师需要通过监控性能、保持高利用率以及智能调度任务来充分释放硬件的全部算力。
The good news is NVIDIA provides a rich software stack to monitor and improve performance, including drivers, profilers, container runtimes, and cluster orchestration tools. Throughout the rest of the book, we’ll see how to optimize software to fully utilize systems like the GB200/GB300 NVL72. For now, the takeaway is that when you’re given an AI system with exaFLOPS-scale performance in a box, you need equally advanced strategies to make every flop and every byte count.好消息是,NVIDIA 提供了丰富的软件栈用于监控和提升性能,包括驱动程序、性能剖析器、容器运行时和集群编排工具。在本书后续章节中,我们将探讨如何优化软件以充分利用 GB200/GB300 NVL72 等系统。目前的要点是,当你获得一台具备 exaFLOPS 级性能的 AI 系统时,你需要同样先进的策略来确保每一次浮点运算和每一个字节都物尽其用。
未来展望:NVIDIA 路线图
A Glimpse into the Future: NVIDIA’s Roadmap
At the time of writing, the Grace Blackwell NVL72 platform represents the state-ofthe-art in AI hardware. But NVIDIA is already preparing the next leaps. It’s worth briefly looking at NVIDIA’s hardware roadmap for the coming few years, because it shows a clear pattern of scaling. NVIDIA intends to continue doubling down on performance, memory, and integration.截至撰写本书时,Grace Blackwell NVL72 平台代表了 AI 硬件的最先进水平。但 NVIDIA 已经在为下一次飞跃做准备。简要回顾 NVIDIA 未来几年的硬件路线图是值得的,因为它展示了一个清晰的扩展模式。NVIDIA 打算继续在性能、内存和集成度上加倍投入。
Blackwell Ultra 与 Grace Blackwell Ultra
Blackwell Ultra and Grace Blackwell Ultra
NVIDIA’s Blackwell Ultra (B300) and corresponding Grace Blackwell Ultra Superchip (GB300) are a drop-in upgrade to the NVL72 architecture. Each Blackwell Ultra B300 GPU has approximately 50% more memory capacity (288 GB) than the B200 (180 GB)—as well as 1.5× higher AI compute performance and larger on-die accelerators specifically designed for attention operations and reduced precision (e.g., NVFP4). This translates to the Blackwell B300 producing 45-50% higher inference throughput than the B200.NVIDIA 的 Blackwell Ultra (B300) 及相应的 Grace Blackwell Ultra 超级芯片 (GB300) 是 NVL72 架构的直接升级替代品。每颗 Blackwell Ultra B300 GPU 的显存容量约为 288 GB,比 B200 (180 GB) 高出约 50%;其 AI 计算性能提高了 1.5 倍,并配备了专为注意力操作和低精度(例如 NVFP4)设计的更大片上加速器。这使得 Blackwell B300 的推理吞吐量比 B200 高出 45-50%。
A 72-GPU rack of GB300s consists of 36 Grace Blackwell Ultra modules (2 GPUs + 1 CPU each), ~20.7 TB of HBM (72 × 288 GB), and ~18 TB of DDR (36 × 500 GB). Combined, this is ~38 TB of fast memory per GB300 NVL72 rack. And the intra-rack NVLink and NVSwitch networks in the GB300 NVL72 Ultra use the same NVLink 5 generation as the GB200 NVL72.由 72 颗 GB300 GPU 组成的机架包含 36 个 Grace Blackwell Ultra 模块(每个模块含 2 颗 GPU + 1 颗 CPU)、约 20.7 TB 的 HBM(72 × 288 GB)以及约 18 TB 的 DDR(36 × 500 GB)。综合来看,每个 GB300 NVL72 机架拥有约 38 TB 的高速显存。GB300 NVL72 Ultra 机架内的 NVLink 和 NVSwitch 网络使用与 GB200 NVL72 相同的 NVLink 5 代技术。
In short, the GB300 is an evolutionary upgrade to the GB200, as it uses the same architecture. However, it has more of everything, including more SMs, higher memory, and faster clocks.简而言之,GB300 是 GB200 的演进式升级,因为它采用相同的架构。然而,它在各方面都更强,包括更多的流多处理器(SM)、更高的显存容量和更快的时钟频率。
Vera Rubin 超级芯片 (2026)
Vera Rubin Superchip (2026)
Codenamed after the female astronomer whose work provided evidence of dark matter, the Vera Rubin Superchip (VR200) is the next major architecture step. Vera is the ARM-based CPU successor to the Grace CPU, and Rubin is the GPU architecture successor to Blackwell. NVIDIA continues the superchip concept by combining one Vera CPU with two Rubin GPUs in a single module (VR200) similar to the Grace Blackwell (GB200/GB300) configuration.Vera Rubin 超级芯片 (VR200) 以发现暗物质证据的女天文学家命名,是下一个主要的架构步骤。Vera 是 Grace CPU 的 ARM 架构继任者,而 Rubin 是 Blackwell 的 GPU 架构继任者。NVIDIA 延续了超级芯片概念,将一颗 Vera CPU 与两颗 Rubin GPU 组合在单个模块 (VR200) 中,类似于 Grace Blackwell (GB200/GB300) 的配置。
The Vera CPU uses TSMC’s 3nm semiconductor process with more CPU cores and faster LPDDR6 memory running at approximately 1 TB/s. The Rubin GPU supports higher GPU high-bandwidth memory (HBM) running at approximately 13–14 TB/s.Vera CPU 采用台积电 (TSMC) 的 3nm 半导体工艺,拥有更多 CPU 核心,并运行速度约为 1 TB/s 的更快 LPDDR6 内存。Rubin GPU 支持带宽约为 13–14 TB/s 的更高带宽 GPU 高带宽显存 (HBM)。
NVLink is also expected to move to its sixth generation, NVLink 6, which would double the CPU-to-GPU and GPU-to-GPU link bandwidth. There’s also speculation that the Vera Rubin could allow more nodes per rack—or more racks per NVLink domain—to scale beyond the 576 GPU limit of the eight-rack GB200/GB300 NVL72 cluster.NVLink 预计也将升级到第六代 NVLink 6,这将使 CPU 到 GPU 以及 GPU 到 GPU 的链路带宽翻倍。还有推测认为,Vera Rubin 可能允许每个机架容纳更多节点——或者每个 NVLink 域容纳更多机架——从而突破八机架 GB200/GB300 NVL72 集群 576 颗 GPU 的限制。
The bottom line is that the Vera Rubin generation is yet another ~2× jump in most metrics, including more cores, more memory, more bandwidth, and more TFLOPS. Rubin GPUs increase SM counts to ~200 SMs per die. This could further add efficiency improvements. They could also integrate new features like second-generation FP4 or even experimental 2-bit precisions, though that’s just speculation at this point.总而言之,Vera Rubin 一代在大多数指标上又实现了约 2 倍的飞跃,包括更多核心、更多内存、更高带宽和更多 TFLOPS。Rubin GPU 将每颗芯片的 SM 数量增加到约 200 个。这可能会进一步提升效率。它们还可能集成第二代 FP4 甚至实验性的 2-bit 精度等新特性,尽管目前这仅是推测。
Another especially interesting possibility is that because Rubin’s 288 GB HBM RAM is still a bottleneck for large AI models, NVIDIA might incorporate some second-tier memory for GPUs directly in the GPU module. For instance, they may place some LPDDR memory directly on the base of the GPU module to act as an even larger, but slower, memory pool for the GPU—separate from Vera’s CPU DDR memory.另一个特别有趣的可能性是,由于 Rubin 的 288 GB HBM 显存对大型 AI 模型而言仍是瓶颈,NVIDIA 可能会在 GPU 模块中直接集成某种面向 GPU 的二级显存。例如,他们可能将一些 LPDDR 内存直接置于 GPU 模块的基板上,作为 GPU 一个更大但更慢的显存池——与 Vera 的 CPU DDR 内存相互独立。
If this happens, a single GPU module could have ~550 GB (288 GB HBM + 256 GB LPDDR) of total cache-coherent, unified memory. This would further blur the line between CPU and GPU memory, as GPUs would have a multitier memory hierarchy of their own. Whether this happens with the Rubin GPU generation or not, it’s a direction to keep an eye on.如果这一设想成真,单个 GPU 模块将拥有约 550 GB(288 GB HBM + 256 GB LPDDR)的缓存一致统一内存总量。这将进一步模糊 CPU 内存与 GPU 显存之间的界限,因为 GPU 将拥有自己的多级显存层次结构。无论这一设想是否会在 Rubin 这一代 GPU 上实现,这都是一个值得关注的方向。
Overall, the Vera Rubin and Vera Rubin Ultra racks deliver 5× the performance of a GB200/GB300 NVL72. They also run at 5× the power—nearly 600 kW per rack. The VR200/VR300 NVL system comes with a massive amount of total GPU HBM per rack across all of the Rubin GPUs (288 GB HBM per GPU) plus tens of TB of CPU memory. And NVLink 6 within the rack incurs less communication overhead than NVLink 5.总体而言,Vera Rubin 和 Vera Rubin Ultra 机架可提供 GB200/GB300 NVL72 的 5 倍性能,同时功耗也是 5 倍——每机架接近 600 kW。VR200/VR300 NVL 系统在每机架内的所有 Rubin GPU 上配备总量极为可观的 GPU HBM(每 GPU 288 GB HBM),外加数十 TB 的 CPU 内存。而且机架内的 NVLink 6 相比 NVLink 5 通信开销更低。
Rubin Ultra 与 Vera Rubin Ultra(2027)
Rubin Ultra and Vera Rubin Ultra (2027)
Following the pattern, an “Ultra” version of Rubin (R300) and Vera Rubin arrives a year after the original release. One report suggests that NVIDIA might move to a four-die GPU module by then. This would combine two dual-die Rubin packages and put them together to yield a quad-die Rubin GPU. This R300 Rubin Ultra GPU module has four GPU dies on one package and 16 HBM stacks totaling 1 TB of HBM memory on a single R300 GPU module. The four dies together double the cores of the dual-die B300 module.按照这一规律,Rubin(R300)和 Vera Rubin 的“Ultra”版本将在首发一年后推出。有报告称,届时 NVIDIA 可能会转向四裸片(die)GPU 模块。这将把两个双裸片 Rubin 封装组合在一起,构成一个四裸片 Rubin GPU。这款 R300 Rubin Ultra GPU 模块在单个封装上集成四个 GPU 裸片和 16 个 HBM 堆栈,单个 R300 GPU 模块的 HBM 显存总量达 1 TB。四个裸片合计使核心数量达到双裸片 B300 模块的两倍。
In particular, the Vera Rubin NVL144 system has 144 of those dies across the rack. This is 36 superchip modules of four dies each. There is also a Vera Rubin NVL576 configuration that will have 4× the GPU count with multidie packages in the complete system.具体来说,Vera Rubin NVL144 系统在整个机架内共有 144 个此类裸片,即 36 个超级芯片(Superchip)模块,每个模块含四个裸片。此外还有 Vera Rubin NVL576 配置,其完整系统采用多裸片封装,GPU 数量将达到 4 倍。
By 2027, each rack could be pushing 3–4 exaFLOPS of compute performance and a combined 165 TB of GPU HBM RAM (288 GB HBM per Rubin GPU × 576 GPUs). While these numbers are still a bit speculative, the trajectory toward ultrascale AI systems with a massive number of exaFLOPS for compute and terabytes for GPU HBM RAM is clear.到 2027 年,每个机架的计算性能可能高达 3–4 exaFLOPS,GPU HBM 显存合计达 165 TB(每 Rubin GPU 288 GB HBM × 576 个 GPU)。尽管这些数字仍带有一定推测成分,但朝着拥有海量 exaFLOPS 级计算能力和数 TB 级 GPU HBM 显存的超大规模 AI 系统演进的趋势已十分清晰。
Feynman GPU(2028)与每年翻倍
Feynman GPU (2028) and Doubling Something Every Year
NVIDIA has code-named the post-Rubin generation as Feynman, which is scheduled for a 2028 release. Details are scarce, but the Feynman GPU will likely move to an even finer 2 nm TSMC process node. It will likely use HBM5 and include even more DDR memory inside the module. And perhaps it will double the number of dies from four to eight.NVIDIA 已将 Rubin 之后的下一代产品代号为 Feynman,计划于 2028 年发布。目前细节寥寥,但 Feynman GPU 很可能采用更精细的 2 nm TSMC 工艺节点,很可能使用 HBM5,并在模块内部集成更多 DDR 内存,或许还会将裸片数量从四个翻倍至八个。
By 2028, it’s expected that inference demands will surely dominate AI workloads— especially as reasoning continues to evolve in AI models. Reasoning requires hundreds or thousands of times more inference-time computation than previous, non-reasoning models. As such, chip designs will likely optimize for inference efficiency at scale, which might include more novel precisions, more on-chip memory, and on-package optical links to improve NVLink’s throughput even further.到 2028 年,预计推理需求必将主导 AI 工作负载——尤其是随着 AI 模型中推理(reasoning)能力的持续演进。推理所需的推理时计算量是此前非推理模型的数百倍乃至数千倍。因此,芯片设计可能会针对规模化推理效率进行优化,这可能包括更新颖的精度格式、更多的片上内存,以及封装内光链路,从而进一步提升 NVLink 的吞吐量。
NVIDIA seems to be doubling something every generation, every year if possible. One year they double memory, another year they double the number of dies, another year they double interconnect bandwidth, and so on. Over a few years, the compound effect of this doubling is huge. NVIDIA’s aggressive trajectory can be seen in how each generation doubles something significant. For instance, Blackwell introduced dual GPU dies (two dies per module instead of one), NVLink bidirectional bandwidth per link doubled from ~900 GB/s to ~1.8 TB/s, and per-GPU memory increases from 180 GB in Blackwell to ~288 GB in the Blackwell Ultra generation. Rubin and Feynman further increase compute, memory, and bandwidth.NVIDIA 似乎在每一代产品中都将某项指标翻倍,如果可能的话甚至每年翻倍。某一年是内存翻倍,另一年是裸片数量翻倍,再一年是互连带宽翻倍,诸如此类。经过几年时间,这种翻倍的复合效应十分巨大。NVIDIA 激进的发展轨迹体现在:每一代产品都会将某项重要指标翻倍。例如,Blackwell 引入了双 GPU 裸片设计(每个模块包含两颗裸片而非一颗),NVLink 每链路双向带宽从约 900 GB/s 翻倍至约 1.8 TB/s,单 GPU 显存从 Blackwell 的 180 GB 增至 Blackwell Ultra 一代的约 288 GB。Rubin 和 Feynman 则进一步提升算力、内存和带宽。
NVIDIA repeatedly talks about AI factories where the racks are the production lines for AI models. NVIDIA envisions offering a rack as a service through its partners so companies can rent a slice of a supercomputer rather than building everything themselves. This trend will likely continue as the cutting-edge hardware will be delivered as integrated pods that you can deploy. And each generation allows you to swap in new pods to double your capacity, increase your performance, and reduce your cost.NVIDIA 反复谈及 AI 工厂,其中机架就是 AI 模型的生产线。NVIDIA 设想通过其合作伙伴提供机架即服务,让企业可以租用超级计算机的一个切片,而不必自行构建一切。这一趋势很可能延续,因为前沿硬件将以可部署的集成式机柜(pod)形式交付。而且每一代产品都允许你换入新的机柜,从而实现容量翻倍、性能提升和成本降低。
For us as performance engineers, what matters is that the hardware will keep unlocking new levels of scale. Models that are infeasible today might become routine in a few years. It also means we’ll have to continually adapt our software to leverage things like new precision formats, larger memory pools, and improved interconnects. This is an exciting time as the advancement of frontier models is very much tied to these hardware innovations.对于我们这些性能工程师而言,关键在于硬件将持续解锁新的规模层级。如今不可行的模型,几年后可能变得司空见惯。这也意味着我们必须持续调整软件,以利用新的精度格式、更大的显存池以及改进的互连等特性。这是一个激动人心的时代,因为前沿模型的进步与这些硬件创新息息相关。
关键要点
Key Takeaways
The following innovations collectively enable NVIDIA’s hardware to handle ultralarge AI models with unprecedented speed, efficiency, and scalability:以下创新共同使 NVIDIA 硬件能够以前所未有的速度、效率和可扩展性处理超大规模 AI 模型:
- Integrated superchip architecture集成超级芯片架构
- NVIDIA fuses ARM-based CPUs (Grace) with GPUs (Hopper/Blackwell) into a single superchip, which creates a unified memory space. This design simplifies data management by eliminating the need for manual data transfers between CPU and GPU.NVIDIA 将基于 ARM 的 CPU(Grace)与 GPU(Hopper/Blackwell)融合为单一超级芯片,从而创建统一内存空间。该设计通过消除 CPU 与 GPU 之间手动数据传输的需求,简化了数据管理。
- Unified memory architecture统一内存架构
- The unified memory architecture and coherent interconnect reduce the programming complexity. Developers can write code without worrying about explicit data movement, which accelerates development and helps them focus on improving AI algorithms.统一内存架构与一致性互连降低了编程复杂度。开发者编写代码时无需担心显式数据移动,这加速了开发,并帮助他们专注于改进 AI 算法。
- Ultrafast interconnects超高速互连
- Using NVLink (including NVLink-C2C and NVLink 5) and NVSwitch, the system achieves extremely high intra-rack bandwidth and low latency. This means GPUs can communicate nearly as if they were parts of one large processor, which is critical for scaling AI training and inference.通过使用 NVLink(包括 NVLink-C2C 和 NVLink 5)和 NVSwitch,系统实现了极高的机架内带宽和低时延。这意味着 GPU 之间的通信几乎如同它们是一个大型处理器的组成部分,这对扩展 AI 训练和推理至关重要。
- High-density, ultrascale system (NVL72)高密度、超大规模系统(NVL72)
- The NVL72 rack integrates 72 GPUs in one compact system. This consolidated design supports massive models by combining high compute performance with an enormous unified memory pool, enabling tasks that would be impractical on traditional setups.NVL72 机架将 72 个 GPU 集成到一个紧凑系统中。这种整合设计将高计算性能与庞大的统一内存池相结合,支持超大规模模型,使在传统配置上不切实际的任务成为可能。
- Advanced cooling and power management先进散热与电源管理
- NVL72 relies on sophisticated liquid cooling and robust power distribution systems and operates at around 130 kW per rack (130 kW = 18 nodes × 6 kW per node + ~20 kW NVSwitch/cooling/overhead). This amount of cooling and power are essential for managing the high-density, high-performance components and ensuring reliable operation.NVL72 依赖复杂的液冷(liquid cooling)和稳健的配电(power distribution)系统,每机架功耗约为 130 kW(130 kW = 18 个节点 × 每节点 6 kW + 约 20 kW NVSwitch/冷却/开销)。这种规模的冷却和供电对于管理高密度、高性能组件并确保可靠运行至关重要。
- Significant performance and efficiency gains显著的性能与效率提升
- Compared to previous generations such as the Hopper H100, Blackwell GPUs offer roughly 2–2.5× improvements in compute and memory bandwidth. This leads to significant improvements in training and inference speeds—up to 30× faster inference in some cases that use Blackwell’s FP4 Tensor Cores and Transformer Engine—as well as potential cost savings through reduced GPU counts.与 Hopper H100 等前代产品相比,Blackwell GPU 在算力和显存带宽方面提供约 2–2.5× 的提升。这带来训练和推理速度的显著改善——在使用 Blackwell 的 FP4 张量核心和 Transformer Engine 的某些情况下,推理速度最高可提升 30×——并通过减少 GPU 数量带来潜在成本节省。
- Modern software stack support现代软件栈支持
- NVIDIA’s software and frameworks continue to evolve to fully utilize their latest hardware and support the latest codesigned system optimizations. This includes unified memory management and native FP8/FP4 precision support. As such, engineers can utilize the system’s full performance with minimal code changes.NVIDIA 的软件和框架持续演进,以充分利用其最新硬件并支持最新的协同设计(codesigned)系统优化。这包括统一内存管理和原生 FP8/FP4 精度支持。因此,工程师只需最少的代码改动即可发挥系统的全部性能。
- Future-proof roadmap面向未来的路线图
- NVIDIA’s development roadmap (including Blackwell Ultra, Vera Rubin, Vera Rubin Ultra, and Feynman) promises continual doubling of key parameters like compute throughput and memory bandwidth. This trajectory is designed to support ever-larger AI models and more complex workloads in the future.NVIDIA 的开发路线图(包括 Blackwell Ultra、Vera Rubin、Vera Rubin Ultra 和 Feynman)承诺持续翻倍计算吞吐量和显存带宽等关键参数。这一轨迹旨在支持未来不断增大的 AI 模型和更复杂的工作负载。
结语
Conclusion
The NVIDIA NVL72 system—with its Grace Blackwell Superchips, NVLink fabric, and advanced cooling—exemplifies the cutting-edge of AI hardware design. In this chapter, we’ve seen how every component is codesigned to serve the singular goal of accelerating AI workloads. The CPU and GPU are fused into one unit to eliminate data transfer bottlenecks and provide a gigantic, unified memory.NVIDIA NVL72 系统凭借其 Grace Blackwell 超级芯片、NVLink 互连网络和先进散热,堪称 AI 硬件设计前沿的典范。在本章中,我们看到每个组件都经过协同设计,服务于加速 AI 工作负载这一单一目标。CPU 与 GPU 融合为一个单元,从而消除数据传输瓶颈,并提供巨大的统一内存。
Dozens of GPUs are wired together with an ultrafast network so they behave like one colossal GPU with minimal communication delay. And the memory subsystem is expanded and accelerated to feed the voracious appetite of the GPU cores. Even the power delivery and thermal management are pushed to new heights to allow this density of computing.数十个 GPU 通过超高速网络连接在一起,使它们表现得像一个巨型 GPU,且通信时延极低。内存子系统经过扩展和加速,以满足 GPU 核心对数据的巨大需求。甚至连供电和热管理也被推向新的高度,以支撑这样的计算密度。
The result is a single rack that delivers performance previously seen only in multirack supercomputers. NVIDIA took the entire computing stack—chips, boards, networking, cooling—and optimized it end to end to allow training and serving massive AI models at ultrascale.其结果是,单个机架即可提供以往只有多机架超级计算机才能达到的性能。NVIDIA 对整个计算栈——芯片、电路板、网络、散热——进行了端到端优化,从而支持以超大规模训练和服务大型 AI 模型。
But such hardware innovations come with challenges, as you need specialized facilities, careful planning for power and cooling, and sophisticated software to utilize them fully. But the payoff is immense. Researchers can now experiment with models of unprecedented scale and complexity without waiting weeks or months for results. A model that might have taken a month to train on older infrastructure might train in a few days on NVL72. Inference tasks that were barely interactive (seconds per query) are now a real-time (milliseconds) reality. This opens the door for AI applications that were previously impractical, such as multi-trillion-parameter interactive AI assistants and agents.但此类硬件创新也伴随着挑战:你需要专用设施、对供电和散热的精心规划,以及精密复杂的软件才能充分发挥其能力。但回报是巨大的。研究人员如今可以试验规模与复杂度前所未有的模型,而无需等待数周甚至数月才能得到结果。过去在旧基础设施上可能需要一个月训练的模型,在 NVL72 上或许几天就能完成训练。过去几乎谈不上交互式(每次查询需数秒)的推理任务,如今已成为实时(毫秒级)的现实。这为以前不切实际的 AI 应用打开了大门,例如数万亿参数的交互式 AI 助手和智能体。
NVIDIA’s rapid roadmap suggests that this is just the beginning. The Grace Blackwell architecture will evolve into Vera Rubin and Feynman and beyond. As NVIDIA’s CEO, Jensen Huang, describes, “AI is advancing at light speed, and companies are racing to build AI factories that can scale to meet the processing demands of reasoning AI and inference time scaling.”NVIDIA 快速推进的路线图表明,这仅仅是开始。Grace Blackwell 架构将演进为 Vera Rubin、Feynman 以及更远的未来。正如 NVIDIA CEO 黄仁勋(Jensen Huang)所言:“AI 正以光速前进,各公司正在竞相构建可扩展的 AI 工厂,以满足推理型 AI(reasoning AI)和推理时扩展(inference time scaling)的处理需求。”
The NVL72 and its successors are the core of the AI factory. It’s the heavy machinery that will churn through mountains of data to produce incredible AI capabilities. As performance engineers, we stand on the shoulders of this hardware innovation. It gives us a tremendous raw capability, as our role is to harness this innovation by developing software and algorithms that make the most of the hardware’s potential.NVL72 及其后续产品是 AI 工厂的核心。它是吞吐海量数据、产出惊人 AI 能力的重型机械。作为性能工程师,我们站在这一硬件创新的肩膀上。它赋予我们强大的原始能力,而我们的职责是通过开发软件和算法来驾驭这一创新,最大限度地发挥硬件的潜力。
In the next chapter, we will transition from hardware to software. We’ll explore how to optimize the operating systems, drivers, and libraries on systems like NVL72 to ensure that none of this awesome hardware goes underutilized. In later chapters, we’ll look at memory management and distributed training/inference algorithms that complement the software architecture.下一章,我们将从硬件转向软件。我们将探讨如何优化 NVL72 等系统上的操作系统、驱动程序和库,以确保这些强大的硬件不会出现利用不足的情况。在后续章节中,我们将讨论与软件架构相辅相成的内存管理以及分布式训练/推理算法。
The theme for this book is codesign. Just as the hardware was codesigned for AI, our software and methods must be codesigned to leverage the hardware. With a clear understanding of the hardware fundamentals now, we’re equipped to dive into software strategies to improve AI system performance. The era of AI supercomputing is here, and it’s going to be a thrilling ride utilizing it to its fullest.本书的主题是协同设计(codesign)。正如硬件是为 AI 而协同设计的一样,我们的软件与方法也必须经过协同设计,才能充分发挥硬件的效能。现在,我们已经对硬件基础知识有了清晰的认识,可以深入探讨提升 AI 系统性能的软件策略了。AI 超级计算的时代已经到来,将其发挥到极致必将是一段激动人心的旅程。
Let’s dive in!让我们开始吧!