GPU 显存访问模式的剖析与调优
Chapter 7. Profiling and Tuning GPU Memory Access Patterns
本章目录
As AI models grow in size and complexity, a GPU’s memory system often becomes the bottleneck that stands between theoretical compute capability and real-world performance. As you saw in Chapter 6, modern NVIDIA GPUs combine thousands of simple, throughput-optimized cores with specialized Tensor Cores. They also include high-bandwidth memory (HBM), coherent CPU-GPU unified memory address space (e.g., Grace Blackwell Superchip), on-chip shared memory, caches, and specialized direct memory access (DMA) engines like the Tensor Memory Accelerator (TMA).随着 AI 模型规模和复杂度不断增长,GPU 的内存系统往往成为横亘在理论算力与实际性能之间的瓶颈。正如你在第 6 章所见,现代 NVIDIA GPU 将数千个简单的、面向吞吐量优化的核心与专用张量核心结合在一起。它们还包含高带宽内存(HBM)、CPU-GPU 一致的统一内存地址空间(例如 Grace Blackwell 超级芯片)、片上共享内存、缓存,以及诸如张量内存加速器(TMA)之类的专用直接显存访问(DMA)引擎。
In this chapter, you’ll see various CUDA C++ and PyTorch optimization techniques to align data structures for efficient memory access, eliminate redundant data loads, and overlap data transfers with computation using hardware.本章将介绍多种 CUDA C++ 与 PyTorch 优化技术,用于对齐数据结构以实现高效显存访问、消除冗余数据加载,以及利用硬件将数据传输与计算重叠。
Through concrete before-and-after examples of matrix multiplies, tensor operations, and more, you’ll see how small changes in memory access patterns, tiling strategies, and asynchronous data transfers can reduce wasted bandwidth, boost arithmetic efficiency, and transform kernels from memory bound to compute bound.通过矩阵乘法、张量运算等的具体前后对比示例,你将看到显存访问模式、分块(tiling)策略和异步数据传输上的细微改动,如何减少带宽浪费、提升算术效率,并将内核从显存受限转变为计算受限。
By the end of this chapter, you’ll know how to write CUDA kernels that can better utilize the GPU’s memory hierarchy and hardware-optimized data transfer engines.到本章结束时,你将掌握如何编写能更好地利用 GPU 显存层次结构与硬件优化数据传输引擎的 CUDA 内核。
全局内存的合并访问与非合并访问
Coalesced Versus Uncoalesced Global Memory Access
The memory access pattern of your code can greatly impact performance. Global memory accesses are fastest when threads in a warp access contiguous memory addresses that the hardware can combine into fewer, larger transactions. If threads access scattered or misaligned addresses, the device cannot coalesce requests into the minimal number of cache line transactions, which on modern GPUs are 128-byte lines composed of four 32-byte sectors. This results in many more memory transactions retrieving unused data, which quickly eats up memory bandwidth.代码的显存访问模式会极大影响性能。当一个线程束中的线程访问连续的内存地址、硬件可将这些访问合并为更少、更大的事务时,全局内存访问速度最快。如果线程访问的是分散或未对齐的地址,设备就无法将请求合并为最少数量的缓存行事务——在现代 GPU 上,缓存行为 128 字节,由四个 32 字节的扇区(sector)组成。这会导致多得多的内存事务去读取未使用的数据,从而迅速耗尽显存带宽。
On a Blackwell GPU, per-device HBM3e bandwidth is up to 8 TB/s. Within the Grace Blackwell GB200 and GB300 (two GPU superchips), this increases 16 TB/s across both GPUs. Using uncoalesced memory accesses will leave most of this bandwidth unused due to excess memory transactions and stalls.在 Blackwell GPU 上,单设备的 HBM3e 带宽最高可达 8 TB/s。在 Grace Blackwell GB200 和 GB300(两个 GPU 超级芯片)中,两块 GPU 合计的带宽提升至 16 TB/s。使用非合并显存访问会因过多的事务和停顿而使其中大部分带宽闲置。
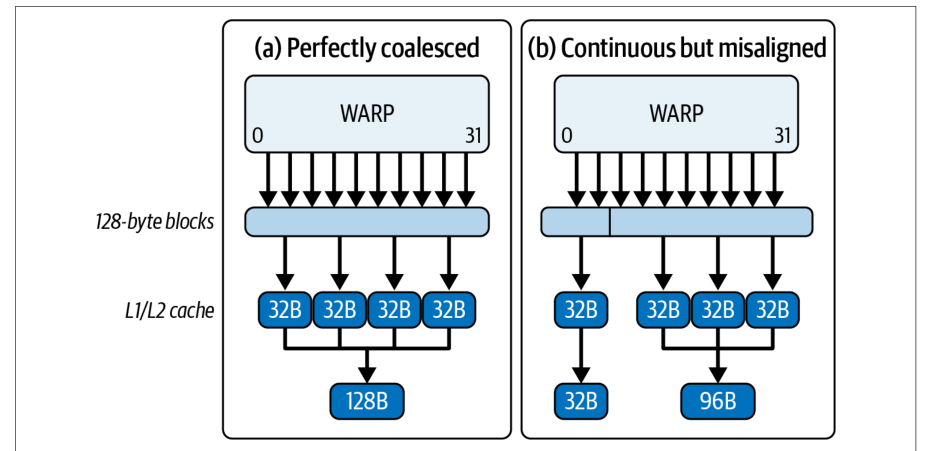
In the uncoalesced case, each thread in a warp loads from scattered addresses. This results in many separate memory transactions. Even if threads in a warp access consecutive addresses, if the first address isn’t 128-byte aligned, the warp’s request will span two 128-byte cache lines.在非合并访问的情况下,线程束中的每个线程都从分散的地址加载数据,这会产生许多独立的内存事务。即使线程束中的线程访问的是连续地址,只要首个地址不是 128 字节对齐,该线程束的请求就会跨越两条 128 字节缓存行。
For example, if a warp’s first thread starts at an address that isn’t 128-byte aligned, the warp’s memory request will cross a cache-line boundary, often resulting in two 128-byte transactions instead of one. In that case the warp may fetch an extra sector beyond the optimal four sectors, for a total of five sectors across the two lines. This is a waste of bandwidth. Whether a misaligned, contiguous 128-byte warp load touches 5× 32 B sectors or 8× 32 B sectors depends on the start offset. Aligned accesses keep it to 4× 32 B sectors.例如,如果线程束的第一个线程从一个非 128 字节对齐的地址开始,该线程束的内存请求就会跨越缓存行边界,通常导致产生两次 128 字节事务而非一次。此时线程束可能在最优的四个扇区之外多取一个扇区,两条缓存行合计共五个扇区。这是对带宽的浪费。一次未对齐的、连续的 128 字节线程束加载究竟触及 5× 32 B 扇区还是 8× 32 B 扇区,取决于起始偏移量。对齐访问则可保持在 4× 32 B 扇区。
In the coalesced case, however, threads load from consecutive addresses combined into a single wide transaction. Figure 7-1 compares coalesced and uncoalesced memory access.而在合并访问的情况下,线程从连续地址加载的数据会被合并为单个宽事务。图 7-1 对比了合并访问与非合并访问的显存访问。
In kernel code, this problem typically appears as strided or irregular indexing such that each thread reaches into different cache lines. When a kernel’s threads fetch data with strided or irregular indices, the GPU issues many small, uncoalesced global-memory transactions rather than a handful of full-width loads.在内核代码中,这一问题通常表现为*跨步*或不规则的索引方式,使得每个线程访问到不同的缓存行。当内核的线程以跨步或不规则的索引取数据时,GPU 会发出许多小的、非合并的全局内存事务,而不是少量全宽加载。
In Nsight Compute, the Memory Workload Analysis section will show lower Global Memory Load Efficiency, higher DRAM sector read counts, and average sectors per request above 4.0 when uncoalesced patterns are present. This is because more sectors are being fetched than a properly coalesced memory access pattern, and it indicates that you’re wasting bandwidth by fetching mostly unused bytes. And DRAM throughput percentage will remain well below peak. This confirms that your warp is spending cycles stalled on memory rather than driving the ALUs.在 Nsight Compute 中,当存在非合并访问模式时,Memory Workload Analysis 部分会显示较低的 Global Memory Load Efficiency、较高的 DRAM 扇区读取计数,以及平均每请求扇区数高于 4.0。这是因为相比正确合并的显存访问模式,此时取回了更多扇区,说明你正在取回大量未使用的字节,从而浪费带宽。并且 DRAM 吞吐量百分比会远低于峰值。这证实了你的线程束把周期花在因内存而停顿上,而不是驱动 ALU。
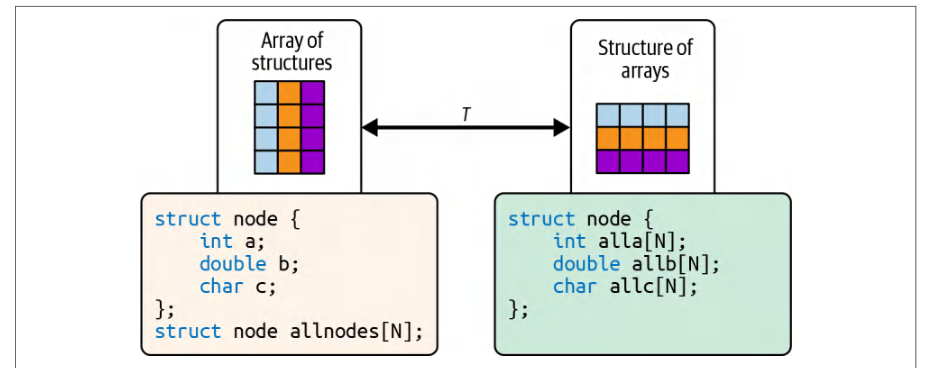
To break out of this memory-bound regime, you can reorganize your data so that each warp’s 32 threads load contiguous elements. Either index the array with input[idx] where idx = blockIdx.x * blockDim.x + threadIdx.x or switch to a structure-of-arrays (SoA) layout so that thread i always touches element i. The difference between an array of structures (AoS) and an SoA is shown in Figure 7-2.要跳出这种显存受限的状态,你可以重新组织数据,使每个线程束的 32 个线程加载连续的元素。要么用 input[idx] 索引数组,其中 idx = blockIdx.x * blockDim.x + threadIdx.x,要么改用数组结构体(SoA)布局,使线程 i 始终访问元素 i。结构体数组(AoS)与 SoA 的差异如图 7-2 所示。
Once you make the change, the hardware will automatically combine the warp’s global memory loads into fewer, wider transactions with more usable (less wasted) data being returned. The Nsight Compute counters will immediately show improvement.完成修改后,硬件会自动把线程束的全局内存加载合并为更少、更宽的事务,返回更多可用(更少浪费)的数据。Nsight Compute 的计数器会立即显示出改善。
Let’s demonstrate this with an example. The following before-and-after code demonstrates how restructuring global memory accesses from a strided pattern to a contiguous pattern produces a significant performance gain.下面用一个例子来演示。以下的前后对比代码展示了将全局内存访问从跨步模式重构为连续模式如何带来显著的性能提升。
Before example (C++): uncoalesced strided access. In this example, each thread copies from an input array with a stride of 2, causing misaligned memory accesses:修改前示例(C++):非合并的跨步访问。 在此示例中,每个线程从输入数组中以步长 2 进行拷贝,导致显存访问未对齐:
#include <cuda_runtime.h>
#include <iostream>
__global__ void uncoalescedCopy(const float* __restrict__ in,
float* __restrict__ out,
int N, int stride) {
    // n = 1048576,stride = 2
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // 以跨步方式从 in[] 加载,导致
        // 需要取回多个内存段
        out[idx] = in[idx * stride];
    }
}
int main() {
    const int N = 1 << 20;
    const int stride = 2;
    float* h_in = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_in, N * stride * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < N * stride; ++i) {
        h_in[i] = static_cast<float>(i);
    }
    float *d_in, *d_out;
    cudaMalloc(&d_in,  N * stride * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_in, h_in, N * stride * sizeof(float),
      cudaMemcpyHostToDevice);
    // 每个线程块的线程数(32 的倍数)
    const int threadsPerBlock = 256;
    // 每个网格的线程块数量
    const int blocksPerGrid = (N + threadsPerBlock - 1) /
      threadsPerBlock;
    uncoalescedCopy<<<blocksPerGrid,
      threadsPerBlock>>>(d_in, d_out, N, stride);
    cudaDeviceSynchronize();
    cudaFree(d_in);
    cudaFree(d_out);
    cudaFreeHost(h_in);
    cudaFreeHost(h_out);
    return 0;
}
__global__ void uncoalescedCopy(const float* __restrict__ in,
float* __restrict__ out,
int N, int stride) {
    // n = 1048576, stride = 2
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // Loads from in[] with a stride, causing
        // multiple memory segments to be fetched
        out[idx] = in[idx * stride];
    }
}
int main() {
    const int N = 1 << 20;
    const int stride = 2;
    float* h_in = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_in, N * stride * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < N * stride; ++i) {
        h_in[i] = static_cast<float>(i);
    }
    float *d_in, *d_out;
    cudaMalloc(&d_in,  N * stride * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_in, h_in, N * stride * sizeof(float),
      cudaMemcpyHostToDevice);
    // Number of threads per block (multiple of 32)
    const int threadsPerBlock = 256;
    // Number of blocks per grid
    const int blocksPerGrid = (N + threadsPerBlock - 1) /
      threadsPerBlock;
    uncoalescedCopy<<<blocksPerGrid,
      threadsPerBlock>>>(d_in, d_out, N, stride);
    cudaDeviceSynchronize();
    cudaFree(d_in);
    cudaFree(d_out);
    cudaFreeHost(h_in);
    cudaFreeHost(h_out);
    return 0;
}
The CUDA C++ kernel issues global memory loads at addresses separated by a stride > 1, which is, by definition, noncontiguous. This causes each warp to generate multiple small transactions instead of a single wide transaction.该 CUDA C++ 内核发出的全局内存加载地址间隔为大于 1 的步长,按定义即为非连续。这导致每个线程束产生多次小事务,而不是一次宽事务。
*Before example (PyTorch). *In PyTorch, an analogous situation can be created using a strided index for a gather operation:修改前示例(PyTorch)。 在 PyTorch 中,可以用跨步索引执行 gather 操作来构造类似的情形:
import torch
def uncoalesced_copy(input_tensor, stride):
    # 展平为一维,以便确切知道
    #   我们正在索引哪个维度
    flat_tensor = input_tensor.contiguous().view(-1)
    # 生成固定跨步的索引以进行收集
    assert flat_tensor.numel() % stride == 0,"stride must divide tensor length"
    idx = torch.arange(0, flat_tensor.numel(), stride,
        device=flat_tensor.device, dtype=torch.long)
    # index_select 使用 gather 内核,会发起非合并访问的加载
    return torch.index_select(flat_tensor, 0, idx)
# 用法
n, stride = 1 << 20, 2
inp = torch.arange(n * stride, device='cuda',
                   dtype=torch.float32)
out = uncoalesced_copy(inp, stride)
import torch
def uncoalesced_copy(input_tensor, stride):
    # Flatten to 1D so we know exactly
    #   which dimension we're indexing
    flat_tensor = input_tensor.contiguous().view(-1)
    # Generate indices with a fixed stride to gather
    assert flat_tensor.numel() % stride == 0,"stride must divide tensor length"
    idx = torch.arange(0, flat_tensor.numel(), stride,
        device=flat_tensor.device, dtype=torch.long)
    # index_select uses a gather kernel that issues uncoalesced loads
    return torch.index_select(flat_tensor, 0, idx)
# Usage
n, stride = 1 << 20, 2
inp = torch.arange(n * stride, device='cuda',
                   dtype=torch.float32)
out = uncoalesced_copy(inp, stride)
This PyTorch snippet uses torch.index_select with a strided index pattern, which causes the underlying GPU gather kernel to perform uncoalesced loads. Specifically, a warp of 32 threads will access addresses that are stride * 4 bytes apart.这段 PyTorch 代码使用带跨步索引模式的 torch.index_select,使底层 GPU gather 内核执行非合并加载。具体来说,一个 32 线程的线程束将访问彼此相隔 stride * 4 bytes 的地址。
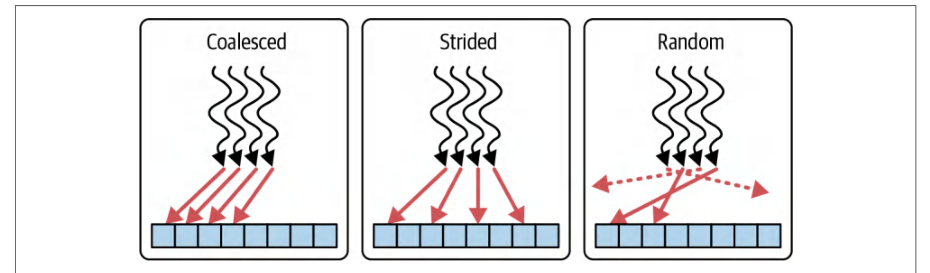
This does not allow a single wide transaction and instead generates 32 separate loads. Each thread loads a value from inp that is far apart in memory from the value loaded by the next thread, which prevents coalescing. Figure 7-3 shows the coalesced versus strided access pattern—as well as random access.这无法形成单次宽事务,而是产生 32 次独立的加载。每个线程从 inp 中加载的值与下一个线程加载的值在内存中相距很远,从而无法合并。图 7-3 展示了合并访问与跨步访问模式,以及随机访问。
After running the C++ and PyTorch codes on a GPU, we measure performance metrics. In the uncoalesced version, each warp’s memory request is broken into 8 separate 32-byte sectors on average. Since each 128-byte cache line fetch is split into 4 separate 32-byte sectors (more on this number 4 in a bit), the access pattern spans two lines per warp to retrieve the 8 separate 32-byte sectors.在 GPU 上运行 C++ 和 PyTorch 代码后,我们测量性能指标。在非合并版本中,每个线程束的内存请求平均被拆分为 8 个独立的 32 字节扇区。由于每次 128 字节缓存行读取被拆分为 4 个独立的 32 字节扇区(关于数字 4 稍后详述),该访问模式每个线程束跨越两条缓存行来取回这 8 个独立的 32 字节扇区。
In the unoptimized version, each warp’s uncoalesced loads break a single logical request into up to eight separate 32-byte sectors, ballooning transaction counts and starving the memory pipeline. As a result, Nsight Compute reports only about 25% of sustained peak dynamic random-access memory (DRAM) throughput.在未优化版本中,每个线程束的非合并加载将单个逻辑请求拆分为最多 8 个独立的 32 字节扇区,使事务数量激增,并让内存流水线处于饥饿状态。结果,Nsight Compute 报告的持续峰值动态随机存取存储器(DRAM)吞吐量仅约 25%。
Now, let’s optimize this by coalescing the memory accesses and making threads read contiguous elements so each warp issues fewer, larger transactions.现在,我们通过合并显存访问、让线程读取连续元素来优化它,使每个线程束发出更少、更大的事务。
After example (C++): coalesced access. By simply removing the stride (or setting it to 1), each thread copies a contiguous element. This alignment of thread accesses allows the hardware to coalesce memory requests into full 128-byte transactions:修改后示例(C++):合并访问。 只需去掉步长(或将其设为 1),每个线程就拷贝连续的元素。这种线程访问的对齐使硬件能够将内存请求合并为完整的 128 字节事务:
#include <cuda_runtime.h>
#include <iostream>
__global__ void coalescedCopy(const float* __restrict__ in,
                             float* __restrict__ out,
                             int n) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < n) {
        // 连续加载
        // 各线程拷贝相邻元素
        out[idx] = in[idx];
    }
}
int main() {
    const int n = 1 << 20;
    const size_t bytes = n * sizeof(float);
    // 1) 分配锁页主机内存
    float *h_in = nullptr, *h_out = nullptr;
    cudaMallocHost(&h_in,  bytes);  // 锁页主机内存分配
    cudaMallocHost(&h_out, bytes);
    // 2) 初始化输入
    for (int i = 0; i < n; ++i) {
        h_in[i] = static_cast<float>(i);
    }
    // 3) 分配设备显存
    float *d_in = nullptr, *d_out = nullptr;
    cudaMalloc(&d_in,  bytes);
    cudaMalloc(&d_out, bytes);
    // 4) 拷贝到设备
    cudaMemcpy(d_in, h_in, bytes,
      cudaMemcpyHostToDevice);
    // 5) 启动内核
    dim3 block(256);
#include <cuda_runtime.h>
#include <iostream>
__global__ void coalescedCopy(const float* __restrict__ in,
                             float* __restrict__ out,
                             int n) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < n) {
        // Contiguous load
        // Threads copy neighboring elements
        out[idx] = in[idx];
    }
}
int main() {
    const int n = 1 << 20;
    const size_t bytes = n * sizeof(float);
    // 1) Allocate pinned host memory
    float *h_in = nullptr, *h_out = nullptr;
    cudaMallocHost(&h_in,  bytes);  // page-locked host alloc
    cudaMallocHost(&h_out, bytes);
    // 2) Initialize input
    for (int i = 0; i < n; ++i) {
        h_in[i] = static_cast<float>(i);
    }
    // 3) Allocate device memory
    float *d_in = nullptr, *d_out = nullptr;
    cudaMalloc(&d_in,  bytes);
    cudaMalloc(&d_out, bytes);
    // 4) Copy to device
    cudaMemcpy(d_in, h_in, bytes,
      cudaMemcpyHostToDevice);
    // 5) Launch kernel
    dim3 block(256);
| Metric指标 | Before (uncoalesced)优化前(非合并访问) | After (coalesced)优化后(合并访问) |
|---|---|---|
| DRAM throughput (% of peak)DRAM 吞吐量(占峰值的百分比) | 25%25% | 90% (3.6×)90% (3.6×) |
| Global Memory Load Efficiency全局内存加载效率 | 23%23% | 99%99% |
| Average sectors per request每次请求的平均扇区数 | 8.08.0 | 4.0 (optimal)4.0(最优) |
| SM Active %SM 活跃占比 % | 62%62% | 99%99% |
| Kernel execution time (ms)内核执行时间(ms) | 4.8 ms4.8 ms | 1.3 ms (3.7×)1.3 ms(3.7×) |
    dim3 grid((n + block.x - 1) / block.x);
    coalescedCopy<<<grid, block>>>(d_in, d_out, n);
    cudaDeviceSynchronize();
    // 6) 拷贝回主机
    cudaMemcpy(h_out, d_out, bytes,
      cudaMemcpyDeviceToHost);
    // 7) 清理
    cudaFree(d_in);
    cudaFree(d_out);
    cudaFreeHost(h_in);
    cudaFreeHost(h_out);
    return 0;
}
    dim3 grid((n + block.x - 1) / block.x);
    coalescedCopy<<<grid, block>>>(d_in, d_out, n);
    cudaDeviceSynchronize();
    // 6) Copy back to host
    cudaMemcpy(h_out, d_out, bytes,
      cudaMemcpyDeviceToHost);
    // 7) Clean up
    cudaFree(d_in);
    cudaFree(d_out);
    cudaFreeHost(h_in);
    cudaFreeHost(h_out);
    return 0;
}
We leave out the coalesced PyTorch implementation for brevity since it’s already built into PyTorch. A coalesced version in PyTorch would simply do something like out = inp.clone(). This copies contiguous elements efficiently. In fact, clone() on a contiguous tensor uses a vectorized memory copy under the hood, analogous to our coalesced kernel.为简洁起见,我们省略了合并访问的 PyTorch 实现,因为它已经内置于 PyTorch 中。PyTorch 中的合并访问版本只需执行类似 out = inp.clone() 的操作即可。这会高效地复制连续元素。事实上,对连续张量调用 clone() 在底层使用的是向量化显存拷贝,与我们合并访问的内核类似。
With coalesced access, or no stride, each warp’s threads access adjacent addresses. In this case, the hardware coalesces each warp’s loads into the minimum number of 128-byte transactions—often one 128-byte transaction per warp when the first address is 128-byte aligned, or two if the access straddles a boundary. Table 7-1 shows the dramatic improvements resulting from this optimization.在使用合并访问(即无跨步)时,每个线程束的线程访问相邻地址。此时,硬件会将每个线程束的加载合并为最少数量的 128 字节事务——当首地址按 128 字节对齐时,通常每个线程束只需一个 128 字节事务;若访问跨越边界,则需要两个。表 7-1 展示了这一优化带来的显著提升。
After fixing the data layout and coalescing global memory accesses, DRAM throughput rises from 25% to 90% of peak, about 3.6× higher. Kernel execution time improves by about 3.7×, from 4.8 ms to 1.3 ms, as fewer stalls free the SMs to make forward progress.在修正数据布局并合并全局内存访问之后,DRAM 吞吐量从峰值的 25% 提升到 90%,约为原来的 3.6 倍。内核执行时间改善约 3.7 倍,从 4.8 ms 降至 1.3 ms,因为停顿减少使 SM 得以持续向前推进。
Global Memory Load Efficiency rises from 23% to 99%, meaning nearly every fetched byte is useful. At the same time, Average Sectors per Request falls to about 4.0.Global Memory Load Efficiency 从 23% 升至 99%,意味着几乎每个取回的字节都是有用的。同时,Average Sectors per Request 降至约 4.0。
In the worst case with strided or scattered access, the value can approach 32 because activity is reported in 32-byte sectors at L2. Values above 4.0 indicate uncoalesced or misaligned access. In an unoptimized version, uncoalesced loads can break a single logical access into many sectors per request, approaching the worst case.在最坏的跨步或分散访问情况下,该数值可能接近 32,因为 L2 以 32 字节扇区为单位报告活动。数值高于 4.0 表明访问未合并或未对齐。在未优化的版本中,未合并的加载可能将单次逻辑访问拆分为每个请求的多个扇区,接近最坏情况。
Here we are at about 4.0 sectors per request, which indicates that requests map cleanly to 128-byte lines with no unused sectors. With fewer memory stalls, SM Active percent improves from 62% to 99%.此处我们约为每个请求 4.0 个扇区,表明请求干净地映射到 128 字节缓存行,没有未使用的扇区。由于内存停顿减少,SM Active 百分比从 62% 提升到 99%。
In summary, by aligning each warp’s threads on successive addresses, the GPU’s memory controller can service each warp with a few large transactions instead of dozens of tiny ones. This boosts the Global Memory Load Efficiency (fraction of each transaction that returns useful data) to near 100% and raises SM Active % by keeping warps busy instead of idle.总之,通过让每个线程束的线程对齐到连续地址,GPU 的显存控制器可以用少量大事务而非数十个小事务来服务每个线程束。这将 Global Memory Load Efficiency(每个事务中返回有用数据的比例)提升至接近 100%,并通过让线程束保持忙碌而非空闲来提高 SM Active %。
And with that, you’ve seen how coalescing reshapes your thread-to-address mapping so an entire warp’s loads line up on the GPU’s 128-byte segments. However, even a fully coalesced warp still issues 32 individual 4-byte reads under the hood, one per thread, forcing the hardware to stitch them back together into each 128-byte transaction.至此,你已经看到合并如何重塑线程到地址的映射,使整个线程束的加载对齐到 GPU 的 128 字节段。然而,即便是完全合并的线程束,在底层仍然发出 32 次独立的 4 字节读取,每个线程一次,迫使硬件将它们重新拼接成每个 128 字节事务。
To eliminate that last layer of inefficiency, we turn to vectorized memory access: having each thread fetch a wider, aligned chunk (e.g., a 16-byte float4) in a single instruction so that a coalesced warp issues exactly four 128-byte transactions, not 32. Let’s dive into how to pack your per-thread loads into CUDA’s built-in vector types.为消除最后一层低效,我们转向向量化显存访问:让每个线程在单条指令中取回更宽的、对齐的数据块(例如 16 字节的 float4),从而使一个合并的线程束恰好发出四个 128 字节事务,而不是 32 个。下面我们深入探讨如何将每线程加载打包为 CUDA 内置的向量类型。
向量化显存访问
Vectorized Memory Access
While memory coalescing is a runtime hardware optimization on NVIDIA GPUs, vectorized memory access is a compile-time strategy in which each load or store instruction explicitly fetches multiple contiguous elements (e.g., float4, or 16 bytes) per thread. This reduces instruction count and eliminates stitching overhead.内存合并访问是 NVIDIA GPU 上的运行时硬件优化,而向量化显存访问是一种编译期策略:每条加载或存储指令显式地让每个线程取回多个连续元素(例如 float4,即 16 字节)。这减少了指令数量并消除了拼接开销。
Efficient global-memory access on Blackwell relies on matching your loads to the GPU’s native 128-byte transaction size. When each thread reads only a 4-byte float, a 32-thread warp still has to stitch together 32 4-byte requests to fill one 128-byte line.在 Blackwell 上,高效的全局内存访问依赖于让加载匹配 GPU 原生的 128 字节事务大小。当每个线程只读取 4 字节的 float 时,一个 32 线程的线程束仍需拼接 32 个 4 字节请求才能填满一条 128 字节缓存行。
In ideal coalesced cases, a warp that reads 32 4-byte words aligned to a 128-byte boundary maps to exactly four 32-byte sectors. Nsight Compute captures this waste in the average sectors per request metric, which can climb well above 4.0 when your accesses are misaligned, strided, or scattered. As such, you’ll see Global Memory Load Efficiency drop as bandwidth goes underutilized.在理想的合并情形下,一个读取 32 个按 128 字节边界对齐的 4 字节字的线程束恰好映射到四个 32 字节扇区。Nsight Compute 通过 average sectors per request 指标捕捉这种浪费——当访问未对齐、跨步或分散时,该指标可能远高于 4.0。因此,你会看到 Global Memory Load Efficiency 下降,带宽未被充分利用。
The fix is to bundle each thread’s work into a larger, naturally aligned vector that maps cleanly onto those 128-byte transactions. CUDA’s built-in float4 type does exactly that: it packs four 4-byte floats into a 16-byte struct guaranteed by the compiler to be 16-byte aligned. For illustration purposes, it looks something like the following code:解决办法是把每个线程的工作打包成一个更大、自然对齐的向量,使其能够干净地映射到那些 128 字节事务上。CUDA 内置的 float4 类型正是这么做的:它把四个 4 字节的 float 打包进一个 16 字节的结构体,编译器保证该结构体按 16 字节对齐。为便于说明,它大致如下面的代码所示:
// 自定义 float4 的示例,仅用于说明。
// 注意:建议使用 CUDA 内置的 float4 类型。
// 注意:若 N 不能被 4 整除,需处理末尾 N % 4 个元素
// (例如一小段标量收尾处理),或在主机端代码中断言其可整除性。
// 输入与输出指针必须按 16 字节对齐,才能进行 float4 加载/存储。
struct my_float4 {
    float x;  // 4 字节
    float y;  // 4 字节
    float z;  // 4 字节
    float w;  // 4 字节
};
// Example of a custom float4 for illustration purposes.
// Note: it's recommended to use the built-in CUDA float4 type.
// Note: if N is not divisible by 4, handle the last N % 4 elements
// (e.g., a short scalar cleanup) or assert divisibility in host code. The
// input and output pointers must be 16-byte aligned for float4 loads/stores.
struct my_float4 {
    float x;  // 4 bytes
    float y;  // 4 bytes
    float z;  // 4 bytes
    float w;  // 4 bytes
};
When all 32 threads in a warp issue a float4 load, they together fetch 32 × 16 bytes = 512 bytes of contiguous data, which the Blackwell memory controller then splits into exactly four 128-byte transactions (512 bytes ÷ 128 bytes per transaction = 4 transactions). This preserves the ideal 4.0 sectors per 128-byte transaction (discussed earlier re: coalesced memory access) because the warp requests 512 bytes, and the hardware services the request with four aligned 128-byte transactions for a total of 16 sectors, each fully utilized.当一个线程束中的全部 32 个线程都发起 float4 加载时,它们共同取回 32 × 16 字节 = 512 字节的连续数据,Blackwell 显存控制器随后将其精确拆分为四个 128 字节事务(512 字节 ÷ 每个事务 128 字节 = 4 个事务)。这保持了每个 128 字节事务 4.0 个扇区的理想值(前面在讨论内存合并访问时已述),因为线程束请求 512 字节,而硬件用四个对齐的 128 字节事务来服务该请求,共 16 个扇区,每个扇区都被充分利用。
Compared to an unaligned or strided case that can inflate sector counts, vectorized float4 loads reduce per-thread load instructions by 4×. This helps maintain the ideal 4.0 sectors per request when alignment is satisfied.与可能使扇区数量膨胀的非对齐或跨步访问情形相比,向量化的 float4 加载将每线程的加载指令数减少到原来的 1/4。在对齐得到满足时,这有助于维持每次请求 4.0 个扇区的理想值。
As a result of this vectorized memory access optimization, global memory load efficiency increases toward 100%. Sectors per transaction remain at 4.0 when each 128-byte transaction is fully utilized, while the warp issues multiple aligned transactions to serve a wider request.得益于这一向量化显存访问优化,全局内存加载效率提升至接近 100%。当每个 128 字节事务都被充分利用时,每事务扇区数保持在 4.0,同时线程束会发起多个对齐事务来服务一个更宽的请求。
Vectorized loads reduce the number of memory instructions per byte moved and often increase effective bandwidth. To benefit from vectorized loads, data pointers must be aligned to the vector width. The CUDA runtime and driver allocation functions, such as cudaMalloc return device pointers aligned to at least 256 bytes.向量化加载减少了每搬运一个字节所需的内存指令数,并且常常能提升有效带宽。要受益于向量化加载,数据指针必须按向量宽度对齐。CUDA 运行时与驱动的分配函数(例如 cudaMalloc)返回的设备指针至少按 256 字节对齐。
The base alignment is sufficient for 16-byte and 32-byte vector alignment at the allocation boundary. Adding an element offset can break alignment if the offset is not a multiple of the vector width. The following cast asserts the intended type to the compiler and assumes the pointer is already correctly aligned:在分配边界处,这一基础对齐足以满足 16 字节与 32 字节的向量对齐要求。如果偏移量不是向量宽度的整数倍,那么加上元素偏移就可能破坏对齐。下面的类型转换向编译器声明了预期的类型,并假定该指针已经正确对齐:
auto ptr4 = reinterpret_cast<const float4*>(ptr);
Make sure the pointer value is a multiple of 16 bytes (4 floats) before casting. This is because cudaMalloc() returns at least 256-byte alignment. Adding an element offset can break alignment if the offset is not a multiple of 4 floats. Correct alignment is a precondition for vectorized loads.在转换之前,请确保指针值是 16 字节(4 个 float)的整数倍。这是因为 cudaMalloc() 返回的地址至少按 256 字节对齐。如果偏移量不是 4 个 float 的整数倍,那么加上元素偏移就可能破坏对齐。正确的对齐是向量化加载的前提条件。
With a base address aligned to 32 bytes, each thread reads 32 bytes per iteration, typically compiling into two 16-byte vector load instructions per thread (Hopper) or one 32-byte load instruction (Blackwell). A 32-thread warp therefore requests 1,024 bytes. Each 128-byte cache line comprises four 32-byte sectors. As such, the warp generates eight aligned 128-byte transactions for a total of 32 sectors when accesses are aligned properly. This way, each access falls on a natural boundary and avoids split transactions.当基地址按 32 字节对齐时,每个线程每次迭代读取 32 字节,通常编译为每线程两条 16 字节向量加载指令(Hopper)或一条 32 字节加载指令(Blackwell)。因此,一个 32 线程的线程束会请求 1,024 字节。每条 128 字节的缓存行由四个 32 字节扇区组成。因此,当访问正确对齐时,该线程束会产生八个对齐的 128 字节事务,共 32 个扇区。这样一来,每次访问都落在自然边界上,避免了拆分事务。
It’s worth noting that CUDA, as of this writing, does not provide a built-in 8-float aggregate CUDA vector type (e.g., eight combined float32s) in its <vector_ types.h>. You can define your own struct of 8 float values, then load it as two float4 values per thread. You would use 32-byte alignment on the type with alignas(32). This way, the pointer value is a multiple of 32 bytes. Global memory vector instructions on modern GPUs typically load 16 bytes per thread (Hopper) or 32 bytes per thread (Blackwell). In the case of Hopper’s 16 bytes per thread, an 8-float aggregate load will compile into two 16-byte loads per thread to include all 32 bytes.值得注意的是,截至本文写作时,CUDA 在其 <vector_ types.h> 中并未提供内置的 8 个 float 聚合 CUDA 向量类型(例如 8 个组合在一起的 float32)。你可以自行定义一个包含 8 个 float 值的结构体,然后让每个线程将其作为两个 float4 值加载。你可以对该类型使用 alignas(32) 施加 32 字节对齐。这样,指针值就是 32 字节的整数倍。现代 GPU 上的全局内存向量指令通常每个线程加载 16 字节(Hopper)或每个线程加载 32 字节(Blackwell)。在 Hopper 每线程 16 字节的情况下,一次 8 个 float 的聚合加载会被编译为每个线程两次 16 字节加载,以涵盖全部 32 字节。
Blackwell, on the other hand, would compile into a single 32-byte load per thread when using proper 32-byte aligned data.另一方面,Blackwell 在使用正确的 32 字节对齐数据时,会将其编译为每个线程单次 32 字节加载。
With 32-byte per-thread loads (e.g., 8 floats × 4 bytes per float), a warp moves 1,024 bytes (1,024 bytes = 32 threads per warp × 32 bytes per thread). This typically maps to 8 × 128-byte lines since each line consists of four 32-byte sectors. With 16-byte per-thread loads (e.g., four float4s), a warp moves 512 bytes (512 bytes = 32 threads per warp × 16 bytes per thread) or 4 × 128-byte lines. When the base pointer and per-thread stride are naturally aligned, the hardware coalescer combines lane accesses into full lines and avoids split sectors. This type of mechanical sympathy is crucial to achieving peak throughput. Therefore, for 256-bit loads on Blackwell, you should enforce 32-byte alignment to maintain peak performance.在每线程 32 字节加载的情况下(例如 8 个 float × 每个 float 4 字节),一个线程束搬运 1,024 字节(1,024 字节 = 每个线程束 32 个线程 × 每线程 32 字节)。这通常映射到 8 条 128 字节的缓存行,因为每条缓存行由四个 32 字节扇区组成。在每线程 16 字节加载的情况下(例如四个 float4),一个线程束搬运 512 字节(512 字节 = 每个线程束 32 个线程 × 每线程 16 字节),即 4 条 128 字节缓存行。当基指针和每线程步长自然对齐时,硬件合并器会将各 lane 的访问合并为完整的缓存行,避免扇区被拆分。这种机械同理心(mechanical sympathy)对于达到峰值吞吐量至关重要。因此,在 Blackwell 上执行 256 位加载时,应当强制 32 字节对齐以保持峰值性能。
Let’s see an example of scalar versus vectorized memory access in a simple vector copy kernel.下面看一个简单向量拷贝内核中标量访问与向量化显存访问的对比示例。
Before example (C++): scalar copy. Each thread copies one float:修改前示例(C++):标量拷贝。 每个线程拷贝一个 float:
#include <cuda_runtime.h>
__global__ void copyScalar(
const float* __restrict__ in,
float* __restrict__ out, int N) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // 标量加载:每个线程复制 4 字节
        out[idx] = in[idx];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_in = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_in, N * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < N; ++i) h_in[i] = float(i);
    float *d_in, *d_out;
    cudaMalloc(&d_in, N * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_in, h_in, N * sizeof(float), cudaMemcpyHostToDevice);
    dim3 block(256), grid((N + 255) / 256);
    copyScalar<<<grid, block>>>(d_in, d_out, N);
    cudaDeviceSynchronize();
    cudaFree(d_in); cudaFree(d_out);
    cudaFreeHost(h_in);
#include <cuda_runtime.h>
__global__ void copyScalar(
const float* __restrict__ in,
float* __restrict__ out, int N) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // Scalar load: 4-byte copy per thread
        out[idx] = in[idx];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_in = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_in, N * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < N; ++i) h_in[i] = float(i);
    float *d_in, *d_out;
    cudaMalloc(&d_in, N * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_in, h_in, N * sizeof(float), cudaMemcpyHostToDevice);
    dim3 block(256), grid((N + 255) / 256);
    copyScalar<<<grid, block>>>(d_in, d_out, N);
    cudaDeviceSynchronize();
    cudaFree(d_in); cudaFree(d_out);
    cudaFreeHost(h_in);
    cudaFreeHost(h_out);
    return 0;
}
Before example (PyTorch). A scalar elementwise copy in PyTorch could be done with a Python loop for illustration:修改前示例(PyTorch)。为便于说明,PyTorch 中的标量逐元素拷贝可以用 Python 循环实现:
import torch
def copy_scalar(inp: torch.Tensor) -> torch.Tensor:
    out = torch.empty_like(inp)
    flat_in = inp.view(-1)
    flat_out = out.view(-1)
    for i in range(flat_in.numel()):
        # 每次迭代在 GPU 上发起一次 4 字节加载
        # 这种方式极慢。切勿这样做!
        # 使用向量化操作以避免 Python 循环
        # 作用于 GPU 张量,如优化版本所示
        flat_out[i] = flat_in[i]
    return out
# 用法
N = 1 << 20
inp = torch.arange(N, device='cuda', dtype=torch.float32)
out = copy_scalar(inp)
import torch
def copy_scalar(inp: torch.Tensor) -> torch.Tensor:
    out = torch.empty_like(inp)
    flat_in = inp.view(-1)
    flat_out = out.view(-1)
    for i in range(flat_in.numel()):
        # Each iteration issues a 4-byte load on the GPU
        # This is extremely slow. DO NOT DO THIS!
        # Use vectorized operations to avoid Python loops
        # on GPU tensors as shown in optimized version
        flat_out[i] = flat_in[i]
    return out
# Usage
N = 1 << 20
inp = torch.arange(N, device='cuda', dtype=torch.float32)
out = copy_scalar(inp)
With scalar 4-byte loads, a warp often issues one 128-byte transaction for 128 bytes when aligned. Otherwise, it uses two transactions if the access straddles a 128-byte boundary. Using float4 (16 bytes per thread) means each warp issues 4× more data per memory instruction—512 bytes per warp—split into four 128-byte transactions. This allows the transfer to complete in fewer instructions. Next, let’s optimize by using vector loads.使用标量 4 字节加载时,一个线程束在对齐情况下通常为 128 字节发起一次 128 字节事务。否则,如果访问跨越 128 字节边界,则会使用两次事务。使用 float4(每线程 16 字节)意味着每条内存指令每个线程束发起的数据量提升 4 倍——每个线程束 512 字节——拆分为四次 128 字节事务。这使得传输能以更少的指令完成。接下来,我们通过使用向量加载来进行优化。
After example (C++): vectorized copy. Each thread copies a float4 (16 bytes):修改后示例(C++):向量化拷贝。 每个线程拷贝一个 float4(16 字节):
#include <cuda_runtime.h>
// 16 字节(128 位)向量复制:每个线程一个 float4
static_assert(alignof(float4) == 16, "float4 alignment must be 16 bytes");
__global__ void copyVector16B(const float4* __restrict__ in,
                              float4* __restrict__ out,
                              int N4)  // float4 元素的数量
{
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N4) {
        // 每线程 16B 加载+存储。
        // 在 sm_90 上,NVCC 生成 ld.global.v4.f32 / st.global.v4.f32。
        // 用于 16 字节向量加载与存储
        // 在 sm_90(Hopper)(Blackwell)上,NVCC 生成
        // 针对 32 字节对齐数据生成 ld.global.v8.f32 与 st.global.v8.f32
        out[idx] = in[idx];
    }
#include <cuda_runtime.h>
// 16-byte (128-bit) vector copy: one float4 per thread
static_assert(alignof(float4) == 16, "float4 alignment must be 16 bytes");
__global__ void copyVector16B(const float4* __restrict__ in,
                              float4* __restrict__ out,
                              int N4)  // number of float4 elements
{
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N4) {
        // Per-thread 16B load+store.
        // On sm_90, NVCC emits ld.global.v4.f32 / st.global.v4.f32.
        // for 16-byte vector loads and stores
        // On sm_90 (Hopper) (Blackwell), NVCC emits
        // ld.global.v8.f32 and st.global.v8.f32 for 32-byte aligned data
        out[idx] = in[idx];
    }
}
int main() {
    const int N  = 1 << 20;   // float 总数
    const int N4 = N / 4;     // float4 总数(16B 块)
    float4 *d_in = nullptr, *d_out = nullptr;
    cudaMalloc(&d_in,  N4 * sizeof(float4));   // >=256B 对齐
    cudaMalloc(&d_out, N4 * sizeof(float4));
    dim3 block(256);
    dim3 grid((N4 + block.x - 1) / block.x);
    copyVector16B<<<grid, block>>>(d_in, d_out, N4);
    cudaDeviceSynchronize();
    cudaFree(d_in);
    cudaFree(d_out);
    return 0;
}
}
int main() {
    const int N  = 1 << 20;   // total number of floats
    const int N4 = N / 4;     // total number of float4s (16B chunks)
    float4 *d_in = nullptr, *d_out = nullptr;
    cudaMalloc(&d_in,  N4 * sizeof(float4));   // >=256B aligned
    cudaMalloc(&d_out, N4 * sizeof(float4));
    dim3 block(256);
    dim3 grid((N4 + block.x - 1) / block.x);
    copyVector16B<<<grid, block>>>(d_in, d_out, N4);
    cudaDeviceSynchronize();
    cudaFree(d_in);
    cudaFree(d_out);
    return 0;
}
Here we use CUDA’s built-in float4 type from <cuda_runtime.h>. We launch N/4 threads to maintain 16-byte alignment and issue true vector loads/stores, and each thread copies one float4 (16 bytes). This means each thread handles four floats, and each warp handles 128 floats total in four transactions. cudaMalloc returns pointers aligned to at least 256 bytes which satisfies the float4 (16-byte) requirement and helps with 32-byte aligned vectors when you use 32-byte alignment for the data’s starting address. It’s important to note that misaligned casts can forfeit vectorization. Following is an example that takes advantage of Blackwell’s support for 32-byte vectorized loads:这里我们使用 CUDA 在 <cuda_runtime.h> 中内置的 float4 类型。我们启动 N/4 个线程以保持 16 字节对齐,并发出真正的向量加载/存储,每个线程拷贝一个 float4(16 字节)。这意味着每个线程处理四个 float,每个线程束在四次事务中共处理 128 个 float。cudaMalloc 返回的指针至少按 256 字节对齐,这满足 float4(16 字节)的要求,并且当你将数据的起始地址设为 32 字节对齐时,也有助于实现 32 字节对齐的向量。需要注意的是,未对齐的类型转换会丧失向量化能力。下面是一个利用 Blackwell 对 32 字节向量化加载支持的示例:
// --- 仅限 Blackwell 的变体:每线程 32 字节向量复制
// (PTX:ld.global.v8.f32)
// 要求 32B 对齐。
#include <cuda_runtime.h>
// 32 字节对齐的证明
static_assert(alignof(float8) == 32, "float8 alignment must be 32 bytes");
struct alignas(32) float8 { float v[8]; };
__global__ void copyVector32B(const float8* __restrict__ in,
                              float8* __restrict__ out, int N8) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N8) {
        // 每线程 32B 加载+存储
        // NVCC 在 sm_100 上生成 ld.global.v8.f32/st.global.v8.f32
        out[idx] = in[idx];
    }
}
int main() {
    const int N = 1 << 20;
// --- Blackwell-only variant: 32-byte per-thread vector copy
// (PTX: ld.global.v8.f32)
// Requires 32B alignment.
#include <cuda_runtime.h>
// Proof of 32-byte alignment
static_assert(alignof(float8) == 32, "float8 alignment must be 32 bytes");
struct alignas(32) float8 { float v[8]; };
__global__ void copyVector32B(const float8* __restrict__ in,
                              float8* __restrict__ out, int N8) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N8) {
        // Per-thread 32B load+store
        // NVCC emits ld.global.v8.f32/st.global.v8.f32 on sm_100
        out[idx] = in[idx];
    }
}
int main() {
    const int N = 1 << 20;
    const int N8 = N / 8;
    float8 *d_in, *d_out;
    // cudaMalloc 返回对齐到 ≥256 字节的指针
    // 这将允许编译器生成
    // 优化后的 ld.global.v8.f32 和 st.global.v8.f32 指令
    cudaMalloc(&d_in,  N8 * sizeof(float8));
    cudaMalloc(&d_out, N8 * sizeof(float8));
    dim3 block(256), grid((N8 + block.x - 1) / block.x);
    copyVector32B<<<grid, block>>>(d_in, d_out, N8);
    cudaDeviceSynchronize();
    cudaFree(d_in); cudaFree(d_out);
    return 0;
}
    const int N8 = N / 8;
    float8 *d_in, *d_out;
    // cudaMalloc returns pointers aligned to ≥256 bytes
    // This will allow the compiler to emit
    // optimized ld.global.v8.f32 and st.global.v8.f32 instructions
    cudaMalloc(&d_in,  N8 * sizeof(float8));
    cudaMalloc(&d_out, N8 * sizeof(float8));
    dim3 block(256), grid((N8 + block.x - 1) / block.x);
    copyVector32B<<<grid, block>>>(d_in, d_out, N8);
    cudaDeviceSynchronize();
    cudaFree(d_in); cudaFree(d_out);
    return 0;
}
After example (PyTorch). We can simulate vectorized copy by using a tensor view and clone:修改后示例(PyTorch)。我们可以通过张量视图和 clone 来模拟向量化拷贝:
import torch
def copy_vectorized(inp: torch.Tensor) -> torch.Tensor:
    # 重塑为每 4 个 float 一组的组,以便批量拷贝
    vec = inp.view(-1, 4)
    # 对连续的 CUDA 张量调用 clone() 会执行设备到设备的拷贝
    # 使用诸如 cudaMemcpyAsync() 之类的优化运行时路径。
    out_vec = vec.clone()
    return out_vec.view(-1)
# 用法
N = 1 << 20
inp = torch.arange(N, device='cuda', dtype=torch.float32)
out = copy_vectorized(inp)
import torch
def copy_vectorized(inp: torch.Tensor) -> torch.Tensor:
    # Reshape into groups of 4 floats for bulk copy
    vec = inp.view(-1, 4)
    # clone() on a contiguous CUDA tensor performs a device-to-device copy
    # using optimized runtime paths such as cudaMemcpyAsync().
    out_vec = vec.clone()
    return out_vec.view(-1)
# Usage
N = 1 << 20
inp = torch.arange(N, device='cuda', dtype=torch.float32)
out = copy_vectorized(inp)
Calling clone() on the reshaped tensor causes PyTorch to perform contiguous copies. This is in contrast to copying element by element. By using float4 vector loads, each thread moves 16 bytes per instruction, which is optimized for Hopper. (Blackwell supports 32-byte vector loads per thread.) A warp issues 512 bytes for that load, typically split into four 128-byte transactions when aligned. The benefit comes from fewer instructions per byte moved, better sector utilization, and proper alignment to maximize memory throughput on modern GPUs. This shows far better utilization of memory bandwidth, as shown in Table 7-2.对重塑后的张量调用 clone() 会使 PyTorch 执行连续拷贝,这与逐元素拷贝形成对比。通过使用 float4 向量加载,每个线程每条指令搬运 16 字节,这是针对 Hopper 优化的。(Blackwell 支持每线程 32 字节向量加载。)一个线程束为该次加载发出 512 字节,对齐时通常拆分为四次 128 字节事务。其收益来自每搬运字节所需的指令更少、扇区利用率更高,以及恰当的对齐,从而在现代 GPU 上最大化显存吞吐量。如表 7-2 所示,这体现出对显存带宽的利用要好得多。
| Metric指标 | Before (scalar)优化前(标量) | After (vectorized)优化后(向量化) |
|---|---|---|
| Global Memory Load Efficiency全局内存加载效率 | 28%28% | 97%97% |
| Average sectors per request每次请求的平均扇区数 | 31.831.8 | 4.04.0 |
| DRAM throughput (% of peak)DRAM 吞吐量(占峰值的百分比) | 25%25% | 90% (3.6×)90% (3.6×) |
| Kernel execution time内核执行时间 | 4.2 ms4.2 ms | 1.2 ms (3.5× improvement)1.2 ms(提升 3.5×) |
By using properly aligned float4 vector loads, each thread moves 16 bytes per instruction. This shows far better utilization of memory bandwidth, as shown in the results in Table 7-2.通过使用对齐正确的 float4 向量加载,每个线程每条指令可搬运 16 字节。如表 7-2 中的结果所示,这体现出对显存带宽的利用要好得多。
These metrics confirm the improvement. Global Memory Load Efficiency jumped from 28% to 97% (~3.5×), and percentage of peak DRAM throughput increased from 25% to 90% (~3.6×), trimming the overall kernel runtime by ~3.5×.这些指标印证了上述改进。全局内存加载效率从 28% 跃升至 97%(约 3.5×),DRAM 吞吐量占峰值的百分比从 25% 提升到 90%(约 3.6×),使内核整体运行时间缩短了约 3.5×。
This optimization trimmed the kernel execution runtime by roughly 3.5× from 4.2 ms down to 1.2 ms. Global Memory Load Efficiency jumps from 28% (scalar) to 97% (vectorized), meaning that almost every fetched 128-byte transaction is now used.该优化将内核执行时间从 4.2 ms 缩短到 1.2 ms,约提升 3.5×。全局内存加载效率从 28%(标量)跃升至 97%(向量化),这意味着几乎每一次取回的 128 字节事务都得到了利用。
The average sectors per request drops toward the 4.0 sector-per-line ideal value. This indicates that each 128-byte line is fully utilized. Each warp-wide float4 instruction issues four aligned 128-byte transactions to move 512 bytes. As such, every transaction is fully utilized.每次请求的平均扇区数向 4.0 扇区/行的理想值下降。这表明每个 128 字节的行都被充分利用。每条线程束范围的 float4 指令发出四个对齐的 128 字节事务,以搬运 512 字节。因此,每个事务都被充分利用。
The reduction in memory requests and the replacement of four scalar loads with one vector load increase global memory load efficiency from 28% to 97% and raise sustained DRAM throughput from about 25% to about 90% of peak. In this case, warps are doing far fewer memory operations and get more data with each operation, so they spend much less time waiting on memory and more time executing useful work. The end result is a significantly faster kernel.内存请求数量的减少,以及用一次向量加载替代四次标量加载,使全局内存加载效率从 28% 提升到 97%,并将持续的 DRAM 吞吐量从峰值的约 25% 提升到约 90%。在这种情况下,线程束执行的内存操作少得多,且每次操作获取的数据更多,因此它们等待内存的时间大幅减少,执行有效工作的时间更多。最终结果是内核显著加快。
| Aspect方面 | Coalesced warp load (interthread)合并的线程束加载(线程间) | Vectorizing (intrathread)向量化(线程内) |
|---|---|---|
| Granularity粒度 | Threads ↔ contiguous memory addresses线程 ↔ 连续内存地址 | Per thread ↔ vector loads每线程 ↔ 向量加载 |
| Typical fix典型修复方法 | Contiguous indexing (stride = 1)连续索引(步长 = 1) | Use float4, a custom 32-byte struct with explicit 32-byte alignment, or a 32-byte-aligned vector type (e.g., Blackwell and CUDA 13+)使用 float4、显式 32 字节对齐的自定义 32 字节结构体,或 32 字节对齐的向量类型(例如 Blackwell 与 CUDA 13+) |
| Transactions/warp事务数/线程束 | 32 threads × 4 bytes → 128 bytes, equal to 4 32-byte sectors if aligned (4 sectors)32 个线程 × 4 字节 → 128 字节,若已对齐则等于 4 个 32 字节扇区(4 个扇区) | 32 threads × 16 bytes → 512 bytes, equal to 4 128-byte transactions, which correspond to 16 32-byte sectors (16 sectors)32 个线程 × 16 字节 → 512 字节,等于 4 个 128 字节事务,对应 16 个 32 字节扇区(16 个扇区) |
| Instruction count指令数 | Same number of loads加载次数相同 | 1 vector load instead of 4 scalars1 次向量加载替代 4 次标量加载 |
| change变化 | ||
| Benefit收益 | Fewer scattered sectors更少的分散扇区 | Perfectly sized, fewer sectors尺寸恰好匹配,扇区更少 |
Let’s quickly compare coalesced global memory access from the previous section to vectorized memory access discussed here. Coalescing makes sure threads in a warp all hit one big contiguous block. Vectorizing makes sure each thread fetches a wide chunk that exactly maps onto those big blocks. The differences are summarized in我们快速对比一下上一节介绍的合并访问全局内存与此处讨论的向量化显存访问。合并访问确保一个线程束中的所有线程都命中同一个大的连续块。向量化则确保每个线程获取一个宽数据块,且恰好映射到这些大块上。两者的差异总结于
By combining both strategies, you ensure that warps hit contiguous blocks such that each thread fetches a wide, aligned vector. This helps you push your kernel’s memory bandwidth utilization to its peak and unlock the full power of your GPU.通过结合这两种策略,可以确保线程束命中连续块,同时每个线程获取一个宽的、已对齐的向量。这有助于将内核的显存带宽利用率推向峰值,充分释放 GPU 的全部能力。
It’s worth noting that, prior to Blackwell and CUDA 13, global memory vector loads were limited to 16 bytes (128 bits) per thread. However, Blackwell and CUDA 13 added 32-byte (256-bit) load/store instructions and data types for specific vector types with 32-byte alignment.值得注意的是,在 Blackwell 和 CUDA 13 之前,全局内存向量加载被限制为每个线程 16 字节(128 位)。不过,Blackwell 和 CUDA 13 针对具有 32 字节对齐的特定向量类型新增了 32 字节(256 位)的加载/存储指令与数据类型。
When available, prefer these wider 32-byte types and instructions for user-defined 8-float aggregates. This will reduce the number of instructions needed to load and store wider 32-byte aligned data.在可用的情况下,对于用户自定义的 8 个 float 的聚合类型,优先使用这些更宽的 32 字节类型与指令。这将减少加载和存储更宽的 32 字节对齐数据所需的指令数量。
Custom 8-float aggregates will still compile into two 16-byte loads unless you explicitly use the 32-byte-aligned types that map to a single 32-byte instruction.除非显式使用映射到单条 32 字节指令的 32 字节对齐类型,否则自定义的 8 个 float 的聚合类型仍会被编译为两次 16 字节加载。
使用共享内存的分块与数据复用
Tiling and Data Reuse Using Shared Memory
A common performance pitfall is repeatedly reading the same data from global memory. Tiling is a technique to avoid this by loading chunks of data into faster on-chip shared memory—and reusing those chunks across many threads.一个常见的性能陷阱是反复从全局内存读取相同的数据。分块(tiling)是一种避免该问题的技术:将数据块加载到更快的片上共享内存,并在众多线程之间复用这些数据块。
For example, a naive matrix multiplication of size N × N might load each element of matrix A from HBM N times, once for each row of B it multiplies with. This results in N–1 redundant loads per element. And on Blackwell, which can easily execute tens of teraFLOPS (TFLOPS), redundant loads can waste memory bandwidth, which could otherwise be feeding more math operations to the GPU SMs.例如,对规模为 N × N 的矩阵乘法,朴素实现可能会从 HBM 中加载矩阵 A 的每个元素 N 次,每与 B 的一行相乘就加载一次。这导致每个元素有 N–1 次冗余加载。而在 Blackwell 上,它可以轻松执行数十 teraFLOPS(TFLOPS),冗余加载会浪费显存带宽,而这些带宽本可以为 GPU 的 SM 提供更多数学运算。
Tiling eliminates this waste by having each thread block pull a small submatrix (a tile) of A and B into shared memory exactly once. It then reuses the cached values across all threads for multiple multiply-accumulate operations. In our next example, we’ll use a 32 × 32 tile, which is a common choice that fits well in shared memory.分块通过让每个线程块将 A 和 B 的一个小子矩阵(一个*分块*)恰好一次地拉入共享内存来消除这种浪费。随后它在所有线程之间复用这些缓存值,完成多次乘累加运算。在下一个示例中,我们将使用 32 × 32 的分块,这是一个常见选择,能很好地放入共享内存。
Threads within a block can cooperatively load the tile into shared memory, then call __syncthreads() to synchronize the data. Then the threads perform parallel matrix-multiply computations using the data in shared memory. This amortizes the global memory access cost over many threads and computations. It’s worth noting that these tile loads are also arranged to be coalesced. Specifically, each warp loads a full 128-byte segment from global memory into shared memory—consistent with the coalescing example from earlier.线程块内的线程可以协作地将分块加载到共享内存,然后调用 __syncthreads() 同步数据。接着,线程使用共享内存中的数据执行并行的矩阵乘法计算。这样就把全局内存访问开销分摊到众多线程和计算之上。值得注意的是,这些分块加载也被安排为合并访问。具体来说,每个线程束从全局内存加载完整的 128 字节段到共享内存——与前面的合并访问示例一致。
By reading each element from DRAM only once (into shared memory) and reusing it for many calculations, we reduce global memory traffic. Let’s illustrate this with an N × N matrix multiplication example. First, consider a naive implementation.通过只从 DRAM 读取每个元素一次(读入共享内存)并将其复用于大量计算,我们减少了全局内存流量。让我们用一个 N × N 矩阵乘法的例子来说明。首先,考虑朴素实现。
Before example (CUDA C++): naive matrix multiply. Each thread computes one element of the result matrix C, reading entire rows of A and columns of B from global memory for each output:改进前的示例(CUDA C++):朴素矩阵乘法。每个线程计算结果矩阵 C 的一个元素,对每个输出都从全局内存读取 A 的整行和 B 的整列:
#include <cuda_runtime.h>
#include <iostream>
__global__ void naiveMatMul(const float* A, const float* B, float* C, int N) {
    int row = blockIdx.y * blockDim.y + threadIdx.y;
    int col = blockIdx.x * blockDim.x + threadIdx.x;
    if (row < N && col < N) {
        float sum = 0.0f;
        for (int k = 0; k < N; ++k) {
            // 每个线程加载 A[row, k] 和 B[k, col]
            // 对每个 k 都从全局内存中加载。
            // 这非常耗费内存。
            sum += A[row * N + k] * B[k * N + col];
        }
        C[row * N + col] = sum;
#include <cuda_runtime.h>
#include <iostream>
__global__ void naiveMatMul(const float* A, const float* B, float* C, int N) {
    int row = blockIdx.y * blockDim.y + threadIdx.y;
    int col = blockIdx.x * blockDim.x + threadIdx.x;
    if (row < N && col < N) {
        float sum = 0.0f;
        for (int k = 0; k < N; ++k) {
            // Each thread loads A[row, k] and B[k, col]
            // from global memory for every k.
            // This is very memory heavy.
            sum += A[row * N + k] * B[k * N + col];
        }
        C[row * N + col] = sum;
    }
}
int main() {
    const int N = 1024;
    size_t bytes = N * N * sizeof(float);
    float* h_A = nullptr;
    float* h_B = nullptr;
    float* h_C = nullptr;
    cudaMallocHost(&h_A, N*N * sizeof(float));
    cudaMallocHost(&h_B, N*N * sizeof(float));
    cudaMallocHost(&h_C, N*N * sizeof(float));
    for (int i = 0; i < N*N; ++i) { h_A[i] = 1.0f; h_B[i] = 1.0f; }
    float *d_A, *d_B, *d_C;
    cudaMalloc(&d_A, bytes);
    cudaMalloc(&d_B, bytes);
    cudaMalloc(&d_C, bytes);
    cudaMemcpy(d_A, h_A, bytes, cudaMemcpyHostToDevice);
    cudaMemcpy(d_B, h_B, bytes, cudaMemcpyHostToDevice);
    dim3 block(32, 32);
    dim3 grid((N + 31) / 32, (N + 31) / 32);
    naiveMatMul<<<grid, block>>>(d_A, d_B, d_C, N);
    cudaDeviceSynchronize();
    cudaFree(d_A);
    cudaFree(d_B);
    cudaFree(d_C);
    cudaFreeHost(h_A);
    cudaFreeHost(h_B);
    cudaFreeHost(h_C);
    return 0;
}
This CUDA C++ kernel issues global memory loads for every multiplication inside the inner loop. Each thread reads A[row, k] and B[k, col] from DRAM for every k, causing massive redundant traffic. The result is a heavily memory-bound kernel with low SM utilization and frequent stalls waiting on global memory. Here is the PyTorch version of the naive matrix multiplication:这个 CUDA C++ 内核在内层循环中为每次乘法都发起全局内存加载。每个线程对每个 k 都从 DRAM 读取 A[row, k] 和 B[k, col],造成大量冗余流量。结果是一个严重受限于内存的内核,SM 利用率低,并频繁因等待全局内存而停顿。下面是朴素矩阵乘法的 PyTorch 版本:
import torch
def naive_matmul(A, B):
    N = A.size(0)
    C = torch.zeros((N, N), device='cuda')
    for i in range(N):
        for j in range(N):
            # 每个点积都反复从全局内存加载 A[i,:] B[:,j]
            C[i, j] = (A[i, :] * B[:, j]).sum()
    return C
import torch
def naive_matmul(A, B):
    N = A.size(0)
    C = torch.zeros((N, N), device='cuda')
    for i in range(N):
        for j in range(N):
            # Each dot product loads A[i,:] B[:,j] from global memory repeatedly
            C[i, j] = (A[i, :] * B[:, j]).sum()
    return C
# 用法
N = 1024
A = torch.ones((N, N), device='cuda', dtype=torch.float32)
B = torch.ones((N, N), device='cuda', dtype=torch.float32)
C = naive_matmul(A, B)
# Usage
N = 1024
A = torch.ones((N, N), device='cuda', dtype=torch.float32)
B = torch.ones((N, N), device='cuda', dtype=torch.float32)
C = naive_matmul(A, B)
This PyTorch implementation uses nested Python loops. While the innermost operations are offloaded to GPU as elementwise multiply and sum operations, it still triggers repeated global memory loads under the hood for each dot product. This mimics the memory-bound behavior of the naive CUDA kernel since the GPU spends most cycles waiting on memory rather than computing multiplications.这个 PyTorch 实现使用嵌套的 Python 循环。虽然最内层的运算被作为逐元素乘法和求和操作卸载到 GPU,但它在底层仍会为每个点积触发重复的全局内存加载。这模拟了朴素 CUDA 内核受限于内存的行为,因为 GPU 的大部分周期都花在等待内存上,而不是执行乘法计算。
Now, let’s apply tiling to improve this. We divide the matrices into 32 × 32 tiles. 32 × 32 is a convenient tile size since it aligns with a warp size of 32, it fits well in shared memory, and it maps to a full warp of 32 threads reading each row. This allows each warp to collaboratively load and process one single row (per tile) at a time.现在,让我们应用分块来改进它。我们将矩阵划分为 32 × 32 的分块。32 × 32 是一个方便的尺寸,因为它与 32 的线程束大小对齐,能很好地放入共享内存,并且对应一个完整的 32 线程线程束读取每一行。这使得每个线程束可以一次协作地加载和处理(每个分块中的)单独一行。
As such, each thread block loads one 32 × 32 tile of A and one 32 × 32 tile of B into shared memory, performs the 32 × 32 matrix multiplies, and accumulates the results. This way, each element of A and B is loaded from HBM only once per tile instead of 32 times in the naive version. The optimized version using shared memory to cache tiles for matrix multiplies is shown here:因此,每个线程块将 A 的一个 32 × 32 分块和 B 的一个 32 × 32 分块加载到共享内存,执行 32 × 32 的矩阵乘法并累加结果。这样一来,A 和 B 的每个元素在每个分块中只需从 HBM 加载一次,而不是朴素版本中的 32 次。使用共享内存缓存分块以进行矩阵乘法的优化版本如下所示:
#include <cuda_runtime.h>
#include <iostream>
#define TILE_SIZE 32
__global__ void tiledMatMul(const float* A, const float* B, float* C, int N) {
    __shared__ float sA[TILE_SIZE][TILE_SIZE];
    __shared__ float sB[TILE_SIZE][TILE_SIZE];
    int row = blockIdx.y * TILE_SIZE + threadIdx.y;
    int col = blockIdx.x * TILE_SIZE + threadIdx.x;
    float sum = 0.0f;
    // 使用该分块计算部分结果
    // 在共享内存中
    for (int t = 0; t < N; t += TILE_SIZE) {
        // 协作地将 A 和 B 的一个分块加载到共享内存中
        // 带边界检查地加载分块 A
        if (row < N && (t + threadIdx.x) < N) {
            sA[threadIdx.y][threadIdx.x] = A[row * N + t + threadIdx.x];
        } else {
#include <cuda_runtime.h>
#include <iostream>
#define TILE_SIZE 32
__global__ void tiledMatMul(const float* A, const float* B, float* C, int N) {
    __shared__ float sA[TILE_SIZE][TILE_SIZE];
    __shared__ float sB[TILE_SIZE][TILE_SIZE];
    int row = blockIdx.y * TILE_SIZE + threadIdx.y;
    int col = blockIdx.x * TILE_SIZE + threadIdx.x;
    float sum = 0.0f;
    // compute partial results using the tile
    // in shared memory
    for (int t = 0; t < N; t += TILE_SIZE) {
        // Cooperative load of a tile of A and B into shared memory
        // Load tile A with boundary check
        if (row < N && (t + threadIdx.x) < N) {
            sA[threadIdx.y][threadIdx.x] = A[row * N + t + threadIdx.x];
        } else {
            sA[threadIdx.y][threadIdx.x] = 0.0f;
        }
        // 带边界检查地加载分块 B
        if ((t + threadIdx.y) < N && col < N) {
            sB[threadIdx.y][threadIdx.x] = B[(t + threadIdx.y) * N + col];
        } else {
            sB[threadIdx.y][threadIdx.x] = 0.0f;
        }
        // 我们稍后将对此进行优化,以使用一个
        // 线程块作用域的协作组屏障
        __syncthreads();
        // 使用已加载到共享内存中的分块进行计算
        for (int k = 0; k < TILE_SIZE; ++k) {
            sum += sA[threadIdx.y][k] * sB[k][threadIdx.x];
        }
        // 我们稍后将对此进行优化,以使用一个
        // 线程块作用域的协作组屏障
        __syncthreads();
    }
    if (row < N && col < N) {
        C[row * N + col] = sum;
    }
}
int main() {
    const int N = 1024;
    size_t bytes = N * N * sizeof(float);
    float* h_A = nullptr;
    float* h_B = nullptr;
    float* h_C = nullptr;
    cudaMallocHost(&h_A, N*N * sizeof(float));
    cudaMallocHost(&h_B, N*N * sizeof(float));
    cudaMallocHost(&h_C, N*N * sizeof(float));
    for (int i = 0; i < N*N; ++i) { h_A[i] = 1.0f; h_B[i] = 1.0f; }
    float *d_A, *d_B, *d_C;
    cudaMalloc(&d_A, bytes);
    cudaMalloc(&d_B, bytes);
    cudaMalloc(&d_C, bytes);
    cudaMemcpy(d_A, h_A, bytes, cudaMemcpyHostToDevice);
    cudaMemcpy(d_B, h_B, bytes, cudaMemcpyHostToDevice);
    dim3 block(TILE_SIZE, TILE_SIZE);
    dim3 grid((N + TILE_SIZE - 1) / TILE_SIZE, (N + TILE_SIZE - 1) / TILE_SIZE);
    tiledMatMul<<<grid, block>>>(d_A, d_B, d_C, N);
            sA[threadIdx.y][threadIdx.x] = 0.0f;
        }
        // Load tile B with boundary check
        if ((t + threadIdx.y) < N && col < N) {
            sB[threadIdx.y][threadIdx.x] = B[(t + threadIdx.y) * N + col];
        } else {
            sB[threadIdx.y][threadIdx.x] = 0.0f;
        }
        // We will optimize this later to use a
        // thread-block-scoped cooperative-groups barrier
        __syncthreads();
        // Compute using the tile loaded in shared memory
        for (int k = 0; k < TILE_SIZE; ++k) {
            sum += sA[threadIdx.y][k] * sB[k][threadIdx.x];
        }
        // We will optimize this later to use a
        // thread-block-scoped cooperative-groups barrier
        __syncthreads();
    }
    if (row < N && col < N) {
        C[row * N + col] = sum;
    }
}
int main() {
    const int N = 1024;
    size_t bytes = N * N * sizeof(float);
    float* h_A = nullptr;
    float* h_B = nullptr;
    float* h_C = nullptr;
    cudaMallocHost(&h_A, N*N * sizeof(float));
    cudaMallocHost(&h_B, N*N * sizeof(float));
    cudaMallocHost(&h_C, N*N * sizeof(float));
    for (int i = 0; i < N*N; ++i) { h_A[i] = 1.0f; h_B[i] = 1.0f; }
    float *d_A, *d_B, *d_C;
    cudaMalloc(&d_A, bytes);
    cudaMalloc(&d_B, bytes);
    cudaMalloc(&d_C, bytes);
    cudaMemcpy(d_A, h_A, bytes, cudaMemcpyHostToDevice);
    cudaMemcpy(d_B, h_B, bytes, cudaMemcpyHostToDevice);
    dim3 block(TILE_SIZE, TILE_SIZE);
    dim3 grid((N + TILE_SIZE - 1) / TILE_SIZE, (N + TILE_SIZE - 1) / TILE_SIZE);
    tiledMatMul<<<grid, block>>>(d_A, d_B, d_C, N);
    // 将内核与设备同步
    // 以保证计时准确性
    cudaDeviceSynchronize();
    cudaFree(d_A);
    cudaFree(d_B);
    cudaFree(d_C);
    cudaFreeHost(h_A);
    cudaFreeHost(h_B);
    cudaFreeHost(h_C);
    return 0;
}
    // synchronize the kernel with the device
    // for timing accuracy
    cudaDeviceSynchronize();
    cudaFree(d_A);
    cudaFree(d_B);
    cudaFree(d_C);
    cudaFreeHost(h_A);
    cudaFreeHost(h_B);
    cudaFreeHost(h_C);
    return 0;
}
In this tiled kernel, each block cooperatively loads a 32 × 32 tile of A (into sA) and a 32 × 32 tile of B (into sB) from global memory. These loads happen in the first two lines inside the loop and are followed by __syncthreads() to ensure the tile is fully loaded before use.在这个分块内核中,每个块协作地从全局内存加载 A 的 32 × 32 分块(存入 sA)和 B 的 32 × 32 分块(存入 sB)。这些加载发生在循环内的前两行,随后调用 __syncthreads(),以确保分块在使用前已完全加载。
Then the block performs 32 × 32 multiply-accumulate operations using the shared memory tiles. This inner loop, running over k in steps of 32, reuses each loaded value 32×, yielding a 32× reduction in global memory reads for those elements.随后,该块使用共享内存中的分块执行 32 × 32 次乘累加运算。这个内层循环以 32 为步长遍历 k,使每个已加载的值被复用 32 次,从而将这些元素的全局内存读取量减少 32 倍。
After finishing all tile iterations, each thread writes its result to C. The result is a dramatic 8× reduction in global memory accesses per thread, as you’ll see in a bit.完成所有分块迭代后,每个线程将其结果写入 C。结果是每个线程的全局内存访问量大幅减少 8 倍,稍后你就会看到。
This PyTorch version manually tiles the matrices and invokes torch.mm on each tile. PyTorch’s torch.mm leverages NVIDIA’s cuBLAS and CUTLASS, which implement shared memory tiling and reuse internally at the C++ level. Here is the PyTorch version of the tiled matrix multiply:这个 PyTorch 版本手动对矩阵分块,并对每个分块调用 torch.mm。PyTorch 的 torch.mm 借助 NVIDIA 的 cuBLAS 和 CUTLASS,它们在 C++ 层面内部实现了共享内存分块与复用。以下是分块矩阵乘法的 PyTorch 版本:
import torch
def tiled_matmul(A, B, tile_size=32):
    N = A.size(0)
    C = torch.zeros((N, N), device='cuda')
    for i in range(0, N, tile_size):
        for j in range(0, N, tile_size):
            C_block = torch.zeros((tile_size, tile_size), device='cuda')
            for k in range(0, N, tile_size):
                A_block = A[i:i+tile_size, k:k+tile_size]
                B_block = B[k:k+tile_size, j:j+tile_size]
                # torch.mm 使用经过优化的内核(内部很可能做了分块)
                C_block += torch.mm(A_block, B_block)
            C[i:i+tile_size, j:j+tile_size] = C_block
import torch
def tiled_matmul(A, B, tile_size=32):
    N = A.size(0)
    C = torch.zeros((N, N), device='cuda')
    for i in range(0, N, tile_size):
        for j in range(0, N, tile_size):
            C_block = torch.zeros((tile_size, tile_size), device='cuda')
            for k in range(0, N, tile_size):
                A_block = A[i:i+tile_size, k:k+tile_size]
                B_block = B[k:k+tile_size, j:j+tile_size]
                # torch.mm uses an optimized kernel (likely tiling internally)
                C_block += torch.mm(A_block, B_block)
            C[i:i+tile_size, j:j+tile_size] = C_block
| Metric指标 | Before (naive kernel)优化前(朴素内核) | After (tiled kernel)优化后(分块内核) | Notes说明 |
|---|---|---|---|
| DRAM throughputDRAM 吞吐量 | 90%90% | 25% (3.6× less)25%(减少 3.6 倍) | Naive uses more bandwidth, but it’s wasteful. The tile朴素版本占用了更多带宽,但属于浪费。分块 |
| (% of peak)(占峰值的百分比) | implementation is lower because it’s more efficient after tiling due to fewer redundant loads.实现更低,因为分块后冗余加载更少,因而更高效。 | ||
| Achieved occupancy实际占用率 | 42%42% | 89%89% | More resident warps make forward progress with fewer stalls.更多常驻线程束以更少的停顿向前推进。 |
| (%)(%) | |||
| Floating-point浮点 | 15 GFLOPS15 GFLOPS | 170 GFLOPS170 GFLOPS | Small matrix size limits the absolute value. Reuse increases矩阵尺寸小限制了绝对值。复用提升了 |
| throughput吞吐量 | sustained compute.持续计算。 | ||
| (GFLOPS)(GFLOPS) | (The absolute GFLOPS numbers are low because the matrix size (N = 1,024) is small and the kernel is memory limited.)(绝对 GFLOPS 数值偏低,是因为矩阵尺寸(N = 1,024)较小,且该内核受内存限制。) | ||
| Global memory全局内存 | 98009800 | 12001200 | Each element is fetched once per tile instead of 32 times (once每个元素在每个分块中只取一次,而不是 32 次(一次 |
| load sectors加载扇区数 | per thread). Total number of 32-byte sector reads issued by the kernel. The decrease reflects the elimination of redundant loads thanks to shared-memory tiling.每线程)。内核发出的 32 字节扇区读取总数。该数值的下降反映了共享内存分块消除了冗余加载。 | ||
| Shared memory共享内存 | 52%52% | 99%99% | Tiled kernel access pattern avoids memory-bank conflicts on sA分块内核的访问模式避免了 sA |
| throughput (% of吞吐量(占 | and sB.和 sB 上的存储体冲突。 | ||
| peak)峰值) |
    return C
# 用法
N = 1024
A = torch.ones((N, N), device='cuda', dtype=torch.float32)
B = torch.ones((N, N), device='cuda', dtype=torch.float32)
C = tiled_matmul(A, B)
    return C
# Usage
N = 1024
A = torch.ones((N, N), device='cuda', dtype=torch.float32)
B = torch.ones((N, N), device='cuda', dtype=torch.float32)
C = tiled_matmul(A, B)
The performance impact of tiling is significant. By structuring the computation in tiles and reusing data in shared memory, we reduce DRAM traffic and raise arithmetic intensity because each byte retrieved from memory is used for many more floating-point operations. Along with fewer global memory transactions, we also observe higher achieved occupancy. Table 7-4 compares key metrics before and after applying shared memory tiling.分块对性能的影响十分显著。通过将计算组织成分块并在共享内存中复用数据,我们减少了 DRAM 流量并提高了算术强度,因为从内存取回的每个字节都被用于多得多的浮点运算。除了全局内存事务减少之外,我们还观察到实际达到的占用率更高。表 7-4 对比了应用共享内存分块前后的关键指标。
Staging 32 × 32 tiles in shared memory makes sure that each element is fetched once from DRAM and reused across all threads in a block. DRAM throughput falls from 90% to 25%, a reduction of about 3.6×, which is expected when redundant traffic is removed.将 32 × 32 的分块暂存到共享内存中,可确保每个元素只从 DRAM 取一次,并在一个线程块内的所有线程间复用。DRAM 吞吐量从 90% 降至 25%,降幅约 3.6 倍,这在消除冗余流量时是预期之中的。
The drop in DRAM throughput is desirable because the kernel now performs more work per byte moved. Arithmetic intensity increases, and sustained floating-point throughput rises from 15 GFLOPS to 170 GFLOPS, a gain of nearly 11×.DRAM 吞吐量的下降是可喜的,因为内核现在每搬运一个字节所完成的工作更多。算术强度提高,持续浮点吞吐量从 15 GFLOPS 升至 170 GFLOPS,提升近 11 倍。
This shift in arithmetic intensity moves the kernel from memory bound toward compute bound, which is ideal because performance becomes limited by abundant floating-point throughput rather than comparatively scarce chip bandwidth. Global memory load sectors drop substantially from 9,800 down to 1,200 because each element is fetched once into shared memory and reused across threads. This eliminates redundant loads. The tiled kernel also accesses sA and sB in a way that avoids shared-memory bank conflicts, which is why shared memory throughput approaches 100%.算术强度的这一转变使内核从显存受限转向计算受限,这是理想情况,因为性能不再受相对稀缺的芯片带宽限制,而是受充裕的浮点吞吐量限制。全局内存加载扇区数从 9,800 大幅降至 1,200,因为每个元素只被取入共享内存一次并在各线程间复用。这消除了冗余加载。分块内核访问 sA 和 sB 的方式还避免了共享内存存储体冲突,这正是共享内存吞吐量接近 100% 的原因。
Overall, we shifted this kernel from memory bound to compute bound, which was the goal. We successfully relieved memory pressure, freed up the memory bus for other useful work, and achieved higher compute throughput.总体而言,我们把这个内核从显存受限转变为计算受限,这正是目标所在。我们成功缓解了显存压力,为其他有用的工作释放了内存总线,并获得了更高的计算吞吐量。
We also see a large increase in achieved occupancy percentage from 42% to 89%. This metric nearly doubles because the tiled kernel keeps allowing more resident warps to make progress with fewer stalls. As such, the SMs remain busy more consistently.我们还看到实际达到的占用率百分比从 42% 大幅提升到 89%。该指标几乎翻倍,因为分块内核持续让更多常驻线程束以更少的停顿向前推进。因此,SM 能更稳定地保持忙碌状态。
By introducing shared memory tiling, we increased per-thread work without increasing per-thread resource usage beyond available registers and shared memory. This helped our kernel achieve higher occupancy and utilization, which is important on GPUs like Blackwell, which offer a very large register file (65,536 32-bit registers per SM) that threads can exploit up to the 255-register per-thread limit without spilling.通过引入共享内存分块,我们在不使每线程资源用量超出可用寄存器和共享内存的前提下,增加了每线程的工作量。这帮助我们的内核实现了更高的占用率和利用率,这在 Blackwell 这类 GPU 上尤为重要——它们提供非常大的寄存器堆(每个 SM 65,536 个 32 位寄存器),线程可以在每线程 255 个寄存器的上限内充分利用,而不会发生寄存器溢出。
We can compare the arithmetic intensity of the naive and tiled kernels by examining their sustained FLOP rates and average DRAM bandwidth. The naive version ran at 15 GFLOPS while moving 10 GB/s of data on average, or 1.5 FLOPS per byte. The tiled implementation, by contrast, sustained 170 GFLOPS while moving 21 GB/s on average, or 8 FLOPS/byte.我们可以通过考察朴素内核与分块内核的持续 FLOP 速率和平均 DRAM 带宽,来比较二者的算术强度。朴素版本以 15 GFLOPS 运行,同时平均搬运 10 GB/s 的数据,即每字节 1.5 FLOPS。相比之下,分块实现持续达到 170 GFLOPS,同时平均搬运 21 GB/s,即 8 FLOPS/字节。
It might be tempting to increase the tile size further to 64 × 64 or 128 × 128 in order to reduce memory traffic even more and increase data reuse. Just remember that larger tiles consume more on-chip resources, including both registers and shared memory. This leaves less capacity for additional thread blocks on each SM.人们可能很想把分块尺寸进一步增大到 64 × 64 或 128 × 128,以进一步减少内存流量并提高数据复用。但要记住,更大的分块会消耗更多片上资源,包括寄存器和共享内存。这会为每个 SM 上额外的线程块留下更少的容量。
For instance, Blackwell GPUs provide up to 228 KB of allocatable shared memory per SM. This can easily accommodate a 64 × 64 tile of 4-byte floats in which each A and B tile requires 16 KB (16,384 bytes = 64 × 64 floats × 4 bytes per float). However, in addition to shared-memory usage, you need to budget for the additional registers per thread.例如,Blackwell GPU 每个 SM 提供最多 228 KB 的可分配共享内存。这可以轻松容纳一个由 4 字节浮点数构成的 64 × 64 分块,其中每个 A 分块和 B 分块需要 16 KB(16,384 字节 = 64 × 64 个浮点数 × 每个浮点数 4 字节)。然而,除了共享内存占用之外,你还需要为每线程额外的寄存器预留预算。
Each Blackwell SM provides up to 64K registers (32-bit each) in total with a per-thread maximum of 255 registers. When you launch a 32 × 32 thread block (1,024 threads) to compute a 64 × 64 tile, each thread handles a 2 × 2 subtile, which produces 4 outputs.每个 Blackwell SM 总共提供最多 64K 个寄存器(每个 32 位),每线程最多 255 个寄存器。当你启动一个 32 × 32 的线程块(1,024 个线程)来计算一个 64 × 64 的分块时,每个线程处理一个 2 × 2 的子块,产生 4 个输出。
For a 64 × 64 tile size, you need the following: four accumulator registers (one per output), two registers for A-tile elements (reused across two outputs), two registers for B-tile elements (same reuse), and ~4 registers for loop counters, thread indices, and address arithmetic. In total, this is ~12 registers per thread.对于 64 × 64 的分块尺寸,你需要以下寄存器:4 个累加器寄存器(每个输出一个)、2 个用于 A 分块元素的寄存器(在两个输出之间复用)、2 个用于 B 分块元素的寄存器(同样复用),以及约 4 个用于循环计数器、线程索引和地址运算的寄存器。总计约为每线程 12 个寄存器。
12 registers per thread × 1,024 threads per block = 12,288 registers needed per thread block. And since each Blackwell SM has 65,536 32-bit registers (maximum 255 registers per thread), in theory, up to 5 blocks’ worth of registers can fit (≈61,440 registers). However, the SM can support only 2,048 concurrent threads (64 warps). So, in practice, occupancy is limited by the smaller limits of registers, shared memory, warps, and threads. For this configuration, two blocks per SM will saturate the 2,048-thread limit.每线程 12 个寄存器 × 每块 1,024 个线程 = 每个线程块需要 12,288 个寄存器。而由于每个 Blackwell SM 有 65,536 个 32 位寄存器(每线程最多 255 个),理论上最多可容纳 5 个线程块的寄存器用量(约 61,440 个寄存器)。然而,SM 只能支持 2,048 个并发线程(64 个线程束)。因此,在实践中,占用率受限于寄存器、共享内存、线程束和线程这几者中较小的限制。对于此配置,每个 SM 两个线程块就会达到 2,048 个线程的上限。
For a 64 × 64 tile size, 22 registers per thread are needed for a total of 22,528 registers for a 32 × 32 thread block (1,024 threads). In this case, you can only fit up to two thread blocks per Blackwell SM. This translates to a maximum occupancy of only 2,048 threads—hitting the SM’s thread limit with only two blocks (out of the 16 maximum concurrent blocks per SM).对于 64 × 64 的分块尺寸,每线程需要 22 个寄存器,一个 32 × 32 的线程块(1,024 个线程)总共需要 22,528 个寄存器。在这种情况下,每个 Blackwell SM 最多只能容纳两个线程块。这意味着最大占用率仅为 2,048 个线程——仅用两个线程块就触及了 SM 的线程上限(而每个 SM 最多支持 16 个并发线程块)。
A reduction in concurrent thread blocks caused by using a larger tile size will lower occupancy and hurt performance if you exceed the hardware’s limits. In practice, your tile dimensions must fit within the GPU’s shared-memory and register budgets to maintain high occupancy and throughput.使用更大的分块(tile)尺寸会导致并发线程块数量减少,从而降低占用率;一旦超出硬件限制,还会损害性能。在实践中,分块维度必须落在 GPU 的共享内存与寄存器预算之内,才能维持高占用率和高吞吐量。
For a Blackwell GPU with ~228 KB of allocatable shared memory per SM, a 64 × 64 tile (~16 KB per input matrix tile) might still fit, but doubling the tile dimensions squares the reuse factor while quadrupling shared memory usage. There are diminishing returns and possible trade-offs.对于每个 SM 拥有约 228 KB 可分配共享内存的 Blackwell GPU 而言,64 × 64 的分块(每个输入矩阵分块约 16 KB)或许仍能容纳,但把分块维度翻倍会使复用因子变为平方,同时使共享内存用量变为四倍。这里存在收益递减,也可能存在权衡取舍。
It is recommended to experiment with different tile dimensions to balance on-chip reuse against resource limits. A 32 × 32 tile is a solid starting point on modern NVI-DIA GPUs, but depending on your shared-memory and register usage, you may find that a slightly smaller or larger tile delivers better throughput.建议尝试不同的分块维度,以在片上复用与资源限制之间取得平衡。在现代 NVIDIA GPU 上,32 × 32 的分块是一个稳妥的起点;但取决于你的共享内存与寄存器用量,你可能会发现稍小或稍大的分块能带来更好的吞吐量。
In short, we transformed a naive, global-memory-only matrix multiplication into a tiled implementation that uses shared memory. This enabled cooperative data reuse, reduced the number of DRAM transactions, and boosted arithmetic intensity. Both the CUDA C++ and PyTorch implementations benefited from this tiling technique.简而言之,我们把一个仅使用全局内存的朴素矩阵乘法改造成了使用共享内存的分块实现。这实现了协作式数据复用,减少了 DRAM 事务数量,并提升了算术强度。CUDA C++ 与 PyTorch 两种实现都从这一分块技术中获益。
It’s worth noting that the tiling techniques we applied manually are exactly what high-performance GPU libraries do under the hood. NVIDIA’s CUTLASS library, for instance, provides templated components to implement general matrix multiplies (GEMMs) with multiple layers of tiling. These CUTLASS components load fragments of matrices into registers and shared memory—and then compute partial results much like our previous 32 × 32 tile example.值得注意的是,我们手动应用的分块技术,正是高性能 GPU 库在底层所做的事情。例如,NVIDIA 的 CUTLASS 库提供了模板化组件,用于实现具有多层分块的通用矩阵乘法(GEMM)。这些 CUTLASS 组件把矩阵片段加载到寄存器和共享内存中,然后计算部分结果,与我们之前的 32 × 32 分块示例非常相似。
In fact, NVIDIA’s optimized cuBLAS and cuDNN libraries use similar blocking strategies at the thread, warp, and block levels to achieve near-peak throughput. NVI-DIA even announced a Python-first API in early 2025 called cuTile that lets programmers describe these tile shapes in a more convenient Pythonic way. In fact, NVIDIA has developed a Tile-based intermediate representation (IR) called TileIR to support cuTile and facilitate automatic compilation and tuning.事实上,NVIDIA 经过优化的 cuBLAS 和 cuDNN 库在线程、线程束和线程块级别采用了类似的阻塞策略,以达到接近峰值的吞吐量。NVIDIA 甚至在 2025 年初发布了一个 Python 优先的 API,名为 cuTile,让程序员能以更方便的 Python 风格描述这些分块形状。事实上,NVIDIA 还开发了一种基于分块的中间表示(IR),名为 TileIR,用以支撑 cuTile 并便于自动编译与调优。
Other high-performance libraries encapsulate these tiling patterns as well. For instance, NVIDIA’s CUTLASS C++ and Python libraries expose templated tile iterators and profilers. And PyTorch-based compilers like TorchInductor (using the OpenAI Triton library) generate tiled kernels automatically when shapes and alignment permit. These libraries lower the barrier to using these tiling optimizations— and reduce the amount of boilerplate code.其他高性能库同样封装了这些分块模式。例如,NVIDIA 的 CUTLASS C++ 和 Python 库提供了模板化的分块迭代器与性能剖析器。而 TorchInductor(使用 OpenAI Triton 库)这类基于 PyTorch 的编译器,在形状与对齐条件允许时会自动生成分块内核。这些库降低了使用分块优化的门槛,也减少了样板代码的数量。
The key idea is that reusing data in registers/shared memory as much as possible before going back to DRAM is fundamental, and libraries encapsulate this. So whenever possible, leverage these highly optimized libraries (or refer to them) for performant tiling patterns.核心思想是:在回到 DRAM 之前尽可能多地在寄存器/共享内存中复用数据,这一点是根本性的,而库已经把它封装起来了。因此,只要有可能,就应利用这些高度优化的库(或参考它们)来获得高性能的分块模式。
For instance, if you use torch.mm in PyTorch or cublasSgemm in your code, under the covers it’s doing exactly this kind of tiling and memory coalescing. This is why our PyTorch example saw the same benefits automatically.例如,如果你在 PyTorch 中使用 torch.mm,或在代码中使用 cublasSgemm,它在底层做的正是这类分块与内存合并访问。这就是我们的 PyTorch 示例能自动获得相同收益的原因。
In practice, you would use high-performance libraries like cuBLAS and PyTorch’s torch.matmul, which already implement tiling and other optimizations in C++. In production code, directly using torch.mm or torch.matmul would produce the same benefits—and possibly more, thanks to highly tuned kernels.在实践中,你会使用 cuBLAS 和 PyTorch 的 torch.matmul 这类高性能库,它们已经在 C++ 中实现了分块和其他优化。在生产代码中,直接使用 torch.mm 或 torch.matmul 会产生相同的收益——得益于高度调优的内核,甚至可能更多。
As mentioned earlier in this section, when using a 32 × 32 tile, the threads in a warp will contend for the same shared-memory bank when they access the same column. Let’s explain this issue—as well as some optimizations—in the next section.正如本节前面所提到的,当使用 32 × 32 的分块时,线程束中的线程在访问同一列时会争用同一个共享内存存储体。我们将在下一节解释这个问题以及一些优化方法。
避免共享内存存储体冲突
Avoid Shared-Memory Bank Conflicts
On modern NVIDIA GPUs, including Blackwell, shared memory has 32 banks with a 4-byte bank width (i.e., addresses map mod 32). As such, a warp that strides by 128 B (32 floats × 4 B) maps all threads to the same bank. If multiple threads in a warp access the same bank, a bank conflict occurs. This forces the memory accesses to serialize, which negates the speed advantage of shared memory.在现代 NVIDIA GPU(包括 Blackwell)上,共享内存有 32 个存储体,存储体宽度为 4 字节(即地址按 mod 32 映射)。因此,以 128 B 为步长(32 个 float × 4 B)访问的线程束会把所有线程映射到同一个存储体。如果线程束中的多个线程访问同一个存储体,就会发生*存储体冲突*。这会迫使显存访问串行化,从而抵消共享内存的速度优势。
In code, bank conflicts often occur when threads access a shared-memory array with a stride that causes them to fall into the same bank. Figure 7-4 shows two examples of conflict-free memory bank accesses.在代码中,当线程以某种步长访问共享内存数组、致使它们落入同一个存储体时,往往就会发生存储体冲突。图 7-4 展示了两个无冲突存储体访问的示例。
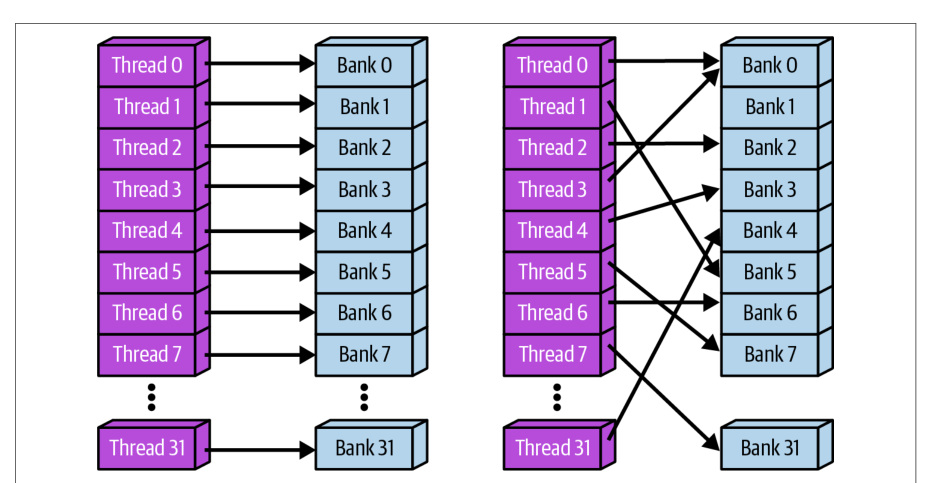
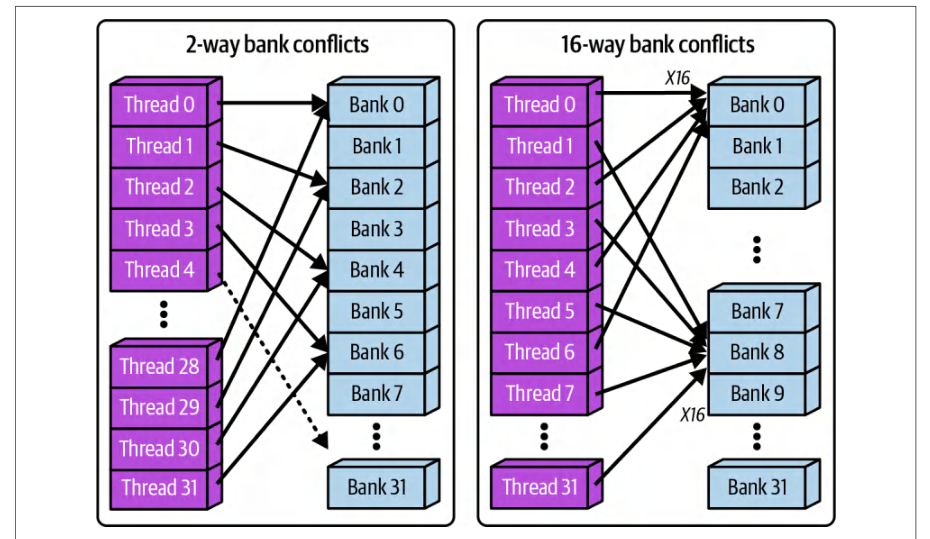
Here, there are no two threads accessing the same memory bank concurrently. This is ideal. Figure 7-5 shows examples of both a 2-way and 16-way bank conflict.这里没有任何两个线程同时访问同一个存储体。这是理想情况。图 7-5 展示了 2 路和 16 路存储体冲突的示例。
Here, multiple threads are accessing the same memory bank, which will cause conflicts and impact performance. A classic example of a bank conflict is a naive matrix transpose that uses a 32 × 32 shared memory tile. If 32 threads each read tile[i] [threadIdx.x] such that the same column index (threadIdx.x) is read across different rows (i), all 32 threads in the warp will each access memory addresses that lie in the same shared-memory bank, causing a 32-way bank conflict.这里,多个线程访问同一个存储体,这将导致冲突并影响性能。存储体冲突的一个经典例子是使用 32 × 32 共享内存分块的朴素矩阵转置。如果 32 个线程各自读取 tile[i] [threadIdx.x],使得在不同行(i)上读取相同的列索引(threadIdx.x),那么线程束中的全部 32 个线程各自访问的内存地址都落在同一个共享内存存储体中,从而造成 32 路存储体冲突。
Specifically, during a matrix transpose, you are reading down the same column of a row-major tile by holding the column index constant (threadIdx.x) and varying the row index (i) across threads. And because each row is 128 bytes apart in memory (32 columns × 4 bytes per column = 128 bytes), the accessed memory addresses will differ by exact multiples of 128 bytes.具体来说,在矩阵转置过程中,你保持列索引(threadIdx.x)不变、让行索引(i)在线程间变化,从而沿行主序分块的同一列向下读取。又因为内存中每一行相隔 128 字节(32 列 × 每列 4 字节 = 128 字节),所访问的内存地址之差恰好是 128 字节的整数倍。
Remember that the address-to-bank mapping repeats every 128 bytes because there are 32 banks with a 4-byte bank width (per access). Therefore, accessing memory addresses offset by 128 bytes will always land back in bank 0—hence, the full 32-way bank conflict.请记住,由于有 32 个存储体、每个存储体宽度为 4 字节(每次访问),地址到存储体的映射每 128 字节重复一次。因此,访问偏移 128 字节的内存地址总会落回存储体 0——这就是完整的 32 路存储体冲突。
Another common pitfall is using a stride equal to the number of memory banks, 32 in this case. For instance, if you stride your index by exactly 32 floats, each 4 bytes, then every thread’s address ends up differing by multiples of 128 bytes. In this case, all threads map to bank 0, as shown in this code:另一个常见的陷阱是使用等于存储体数量(此处为 32)的步长。例如,如果你的索引步长恰好是 32 个 float、每个 4 字节,那么每个线程的地址之差都是 128 字节的整数倍。在这种情况下,所有线程都映射到存储体 0,如下代码所示:
// 分配一个足够容纳多个线程束(warpCount)的共享缓冲区
__shared__ float arr[32 * warpCount];
// 每个线程从 arr[threadIdx.x * 32] 读取
float x = arr[threadIdx.x * 32];
// Allocate a shared buffer big enough for several warps (warpCount)
__shared__ float arr[32 * warpCount];
// Each thread reads from arr[threadIdx.x * 32]
float x = arr[threadIdx.x * 32];
Here, threadIdx.x * 32 in floats becomes (threadIdx.x * 32 * 4) bytes. Because 32 * 4 = 128, every thread’s memory-load address is threadIdx.x * 128 bytes. And threadIdx.x * 128 mod 128 = 0 for all threads. They all hit bank 0 simultaneously, creating a 32-way bank conflict.这里,以 float 计的 threadIdx.x * 32 变成 (threadIdx.x * 32 * 4) 字节。因为 32 * 4 = 128,每个线程的内存加载地址都是 threadIdx.x * 128 字节。而对所有线程来说,threadIdx.x * 128 mod 128 = 0。它们同时命中存储体 0,造成 32 路存储体冲突。
When this happens, the hardware must serialize what should have been 32 parallel reads into a sequence of single-bank accesses. In Nsight Compute (Shared Memory section), you will see an increased bank conflict count and lower shared-memory efficiency. At the same time, the shared-memory throughput is a fraction of its expected bandwidth. In Nsight Systems, you’ll see warps are waiting on long bank-conflict stalls rather than doing useful work.出现这种情况时,硬件必须把本应是 32 路并行的读取串行化为一系列单存储体访问。在 Nsight Compute 的 Shared Memory 部分,你会看到存储体冲突计数上升、共享内存效率下降。与此同时,共享内存吞吐量只有其预期带宽的一小部分。在 Nsight Systems 中,你会看到线程束在漫长的存储体冲突停顿上等待,而不是在做有效的工作。
Bank conflicts force what should be parallel on-chip shared-memory accesses to replay one by one, wiping out any speedup you expected from buffering and often yielding disappointing, lower-than-anticipated performance. If your kernel isn’t accelerating as it should, bank conflicts are a likely culprit.存储体冲突迫使本应并行的片上共享内存访问逐个重放,抹掉了你期望从缓冲中获得的所有加速,往往带来令人失望的、低于预期的性能。如果你的内核没有按预期加速,存储体冲突很可能就是元凶。
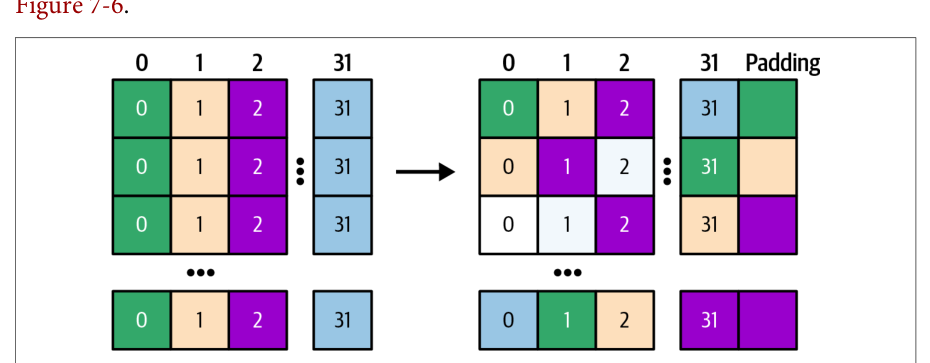
The solution is to adjust data layouts in shared memory to avoid conflicts. A common technique is padding shared arrays so that each row, or each memory-access pattern, maps to different banks. For instance, if you have a 32 × 32 shared tile, you can declare it as [32][33] by adding one extra padding column so that each row now occupies 33 floats. This extra 1-element offset means that when thread k of a warp accesses tile[i][k], successive rows start at addresses that shift across shared-memory banks. This keeps all threads from hitting the same bank, as shown in解决方案是调整共享内存中的数据布局以避免冲突。一种常用技术是对共享数组进行*填充*,使每一行、或每一种显存访问模式都映射到不同的存储体。例如,如果你有一个 32 × 32 的共享瓦片,可以额外增加一列填充,将其声明为 [32][33],这样每一行现在占用 33 个 float。这个多出 1 个元素的偏移意味着,当线程束中的线程 k 访问 tile[i][k] 时,相邻行的起始地址会在共享内存各存储体之间错开。这使所有线程不会命中同一个存储体,如图所示
By changing the stride to 33, no two threads in a warp will contend for the same bank when accessing a given column. This eliminates what would have been a 32-way bank conflict.通过将步长改为 33,线程束中任意两个线程在访问给定列时都不会争用同一个存储体。这消除了原本会出现的 32 路存储体冲突。
The padding adds a negligible overhead, ~3% more memory for a 32-wide tile, but it completely eliminates the conflicts, which greatly improves performance. And remember that Blackwell has > 200 KB shared memory per SM. A 3% memory overhead is only 1 KB for a 32 × 32 tile. This is worth the performance increase.填充带来的开销可以忽略不计——对于 32 宽的瓦片,内存增加约 3%——但它完全消除了冲突,从而大幅提升性能。还要记住,Blackwell 每个 SM 拥有超过 200 KB 的共享内存。3% 的显存开销对于 32 × 32 的瓦片来说只有 1 KB。这点代价换来性能提升是值得的。
Let’s show an example of removing shared-memory bank conflicts for a simple transpose kernel. In this example, each thread accesses shared memory addresses that fall into the same shared-memory bank as other threads. This causes the memory access to serialize, prevents parallelism, and shows slow performance. Here is the native implementation of the transpose kernel that incurs bank conflicts.下面展示一个为简单转置内核消除共享内存存储体冲突的例子。在这个例子中,每个线程访问的共享内存地址与其他线程落入同一个共享内存存储体。这导致显存访问串行化、无法并行,表现出很慢的性能。以下是会产生存储体冲突的转置内核的原始实现。
Before example (C++): naive transpose with bank conflicts:修改前示例(C++):存在存储体冲突的朴素转置:
#include <cuda_runtime.h>
#define TILE_DIM 32
__global__ void transposeNaive(const float *idata, float *odata, int width) {
    __shared__ float tile[TILE_DIM][TILE_DIM];
    int x = blockIdx.x * TILE_DIM + threadIdx.x;
    int y = blockIdx.y * TILE_DIM + threadIdx.y;
    // 一个线程束中的线程写入一行
    tile[threadIdx.y][threadIdx.x] = idata[y * width + x];
    __syncthreads();
    // 使用转置后的索引从共享内存读取
    // 这是一个典型情形:一个线程束中的所有线程
    // 访问同一个存储体,从而引发存储体冲突
    // 从共享内存按转置方式读取并写出
    odata[x * width + y] = tile[threadIdx.x][threadIdx.y];
}

int main() {
    const int N = 1024;
    size_t size = N * N * sizeof(float);
    float *h_idata = (float*)malloc(size);
    float *h_odata = (float*)malloc(size);
    // 初始化输入 h_idata...
    float *d_idata, *d_odata;
    cudaMalloc(&d_idata, size);
    cudaMalloc(&d_odata, size);
    cudaMemcpy(d_idata, h_idata, size, cudaMemcpyHostToDevice);
    dim3 block(TILE_DIM, TILE_DIM);
    dim3 grid(N / TILE_DIM, N / TILE_DIM);
    transposeNaive<<<grid, block>>>(d_idata, d_odata, N);
    cudaDeviceSynchronize();
    cudaFree(d_idata);
    cudaFree(d_odata);
    free(h_idata);
    free(h_odata);
    return 0;
}
#include <cuda_runtime.h>
#define TILE_DIM 32
__global__ void transposeNaive(const float *idata, float *odata, int width) {
    __shared__ float tile[TILE_DIM][TILE_DIM];
    int x = blockIdx.x * TILE_DIM + threadIdx.x;
    int y = blockIdx.y * TILE_DIM + threadIdx.y;
    // threads in a warp write a row
    tile[threadIdx.y][threadIdx.x] = idata[y * width + x];
    __syncthreads();
    // Read from shared memory with transposed indices
    // This is a classic case of all threads in a warp
    // hitting the same bank causing a bank conflict
    // Read transposed from shared memory and write out
    odata[x * width + y] = tile[threadIdx.x][threadIdx.y];
}

int main() {
    const int N = 1024;
    size_t size = N * N * sizeof(float);
    float *h_idata = (float*)malloc(size);
    float *h_odata = (float*)malloc(size);
    // Initialize input h_idata...
    float *d_idata, *d_odata;
    cudaMalloc(&d_idata, size);
    cudaMalloc(&d_odata, size);
    cudaMemcpy(d_idata, h_idata, size, cudaMemcpyHostToDevice);
    dim3 block(TILE_DIM, TILE_DIM);
    dim3 grid(N / TILE_DIM, N / TILE_DIM);
    transposeNaive<<<grid, block>>>(d_idata, d_odata, N);
    cudaDeviceSynchronize();
    cudaFree(d_idata);
    cudaFree(d_odata);
    free(h_idata);
    free(h_odata);
    return 0;
}
In this kernel, the tile write into shared memory is row-major (tile[ty][tx]) and therefore coalesced such that each warp writes a full row of 32 floats to shared memory in a contiguous manner. (Note: Writing the tile to shared memory with column-major tile[tx][ty] would make the warp stride by 128 bytes and trigger a 32-way bank conflict.) In contrast, the tile read is transposed since each thread reads a value where threadIdx.y is the row index and threadIdx.x is the column index.在这个内核中,写入共享内存的 tile 是行主序的(tile[ty][tx]),因此是合并的,每个线程束以连续方式把一整行 32 个 float 写入共享内存。(注意:若以列主序 tile[tx][ty] 写入瓦片,线程束的步长将变为 128 字节,并触发 32 路存储体冲突。)相比之下,tile 的读取是转置的,因为每个线程读取的值以 threadIdx.y 为行索引、threadIdx.x 为列索引。
As such, for a given warp, fixed threadIdx.y across threads 0–31, all threads access tile[constant_row][varying_col], meaning the same row index is used across different columns. This means all 32 addresses are in the same row of the tile array, which occupies a single memory bank segment and causes a 32-way bank conflict. As a result, those reads are serialized by a factor of 32.因此,对于给定的线程束,线程 0–31 的 threadIdx.y 固定不变,所有线程都访问 tile[constant_row][varying_col],也就是说在不同列上使用相同的行索引。这意味着全部 32 个地址都位于 tile 数组的同一行,而该行只占用一个存储体段,从而造成 32 路存储体冲突。结果,这些读取被串行化了 32 倍。
In this case, 32 threads attempt to read from 32 different addresses, all in bank 0. This results in heavy serialization of memory accesses and poor performance. Let’s apply padding to remove the conflicts.在这种情况下,32 个线程尝试从 32 个不同的地址读取,而这些地址全部位于存储体 0。这会导致显存访问严重串行化,性能很差。下面我们通过填充(padding)来消除这些冲突。
*After example (C++): padded transpose (avoiding bank conflicts). *Here, we add a small padding, an extra unused column, so that each row of shared memory starts at a different bank modulo. This way, the bank-index collisions are eliminated by the offset:*修改后的示例(C++):带填充的转置(避免存储体冲突)。*这里我们添加一个小的填充,即额外的一列未使用列,使共享内存的每一行都从不同的存储体模数位置开始。这样,存储体索引冲突就被这个偏移消除了:
#include <cuda_runtime.h>
#define TILE_DIM 32
#define PAD 1  // padding columns to avoid bank conflicts
__global__ void transposePadded(const float *idata, float *odata, int width) {
    // 每行包含 TILE_DIM+1 个元素,以改变存储体映射
    __shared__ float tile[TILE_DIM][TILE_DIM + PAD];
    int x = blockIdx.x * TILE_DIM + threadIdx.x;
    int y = blockIdx.y * TILE_DIM + threadIdx.y;
    tile[threadIdx.y][threadIdx.x] = idata[y * width + x];
    // 稍后我们会将其优化为使用线程块作用域的
    // 协作组屏障
    __syncthreads();
    odata[x * width + y] = tile[threadIdx.x][threadIdx.y];
}
#include <cuda_runtime.h>
#define TILE_DIM 32
#define PAD 1  // padding columns to avoid bank conflicts
__global__ void transposePadded(const float *idata, float *odata, int width) {
    // Each row is TILE_DIM+1 elements to shift bank mapping
    __shared__ float tile[TILE_DIM][TILE_DIM + PAD];
    int x = blockIdx.x * TILE_DIM + threadIdx.x;
    int y = blockIdx.y * TILE_DIM + threadIdx.y;
    tile[threadIdx.y][threadIdx.x] = idata[y * width + x];
    // We will optimize this later to use a thread-block-scoped
    // cooperative-groups barrier
    __syncthreads();
    odata[x * width + y] = tile[threadIdx.x][threadIdx.y];
}
(The host code and setup are the same as in the naive version and omitted for brevity.)(主机端代码与设置同朴素版本,为简洁起见省略。)
| Metric指标 | Before (no padding)之前(无填充) | After (padding)之后(填充) |
|---|---|---|
| Shared-memory load bank conflicts共享内存加载存储体冲突 | 4.8 million480 万 | 00 |
| Shared-memory utilization (percentage of peak)共享内存利用率(占峰值的百分比) | 52%52% | 100%100% |
| Warp stall fraction (memory)线程束停顿比例(内存) | 38%38% | 0.5%0.5% |
| Kernel execution time (ms)内核执行时间(ms) | 4 ms4 ms | 1.3 ms (3× improvement)1.3 ms(提升 3 倍) |
Padding each shared-memory row with an extra element makes each row 33 floats long. Padding by 1 changes the indexing math so that tile[row][col] addresses differ in the lower 5 bits for each thread, rather than all threads sharing the same 5-bit bank index. This ensures each thread index maps to a different bank.为共享内存的每一行额外填充一个元素,可使每行长度为 33 个 float。填充 1 个元素改变了索引计算方式,使得 tile[row][col] 的地址在每个线程的低 5 位上各不相同,而不是所有线程共享相同的 5 位存储体索引。这确保每个线程索引都映射到不同的存储体。
In the padded kernel, when a warp reads tile[threadIdx.y][threadIdx.x], the addresses for threads 0–31 span multiple banks rather than all hitting bank 0. Now that each thread in the warp accesses distinct banks on reads, bank conflicts are eliminated entirely, as shown in Table 7-5.在填充后的内核中,当一个线程束读取 tile[threadIdx.y][threadIdx.x] 时,线程 0–31 的地址会跨越多个存储体,而不是全部命中存储体 0。由于线程束中的每个线程在读取时访问的都是不同的存储体,存储体冲突被完全消除,如表 7-5 所示。
The Nsight Compute metrics in Table 7-5 confirm the impact: shared-memory load bank conflicts dropped to 0. Shared memory throughput, according to Nsight Compute, rose from 52% to 100% after eliminating conflicts. The warp stall fraction, the percentage of cycles warps spend stalled on shared-memory reads, dropped from ~38% to near 0%.表 7-5 中的 Nsight Compute 指标证实了这一影响:共享内存加载存储体冲突降至 0。根据 Nsight Compute 的统计,消除冲突后共享内存吞吐量从 52% 提升到 100%。线程束停顿比例(warp stall fraction,即线程束因共享内存读取而停顿的周期占比)从约 38% 降至接近 0%。
Here, we have successfully eliminated bank conflicts and unlocked the full performance of the on-chip shared memory. This change improved the kernel’s execution time by about 3× from 4 ms to 1.3 ms since shared-memory accesses went from serialized to fully parallel.至此,我们成功消除了存储体冲突,释放了片上共享内存的全部性能。由于共享内存访问从串行变为完全并行,这一改动使内核执行时间从 4 ms 缩短到 1.3 ms,提升了约 3 倍。
This restores full parallelism for the shared-memory accesses. The cost of padding, 1 extra float per 32, is trivial (~3% memory overhead) compared to the performance gain.这恢复了共享内存访问的完全并行性。填充的代价是每 32 个元素多 1 个 float,与性能收益相比微不足道(约 3% 的显存开销)。
An effective alternative to padding is swizzling. Swizzling is a compile-time index transformation that “scrambles” the linear index used for shared memory so that sequential threads map to different banks. For example, one can XOR the index with a bit mask or use a modulo offset to achieve a conflict-free pattern.填充的一种有效替代方案是*索引重排*(swizzling)。索引重排是一种编译期索引变换,它“打乱”用于共享内存的线性索引,使连续的线程映射到不同的存储体。例如,可以将索引与一个位掩码进行 XOR,或使用取模偏移,从而实现无冲突的访问模式。
Swizzling avoids the slight memory overhead of padding while still ensuring perfect bank parallelism. Padding is simpler to implement, but swizzling can achieve the same goal with zero memory overhead—and it’s fun to say!索引重排避免了填充带来的轻微显存开销,同时仍能确保完美的存储体并行性。填充实现起来更简单,但索引重排能以零显存开销达成同样的目标——而且说起来还挺有趣!
In summary, when using shared memory, it’s important that threads in a warp access different memory banks in parallel rather than queueing up on the same bank. Techniques like padding and swizzling improve shared-memory load/store efficiency, yielding higher throughput and better performance whenever shared memory is used.总之,使用共享内存时,重要的是让线程束中的线程并行访问不同的存储体,而不是在同一存储体上排队。填充和索引重排等技术可提升共享内存的加载/存储效率,从而在任何使用共享内存的场景下带来更高的吞吐量和更好的性能。
Next, let’s explore a technique to avoid shared memory altogether and communicate directly between threads.接下来,让我们探索一种完全避开共享内存、直接在各个线程之间通信的技术。
线程束 shuffle 内建函数:避开共享内存与显式同步
Warp Shuffle Intrinsics: Avoid Shared Memory and Explicit Synchronization
The preceding avoiding-bank-conflicts technique assumes that we use shared memory for communication between threads. But what if we could avoid shared memory altogether—and its bank conflict issues?前面避免存储体冲突的技术假设我们使用共享内存进行线程间通信。但如果我们能完全避开共享内存——以及它的存储体冲突问题呢?
NVIDIA GPUs support warp-synchronous primitives that allow threads in the same warp to exchange data through registers instead of shared memory. In fact, these primitives work only within a single warp such that threads exchange data with their 31 siblings. So no memory banks are involved for this intrawarp communication— and therefore no bank conflicts are possible.NVIDIA GPU 支持线程束同步原语(warp-synchronous primitives),允许同一线程束内的线程通过寄存器而非共享内存交换数据。事实上,这些原语仅在一个线程束内工作,线程与其 31 个同伴交换数据。因此这种线程束内通信不涉及任何存储体——也就不可能发生存储体冲突。
The most common are the __shfl_sync intrinsics (shuffle). __shfl_sync lets you broadcast a value from one thread to all other threads in a warp. You can also perform warp-level reductions without ever writing to shared memory. And remember that these intrinsics let threads exchange values through registers (instead of shared memory), which completely eliminates shared-memory bank conflicts.最常见的是 __shfl_sync 内建函数(shuffle)。__shfl_sync 允许你将一个线程的值广播到线程束中的所有其他线程。你也可以在不写入共享内存的情况下执行线程束级归约。请记住,这些内建函数让线程通过寄存器(而非共享内存)交换值,从而彻底消除了共享内存存储体冲突。
Imagine you need to sum the 32 per-thread partial results within a single warp. The naive shared-memory approach would have each thread write its value into a shared array, call a synchronization barrier, and then read and accumulate all 32 entries. This risks bank conflicts and adds additional synchronization overhead.设想你需要在单个线程束内对 32 个每线程部分结果求和。朴素的共享内存做法是让每个线程将其值写入共享数组,调用同步屏障,然后读取并累加全部 32 个条目。这会带来存储体冲突风险,并增加额外的同步开销。
With __shfl_sync, you can do a tree-style reduction entirely in registers. For example, let’s use a convenience variant called __shfl_down_sync to perform a butterfly-style reduction such that each thread reads the value held by another thread that is offset a number of lanes away, as shown here:使用 __shfl_sync,你可以完全在寄存器中完成树形归约。例如,我们使用一个名为 __shfl_down_sync 的便捷变体来执行蝶形归约,使每个线程读取相隔 offset 个 lane 的另一个线程所持有的值,如下所示:
unsigned mask = __activemask();
float val = threadVal;  // 每个线程的部分和
// 执行蝶形归约:与间隔逐渐增大的 lane 交换数值
for (int offset = 16; offset > 0; offset >>= 1) {
    float other = __shfl_down_sync(mask, val, offset);
    val += other;
}
// 循环结束后,lane 0 保存该线程束的总和
unsigned mask = __activemask();
float val = threadVal;  // each thread’s partial sum
// Perform butterfly reduction: exchange values with increasingly distant lanes
for (int offset = 16; offset > 0; offset >>= 1) {
    float other = __shfl_down_sync(mask, val, offset);
    val += other;
}
// After the loop, lane 0 holds the warp’s total sum
Here, each __shfl_down_sync directly reads another lane’s register, halving the active threads each step, until lane 0 accumulates the full sum. Because all communication stays in registers, there’s no shared-memory traffic and thus zero bank conflicts or extra synchronizations.在这里,每次 __shfl_down_sync 直接读取另一个 lane 的寄存器,每一步将活跃线程数减半,直到 lane 0 累加出完整的总和。由于所有通信都留在寄存器中,因此没有共享内存流量,也就没有存储体冲突或额外同步。
In short, __shfl_sync and its variants perform operations entirely within the warp’s execution lanes. This avoids bank conflicts because no shared memory is used. And it’s often faster since it uses registers and cuts down on the number of shared-memory instructions.简而言之,__shfl_sync 及其变体完全在线程束的执行 lane 内执行操作。由于不使用共享内存,这避免了存储体冲突。而且它通常更快,因为它使用寄存器并减少了共享内存指令的数量。
Many high-performance warp-level reductions bypass shared memory entirely by using shuffle intrinsics, which exchange values directly through registers in just a few instructions and incur no bank conflicts. CUDA’s Cooperative Groups API builds on these primitives. This API provides calls like thread_group.shuffle() to simplify intrawarp communication. Helper intrinsics like __reduce_sync() ultimately compile down to these shuffle patterns for intra-warp data exchange on modern NVIDIA GPUs.许多高性能的线程束级归约完全绕过共享内存,改用 shuffle 内建函数,后者仅用几条指令就通过寄存器直接交换值,且不会产生存储体冲突。CUDA 的协作组(Cooperative Groups)API 建立在这些原语之上。该 API 提供 thread_group.shuffle() 之类的调用,以简化线程束内通信。像 __reduce_sync() 这样的辅助内建函数,在现代 NVIDIA GPU 上最终会编译为这些 shuffle 模式,用于线程束内数据交换。
Remember, however, that shuffles are limited to the 32 threads within a single warp. Whenever you need to pass data across warps, you must still fall back on shared or global memory with proper synchronization.但请记住,shuffle 仅限于单个线程束内的 32 个线程。每当需要跨线程束传递数据时,你仍必须回退到共享内存或全局内存,并配合适当的同步。
In Chapter 10, we’ll explore interwarp patterns like cooperative group (CG) synchronization primitives, multiwarp shuffle methods, and thread block clusters (CTA clusters). All of these ultimately use the same hardware intrinsics under the hood. Mastering both intrawarp and interwarp techniques is essential because memory-related bottlenecks remain one of the most common causes of GPU performance issues.在第 10 章中,我们将探讨线程束间模式,例如协作组(CG)同步原语、多线程束 shuffle 方法以及线程块集群(CTA 集群)。所有这些在底层最终都使用相同的硬件内建函数。掌握线程束内和线程束间技术至关重要,因为与内存相关的瓶颈仍然是 GPU 性能问题最常见的原因之一。
只读数据缓存
Read-Only Data Caches
When all threads read the same values or a thread rereads data that does not change, failing to use the GPU’s caching mechanisms can bottleneck performance. For example, consider a large lookup table such as an embedding vector in a natural language processing (NLP) model that is read-only during inference. Many threads might need to access this vector in parallel. A naive implementation might fetch from global memory each time, even though the data is immutable and could be cached on-chip.当所有线程读取相同的值,或某个线程反复读取不会变化的数据时,若未能利用 GPU 的缓存机制,就可能成为性能瓶颈。例如,考虑一张大型查找表,比如自然语言处理(NLP)模型中的嵌入向量,它在推理期间是只读的。许多线程可能需要并行访问该向量。朴素实现可能每次都从全局内存取数,尽管该数据不可变、本可以缓存在片上。
Note that the read-only cache we refer to here is different from the 64 KB constant memory cache discussed previously in the GPU memory hierarchy section. It’s a large cache for immutable data. The constant memory cache, on the other hand, is too small for big arrays. Modern architectures rely on the larger L1/read-only cache for these types of embedding-vector lookups—rather than trying to squeeze this data into the small 64 KB constant memory cache.注意,这里所说的只读缓存(read-only cache)不同于前面在 GPU 显存层次结构一节中讨论的 64 KB 常量内存缓存(constant memory cache)。它是面向不可变数据的大容量缓存。而常量内存缓存对于大型数组来说太小了。现代架构依赖更大的 L1/只读缓存来处理这类嵌入向量查找,而不是试图把这些数据塞进 64 KB 的常量内存缓存中。
On modern GPUs, global memory loads are automatically cached in L2 and often L1. You can use const __restrict__ qualified pointers to define your function arguments as non-coherent and read-mostly (versus read-only). For read-only data, the compiler may route loads through this read-only path when it can prove immutabil-ity, nonaliasing, and safety. This lets the compiler/hardware route unchanging data through the read-only L1 cache, which has lower latency—especially for broadcast accesses—and doesn’t evict other cached data.在现代 GPU 上,全局内存加载会自动缓存在 L2 中,通常也会缓存在 L1 中。你可以使用带 const __restrict__ 限定的指针,把函数参数声明为非一致(non-coherent)且以读为主(read-mostly,相对于只读)。对于只读数据,当编译器能够证明其不可变性、无别名(non-aliasing)和安全性时,就可能让加载走这条只读路径。这使得编译器/硬件可以把不变的数据经由只读 L1 缓存,从而获得更低的时延——尤其是对广播访问——并且不会驱逐其他已缓存的数据。
A common performance pitfall is forgetting to tell the compiler that a buffer is truly read-only, which means it won’t use the read-only (non-coherent) data path and won’t route those loads through the specialized read-only cache. Instead, every access becomes a plain global memory load, resulting in redundant DRAM traffic and spu-rious cache misses.一个常见的性能陷阱是忘记告诉编译器某个缓冲区确实是只读的,这意味着编译器不会使用只读(非一致)数据路径,也不会让这些加载走专用的只读缓存。于是每次访问都变成普通的全局内存加载,导致冗余的 DRAM 流量和虚假的缓存未命中。
When you profile such a kernel, you’ll spot the same addresses fetched repeatedly from off-chip memory, see no __ldg() operations in the instruction stream, observe a surprisingly low L2 hit rate for that array, and measure elevated DRAM throughput reminiscent of an uncached workload.当你对这样的内核做性能剖析时,会发现相同的地址被反复从片外内存取回,在指令流中看不到任何 __ldg() 操作,观察到该数组的 L2 命中率低得惊人,并测得偏高的 DRAM 吞吐量,令人联想到未使用缓存的工作负载。
The solution is to leverage the read-only path by marking data as const __restrict__ , or by explicitly using the __ldg() intrinsic to load it. This tells the hardware that the data will not be modified, allowing it to be cached in the specialized read-only cache, which sits alongside L1 and has lower latency for broadcast loads.解决方案是利用只读路径:把数据标记为 const __restrict__,或显式使用 __ldg() 内建函数来加载它。这告诉硬件该数据不会被修改,从而允许它缓存在专用的只读缓存中;该缓存与 L1 并列,对广播加载具有更低的时延。
When a warp issues a constant-cache load (__constant__ or uniform __ldg() in older GPUs), the hardware can service all 32 lanes with a single transaction if they hit the same address. By broadcasting that value to every thread, it uses only one cycle instead of doing 32 separate loads. This warp-wide broadcast reduces both latency and memory bandwidth usage for uniform data like lookup tables, coefficients, etc. This lets you fetch a shared constant, for free essentially, once per warp rather than 32 times per warp (1 per thread).当线程束发起一次常量缓存加载时(__constant__,或在较老 GPU 上的一致 __ldg()),如果全部 32 个 lane 命中同一地址,硬件可以用单次事务服务全部 32 个 lane。通过把该值广播给每个线程,它只用一个周期,而不是执行 32 次独立的加载。对于查找表、系数等一致数据,这种线程束范围的广播同时降低了时延和显存带宽占用。这让你基本上可以零成本地每个线程束只取一次共享常量,而不是每个线程束取 32 次(每线程一次)。
As an example of caching benefits using the standard read-only cache, suppose we have a kernel that, for each thread, looks up a value from a table of size T = 1,024 and writes it to an output. This simulates an embedding-lookup pattern and is shown here in both CUDA C++ and PyTorch:作为使用标准只读缓存获得缓存收益的一个例子,假设有一个内核,其中每个线程从大小为 T = 1,024 的表中查找一个值并写入输出。这模拟了嵌入查找的模式,下面分别用 CUDA C++ 和 PyTorch 给出:
#include <cuda_runtime.h>
#define T 1024
__global__ void naiveLookup(const float* table, float* out, int N) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // 此处未使用 __ldg,每次访问都直接
        // 访问全局内存,不经过只读缓存
        int t = idx % T;
        out[idx] = table[t];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_table = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_table, T * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < T; ++i) h_table[i] = float(i);
#include <cuda_runtime.h>
#define T 1024
__global__ void naiveLookup(const float* table, float* out, int N) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        // __ldg not used here, each access goes to
        // global memory without using read-only cache
        int t = idx % T;
        out[idx] = table[t];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_table = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_table, T * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < T; ++i) h_table[i] = float(i);
    float *d_table, *d_out;
    cudaMalloc(&d_table, T * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_table, h_table, T * sizeof(float),
        cudaMemcpyHostToDevice);
    dim3 block(256), grid((N + 255) / 256);
    naiveLookup<<<grid, block>>>(d_table, d_out, N);
    cudaDeviceSynchronize();
    cudaMemcpy(h_out, d_out, N * sizeof(float), cudaMemcpyDeviceToHost);
    cudaFree(d_table);
    cudaFree(d_out);
    cudaFreeHost(h_table);
    cudaFreeHost(h_out);
    return 0;
}
Here is a rough PyTorch equivalent to the naive version shown in CUDA C++:下面是 CUDA C++ 中所示朴素版本的大致 PyTorch 等价实现:
import torch
def vectorized_lookup(table, N):
    flat = table.view(-1)
    T = flat.size(0)
    # 在 GPU 上构建索引 [0,1,2,...,N-1] % T
    idx = torch.arange(N, device=flat.device) % T
    # 一个 gather 内核并行完成全部 N 次加载
    return flat.index_select(0, idx)
# 用法
T = 1024
N = 1 << 20
table = torch.arange(T, dtype=torch.float32,
                     device='cuda')
out = vectorized_lookup(table, N)
import torch
def vectorized_lookup(table, N):
    flat = table.view(-1)
    T = flat.size(0)
    # build indices [0,1,2,...,N-1] % T all on GPU
    idx = torch.arange(N, device=flat.device) % T
    # one gather kernel does all N loads in parallel
    return flat.index_select(0, idx)
# Usage
T = 1024
N = 1 << 20
table = torch.arange(T, dtype=torch.float32,
                     device='cuda')
out = vectorized_lookup(table, N)
In these naive versions, each lookup likely hits in L2 after the first use (since L2 will cache it), but there is no use of the specialized read-only cache. The hardware may still treat it as normal global data, which could evict other useful data or not take full advantage of broadcast caching if multiple threads read the same table[t] in a warp.在这些朴素版本中,首次使用之后每次查找很可能都会命中 L2(因为 L2 会缓存它),但并没有用到专用的只读缓存。硬件仍可能将其视为普通的全局数据,这可能驱逐其他有用数据,或者在同一个线程束内多个线程读取相同的 table[t] 时无法充分利用广播缓存。
Now we optimize the kernel by marking the table as const __restrict__. This will hint to the hardware that it should use the read-only cache path, which is shown here:现在我们通过将表标记为 const __restrict__ 来优化内核。这会向硬件提示应使用只读缓存路径,如下所示:
#include <cuda_runtime.h>
#define T 1024
__global__ void lookup(const float* __restrict__ table,
        float* out, int N) {
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        int t = idx % T;
        // 编译器可将其转换为从
        // 只读缓存加载,从而加快加载速度
        out[idx] = table[t];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_table = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_table, T * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < T; ++i) h_table[i] = float(i);
    float *d_table, *d_out;
    cudaMalloc(&d_table, T * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_table, h_table, T * sizeof(float), cudaMemcpyHostToDevice);
    dim3 block(256), grid((N + 255) / 256);
    lookup<<<grid, block>>>(d_table, d_out, N);
    cudaDeviceSynchronize();
    cudaMemcpy(h_out, d_out, N * sizeof(float), cudaMemcpyDeviceToHost);
    cudaFree(d_table);
    cudaFree(d_out);
    cudaFreeHost(h_table);
    cudaFreeHost(h_out);
    return 0;
}
    int idx = blockIdx.x * blockDim.x + threadIdx.x;
    if (idx < N) {
        int t = idx % T;
        // Compiler can turn this into a load from the
        // read-only cache for faster loads
        out[idx] = table[t];
    }
}
int main() {
    const int N = 1 << 20;
    float* h_table = nullptr;
    float* h_out = nullptr;
    cudaMallocHost(&h_table, T * sizeof(float));
    cudaMallocHost(&h_out, N * sizeof(float));
    for (int i = 0; i < T; ++i) h_table[i] = float(i);
    float *d_table, *d_out;
    cudaMalloc(&d_table, T * sizeof(float));
    cudaMalloc(&d_out, N * sizeof(float));
    cudaMemcpy(d_table, h_table, T * sizeof(float), cudaMemcpyHostToDevice);
    dim3 block(256), grid((N + 255) / 256);
    lookup<<<grid, block>>>(d_table, d_out, N);
    cudaDeviceSynchronize();
    cudaMemcpy(h_out, d_out, N * sizeof(float), cudaMemcpyDeviceToHost);
    cudaFree(d_table);
    cudaFree(d_out);
    cudaFreeHost(h_table);
    cudaFreeHost(h_out);
    return 0;
}
In short, marking the table const __restrict__ tells the compiler that these values are immutable and not aliased, which permits the use of the read-only data path when safe to do so. This increases cache hit rate and reduces off-chip traffic. Table 7-6 shows Nsight Compute measurements before and after this change.简而言之,将表标记为 const __restrict__ 是告诉编译器这些值不可变且不存在别名,从而在安全的情况下允许使用只读数据路径。这提高了缓存命中率并减少了片外流量。表 7-6 展示了这一改动前后的 Nsight Compute 测量结果。
| Metric指标 | Before (no __restrict__)改动前(未使用 __restrict__) | After (__restrict__ used)改动后(使用 __restrict__) |
|---|---|---|
| Global Memory Load Efficiency全局内存加载效率 | 52%52% | 97%97% |
| DRAM throughput (GB/s)DRAM 吞吐量(GB/s) | 600 GB/s600 GB/s | 200 GB/s200 GB/s |
| L2 read throughput (GB/s)L2 读取吞吐量(GB/s) | 1,500 GB/s1,500 GB/s | 1,800 GB/s1,800 GB/s |
| SM Active %SM 活跃占比 % | 45%45% | 93%93% |
| Kernel execution time (ms)内核执行时间(ms) | 2.5 ms2.5 ms | 1.0 ms1.0 ms |
After adding const __restrict__, the kernel time improves by about 2.5×, from 2.5 milliseconds to 1.0 millisecond, because warps spend less time stalled on DRAM. SM Active % rises from 45% to 93%, indicating that nearly every cycle has active work rather than idle memory waits.添加 const __restrict__ 后,内核时间提升约 2.5 倍,从 2.5 毫秒降至 1.0 毫秒,因为线程束因 DRAM 而停顿的时间减少了。SM Active % 从 45% 上升到 93%,表明几乎每个周期都有活跃工作,而不是空闲等待内存。
DRAM throughput falls from 600 GB/s to 200 GB/s, while L2 read throughput increases from 1,500 GB/s to 1,800 GB/s as more requests are satisfied in cache. Global Memory Load Efficiency increases from 52% to 97%, confirming that most fetched cache lines carry useful data.DRAM 吞吐量从 600 GB/s 降至 200 GB/s,而随着更多请求在缓存中得到满足,L2 读吞吐量从 1,500 GB/s 增至 1,800 GB/s。全局内存加载效率从 52% 提升到 97%,证实大多数取回的缓存行都携带了有用数据。
Because more traffic is served by on-chip caches rather than traveling to DRAM, the compute units remain fed and arithmetic intensity increases. This balance is what moves a kernel from the memory-bound regime toward the compute-bound regime. Texture objects and surface objects are also available for read-only and read/write access patterns with strong two-dimensional or three-dimensional locality. By binding an array to a cudaTextureObject_t and using tex1Dfetch or tex2D fetches, the hardware can exploit spatial locality with high cache hit rates and features such as wrapping and interpolation. Surface objects allow writes on similar access patterns.由于更多流量由片上缓存提供,而无需传输到 DRAM,计算单元得以持续获得数据供给,算术强度随之提高。正是这种平衡使内核从显存受限状态转向计算受限状态。纹理对象(texture object)和表面对象(surface object)同样可用于具有强二维或三维局部性的只读与读写访问模式。通过将数组绑定到 cudaTextureObject_t 并使用 tex1Dfetch 或 tex2D 取数,硬件能够以高缓存命中率利用空间局部性,并支持环绕与插值等特性。表面对象则允许在类似的访问模式下进行写入。
In summary, mark read-only data as const __restrict__ to tap into the low-latency read-only cache, cutting DRAM traffic and lifting SM activity. Consider texture or surface memory whenever your access pattern has 2D/3D locality that a regular cache might not handle optimally. Together, these techniques collapse memory stalls, boost cache utilization, and unlock substantial performance gains for memory-bound kernels.总之,将只读数据标记为 const __restrict__,即可利用低时延的只读缓存,减少 DRAM 流量并提升 SM 活跃度。当你的访问模式具有常规缓存可能无法最优处理的二维/三维局部性时,应考虑使用纹理内存或表面内存。这些技术结合起来可消除内存停顿、提高缓存利用率,并为显存受限的内核释放可观的性能收益。
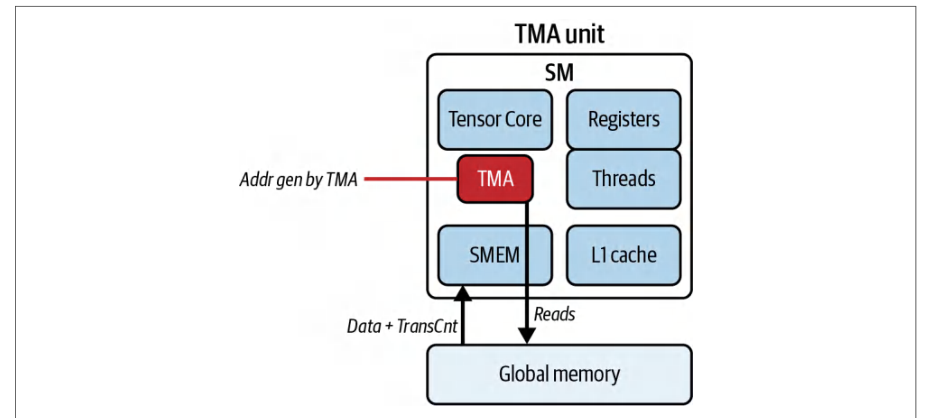
异步内存预取与张量内存加速器
Asynchronous Memory Prefetching and Tensor Memory Accelerator
In earlier sections, we saw how coalescing dozens of 4-byte loads into a single 128-byte transaction significantly improved global-load efficiency and cut wasted sectors per request. Yet even a perfectly coalesced load still stalls a warp for the full DRAM round trip.在前面的小节中,我们看到将数十次 4 字节加载合并为单次 128 字节事务,如何显著提升全局加载效率并减少每次请求中浪费的扇区。然而,即便是完美合并的加载,仍会让线程束停顿整整一个 DRAM 往返时间。
On Blackwell, for instance, a full DRAM round-trip is on the order of hundreds of cycles before any computation can begin. To hide that latency, we need to overlap data transfer with compute. This overlap is what hides most of the DRAM latency.例如在 Blackwell 上,一次完整的 DRAM 往返需要数百个周期,之后才能开始任何计算。为了隐藏这一时延,我们需要让数据传输与计算重叠。正是这种重叠隐藏了大部分 DRAM 时延。
CUDA’s Pipeline API together with the Tensor Memory Accelerator (TMA) hardware engine take this idea to the thread-block level. Instead of having each warp use the SM’s load and store (LD/ST) units to fetch data from global memory, you can invoke the TMA engine to asynchronously fetch an entire tile from global memory into shared memory, as shown in Figure 7-7.CUDA 的 Pipeline API 与张量内存加速器(TMA)硬件引擎一起,将这一思想提升到线程块级别。无需让每个线程束使用 SM 的加载/存储(LD/ST)单元从全局内存取数据,你可以调用 TMA 引擎,将整个数据块(tile)从全局内存异步取入共享内存,如图 7-7 所示。
To start the TMA transfer, you can call cuda::memcpy_async(). On modern GPU architectures, cuda::memcpy_async() together with cuda::pipeline exposes the hardware engines for asynchronous global to shared transfers. This includes the TMA when available. This will use TMA’s on-chip DMA engine to perform the asynchronous bulk data transfer. This is implemented in CUDA as follows:要启动 TMA 传输,可以调用 cuda::memcpy_async()。在现代 GPU 架构上,cuda::memcpy_async() 与 cuda::pipeline 结合,可调用硬件引擎完成全局内存到共享内存的异步传输,其中就包括可用时的 TMA。这将使用 TMA 的片上 DMA 引擎执行异步批量数据传输。在 CUDA 中的实现如下:
cuda::memcpy_async(sharedBuf,
               globalPtr + offset,
               cuda::aligned_size_t<16>(bytes),
               pipe);
pipe.producer_commit();
And while TMA handles the bulk copy, including coalescing, strided transfers, and even multidimensional transfers, the kernel computes the previous tile. This is called double buffering, or ping-ponging.并且,当 TMA 处理批量拷贝(包括合并访问、跨步传输,甚至多维传输)时,内核正在计算上一个 tile。这被称为*双缓冲*,或称*乒乓*。
By implementing double buffering with TMA, the SM’s load/store units are now free to do real work because TMA’s DMA engine moves data for us in the background. In effect, data movement becomes asynchronous such that while TMA streams in the next tile of data, the SM’s warps compute on the previous tile. This overlap is what hides the 800-cycle DRAM latency.通过 TMA 实现双缓冲后,SM 的加载/存储单元得以腾出来做真正的工作,因为 TMA 的 DMA 引擎在后台为我们搬运数据。实际上,数据搬运变为异步的:当 TMA 流入下一个 tile 的数据时,SM 的线程束正在计算上一个 tile。正是这种重叠隐藏了 800 个周期的 DRAM 时延。
Specifically, TMA is capable of 1D–5D bulk copies and arbitrary strides between global and shared memory without blocking the SM instruction pipeline. By offloading these transfers from the SM to TMA, your kernel issues far fewer LD/ST instructions, eliminates extra synchronization, and lets the warp schedulers spend almost every cycle on useful computation instead of waiting on memory.具体而言,TMA 能够在全局内存与共享内存之间执行 1D–5D 批量拷贝和任意跨步访问,且不阻塞 SM 的指令流水线。通过将这些传输从 SM 卸载到 TMA,内核发出的 LD/ST 指令大幅减少,消除了额外的同步,并让线程束调度器几乎每个周期都花在有用的计算上,而不是等待内存。
Here is a code snippet showing how to initiate an asynchronous copy from global to shared memory using the CUDA C++ Pipeline API and the TMA hardware engine:下面的代码片段展示了如何使用 CUDA C++ Pipeline API 和 TMA 硬件引擎发起从全局内存到共享内存的异步拷贝:
#include <cuda/pipeline>
#include <cuda_runtime.h>
#include <cstdint>
#include <cassert>
#define TILE_SIZE 1024  // example tile size
// 用户提供的计算函数,作用于共享内存分块
__device__ void processTile(const float* tile);
__global__ void kernelWithTMA(const float* __restrict__ global_ptr,
                              int nTiles) {
    // 共享内存中的两个乒乓缓冲区
    // 在 Blackwell(CUDA 13+)上,256 位向量建议采用 32B 对齐
    // (v8.f32 / double4)。
    __shared__ __align__(VEC_BYTES) float tile0[TILE_SIZE];
    __shared__ __align__(VEC_BYTES) float tile1[TILE_SIZE];
float* tiles[2] = { tile0, tile1 };

    // 向量化拷贝的对齐/大小保护检查
    // --- 选择向量宽度 -------------------------------------------------
    #ifndef VEC_BYTES
      // 在 CUDA 13+/Blackwell 上优先使用 32B 向量。
      // 定义 -DUSE_256B_VEC 可强制启用。
      #if defined(USE_256B_VEC) || (defined(CUDA_VERSION)&&CUDA_VERSION >= 13000)
        #define VEC_BYTES 32      // 256-bit: v8.f32, double4
#include <cuda/pipeline>
#include <cuda_runtime.h>
#include <cstdint>
#include <cassert>
#define TILE_SIZE 1024  // example tile size
// User-provided compute function operating on a shared-memory tile
__device__ void processTile(const float* tile);
__global__ void kernelWithTMA(const float* __restrict__ global_ptr,
                              int nTiles) {
    // Two ping-pong buffers in shared memory
    // On Blackwell (CUDA 13+), prefer 32B alignment for 256-bit vectors
    // (v8.f32 / double4).
    __shared__ __align__(VEC_BYTES) float tile0[TILE_SIZE];
    __shared__ __align__(VEC_BYTES) float tile1[TILE_SIZE];
float* tiles[2] = { tile0, tile1 };

    // Alignment / size guards for vectorized copies
    // --- choose vector width -------------------------------------------------
    #ifndef VEC_BYTES
      // Prefer 32B vectors on CUDA 13+/Blackwell.
      // Define -DUSE_256B_VEC to force.
      #if defined(USE_256B_VEC) || (defined(CUDA_VERSION)&&CUDA_VERSION >= 13000)
        #define VEC_BYTES 32      // 256-bit: v8.f32, double4
      #else
        #define VEC_BYTES 16      // 128-bit: v4.f32, float4
      #endif
    #endif
    constexpr int VEC_ELEMS = VEC_BYTES / sizeof(float); // 4(128b)或 8(256b)
    constexpr int WARP      = 32;
    // 向量化拷贝/计算的对齐与大小校验
    static_assert((TILE_SIZE % (WARP * VEC_ELEMS)) == 0,
                  "TILE_SIZE must be a multiple of WARP_SIZE * VEC_ELEMS");
    // 同时保证 tile 的字节数
    //  是向量宽度的整数倍
    static_assert(((TILE_SIZE * sizeof(float)) % VEC_BYTES) == 0,
                  "Tile byte size must be a multiple of VEC_BYTES");
    // 在 Blackwell(CUDA 13+)上,优先采用 32B 对齐
    // 以支持 256 位向量(v8.f32 / double4)。
    assert((reinterpret_cast<std::uintptr_t>(global_ptr) % VEC_BYTES) == 0);
    size_t bytes = TILE_SIZE * sizeof(float);
    // 块作用域的 TMA 流水线
    __shared__ cuda::pipeline_shared_state<
        cuda::thread_scope_block, 2> state;
    auto pipe =
        cuda::make_pipeline(cuda::this_thread_block(),
            &state);
    // 用第一次异步拷贝到 tile0 来预热流水线
    pipe.producer_acquire();
    cuda::memcpy_async(tiles[0],
                       global_ptr + 0 * TILE_SIZE,
                       cuda::aligned_size_t<32>{bytes},
                       pipe);
    pipe.producer_commit();
    // 遍历剩余的 tile
    for (int t = 1; t < nTiles; ++t) {
        // 等待上一次拷贝完成,然后在其上计算
        pipe.consumer_wait();
        processTile(tiles[(t - 1) & 1]);
        pipe.consumer_release();
        // 将下一次异步拷贝入队到备用缓冲区
        pipe.producer_acquire();
        cuda::memcpy_async(tiles[t & 1],
                           global_ptr + t * TILE_SIZE,
                           cuda::aligned_size_t<32>{bytes},,
                           pipe);
        pipe.producer_commit();
    }
      #else
        #define VEC_BYTES 16      // 128-bit: v4.f32, float4
      #endif
    #endif
    constexpr int VEC_ELEMS = VEC_BYTES / sizeof(float); // 4 (128b) or 8 (256b)
    constexpr int WARP      = 32;
    // Alignment / size guards for vectorized copies/compute
    static_assert((TILE_SIZE % (WARP * VEC_ELEMS)) == 0,
                  "TILE_SIZE must be a multiple of WARP_SIZE * VEC_ELEMS");
    // Also guarantee the tile byte count
    //  is a multiple of the vector width
    static_assert(((TILE_SIZE * sizeof(float)) % VEC_BYTES) == 0,
                  "Tile byte size must be a multiple of VEC_BYTES");
    // On Blackwell (CUDA 13+), prefer 32B alignment
    // for 256-bit vectors (v8.f32 / double4).
    assert((reinterpret_cast<std::uintptr_t>(global_ptr) % VEC_BYTES) == 0);
    size_t bytes = TILE_SIZE * sizeof(float);
    // Block-scoped pipeline for TMA
    __shared__ cuda::pipeline_shared_state<
        cuda::thread_scope_block, 2> state;
    auto pipe =
        cuda::make_pipeline(cuda::this_thread_block(),
            &state);
    // Prime pipeline with the first async copy into tile0
    pipe.producer_acquire();
    cuda::memcpy_async(tiles[0],
                       global_ptr + 0 * TILE_SIZE,
                       cuda::aligned_size_t<32>{bytes},
                       pipe);
    pipe.producer_commit();
    // Loop over the remaining tiles
    for (int t = 1; t < nTiles; ++t) {
        // Wait for the previous copy to finish, then compute on it
        pipe.consumer_wait();
        processTile(tiles[(t - 1) & 1]);
        pipe.consumer_release();
        // Enqueue the next async copy into the alternate buffer
        pipe.producer_acquire();
        cuda::memcpy_async(tiles[t & 1],
                           global_ptr + t * TILE_SIZE,
                           cuda::aligned_size_t<32>{bytes},,
                           pipe);
        pipe.producer_commit();
    }
    // 最后一次等待并在最后一个 tile 上计算
    pipe.consumer_wait();
    processTile(tiles[(nTiles - 1) & 1]);
    pipe.consumer_release();
}
    // Final wait and compute on the last tile
    pipe.consumer_wait();
    processTile(tiles[(nTiles - 1) & 1]);
    pipe.consumer_release();
}
Immediately after kernel launch, each block allocates two shared-memory tiles (tile0, tile1) and constructs a block-scoped pipeline so all threads in the thread block coordinate their asynchronous DMA, as shown here:内核启动后,每个线程块立即分配两个共享内存 tile(tile0、tile1),并构造一个块作用域的流水线,使线程块中的所有线程协调它们的异步 DMA,如下所示:
__shared__ cuda::pipeline_shared_state<
    cuda::thread_scope_block, 2> state;
auto pipe =
    cuda::make_pipeline(cuda::this_thread_block(),
        &state);
To prime the pipeline, we submit an asynchronous copy using the TMA, which coalesces even strided or multidimensional transfers and streams bytes from global memory into tiles[0] in the background, as seen here:为了给流水线预热,我们使用 TMA 提交一次异步拷贝,它会合并即使是跨步或多维的传输,并在后台将 bytes 个字节从全局内存流入 tiles[0],如下所示:
pipe.producer_acquire();
cuda::memcpy_async(tiles[0],
                   global_ptr + 0 * TILE_SIZE,
                   cuda::aligned_size_t<32>{bytes},
                   pipe);
pipe.producer_commit();
Before using that data, we do the following to ensure we block just long enough for the TMA to finish the copy:在使用这些数据之前,我们执行以下操作,以确保只阻塞到 TMA 完成拷贝所需的时间:
pipe.consumer_wait();
processTile(tiles[0]);
pipe.consumer_release();
Inside the main loop, we alternate buffers using pipe.consumer_wait(); + process Tile() on the previous tile, pipe.consumer_release(), pipe.producer_acquire() + new cuda::memcpy_async() into the other tile, and pipe.producer_commit(). Then we repeat!在主循环内部,我们通过 pipe.consumer_wait(); + 对上一个 tile 执行 process Tile()、pipe.consumer_release()、pipe.producer_acquire() + 向另一个 tile 发起新的 cuda::memcpy_async(),以及 pipe.producer_commit() 来交替使用缓冲区。然后重复此过程!
By ping-ponging between tile0 and tile1, each new memcpy_async overlaps processTile on the previous buffer. The load and store units on the SM experience lower pressure with more instruction issue slots available for computation. At the same time, the TMA moves data in parallel. This eliminates redundant global memory loads, reduces synchronization overhead, and keeps warps busy rather than stalled on memory.通过在 tile0 与 tile1 之间乒乓切换,每次新的 memcpy_async 都与上一个缓冲区上的 processTile 重叠。SM 上的加载与存储单元承受的压力更小,有更多指令发射槽可用于计算。与此同时,TMA 并行搬运数据。这消除了冗余的全局内存加载,降低了同步开销,并让线程束保持忙碌,而不是停滞在显存访问上。
Asynchronous prefetching from global memory to shared memory hides latency behind compute. Threads preload upcoming data into shared memory while they compute on data that was previously loaded.从全局内存到共享内存的异步预取将时延隐藏在计算之后。线程在计算先前已加载的数据的同时,将即将用到的数据预加载到共享内存。
| Metric指标 | Before (no prefetch)优化前(无预取) | After (async prefetch)优化后(异步预取) |
|---|---|---|
| Global Memory Load Efficiency全局内存加载效率 | 23%23% | 99%99% |
| Average sectors per request每次请求的平均扇区数 | 6.46.4 | 4.04.0 |
| DRAM throughput (% of peak)DRAM 吞吐量(占峰值的百分比) | 25%25% | 90%90% |
| SM Active %SM 活跃占比 % | 62%62% | 100%100% |
| Kernel execution time内核执行时间 | 18 ms18 ms | 7 ms7 ms |
This pattern is especially effective in memory-bound loops and tensor computations. On modern GPUs, the TMA can stream the next tile for a matrix multiply while the current tile is being processed.这种模式在显存受限的循环和张量计算中尤其有效。在现代 GPU 上,TMA 可以在当前瓦片(tile)被处理的同时流式加载矩阵乘法的下一个瓦片。
We trade many scattered global reads for one coalesced global copy plus many fast shared-memory loads. This is favorable given the gap between DRAM and on-chip SRAM. Table 7-7 summarizes Nsight Compute metrics before and after a TMA-based double-buffering implementation.我们用一次合并的全局拷贝加上多次快速的共享内存加载,换取了大量分散的全局读取。考虑到 DRAM 与片上 SRAM 之间的差距,这样做是有利的。表 7-7 汇总了基于 TMA 的双缓冲实现前后的 Nsight Compute 指标。
Here, we see SM Active % approaches 100%, which shows that the SMs have active warps for nearly all cycles. Global Memory Load Efficiency increases from 23% to 99%, meaning nearly every fetched byte is useful.在这里,我们看到 SM Active % 接近 100%,这表明 SM 在几乎所有的周期内都有活跃的线程束。Global Memory Load Efficiency 从 23% 提升到 99%,意味着几乎每一个取回的字节都是有用的。
Average sectors per request falls from 6.4 to about 4.0, which indicates that requests map cleanly to 128-byte lines at the cache. DRAM throughput rises from 25% to 90% of peak, and overall time improves from 18 milliseconds to 7 milliseconds, about 2.6× faster. These results confirm that offloading bulk copies to the TMA and ping-ponging shared memory buffers keep the GPU busy and hide most of the DRAM latency behind useful work.每次请求的平均扇区数从 6.4 降至约 4.0,这表明请求在缓存处干净地映射到 128 字节的行。DRAM 吞吐量从峰值的 25% 升至 90%,整体时间从 18 毫秒改善到 7 毫秒,约快 2.6 倍。这些结果证实,将批量拷贝卸载到 TMA 并让共享内存缓冲区乒乓切换,可使 GPU 保持忙碌,并把大部分 DRAM 时延隐藏在有效工作之后。
NVIDIA’s CUDA pipeline API plus TMA is a textbook example of hardware-software codesign. The Pipeline API specifically exposes TMA’s capabilities—and the TMA hardware supports exactly the asynchronous, coalesced, multidimensional copies that cuda::memcpy_async needs.NVIDIA 的 CUDA pipeline API 加上 TMA 是软硬件协同设计的教科书式范例。Pipeline API 专门暴露了 TMA 的能力——而 TMA 硬件恰好支持 cuda::memcpy_async 所需的异步、合并、多维拷贝。
The API and the TMA DMA engine were developed hand in hand so you can express high-level pipeline operations that map closely to the hardware transfer capabilities.该 API 与 TMA DMA 引擎是携手开发的,因此你可以表达与硬件传输能力紧密对应的高层流水线操作。
This allows the efficient overlap of memory movement with compute to boost performance.这使得内存搬运能与计算高效重叠,从而提升性能。
In summary, when memory access limits your kernel’s performance, offload and overlap data movement by combining careful tiling, double buffering, and TMA-driven asynchronous prefetching. By staging tiles in shared memory and using cuda::memcpy_async alongside pipe.producer_commit and pipe.consumer_wait, you hand off coalesced, multidimensional DMA transfers to the TMA, offloading the global to shared memory transfer.总之,当显存访问限制了内核性能时,可通过结合精心的分块、双缓冲和 TMA 驱动的异步预取来卸载并重叠数据搬运。通过在共享内存中暂存分块,并将 cuda::memcpy_async 与 pipe.producer_commit 和 pipe.consumer_wait 配合使用,你把合并的、多维的 DMA 传输交给 TMA,从而卸载全局内存到共享内存的传输。
Using TMA to offload memory transfers helps to relieve pressure on the SM’s load/ store units to help keep the computation pipeline full. As such, the SM focuses on compute, while shared memory traffic uses the on-chip TMA path. On Blackwell’s massive-bandwidth HBM3e fabric, these techniques are essential to hide DRAM latency, sustain peak throughput, and turn memory-bound kernels into near-compute-bound workhorses.使用 TMA 卸载内存传输有助于缓解 SM 的加载/存储单元的压力,从而帮助保持计算流水线满载。因此,SM 专注于计算,而共享内存流量走片上 TMA 路径。在 Blackwell 超大带宽的 HBM3e 互连结构上,这些技术对于隐藏 DRAM 时延、维持峰值吞吐量,以及将显存受限的内核转变为接近计算受限的主力工作负载至关重要。
关键要点
Key Takeaways
Optimizing memory access patterns on GPUs—through coalescing, data reuse, and asynchronous transfers—can shift a kernel from being memory bound to approaching the hardware’s peak capabilities. Small code changes to better align with GPU architecture (such as proper thread grouping, using shared memory, avoiding bank conflicts) can yield massive performance gains. Here are the key takeaways from this chapter:在 GPU 上优化显存访问模式——通过合并访问、数据复用和异步传输——可以将内核从显存受限转变为接近硬件的峰值能力。为更好地契合 GPU 架构而做的小幅代码改动(例如恰当的线程分组、使用共享内存、避免存储体冲突)可以带来巨大的性能收益。以下是本章的关键要点:
- Global-memory coalescing全局内存合并访问
- Coalescing is achieved when each warp’s accesses fall within as few 128-byte cache lines as possible. Arrange your data and thread indexes so that each warp’s threads read consecutive 4-byte words, letting the hardware fuse them into a few 128-byte transactions. Coalesced memory loads maximize effective DRAM bandwidth, or Global Memory Load Efficiency, and minimize average sectors per request down to the optimal 4.0 value. When using modern versions of Nsight Compute, you can当每个线程束的访问落在尽可能少的 128 字节缓存行内时,就实现了合并访问。安排数据与线程索引,使每个线程束的线程读取连续的 4 字节字,让硬件将它们融合为少量 128 字节事务。合并的内存加载可最大化有效 DRAM 带宽(即全局内存加载效率),并将每次请求的平均扇区数降至最优的 4.0。使用现代版本的 Nsight Compute 时,你可以
also use sm__sass_data_bytes_mem_* counters and gpu__dram_throughput
.avg.pct_of_peak_sustained_elapsed to profile and optimize memory
coalescing.
- Vectorized loads/stores向量化加载/存储
- Use built-in vector types such as
float4for 16-byte vectors. On Blackwell with CUDA 13+, prefer 32-byte per-thread vectors when 32-byte alignment is prova-ble. This includesdouble4or a custom structalignas(32) { float v[8]; }. This reduces instructions per byte and keeps sectors/request at the ideal 4.0 when properly aligned. This way, each thread moves as many elements as possible in one instruction. The number of 128-byte transactions per warp scales with the total bytes requested. Be mindful of alignment: ensure your arrays are allocated with at least 16-byte alignment forfloat4, whichcudaMallocdoes by default using 256-byte alignment, typically. Misaligned vector accesses will forfeit these benefits.使用内置向量类型(如float4)来处理 16 字节向量。在 Blackwell 上使用 CUDA 13+ 时,若 32 字节对齐可证明成立,则优先采用每线程 32 字节的向量。这包括double4或自定义结构体alignas(32) { float v[8]; }。这可减少每字节的指令数,并在正确对齐时使每请求扇区数保持在理想的 4.0。这样一来,每个线程在一条指令中搬运尽可能多的元素。每个线程束的 128 字节事务数随请求的总字节数成比例增长。注意对齐:确保数组按至少 16 字节对齐分配以适配float4,cudaMalloc默认通常采用 256 字节对齐。未对齐的向量访问将丧失这些收益。
- Bank-conflict avoidance避免存储体冲突
- Pad your shared-memory arrays (e.g., make rows 33 floats wide for 32-thread warps) so that no two threads hit the same bank in the same cycle. Removing bank conflicts restores full shared-memory throughput. Try swizzling for a slightly more memory-efficient implementation than padding.对共享内存数组进行填充(例如,针对 32 线程的线程束将行宽设为 33 个 float),使同一周期内没有两个线程命中同一存储体。消除存储体冲突可恢复完整的共享内存吞吐量。相比填充,可尝试交织重排(swizzling),以获得略微更省内存的实现。
- Shared-memory tiling and data reuse共享内存分块与数据复用
- Stage working sets in on-chip shared memory (e.g., tiling a matrix in 32 × 32 blocks) so each element is fetched once from DRAM but used many times on the SM. This raises arithmetic intensity and shifts kernels toward being compute bound.将工作集暂存到片上共享内存(例如,将矩阵按 32 × 32 分块),使每个元素只从 DRAM 取一次,却在 SM 上被多次使用。这提高了算术强度,并使内核转向计算受限。
- Read-only data cache只读数据缓存
- Mark small, static lookup tables or coefficients as
const __restrict__so the compiler can route loads through the read-only data path when applicable. Uniform broadcasts are lower-latency than DRAM, avoid redundant transactions, and can be served from on-chip cache.将小型静态查找表或系数标记为const __restrict__,以便编译器在适用时通过只读数据路径执行加载。统一广播的时延低于 DRAM,可避免冗余事务,并可由片上缓存提供。
- Overlap host–GPU copies with streams用流重叠主机—GPU 拷贝
- Allocate your host buffers as page-locked (“pinned”) memory, and use
cudaMemcpyAsyncon multiple streams to overlap H2D/D2H transfers with kernel execution. Pinned memory enables asynchronous DMA transfers, and multiple streams allow copies to overlap with kernel execution to hide PCIe or NVLink transfer latency. PrefercudaMemcpyAsyncwith explicit streams and events to overlap H2D/D2H and kernels. Remember that pageable (non-pinned) memory will disable DMA overlap. You should verify whether pageable or pinned memory is used, as observed transfer rates will vary widely depending on this configuration.将主机缓冲区分配为页锁定(“锁页”)内存,并在多个流上使用cudaMemcpyAsync,使 H2D/D2H 传输与内核执行重叠。锁页内存可启用异步 DMA 传输,而多个流则允许拷贝与内核执行重叠,从而隐藏 PCIe 或 NVLink 的传输时延。优先使用带显式流和事件的cudaMemcpyAsync来重叠 H2D/D2H 传输与内核。请记住,可分页(非锁页)内存会禁用 DMA 重叠。你应当确认使用的是可分页内存还是锁页内存,因为观察到的传输速率会因这一配置而有很大差异。
- Asynchronous prefetch with TMA + Pipeline API使用 TMA + Pipeline API 进行异步预取
- Use the C++ libcu++ barrier and pipeline APIs (
cuda::barrierandcuda::pipeline) withcuda::memcpy_asyncto drive TMA (cp.async.bulk.tensor) for global memory → shared memory bulk copies when alignment and scope requirements are met. This offloads coalesced, strided (even multidimensional) copies into shared memory and overlaps them with computation with double buffering. This will reduce pressure on the SM’s LD/ST units and let the SM focus on compute.在满足对齐与作用域要求时,使用 C++ libcu++ 的屏障与流水线 API(cuda::barrier和cuda::pipeline)配合cuda::memcpy_async来驱动 TMA(cp.async.bulk.tensor),完成全局内存 → 共享内存的批量拷贝。这样可将合并访问的、跨步的(甚至是多维的)拷贝卸载到共享内存中,并通过双缓冲使其与计算重叠。这会减轻 SM 的 LD/ST 单元压力,让 SM 专注于计算。
It’s important to note that the libcu++ pipeline APIs and TMA continue to evolve. Prefer the staged forms (e.g., producer_acquire(), producer_commit(), consumer_wait(), consumer_release()) for two-stage ping-pong buffers. Use a block-scoped pipeline (e.g., cuda::thread_scope_block) or block-scoped barrier (e.g., cuda::barrier<cuda::thread_scope_block>) unless you specifically need cluster-scoped or grid-scoped copies.需要注意的是,libcu++ pipeline API 与 TMA 仍在持续演进。对于两级乒乓缓冲区,优先使用分阶段形式(例如 producer_acquire()、producer_commit()、consumer_wait()、consumer_release())。除非确实需要集群作用域或网格作用域的拷贝,否则使用块作用域的 pipeline(例如 cuda::thread_scope_block)或块作用域的 barrier(例如 cuda::barrier<cuda::thread_scope_block>)。
- Profile to guide you以性能剖析为指导
- Rely on Nsight Compute metrics like Global Memory Load Efficiency, average sectors per request, shared-memory bank conflicts, SM Active %, warp stall reasons, etc. Also, review Nsight Systems timelines to visualize overlaps and stalls, pinpoint bottlenecks, and verify each optimization.依赖 Nsight Compute 的指标,如全局内存加载效率(Global Memory Load Efficiency)、每请求平均扇区数、共享内存存储体冲突、SM 活跃占比(SM Active %)、线程束停顿原因等。同时,查看 Nsight Systems 时间线以可视化重叠与停顿、定位瓶颈,并验证每一项优化。
结语
Conclusion
With your memory-access pipeline now firing on all cylinders with coalesced global memory loads, conflict-free tiling, vectorized fetches, read-only caching, and TMA-driven prefetching, you’ve removed the biggest data-movement bottlenecks and freed the SMs to run at full speed.如今,你的显存访问流水线已全速运转:全局内存合并加载、无冲突分块、向量化取数、只读缓存以及 TMA 驱动的预取,你已经消除了最大的数据搬运瓶颈,并释放 SM 使其全速运行。
Throughout this chapter we’ve relied on Nsight Compute and Nsight Systems to expose exactly where warps were starving for data. We also used them to confirm, step by step, that each optimization really did reduce stalls, collapse wasted transactions, and boost sustained bandwidth. Those tools remain your north star whenever you tune a new kernel.在本章中,我们一直借助 Nsight Compute 和 Nsight Systems 来精确揭示线程束究竟在何处因缺少数据而饥饿。我们还用它们逐步确认每一项优化确实减少了停顿、消除了浪费的事务并提升了持续带宽。无论何时调优新的内核,这些工具始终是你的北极星。
In the next chapter, we’ll cover some fundamental latency-hiding techniques in CUDA and GPU programming. These techniques include tuning occupancy, increasing warp efficiency, avoiding warp divergence, and exposing instruction-level parallelism.在下一章中,我们将介绍 CUDA 与 GPU 编程中一些基本的时延隐藏技术。这些技术包括调整占用率、提升线程束效率、避免线程束发散,以及暴露指令级并行。